
Microsoft Files Patent to Train AI on One Great Answer and a Few Bad Ones
Teaching a chatbot is a bit like grading practice essays: the bot writes dozens of answers, but Microsoft's filing says you only need to study a handful. The trick is keeping the one best answer and a few bad ones that differ from each other.
What Microsoft's answer-trimming patent does
Every time you ask a chatbot a question, it could have answered dozens of different ways. When companies train these bots, they often have the bot write a pile of answers to the same question, score each one, and learn from the results.
The catch is that this gets expensive, and many of those answers are near copies of each other. Microsoft's patent filing describes a shortcut: out of, for example, 32 answers, keep only 8. One is the best-scoring answer, held up as the one to copy. The other seven are picked as examples of what to avoid, chosen so they cover different kinds of mistakes.
Then the training nudges the bot toward the good answer and away from the bad ones, pushing hardest on answers that were far better or far worse than average. Repeat that over and over, and you get a chatbot that behaves more the way people want, with a smaller computing bill.
identifying a highest-reward response as a positive example; and selecting K−1 negative responses from remaining responses by one or more of: selecting remaining responses with the lowest reward scores; …
Translation: The system picks the best answer as a good example and the worst answers as bad examples.
How the system picks its bad examples to learn from
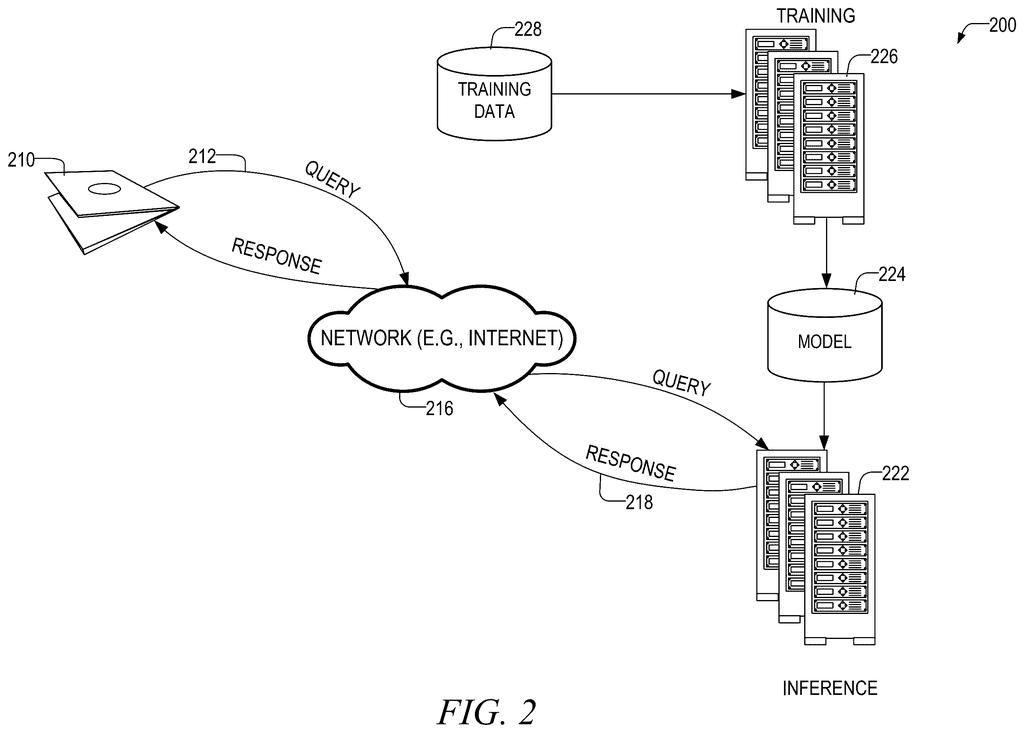
The patent covers a method for training a language model (the software behind a chatbot). For each question in the training set, the model writes N candidate answers. A separate scoring program, called a reward model (a model trained beforehand to rate answers by how well they match human preferences), gives each answer a score.
Next comes the trimming step. The system keeps K answers, where K is smaller than N. The top-scoring answer becomes the positive example. The remaining K minus 1 slots go to negative examples, chosen by one or more of these strategies:
- Bottom-K: simply take the lowest-scoring answers.
- Coreset: turn each answer into embeddings (lists of numbers that capture what a sentence means), sort them into groups with K-means clustering (an automatic grouping method), then take the lowest-scoring answer from each group.
- Opt-Select: give lower-scoring answers more weight, then pick negatives spread across different regions of meaning so they are not near duplicates.
Then the math kicks in. The system averages the scores of the kept answers and measures how far each one sits from that average. Answers above it go in the positive group, and answers at or below it go in the negative group. Answers farther from average get bigger weights. Those weights feed a weighted contrastive loss (a training score that rewards the model for making good answers more likely and bad answers less likely, all in one step), and the model's settings are updated to improve it.
The filing says the loop can repeat, with the freshly updated model writing the next round of answers.
… Active Multi-Preference Optimization (AMPO) in training language models. The method involves generating multiple candidate responses for a given query and selecting a subset of responses that are most informative for training.
Translation: A new method trains language models more efficiently by picking the most useful answers.
Why trimming training data could cut AI costs
Making a chatbot better is expensive. Each round of training means generating lots of answers, scoring them, and holding them in the memory of costly graphics chips. The filing says trimming a pool of 32 answers down to 8 cuts memory, training time and power use. For you, that could mean the assistants you use get tuned and corrected more often, because each round costs less.
The method also aims at quality. Since the model can write its own practice answers, the selection keeps feeding it feedback on the mistakes it actually makes today, and picking varied bad examples covers more kinds of mistakes. The filing gives no test results, so treat the gains as the company's claim for now.
Microsoft's 69th filing in the AI assistant and agent patents we've tracked since May builds on earlier applications like the screen-aware AI and the web page trimmer.
The cost of this design is information. By keeping 8 of 32 answers, the system throws away most of what the bot wrote, and it bets that the scoring program can tell good from bad. If that scorer has blind spots, the bot learns to chase the scorer's quirks, and the trimming makes that worse because every choice about what to keep leans on those scores.
There is also extra work before training even starts. Sorting answers into groups by meaning takes computing too, and the filing's fanciest option involves solving an optimization problem just to choose the examples. Whether the whole thing saves time overall depends on numbers the filing does not give.
Still, the trade reads as worth it. Many answers from the same model look alike, so dropping near duplicates loses little, and a varied set of bad examples teaches more than several copies of one mistake. It is a modest, practical tune-up with a believable upside.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
5 drawing sheets from US 2026/0330232 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in