
IBM Patents a Way to Split AI Processing Between Your Device and the Cloud
Most AI tools ship your raw data straight to a server and let it do everything. IBM has filed a patent for a different approach: your device does the prep work and the cleanup, while the server handles only the heavy AI computation.
How IBM's split AI processing actually works for users
You're filling out a form in a business app and hit a button that runs an AI analysis on your data. Under the hood, that usually means your raw information travels to a remote server, gets processed entirely there, and comes back. Everything happens on someone else's machine.
IBM's patent describes a system where your device takes on more of that work. Before your data goes anywhere, your device follows a downloaded checklist to prepare it, cleaning it up, formatting it, filtering sensitive parts. The server then runs the actual AI model on that prepped data and sends back a result. Your device follows a second checklist to translate that raw result into something useful before showing it to you.
The key idea is that the AI model stays on the server (where it's expensive to run and easy to update), but the steps immediately around it run locally on your device. That split can reduce how much raw data leaves your hands and how much load the server has to absorb.
fetching, at a client from a remote server hosting a machine learning model, a first checklist for pre-processing input data for the machine learning model and a second checklist for post-processing output data from the machine learning model …
Translation: Your device downloads two lists from a cloud server to handle data preparation and cleanup.
How the checklist system divides work between client and server
The patent describes a distributed inference architecture, meaning the job of getting a useful answer from an AI model is divided between two machines rather than handled entirely by one.
Here's how the flow works:
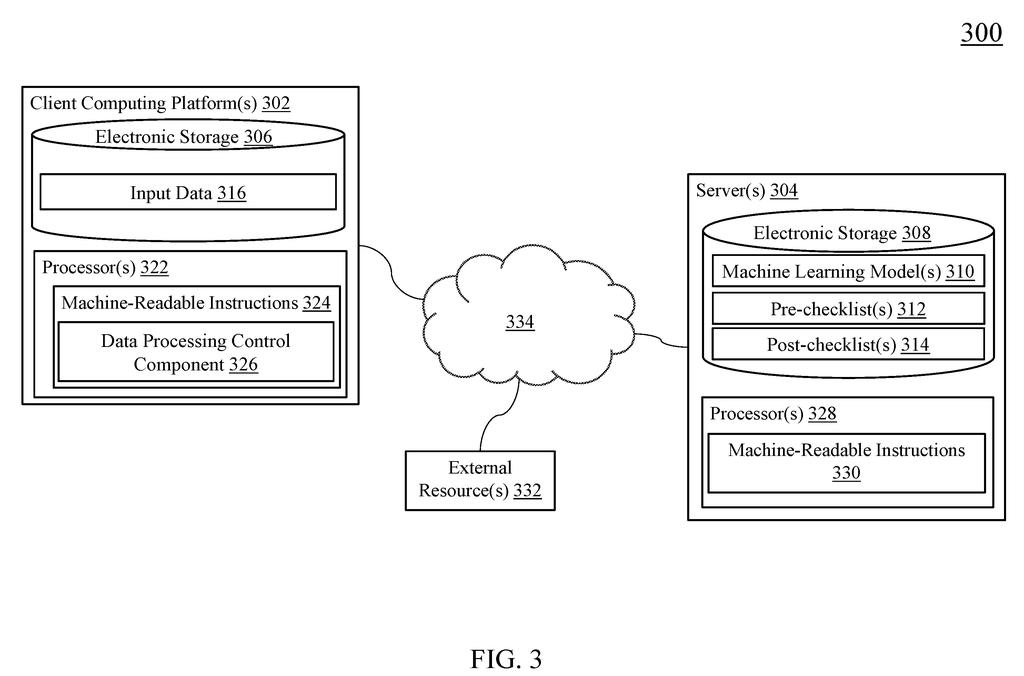
- Your device (the client) fetches two checklists from the server: one for pre-processing (steps to take before sending data) and one for post-processing (steps to take on the result).
- The client executes the pre-processing steps on the raw input, producing a cleaned, formatted dataset ready for the model.
- That prepared dataset is sent to the remote server, where the machine learning model runs and produces an output.
- The server sends that output back. The client then runs the post-processing checklist to turn the raw model output into a finished result and displays it.
The checklists are fetched from the server, so the server owner controls what pre- and post-processing looks like without shipping a new version of the app. If the model changes, the checklists can update independently. The ML model itself never moves to the client, keeping compute-intensive inference centralized while offloading surrounding steps.
… performing the one or more pre-processing steps at a client on an input dataset to generate a pre-processed input dataset; transmitting, from the client to the remote server, the pre-processed input dataset to be processed by the machine learning model …
Translation: Your device prepares the raw data locally before sending it up to the cloud model.
What this means for AI privacy and server costs
For the person using an AI-powered app, this kind of architecture can mean less raw personal data traveling over the network. If pre-processing strips or anonymizes sensitive fields before anything leaves your device, the server never sees the original. That's a meaningful shift for industries like healthcare or finance, where data leaving a device at all can trigger compliance questions.
There's also a server-cost angle. When millions of users hit the same AI service, offloading pre- and post-processing to client devices reduces the server's workload per request. IBM has been filing around enterprise AI deployment You may not notice this directly, but it can translate into faster responses and lower costs for the businesses running these services.
IBM's ninth filing we've tracked since July in our on-device AI privacy push watchlist extends ideas from one that hides real searches and one that shields code testing data.
The clearest win for anyone using a product built on this system is privacy. Your device would scrub and reshape your data before it ever leaves your hands, meaning the remote system receives something partial and prepared rather than your raw information.
You would likely never see this happening, which is precisely the point. The protection would be baked into how the product works, not offered as a setting you have to find and enable.
The risk is quiet rather than obvious: if the instructions your device follows fall out of step with what the remote model expects, results could go wrong without any visible error. That is a failure most users would never trace back to its source, which puts real pressure on whoever maintains the system to keep everything tightly coordinated.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
4 drawing sheets from US 2026/0300781 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in