
Nvidia Patents an AI That Translates Just One Voice in a Crowded Room
Most translation tools try to translate everything they hear. This Nvidia patent application describes a model that listens to a messy conversation, finds the one person you care about, and translates only them.
What Nvidia's one-voice translation model does
A remote worker joins a video call where three colleagues are talking in German. She only needs to follow what one of them, Speaker A, is saying. Today's translation tools tend to translate everything, so she gets a jumbled transcript of all three voices.
Nvidia's filing describes a fix. You give the system a short voice sample of the person you want, and it builds a kind of voice fingerprint. The system then listens to the full conversation, picks out only that person's speech, and translates it into the language you choose.
The key twist is that all of this happens inside one AI model. Older setups chain together separate steps: separate the voices, write down the words, then translate the text. Nvidia's version skips the middle steps, which the company says should cut delay and reduce mistakes that pile up from one stage to the next.
generating, using one or more first encoders of a machine learning model and based at least on first audio data representing speech of a target speaker, a voice profile associated with the target speaker …
Translation: The system first builds a digital voice profile by analyzing a short audio sample of the specific person you want to follow.
How the model finds your voice, then translates it
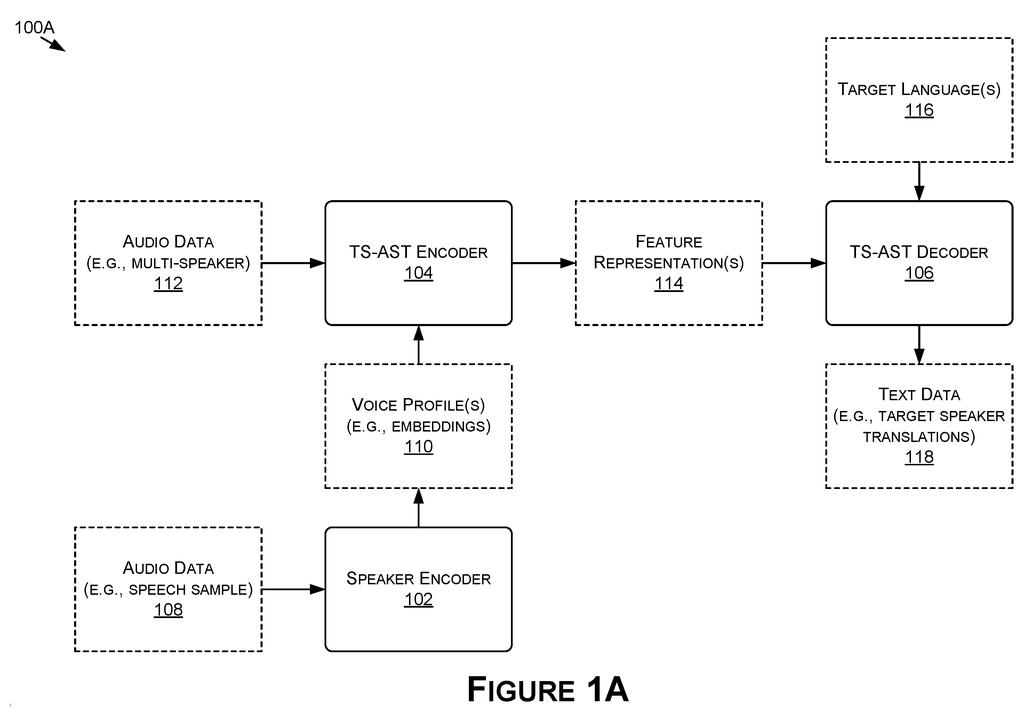
The patent application describes a single machine learning model, which Nvidia calls a TS-AST model (target speaker automatic speech translation), made of three parts that work in sequence.
- Speaker encoder: takes a short enrollment clip of the person you want to follow and turns it into a voice profile, a fixed-length string of numbers (an embedding) that captures things like tone, pitch, pace and accent.
- TS-AST encoder: listens to the mixed audio of the whole conversation and uses the voice profile to pull out features that match the target speaker while ignoring everyone else.
- TS-AST decoder: takes those features plus the chosen output language and writes the translation directly, as text or as speech, with no intermediate written transcript.
The filing also describes an optional language-identification model that works out which language the target speaker is using, so the system can handle any-to-any translation.
For several speakers, the same trained model can be run once per person, each time with a different voice profile. Those runs can happen in parallel, so the delay stays close to the single-speaker case. The claims also cover training the pieces together so the model learns to find the speaker and translate in one pass.
… the AST model may be used to extract the speech of a specified speaker from mixed audio and directly translate the speech into text of a target language without intermediate transcription …
Translation: It pulls one voice out of a noisy room and translates it straight into another language without writing down the original words first.
Why picking one speaker matters for live translation
If you have ever used live captions or translation in a video meeting, you know the problem: the tool treats every voice the same. A system that follows one chosen person could give you a clean translated transcript of your boss, a customer, or a game teammate without the noise of everyone else.
The filing lists video conferencing, gaming, in-car systems, robots and information kiosks as places this could run. It also says the translated text could feed other AI assistants. The patent says the single-model design should lower delay and avoid errors that carry over between steps, though the text gives no test results to back that up.
Nvidia's 28th filing in voice and speech AI we've tracked since May follows patents like fixing podcast words and face-reading games.
Anyone who has tried to follow a translated meeting with three people talking at once knows the output collapses into useless noise. The cost is not abstract: decisions get missed, people disengage, and the tool gets abandoned.
Giving the system a short voice sample up front and saying "follow this person" matches the actual shape of the problem. It is a human-sized solution to a human-sized frustration, and folding it into one model rather than chaining several together cuts the lag and compounding errors that make real-time translation feel perpetually one step behind.
The honest limits are that you need a clean sample to begin with, and the filing offers no accuracy figures to judge how well it holds up in noisy rooms. Even so, targeting one speaker rather than the whole room is a sharper, more useful goal than translation in general.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
13 drawing sheets from US 2026/0360368 A1 · click any drawing to enlarge


Show the other 5 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in