
Nvidia Patents a Way to Train One Speech AI Across Dozens of Languages at Once
Teaching an AI to understand speech in one language is hard. Teaching it to handle dozens at once, without losing accuracy in any of them, is the problem Nvidia is trying to solve here.
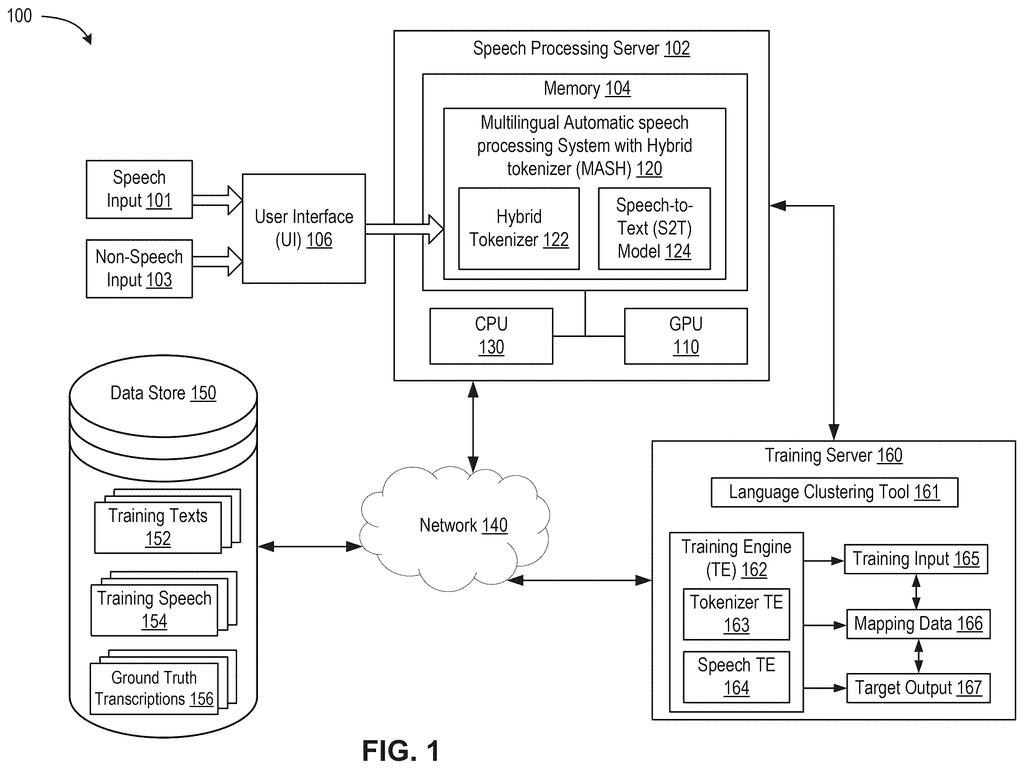
How Nvidia's multilingual speech AI groups languages
A call-center bot fields questions in English all morning, then switches to Arabic and Mandarin by afternoon. For the people building that bot, keeping one AI accurate across all three languages is a genuine engineering headache.
Nvidia's patent describes a way to train a single speech-to-text AI that handles many languages at once, rather than running a separate model for each one. The trick is organizing languages into family groups first, merging the vocabulary lists of related languages, then combining all those merged lists into one unified system before training begins.
The result is an AI that shares what it knows across languages, so learning a word pattern in Spanish can help it with Portuguese too. For you as an end user, that could mean voice assistants and transcription tools that work reliably whether you are speaking English, Arabic, or something far less common.
grouping a plurality of monolingual tokenizers (MTs) into a plurality of clusters, an individual cluster of the plurality of clusters including one or more MTs of the plurality of MTs selected based at least on linguistic similarity of the one or more MTs …
Translation: The system sorts different single language text tools into groups based on how similar the languages are.
How the hybrid tokenizer merges language families
The patent centers on building a hybrid tokenizer, which is the part of a speech AI that breaks spoken words into small chunks the model can learn from. Normally, each language gets its own tokenizer trained on its own vocabulary. This patent proposes a different approach.
The process works in three stages:
- Grouping: Individual language tokenizers are sorted into clusters based on linguistic similarity. Languages that share script, grammar patterns, or vocabulary tend to end up together.
- Merging: Within each cluster, the tokenizers are combined. When two languages share a token (a syllable, a root word, a character sequence), their information is pooled rather than duplicated.
- Combining and training: All the cluster-level tokenizers are merged into one hybrid tokenizer, which is then used to train a single speech-to-text model across all languages simultaneously.
The key insight is that merging at the cluster level first prevents any one language from drowning out another. Linguistically similar languages reinforce each other; dissimilar ones stay in separate clusters until the final combination step, preserving their distinct features.
… combining the plurality of cluster tokenizers into a hybrid tokenizer and training, using the hybrid tokenizer, a speech-to-text model to generate a text associated with a speech input into the model …
Translation: All those language groups are joined into one master tool used to teach a speech recognition model.
What this means for voice AI in global products
Voice AI is only as useful as the range of people it can actually understand. Right now, most production speech systems are English-first, with other languages supported by separate, often lower-quality models. A genuinely shared multilingual model could raise the floor for minority languages without dragging down performance for major ones.
Nvidia's steady investment in conversational AI systems points toward its growing ambitions in enterprise voice tools, data-center inference, and AI agent platforms. A more capable multilingual speech model would slot directly into those products. For end users, the practical payoff is transcription, voice assistants, and call-center AI that work reliably in the language you actually speak, not just the one the company found easiest to train.
That makes this Nvidia's 20th filing in voice and speech AI we've tracked since May, a topic that already includes one on auto-scripting and character voices and one on combined transcription and translation.
The path from this patent to a shippable feature is shorter than many AI filings suggest. Tokenizers and training pipelines are pure software; no new chip or specialized hardware is required. Nvidia would need large multilingual speech datasets and compute time, both things it has in abundance.
The clustering approach is the genuinely interesting part. Grouping languages before merging them is a practical answer to a known failure mode where dominant languages crowd out smaller ones during joint training. That is a real problem in production systems, and this addresses it at the architecture level.
The main open question is how well the merged tokenizer holds up for languages that share little with their cluster neighbors. The patent does not detail how cluster membership is decided or what happens at the edges. That is the kind of gap that tends to show up in ablation studies, not patent filings.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
15 drawing sheets from US 2026/0268889 A1 · click any drawing to enlarge


Show the other 7 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in