
Qualcomm Patents a Way to Identify Objects by Tracking Motion Between Frames
Most cameras figure out what's in a scene by looking at colors and shapes. Qualcomm's new patent takes a different approach: tracking how things move between two images to figure out where objects begin and end.
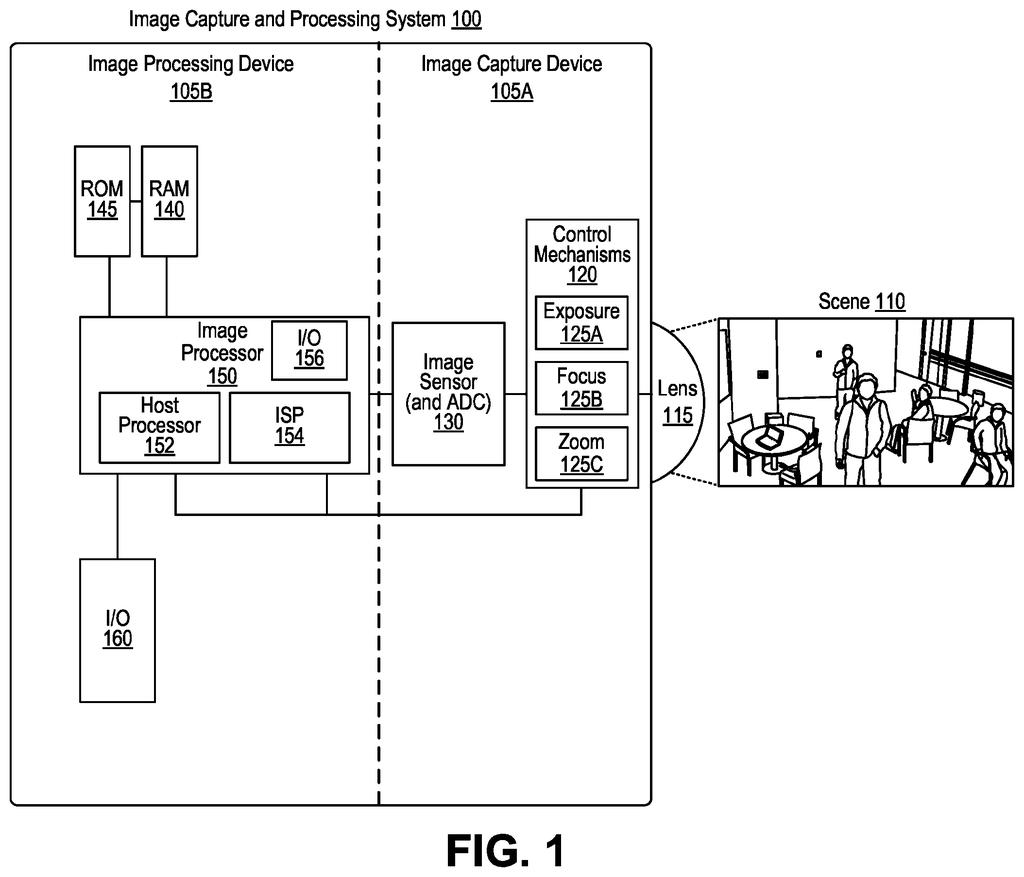
How Qualcomm spots objects without recognizing what they look like
Imagine you're watching a video of a busy street. A cat walks across the frame while everything else stays still. Even if you couldn't see the cat clearly, you could tell it was a separate thing just because it moved differently from the background.
That's roughly the idea behind this Qualcomm patent. A system takes two images captured in quick succession, looks at how the pixels have shifted from one to the other, and uses those movement patterns to identify individual objects. Things that move together are probably part of the same object; things that don't move are probably background.
This approach leans on motion cues rather than color or texture recognition. That could be useful in low-light scenes where a camera can't clearly see what something looks like, or in devices that need to process video quickly and cheaply without running a full image-recognition model.
… determining local motion between the first image and the second image for features of the first image and the second image; generating motion vectors based on the local motion; and identifying an object based on the motion vectors.
Translation: It tracks how specific parts of the picture move from one frame to the next to figure out what the object is.
How motion vectors turn frame differences into object outlines
The patent describes a method for identifying objects inside a video or image sequence using motion vectors (arrows, essentially, that describe how far each part of an image has shifted between two frames).
The process works in four steps:
- Capture two images from one or more sensors, taken at slightly different times.
- Calculate the local motion between those images, meaning how individual regions or feature points have shifted position.
- Build motion vectors from those calculations, which encode the direction and size of movement for each part of the scene.
- Use patterns in those vectors to decide which pixels belong to the same object and which belong to something else or the background.
The title references graph cuts, a technique borrowed from optimization math where you draw a boundary between two groups (here: object vs. Not-object) by finding the cheapest way to split a network of connected points. Applied to video, it's a way to cleanly separate moving objects from their surroundings using the motion data rather than raw pixel appearance.
The phrase object-centric representation learning in the title signals that the broader goal is training an AI model to understand scenes as collections of distinct objects, not just one big grid of pixels.
What motion-based object detection means for cameras and AI chips
For users, the practical upside is video AI that works better in conditions where appearance-based recognition struggles: dark scenes, blurry footage, or objects that look similar to their backgrounds. A security camera that can pick out a person moving through shadows, or an autonomous vehicle sensor that separates a cyclist from a busy sidewalk, could both benefit from this kind of motion-first logic.
Qualcomm's bet on on-device AI processing makes this relevant to the chips it sells for phones, cameras, and cars. Running object detection entirely from motion data is computationally lighter than running a full visual recognition model, which matters when the processing happens on a small chip rather than a cloud server.
Qualcomm's 14th filing in the AI vision work we've tracked since May adds to a run that includes one compressing visual data to codes and one skipping unchanged frames.
The core technique here is software, not new silicon, which shortens the path to a real product considerably. A phone camera already captures the images; this method would layer on top of existing hardware to pick out moving objects by analyzing how pixels shift between frames.
The gap between this filing and a finished feature is still real. The document describes four steps at a high level, and the hard work, making it fast enough to run without draining a battery, handling a shaky hand or tricky lighting, sits outside what is claimed here.
The shortest route to a product would likely be a narrow use case first, something like cleaner background separation in video calls, where the system only needs to work well enough in controlled conditions rather than everywhere at once.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
10 drawing sheets from US 2026/0278988 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →