
Microsoft Patents an AI Training System That Adjusts Its Own Workload Mid-Run
Training an AI model usually means pooling all your data in one place. Microsoft's new patent describes a way to skip that step entirely, and have the system figure out when it has learned enough.
How Microsoft trains AI without touching private data
Every time a hospital, bank, or government agency wants to use AI, they face the same wall: the data that would make the model useful is too sensitive to share. So the model never gets trained on the real stuff, or the organization takes on enormous legal risk to make it happen.
Microsoft's patent describes a different setup. Instead of moving the data to the AI, you move the AI to the data. Each organization (called a "silo" in the patent) trains its own private copy of the model on its own data. Only the lessons learned, not the raw data, get sent back to a central coordinator. The coordinator then combines those lessons into one improved model.
The part that stands out is that the system watches its own progress. If the model is performing well enough, it stops training early. If it still needs work, it adds more rounds automatically. You get a smarter model without anyone having to babysit the process or tune it by hand.
… aggregating the learnable parameters information obtained from the plurality of second silos to obtain a primary instance of the machine learning model that has been fine-tuned according to the learnable parameters information.
Translation: It combines updates from different data sources to create a refined main model.
How the pipeline adds or drops training rounds automatically
The system is built around a concept called federated learning (training a shared AI model across many separate locations without centralizing the underlying data). Microsoft's implementation adds an orchestration layer on top of the basic idea.
Here is how it flows:
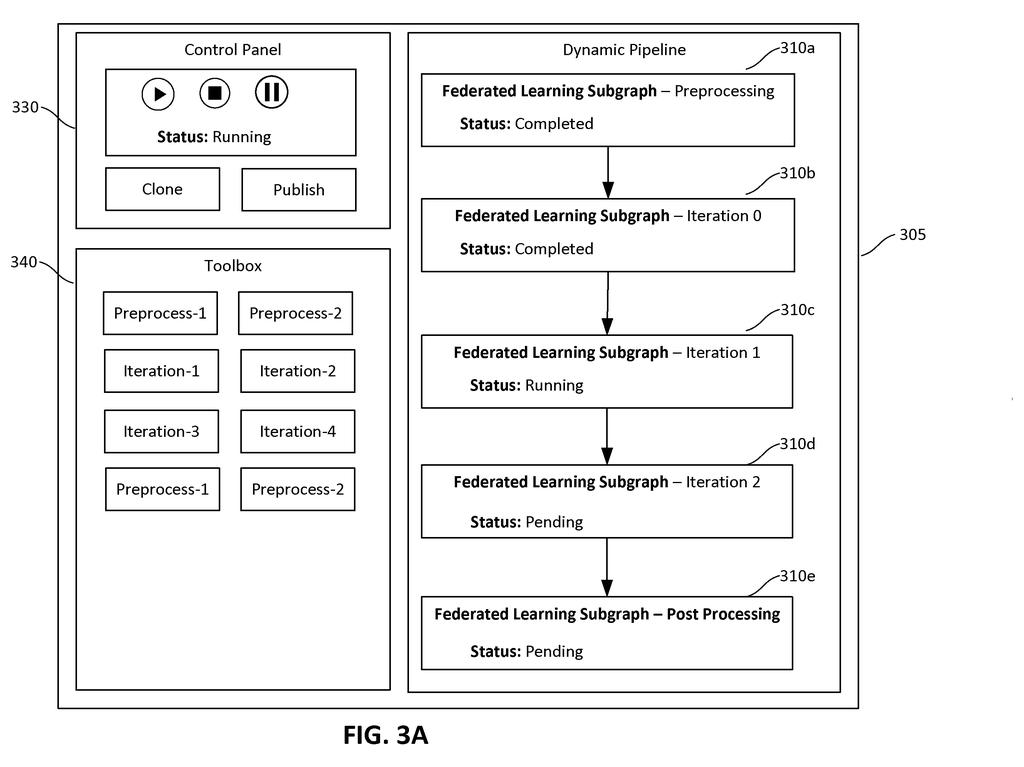
- A first silo (the central coordinator) receives configuration settings and automatically generates a training pipeline, a step-by-step schedule of tasks for all participants to follow.
- Each second silo (a hospital, a branch office, a regional server) runs that pipeline on its own local data, training a local copy of the model without sending any raw data out.
- Each silo sends back only its learnable parameters (the numerical weights the model adjusted during training, not the data itself). The coordinator merges all of these into one combined model.
The key claim in the patent is the self-adjusting loop. After each round, the coordinator checks the combined model against reference output data (a set of known correct answers used as a benchmark). If the model hits the performance target, the system automatically drops the remaining training rounds. If it falls short, the system automatically adds more. This prevents both wasted compute and under-trained models.
What this means for AI trained on sensitive data
For anyone whose data sits inside a regulated industry, such as health records, financial transactions, or government files, this kind of system is the difference between being able to use AI at all and being locked out of it. The model gets trained on real-world data without that data ever leaving the building. That is a meaningful shift in what is practically possible.
The self-adjusting pipeline also matters for the people running these systems. Right now, deciding how many training rounds an AI needs is largely guesswork followed by manual tuning. A system that monitors its own performance and adjusts automatically reduces that burden, and makes the whole process less likely to produce a model that was trained too little to be useful or too long to be cost-effective.
Microsoft lands its seventh filing we've tracked since August in the on-device AI privacy watchlist, following earlier applications on voice without identity and ads without identity.
Federated learning has been a live area of AI research for years, and what Microsoft is adding here is automatic pipeline management: a layer that watches whether the model is actually improving and adjusts the training process without a human stepping in.
For someone using a product built on this, the concrete benefit is an AI tool that stops failing. Tools trained on fragmented or incomplete data give wrong answers on edge cases, work well for some users and poorly for others, and require constant manual retraining to stay useful. A system that self-corrects its own training depth is designed to prevent exactly those frustrations before they reach the user.
Most people will never see this infrastructure directly. But Microsoft's bet is that enterprise AI products only get trusted when the plumbing underneath them actually holds, and this patent is aimed squarely at that foundation.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
10 drawing sheets from US 2026/0278483 A1 · click any drawing to enlarge


Show the other 2 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in