
IBM Patents a Way to Search Databases With Plain-English Questions
Most databases speak only one language: rigid code that takes years to learn. IBM has filed a patent describing a system that trains an AI to accept plain-English questions and translate them into real database results, no SQL required.
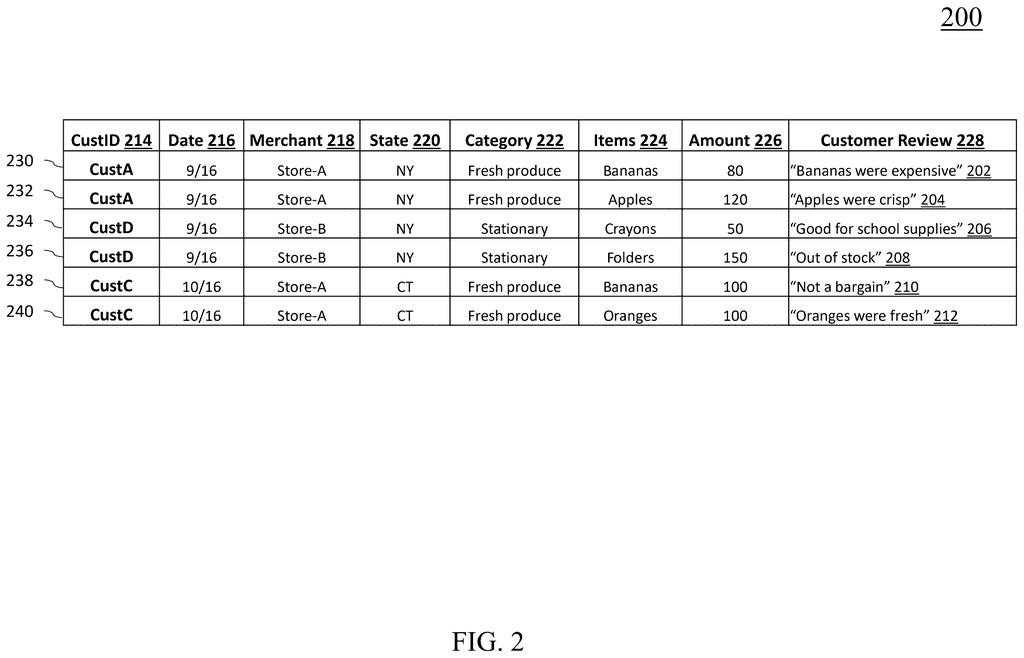
How IBM wants plain questions to replace database code
A company's customer records sit locked inside a database. Only the people who know how to write precise code commands can ask it questions. Everyone else has to wait in line for a developer's help, or make do with pre-built reports that never quite cover what they actually need.
IBM's patent describes a system that bridges that gap. It takes the raw text entries already inside a database, runs them through an AI model to figure out what they mean, and then uses those insights to train a second AI that can answer natural-language questions. You type something like "which customers complained about shipping delays last quarter" and get back a clean, structured answer.
The key step is automatic labeling: the system reads your database entries, generates numerical "fingerprints" called embeddings that capture the meaning of each entry, and uses those to assign category labels. Those labeled entries then teach a machine learning model to handle new queries without a programmer writing custom code every time.
… reading a query for the relational database, wherein the query comprises at least one of a query language code segment and a natural language prompt characterizing a database operation; performing the database operation using at least the first machine learning model; and returning a response to the query as a structured result.
Translation: The system accepts plain English questions or code, runs the request through its model, and gives back a structured answer.
How the encoder labels entries and trains the query model
The patent describes a multi-stage pipeline for making relational databases queryable in plain English.
Stage one: encoding. Every text entry in a database table is fed into an encoder model (an AI that converts text into numerical vectors, called embeddings, that represent meaning rather than just words). Two entries with similar meanings end up with similar vectors, even if the wording differs entirely.
Stage two: labeling. The system clusters or categorizes those embeddings to assign a label to each database entry. Think of it like automatically sorting an unmarked pile of customer notes into buckets: complaints, compliments, shipping issues, returns. No human has to hand-label the data.
Stage three: training. The labeled entries are written into a new training table inside a copy of the database. A first machine learning model is trained on this labeled data so it understands the structure and meaning of what's stored.
Stage four: querying. When a user submits either a plain-English prompt or a formal query-language command, the trained model interprets the request, performs the appropriate database operation, and returns a structured result. The claim covers both natural-language prompts and traditional query syntax, so the system can serve technical and non-technical users from the same interface.
What this means for workers who can't write SQL
For most organizations, getting answers out of a database still requires a developer or data analyst in the loop. That bottleneck slows decisions and keeps useful information out of the hands of the people who actually need it. A system like the one IBM describes could let a sales manager, a nurse, or a supply-chain planner ask real questions in plain English and get reliable answers without waiting on IT.
IBM's track record in enterprise AI patents suggests the company is targeting large organizations that run structured databases but employ far more non-technical staff than developers. Whether this particular approach proves reliable enough for production use is a harder question, but the direction is clear: make the database answer to you, not the other way around.
IBM's 39th filing we've tracked in Language AI since May adds to a run that includes one tracing AI text origins and one tailoring prompts to each user.
The person who benefits most is the one who always had to wait for someone else to pull a report. Instead of sitting on a question for two days while a specialist translates it into database code, they type it themselves and get an answer.
What makes this practical is that the system reads the existing text and figures out its own categories, rather than requiring a team to manually sort through thousands of examples before anything works. That shortens the path from "we have a lot of data" to "we can actually use it" considerably.
The real risk is that a wrong answer delivered in a clean, organized table feels like a right one. Small errors hide inside confident-looking results, and the burden of catching them still falls on whoever asked the question.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
4 drawing sheets from US 2026/0300325 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in