
IBM Patents a System That Teaches Itself to Produce Cleaner, Readable Code
Moving code from one programming language to another is notoriously messy work, and automated tools often produce output that technically runs but is a nightmare to read. IBM's new patent tries to fix that by teaching a translation system to grade its own output and keep improving.
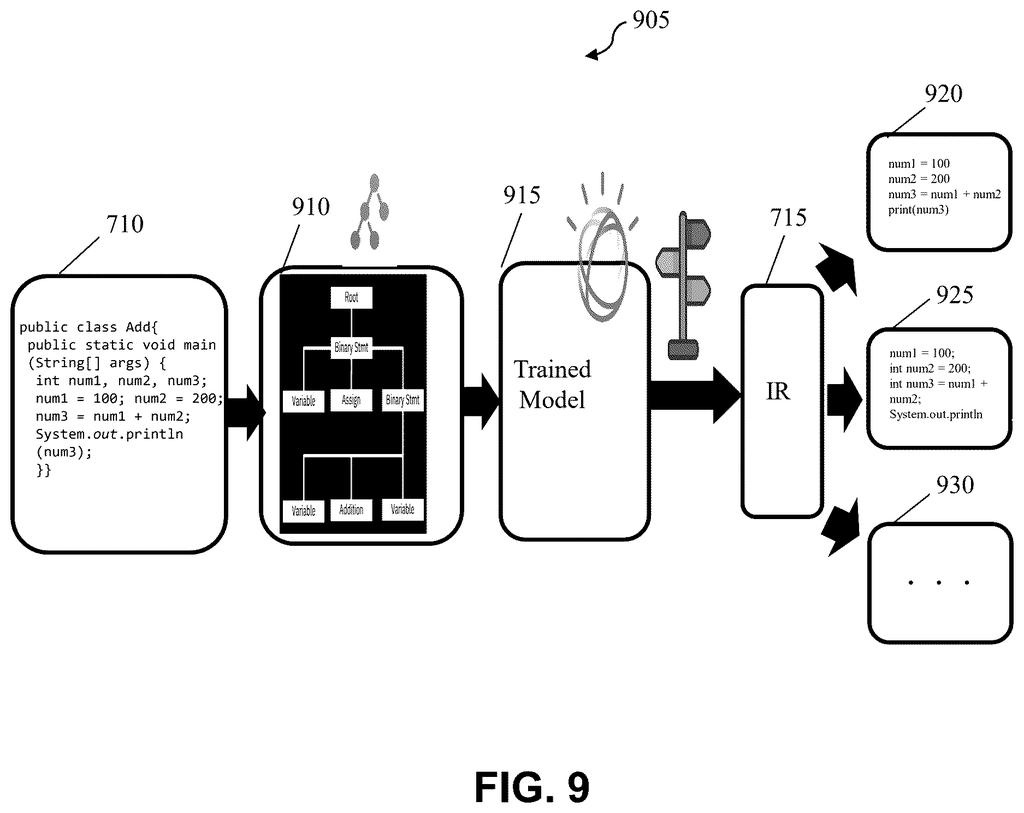
What IBM's self-improving code translator actually does
Converting software from one programming language to another, say from an older language like COBOL to a modern one like Java, is one of the most expensive headaches in the tech industry. The translated code often works but looks like it was written by a machine, because it was. That makes it hard for developers to maintain, debug, or build on later.
IBM's patent describes a system that doesn't just translate code mechanically. It also measures how readable and how complex the translated output is, then uses those scores to train itself to do better on the next attempt. Think of it like a student who gets a grade on each essay and uses that feedback to write a cleaner one next time.
The goal is code that doesn't just run correctly in the new language but is also tidy enough that your development team can actually work with it afterward, without spending weeks cleaning up the mess a basic automated tool would leave behind.
… building a reward model based on the first code readability and the first code complexity of the at least one source code and the second code readability and the second code complexity of the intermediate code; …
Translation: The system measures how readable and complex the original and intermediate code are to create a grading system.
How the reward model grades and guides each translation step
The system takes in source code written in one programming language and produces target code in a different language. The key difference from a standard code compiler is the addition of a learning layer that scores translation quality along the way.
Here's how the process works:
- The system receives the original source code and also examines an intermediate code representation, a halfway step between the source and the final output that many compilers produce internally.
- It measures two properties for both the source and the intermediate code: readability (how easy the code is for a human to understand) and complexity (how tangled or convoluted the logic is).
- Those scores are used to build a reward model, essentially a grading rubric the system applies to its own translations. Better readability and lower complexity earn higher scores.
- A reinforcement learning (RL) algorithm (a training method where the system learns by trial, feedback, and repetition, similar to how a game-playing AI learns to score higher) then trains the reward model to guide future translations toward cleaner output.
The trained reward model then works alongside a conventional code compiler to produce the final translated code. IBM's claim is that by optimizing for readability and simplicity, not just functional correctness, the output is more useful in practice.
… train the reward model by utilizing a reinforcement learning (RL) algorithm; translate the at least one source code by utilizing a code compiler and the trained reward model; …
Translation: It uses trial and error learning to train the system, then applies that knowledge to translate the code.
What this means for developers migrating legacy software
For companies sitting on large amounts of legacy software written in old languages, automated translation tools are already widely used, but the output quality is a constant complaint. Developers often spend as much time cleaning up machine-translated code as they would have spent rewriting it manually. A system that bakes quality metrics directly into the translation process could reduce that cleanup burden significantly.
IBM's long run of enterprise AI filings fits this patent squarely into the company's larger push to help big organizations modernize aging software. If this approach holds up in practice, the payoff for a developer isn't a flashier tool, it's simply less time doing tedious repair work after the automated translation runs.
That makes this IBM's 34th filing we've tracked in Language AI since May, adding to work like plain-English version search and prompt rewriting with company knowledge.
When a company moves its software from one programming language to another, the translated result usually works but is a nightmare to live with. The code runs, but the people who have to maintain it spend weeks just figuring out what it does before they can change anything.
IBM's approach teaches the translation system to grade its own output on clarity and simplicity, then use those grades to improve its next attempt. The practical effect is that a developer opening the translated code on a Monday morning has a reasonable chance of understanding it without a whiteboard session.
The real question is whether a machine-generated clarity score matches what an experienced developer would actually call readable. That gap is where maintenance costs hide, and whether this system closes it enough to matter will only become clear the first time someone has to update the output under deadline pressure.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
9 drawing sheets from US 2026/0259717 A1 · click any drawing to enlarge


Show the other 1 sheets

Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in