
Google Patents a Browser That Remembers Every Page You Visit and Lets You Search Them with Plain English
Google is patenting a browser that converts every web page you visit into a kind of personal searchable archive, so you can ask it questions about your own browsing history the same way you'd ask a person.
What Google's AI-memory browser actually does for you
A person opens a dozen tabs over the course of a day, reads half of them, closes a few, forgets most. Later, they can't remember which article had that specific statistic or which product page listed the return policy. That's the problem Google is trying to solve here, and it involves building a memory system directly into the browser.
The patent describes a browser that automatically converts the content of every page you visit into a format an AI can search and reason over. Instead of just keeping a list of URLs in your history, the browser stores the actual meaning of the content, so you can later ask something like "what did I read about sleep last week?" or "open that page where the price was under $50" and get a useful answer.
Vector database is the technical term for the memory system doing the heavy lifting here. Think of it as a filing cabinet where each page gets stored not as raw text but as a kind of fingerprint that captures its meaning, making it possible to find things by concept, not just by keyword.
… determining, using a vector database representing session data associated with the browser application, session data descriptive of at least one of: a web browsing history, or a current state of the browser application; …
Translation: The browser uses a specialized database to track everything you visit and what you are currently doing.
How the vector database turns web pages into searchable memory
The core idea is that as you browse, the browser feeds each page's content into a machine-learning model that converts it into a vector embedding (a list of numbers that encodes meaning and context, not just words). Those embeddings are stored locally in a vector database tied to your browser session.
When you type or speak a query, the browser doesn't run a keyword search. Instead, it converts your question into the same kind of numerical fingerprint, then finds stored content with similar fingerprints. This is how it can match the concept behind your question to pages you visited, even if your wording doesn't match anything on those pages.
- Session data storage: The database tracks browsing history and the current state of open tabs, not just URLs.
- Multi-modal search: The patent mentions searching across multiple types of content, meaning text, images, and potentially other formats.
- Sequence processing model: A language model (similar to the kind behind chatbots) takes your query plus the retrieved content and constructs an actual answer or browser action.
The output isn't always a text answer. The browser can also use the response to modify its own state, meaning it could navigate to a page, reopen a tab, or fill a form based on what you asked.
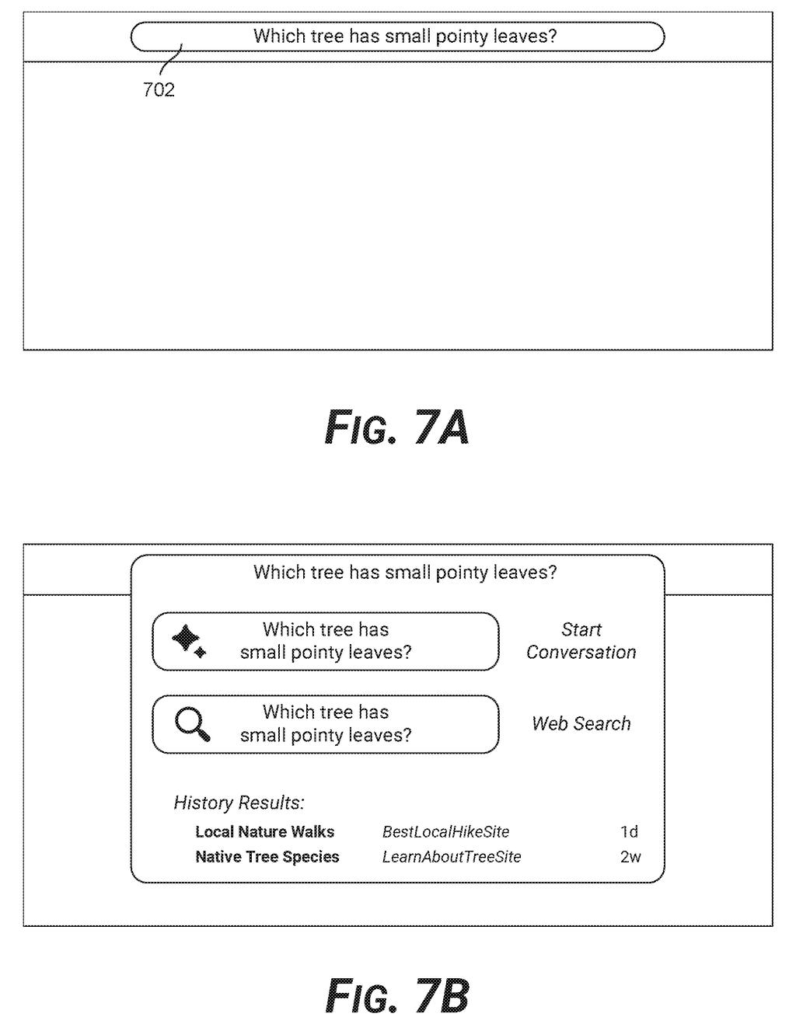
A user can query the web browser using simple instructions. The web browser can interpret the instructions and use the embedded data store to quickly search across multiple modalities of embedded data to retrieve relevant results.
Translation: You can ask the browser plain questions to instantly search your past web activity.
What this means for how you find things you've already read
If this ships in something like Chrome, it changes the basic relationship between you and your browser history. Right now, your history is a timestamp log that tells you what you visited but can't help you find what you actually learned or saw. A browser with this system would let you treat your own browsing the way you treat a conversation with a knowledgeable assistant, asking it things like "what were the ingredients on that recipe I found Tuesday" or "remind me what that article said about interest rates."
the pattern in Google's AI-in-everyday-tools filings points toward baking AI capabilities into products people already have open all day rather than asking them to switch to a new app. Whether this ever reaches a consumer release is a different question, but the direction is clear: the browser as a memory layer, not just a window to the web.
Google's 33rd filing we've tracked since May on AI assistants that remember you follows one on remembering shared images and one on learning formatting habits, adding another application for AI that holds onto personal details.
The person who benefits most from this is anyone who has spent ten minutes clicking through browser history trying to find an article they half-remember reading last week. A browser that lets you ask "what was that piece about urban farming I read Tuesday?" and actually answers correctly would solve a real, daily frustration.
The part the patent leaves open is where your browsing record actually lives. A database stored only on your own device is a very different thing from one that uploads to a server, and that distinction will determine whether most people feel comfortable turning this on.
Until Google shows what a real product looks like, the idea sits in a promising but unresolved place. The benefit is concrete and easy to imagine. The trust question is just as concrete, and it would have to be answered before most people say yes.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
26 drawing sheets from US 2026/0300422 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in