
Google Files Patent for Robots That Turn a Plain-English Request Into a Step-by-Step Plan
Google's filing teaches a robot to look at a room, read your request, and write itself a to-do list in plain English before it moves a finger.
What Google's robot-planning patent describes
Ever tried explaining a chore to someone who has never been in your kitchen? You wouldn't say "move your arm twelve inches left." You'd say "grab the eggs and crack them into the bowl." That everyday style of instruction is what Google is trying to give robots.
In this patent, a robot takes a picture of its surroundings, and you give it a task in ordinary words. An AI language model, the same family of technology behind chatbots, looks at both and writes out a short plan, like "crack egg, put egg in bowl."
A second program then turns each line of that plan into the actual arm and gripper movements. Because the middle step is plain language, you aren't stuck with a short list of approved command words.
… receiving an input text sequence that describes a task to be performed by a robot in the environment and that references the one or more objects in the environment; …
Translation: The system takes in a plain text command telling the robot what job to do around nearby items.
How a language model turns sight into steps
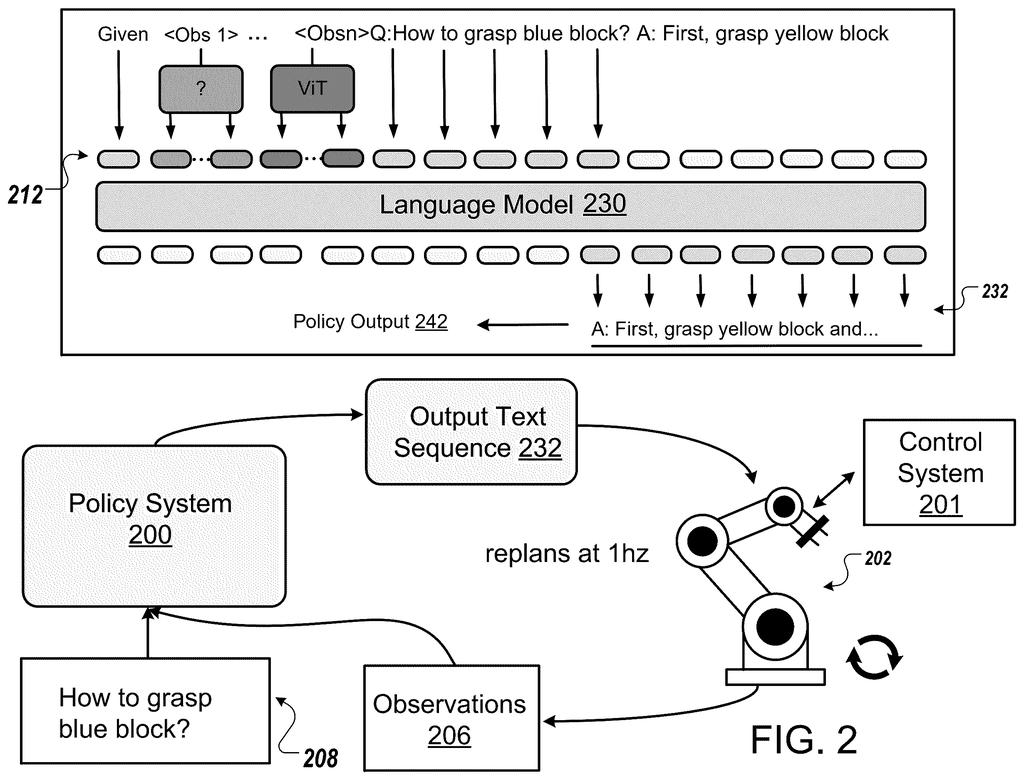
The system starts with two inputs: observations (mainly camera images, though the filing also allows data from force, proximity and other sensors) and a text description of the task that can mention objects in the scene. Both are converted into the same kind of numbers, called an embedding (a list of values that represents the meaning of a word or the content of an image). The images go through an image encoder, such as a vision Transformer (a type of AI model that reads images in patches).
Those numbers are strung together into one sequence of tokens (small numeric chunks the language model reads), sometimes interleaved, like "Given [image] Q: How to grasp blue block?" Extra tokens can be added too. Template tokens make the input look like what the model saw in its original training, and object referral tokens number each object so the model can tell apart, say, several identical blue blocks.
The language model then writes its answer one piece at a time (the claim calls this autoregressive generation). The answer is a high-level plan in plain text, such as "open the drawer and remove the ball from the drawer."
The plan is not what moves the robot. A separate learned module, called a policy network, converts that text into low-level actions: move the arm to the drawer handle, grasp it, pull outward. This repeats at each time step. For training, the filing describes teaching the model to predict the rest of a plan from a partial one, and says a pre-trained language model can be held fixed while only the image-reading parts are trained.
… processing the sequence of input tokens using a language model neural network to generate an output text sequence that comprises high-level natural language instructions; …
Translation: An AI language model reads the data to produce a clear, step by step plan for the robot.
What this means for helper robots at home
The practical payoff is a robot you can direct the way you'd direct a helper. Examples in the filing include "use all of the ingredients you see to make a cake batter" and an open-ended question about what a robot should do to be useful in a messy room. Nothing in the filing says a product is coming, but it shows how Google pictures household robots taking instructions.
The filing also says each plan holds several actions, so the system needs fewer rounds of decision-making than one that picks a single move at a time. It also describes the same setup answering questions about images, including drafting a report from a chest X-ray. That suggests Google sees this as a general way to connect pictures, words and decisions, with robots as one use.
Google's 50th filing we've tracked since May in our AI agents acting for you watch follows patents like speak a command via icon and a tool that researches big questions.
If you ever own a home robot, the first thing you'd notice is how you talk to it. A system built this way lets you say "clean up the table" or "make cake batter from what you see" without memorizing a menu of approved commands, which removes the most annoying part of talking to machines.
The detail that matters most for daily use is how the filing handles look-alike objects. Three blue blocks on a table would confuse a person giving vague directions, too. Numbering each object so the model can point at the right one prevents the wrong-item-picked-up mistake you'd otherwise hit all the time.
The filing gives no accuracy figures, so the paper can't tell you how often a kitchen robot would get your request right. As a design for making robots easier to talk to, it makes a clear and sensible case.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
8 drawing sheets from US 2026/0307248 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in