
Microsoft Patents a Way to Train AI on What You Actually Care About
Every time a recommendation engine serves you something irrelevant, it's essentially admitting it doesn't know you. Microsoft is filing patents on a training method that tries to fix that from the ground up, by teaching an AI to describe your interests in words that actually retrieve things you'd click on.
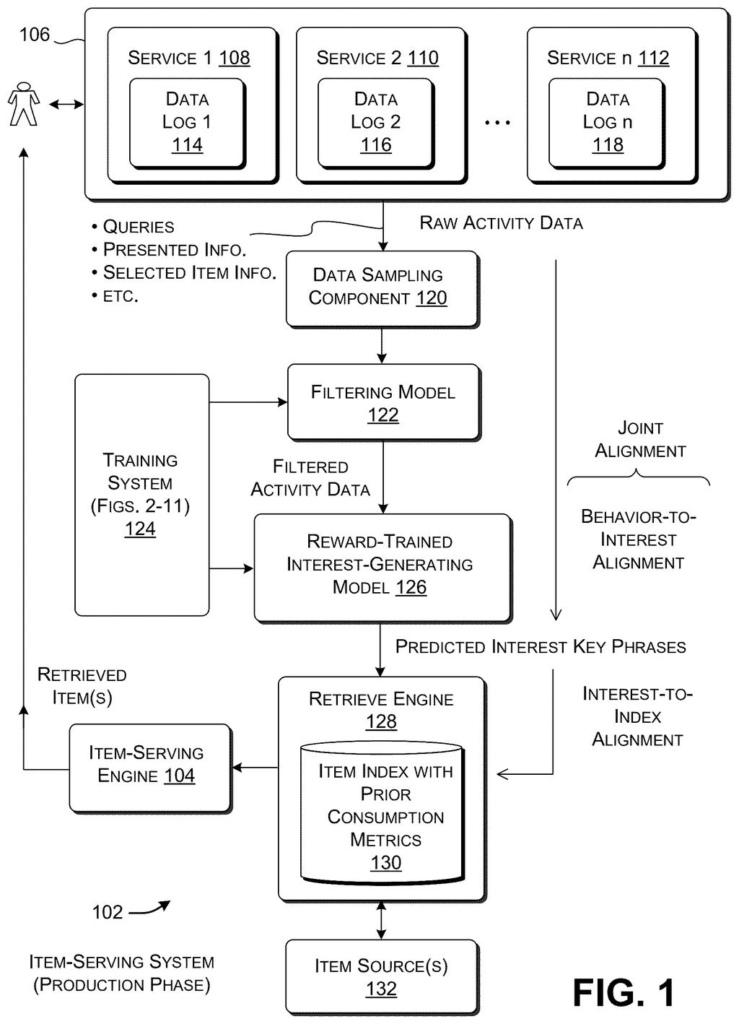
How Microsoft's interest-matching AI learns what to show you
Every time you scroll past a pile of recommendations you don't care about, you're watching a system fail at its one job. Recommendation engines are supposed to know what you like, but they often work from noisy, messy data about what you've done online, and that mess produces bad guesses.
Microsoft's patent describes a way to train an AI to build a cleaner picture of your interests. First, a separate filter model throws out the junk in your activity history. Then the system distills what's left into short phrases that describe what you actually care about. Those phrases get scored based on whether they successfully pull up content you'd actually consume. The AI keeps improving until its descriptions of your interests reliably find content you'd want to see.
The goal is a model that learns to speak the same language as the search index it's querying, so the bridge between "what this person likes" and "what items to serve them" stops leaking so much signal.
… filtering the initial activity data using a machine-trained filtering model to remove a subset of the initial activity data that represents noise, to produce filtered activity data …
Translation: An AI filter cleans up your raw usage history to remove random junk data.
How the reward system scores and refines interest phrases
The patent describes a three-stage training pipeline built around a concept Microsoft calls an interest-generating model, an AI that reads a user's activity history and produces short key phrases describing their interests (think: "trail running gear," "home espresso," "Python tutorials").
- Stage 1 - Noise filtering: Raw activity data (clicks, views, searches across Microsoft services) goes through a separate machine-trained filter that strips out interactions that don't reflect genuine interest, things like accidental clicks or one-off searches.
- Stage 2 - Phrase generation and scoring: The cleaned data is mapped to candidate interest phrases. A reward system (a scoring model) then evaluates each phrase, not on how well it describes the user, but on how well it retrieves items the user would actually consume when those items are served. This is a retrieval-oriented scoring approach, where success is defined by downstream behavior, not by human labelers.
- Stage 3 - Reward-based fine-tuning: The interest model is updated based on those scores, a technique similar to reinforcement learning from human feedback (RLHF) but driven by retrieval performance instead of human ratings. Over time, the model aligns the way it describes interests with the structure of the retrieval index it's querying.
The end result is a model whose interest phrases sit in the same conceptual space as the content index, meaning searches powered by those phrases are more likely to surface items a user will engage with.
… expressing the interests underlying the filtered activity data and (2) retrieving items from a retrieval engine that are likely to consumed when served, given the identified interests …
Translation: The system figures out what you want and pulls items you will actually look at.
What this means for recommendation feeds you use every day
Recommendation systems are among the most economically significant pieces of software on the internet. Ad revenue, content engagement, and subscription retention all ride on whether a feed shows you things you want. Bad recommendations aren't just annoying; they're expensive for platforms and wasted time for you.
Microsoft runs surfaces where this matters directly: the News feed in Windows, Bing's content recommendations, and Microsoft Start. A training method that produces sharper interest descriptions, ones tuned to actually retrieve clicked content rather than just describe a user's past, could measurably lift engagement on those platforms. For you, that would mean fewer "why is this here" moments in your feed and more content that feels like it was chosen by someone who read your mind.
Microsoft's 63rd filing in our language AI coverage since May adds to a run that includes finding better code references and translating code between languages.
Recommendation systems break down in a specific, costly way: the description of what you like rarely maps cleanly onto how a platform's own catalog is organized. That gap kills engagement at scale, and most people experience it as a streaming service that seems to have forgotten everything about them, or a news app that surfaces yesterday's headlines.
Microsoft's approach here ties the system's reward directly to whether a user actually reads or watches something, not whether they clicked. That tighter feedback loop forces the model to solve two problems together: filtering out the noise in your browsing history and learning to describe your interests in words the catalog can actually act on.
For a problem this pervasive and this expensive to platforms, an approach that addresses both the messy input and the retrieval mismatch in a single training process seems appropriately ambitious.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
12 drawing sheets from US 2026/0289394 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in