
New Apple Patent Shrinks AI Data on Chip Using Lookup Tables
Apple is patenting a way to make the weight data that powers AI models dramatically smaller inside its own chips, the kind of quiet engineering work that makes on-device AI faster without draining your battery.
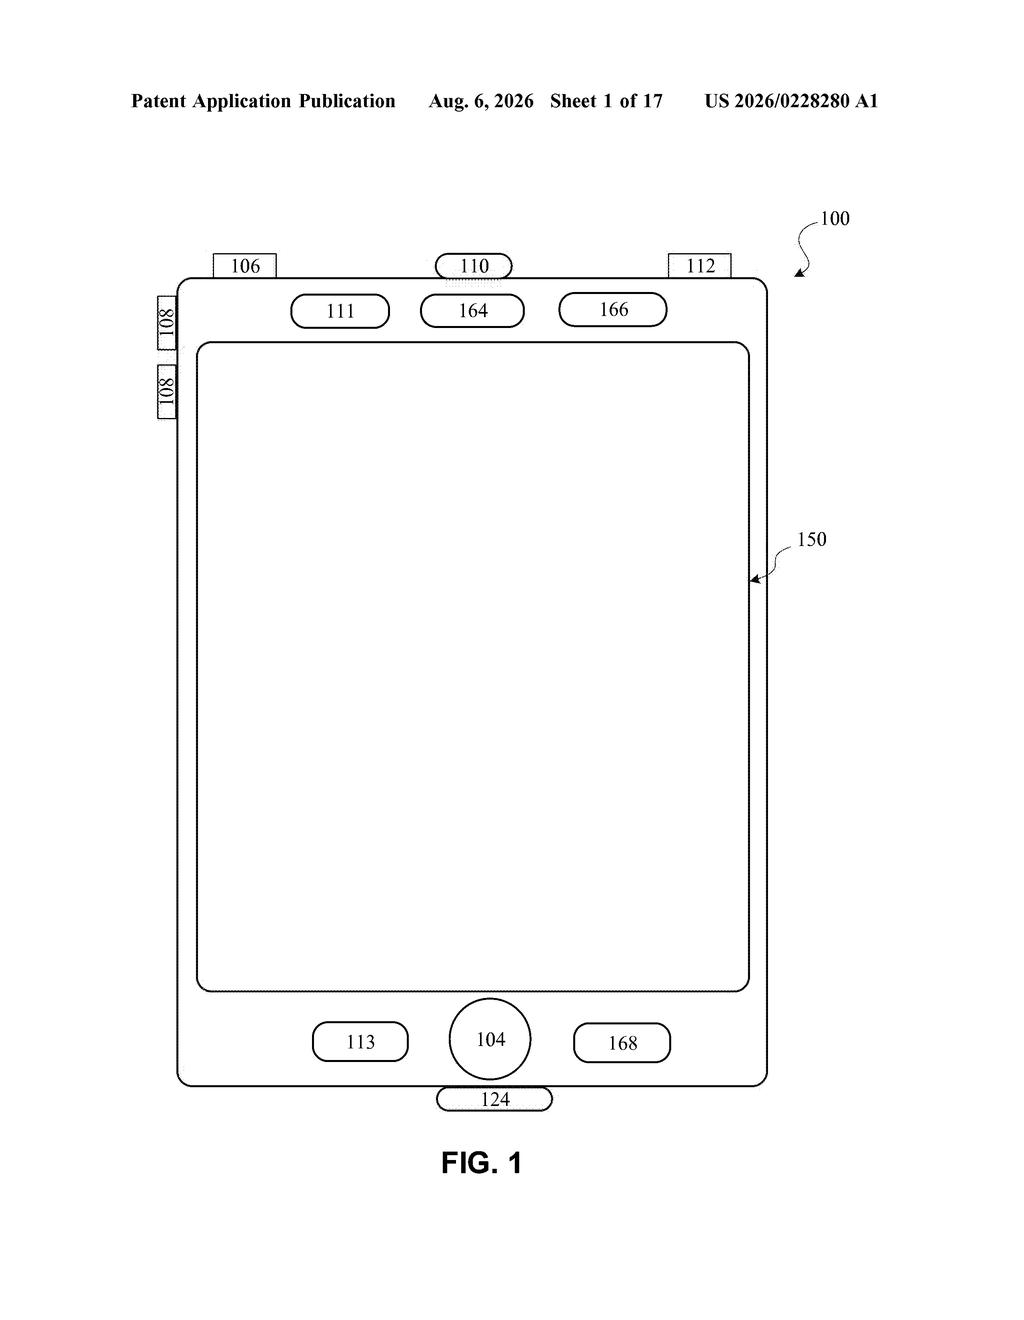
How Apple's chip squeezes AI model weights into tiny tables
Imagine a recipe book where instead of writing out every full ingredient list for every dish, you just write the list once and give each dish a short code pointing to it. Apple's patent does something similar for AI models running on your iPhone or Mac.
AI models are made up of millions of numbers called weights (or kernels) that the chip has to fetch and process constantly. The more of those numbers there are, the more memory and power the chip burns. Apple's idea is to replace those long lists of numbers with a small lookup table, a kind of shared codebook, plus a compact set of index codes pointing into it.
The clever part is that two different groups of AI processing lanes get their own separate lookup tables, so each group can still produce accurate results even though the raw data it's working from is far smaller than before. Less data to move around means the chip can work faster and more efficiently.
… a kernel extract circuit configured to: extract the first LUT and the index data from the kernel data and assign the first LUT and the index data for computing outputs of output channels of a first output channel group (OCG) …
Translation: A special circuit extracts lookup tables and indexes to calculate outputs for different groups.
How the kernel extract circuit assigns LUTs to output channel groups
The patent describes a neural processor circuit, the dedicated AI chip hardware found in Apple's A-series and M-series chips, that compresses AI model weights using a technique called palettization (similar to how image editors reduce colors to a fixed palette).
Instead of storing every weight value in full, the system stores a small lookup table (LUT) containing only the most important representative values, plus a list of short index codes (think: pointers) that say "use entry #3 from the table" instead of writing out the full number every time. Two separate LUTs can be loaded at once.
The kernel extract circuit inside the neural engine then does the following:
- Pulls the first LUT out of the compressed kernel data and hands it to a first group of output channels (processing lanes) along with the shared index list.
- Pulls the second LUT out and hands it to a second group of output channels, again using the same shared index list.
- Each group reconstructs the full weight values it needs on the fly, just before computing its results.
The net effect is that the chip fetches far fewer bytes from memory to do the same AI computation, which reduces memory bandwidth pressure (how fast data must flow to keep the chip busy) and lowers power draw.
Embodiments of the present disclosure relate to a neural processor circuit including a kernel access circuit and at least a neural engine circuit including output channels.
Translation: The patent describes a specialized chip processor designed to handle artificial intelligence tasks.
What this means for on-device AI speed and memory use
On-device AI is only useful if it runs fast enough and doesn't flatten your battery. The bottleneck today is almost never raw compute, it's the time and energy spent moving weight data from memory to the processor. A system that shrinks those weights with lookup tables directly on the chip, without needing software to do anything special, attacks that bottleneck at the hardware level.
For you as a user, the practical result could be AI features (think live translation, photo analysis, or on-device Siri requests) that respond faster and chew through less power. For Apple, it means squeezing more capable AI models into devices where memory is constrained, like an Apple Watch or a future pair of AR glasses, without redesigning the chip from scratch.
This is dry chip architecture work, but it's exactly the kind of patent that determines whether Apple's on-device AI story is real or just marketing. Palettization of neural network weights is a well-known compression technique, so the novel angle here is the two-LUT-per-engine-pass hardware implementation. If Apple ships this in a future Neural Engine revision, the gains would touch every AI feature on every device simultaneously.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Apple patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
17 drawing sheets from US 2026/0228280 A1 · click any drawing to enlarge


Show the other 9 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →