Big Tech's AI Chip Wars: Every Patent Filing in One Race, and where it's headed
This watchlist tracks patents on the plumbing of AI chips: memory bottlenecks, task scheduling, data compression, and coordination across multiple chips. Together, they show that competition in AI hardware is shifting toward how chips move and share data, rather than raw computational speed.
295 filings
· tracking since May 2026 · latest Sep 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
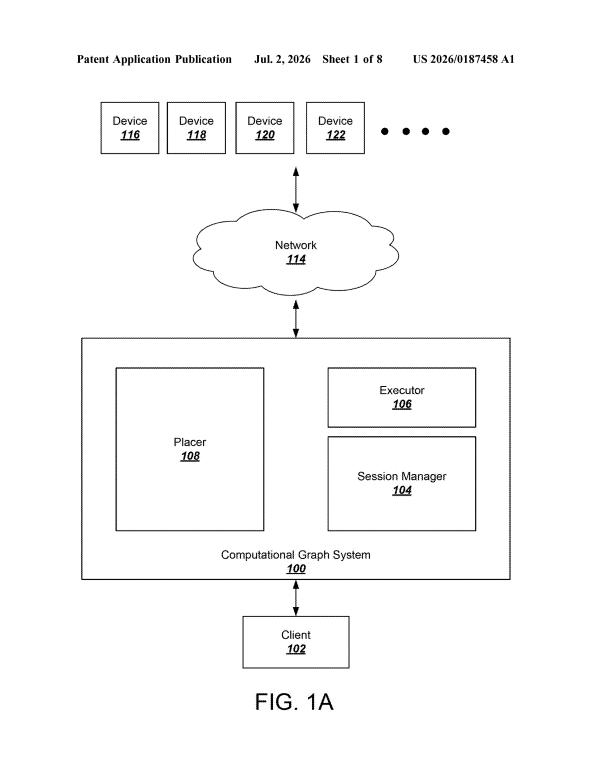
This fight is over who controls the building blocks of AI computing: how chips store data, share work, save power, and run math faster without wasting space or energy.
Samsung and Qualcomm carry the most weight here by filing count, with Samsung leaning into memory and chip design and Qualcomm pushing hard on power-saving and mobile AI.
What’s new in the AI chip wars
a dated entry each week this watchlist moves · older entries stay archived
Sep 17, 2026 24 filings joined
Qualcomm and Samsung led this week with the most filings, focusing on splitting AI work across chips and managing memory under pressure. Power sharing, data rerouting, and running leaner AI on phones were the clearest common threads.
Samsung and Intel led this week's filings, with Samsung focused on compressing and streamlining how AI reads and stores data, and Intel on routing tasks to the right chip faster. The common thread across most companies is doing more AI work with less power and fewer steps.
Nvidia leads this week with four filings focused on how code runs across processors and how to skip unnecessary work at runtime. Intel and Sony each added two filings, with Intel focused on cutting wasted space and memory in AI chip design, and Sony on managing power and connections between chips.
Aug 27, 2026 30 filings joined
This week's filings center heavily on making AI chips faster while using less power, covering everything from smarter memory handling to shrinking math shortcuts. Intel and Samsung led the pack in volume, while Nvidia and Qualcomm each pushed hard on cutting wasted work during AI processing.
Aug 20, 2026 24 filings joined
Most filings this week focus on helping chips do more AI work while using less memory and power. Qualcomm filed the most patents, covering memory sharing, data compression, and keeping calculations fast.
Who’s filing patents in the AI chip wars
counts from tracked filings · focus read from each company’s own filings
the fights inside the fight · each with its three newest filings · new filings join every week
Shrinking AI Models for Small Chips 36 filings
Samsung 9, Qualcomm 8, Nvidia 6
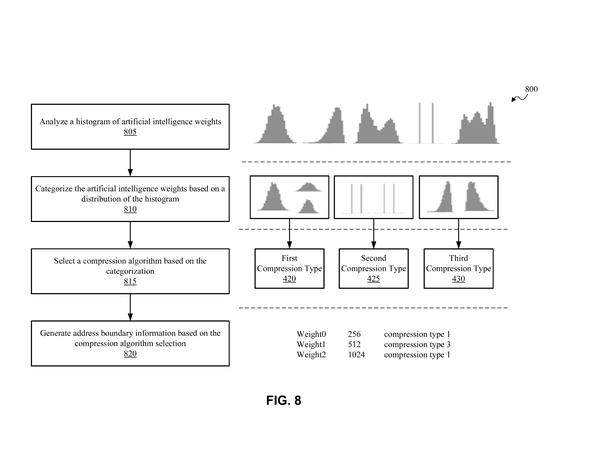
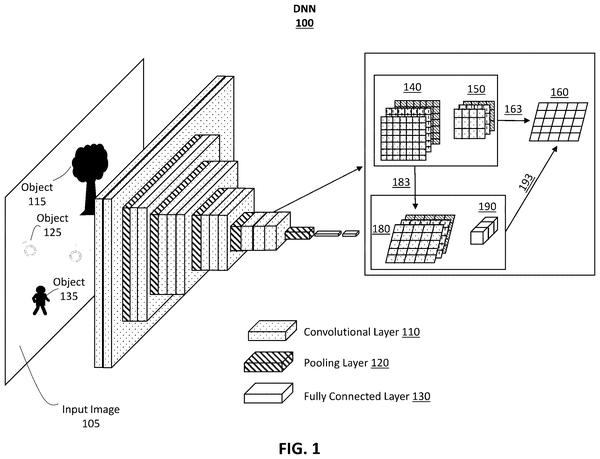
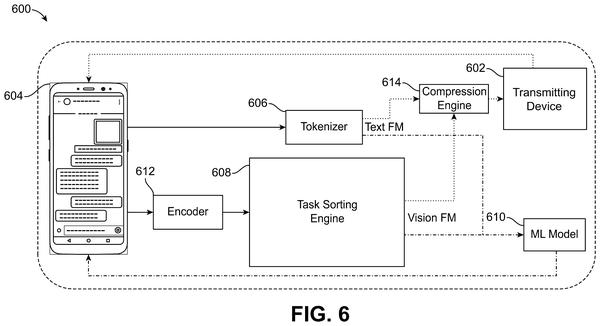
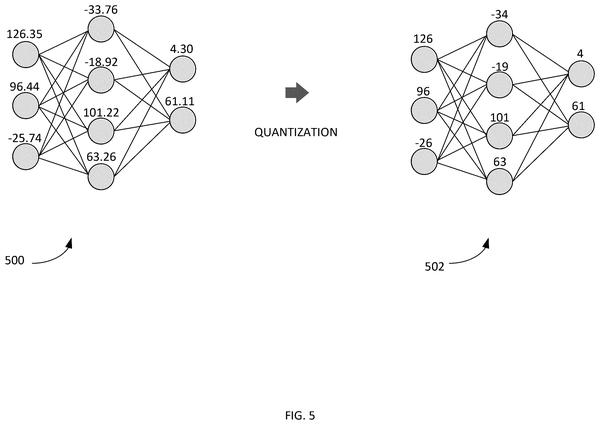
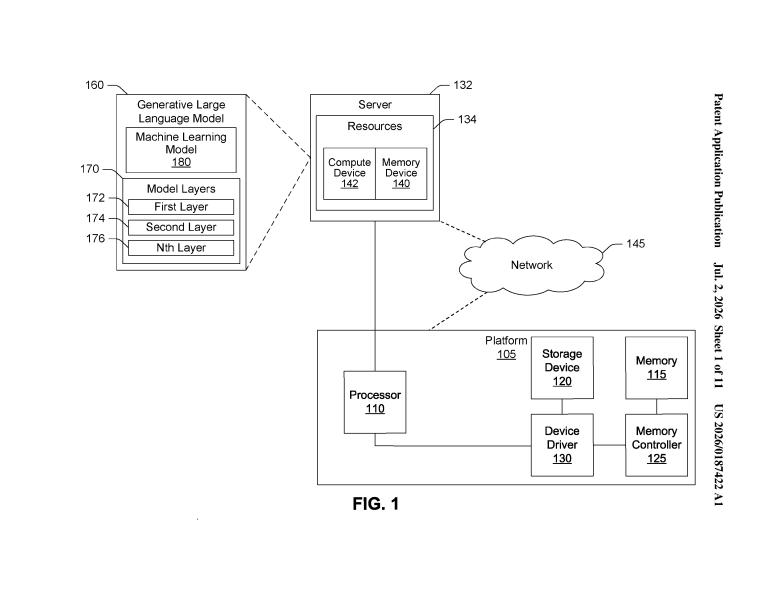
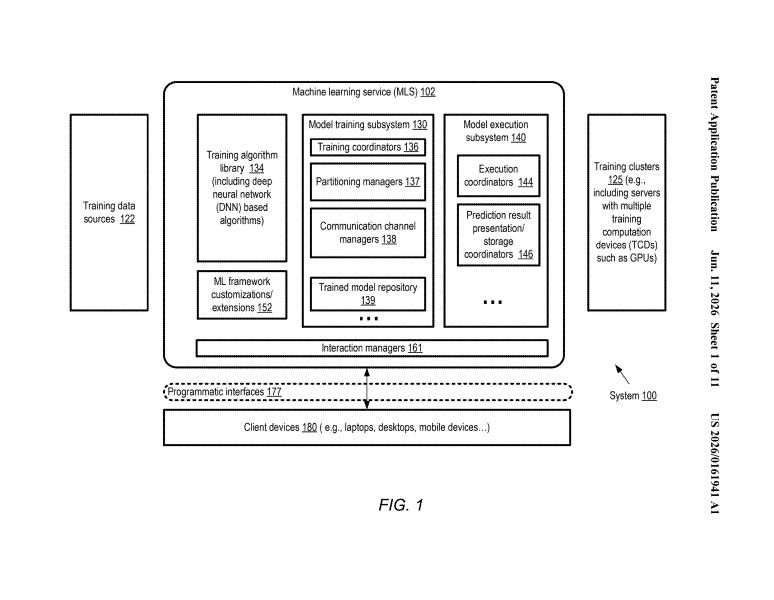
Several companies are filing patents on ways to compress AI models so they run on devices with less memory and power. Qualcomm, Samsung, Nvidia, Apple, AMD, and Intel are all pushing different approaches to cut model size without losing accuracy.
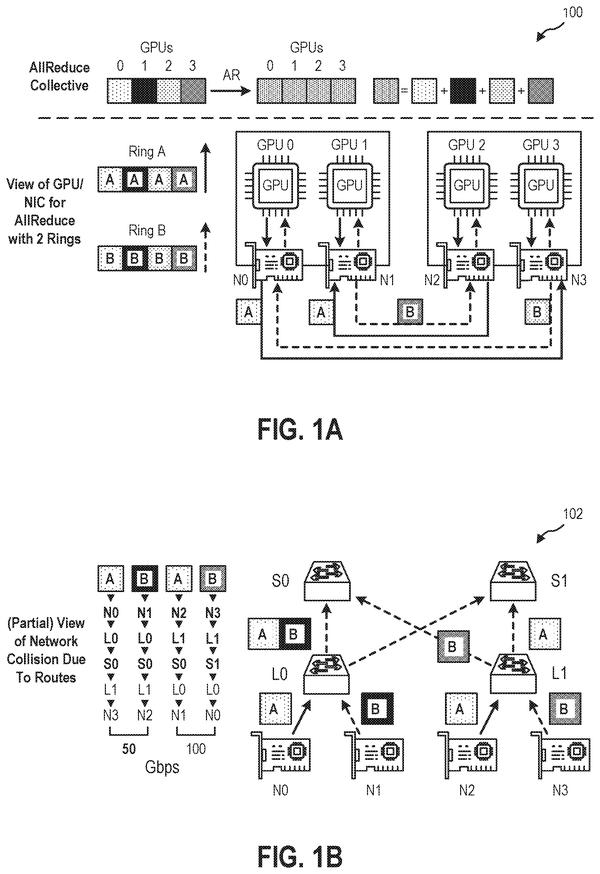
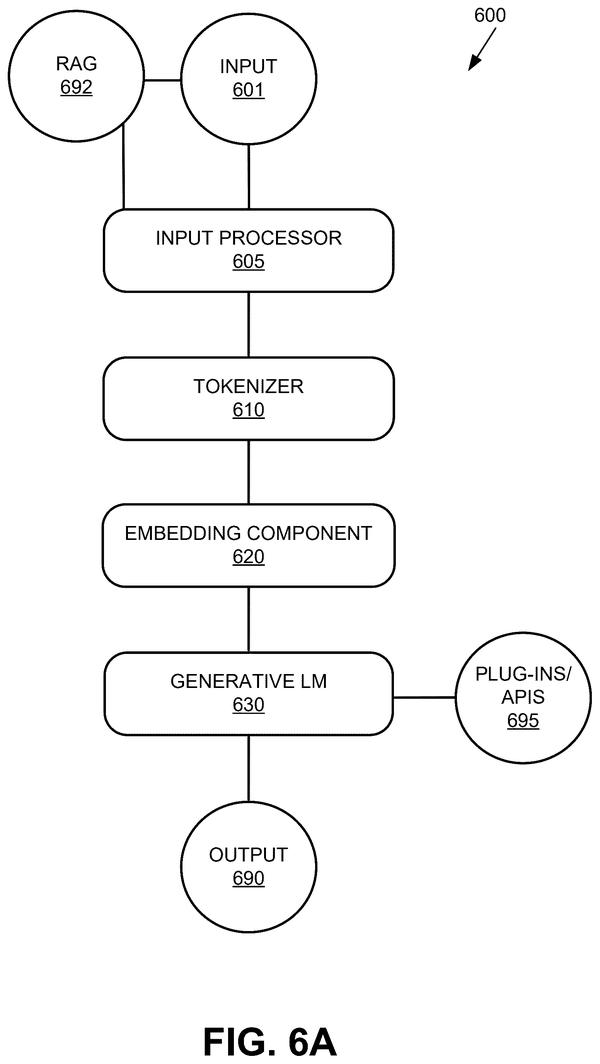
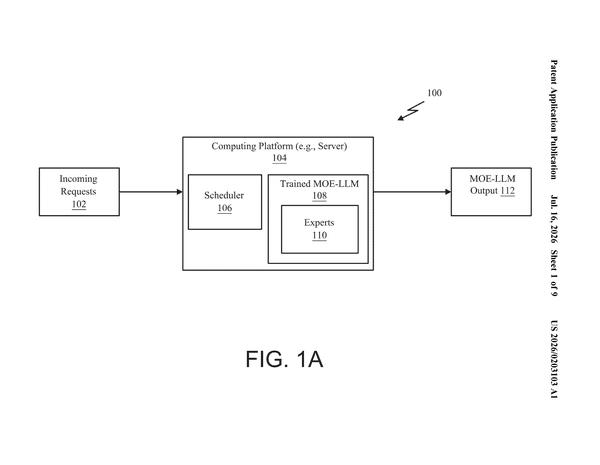
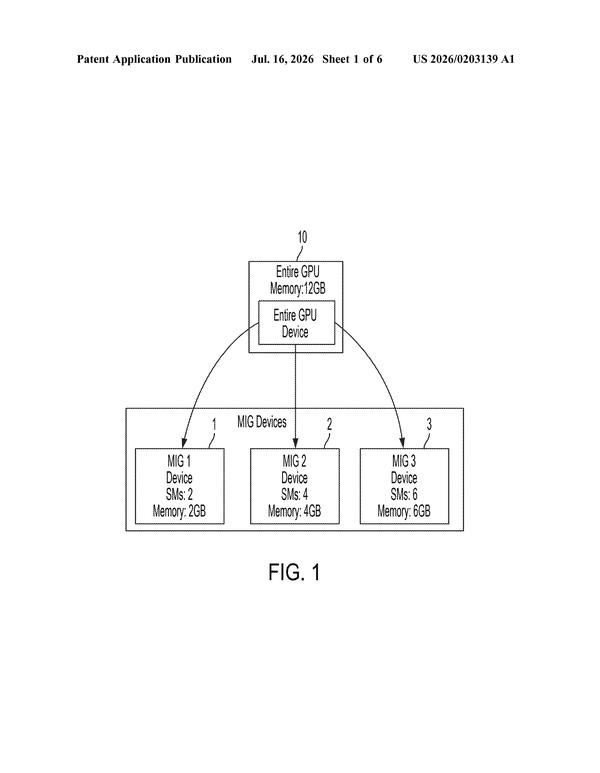
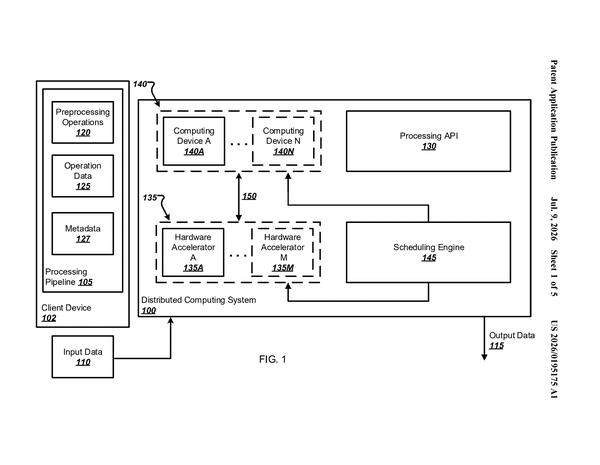
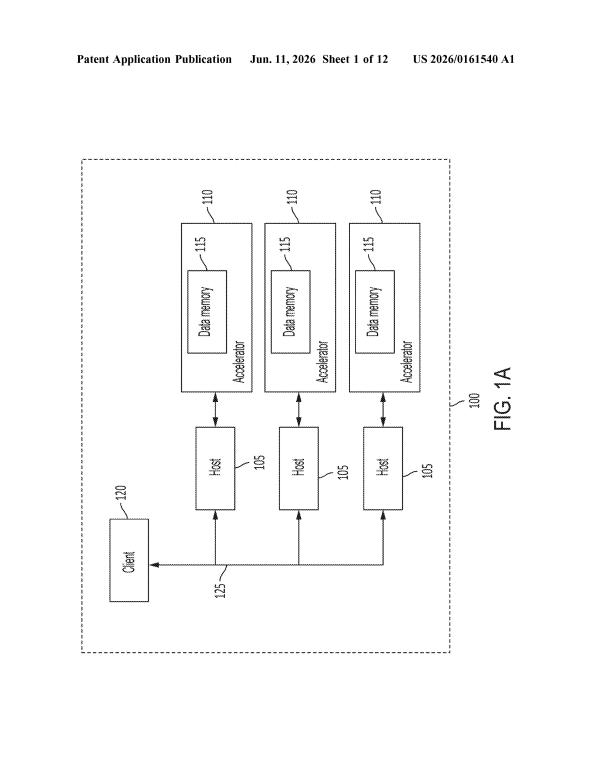
Companies are racing to file patents on ways to break AI tasks into pieces and spread them across different chips, processors, or even separate devices. IBM, Qualcomm, Microsoft, Samsung, Intel, Google, and Nvidia are all staking ground here.
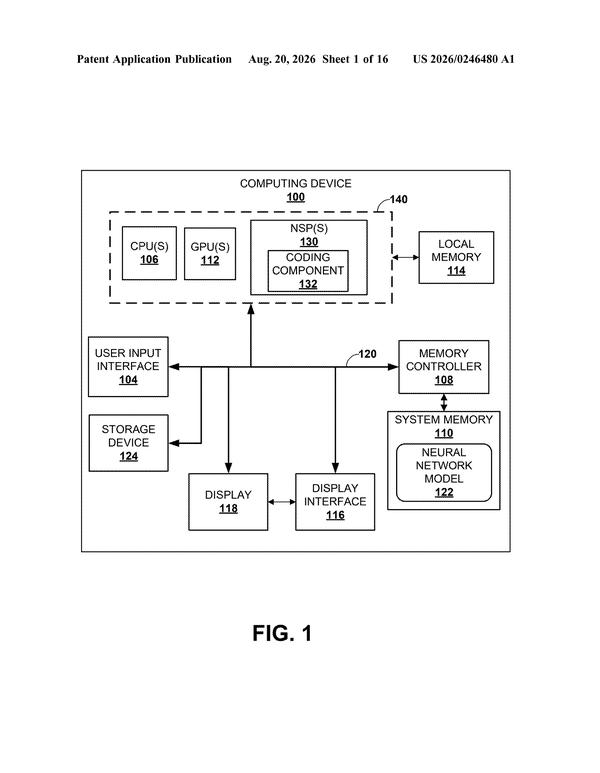
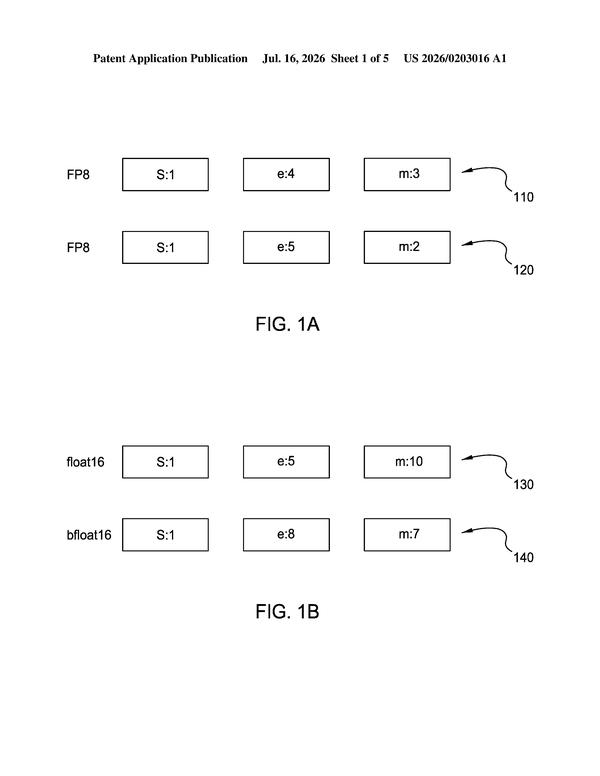
A large cluster of patents targets the core arithmetic inside AI chips, finding ways to run calculations using fewer steps, smaller numbers, or pre-calculated shortcuts so chips burn less energy. AMD, Intel, Qualcomm, Nvidia, and IBM are the most active here.
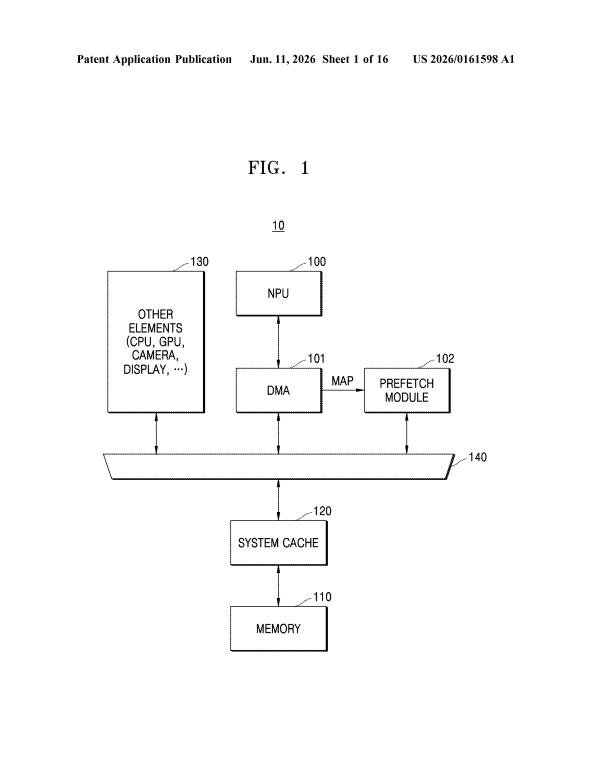
Patents in this thread focus on predicting what data a chip will need next and loading it early so the processor never sits idle waiting. Samsung, Intel, Nvidia, IBM, and AMD are all filing on this problem.
Several companies are filing patents on systems that decide in real time whether to run AI on your device or send it to a remote server, and how to hand work back and forth quickly. Microsoft, Qualcomm, Amazon, and Google are the main players.
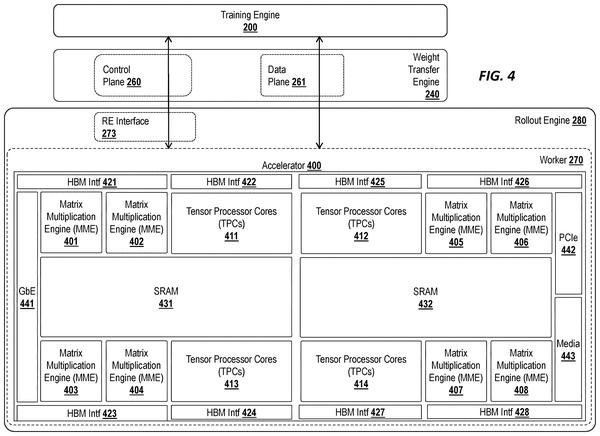
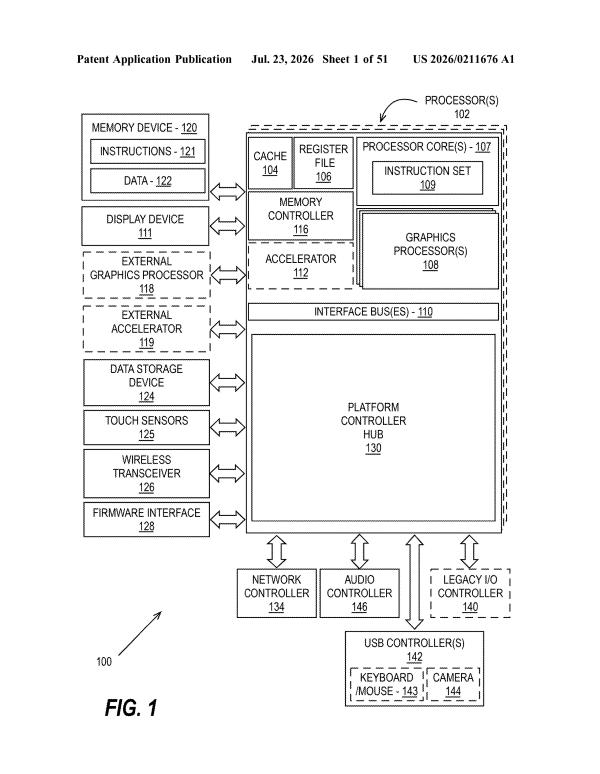
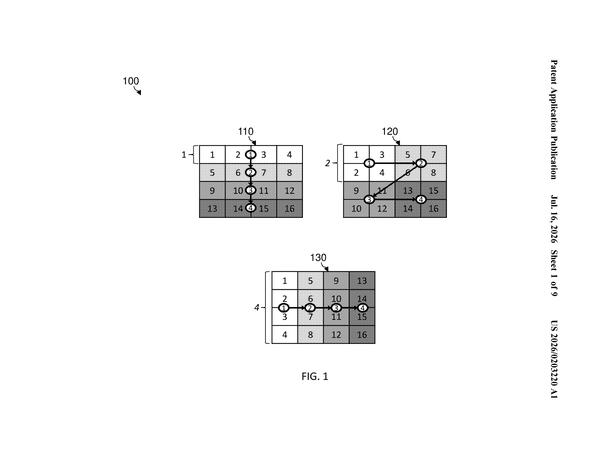
This thread covers patents on how chips store, move, and access data without creating bottlenecks that slow AI down. Samsung, Intel, Nvidia, IBM, and Qualcomm are all filing on different parts of this problem.
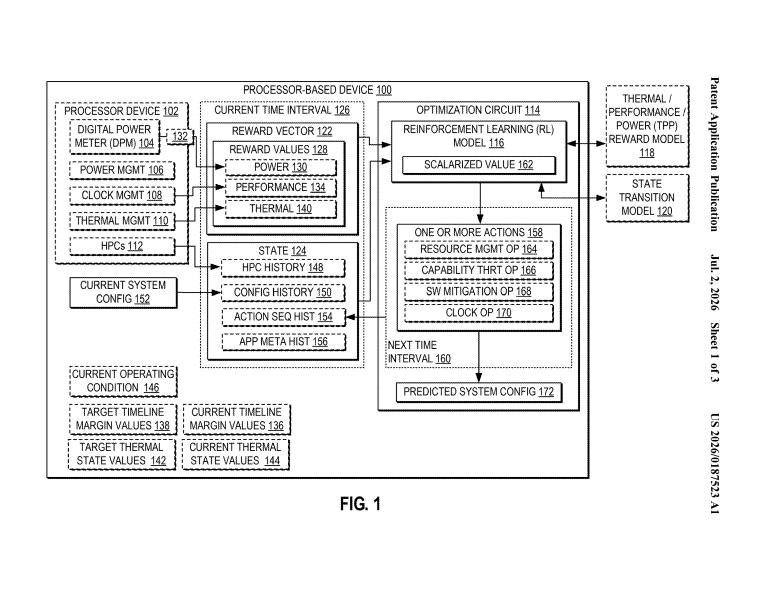
These filings decide how much power a chip gets, when it sleeps, and how it avoids overheating. Qualcomm, AMD, Samsung, Nvidia, IBM, Google and Microsoft all have a hand in it.
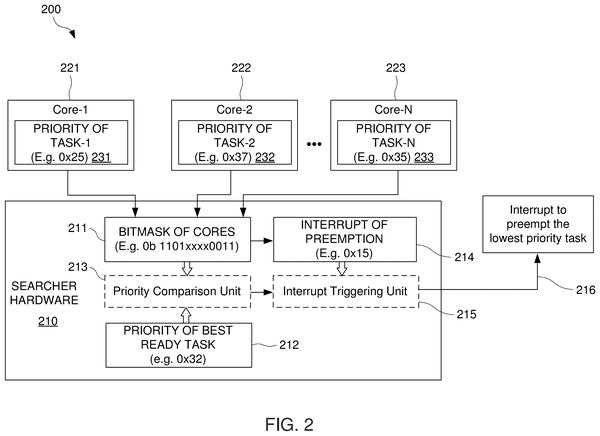
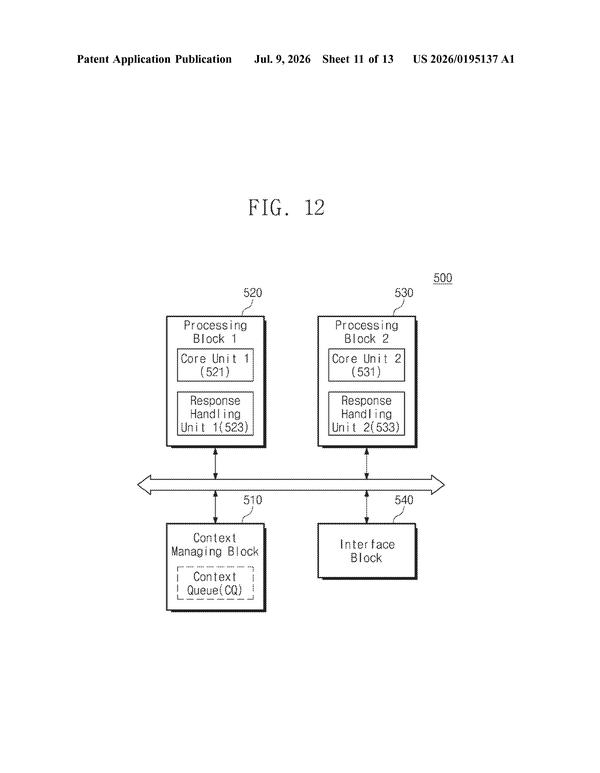
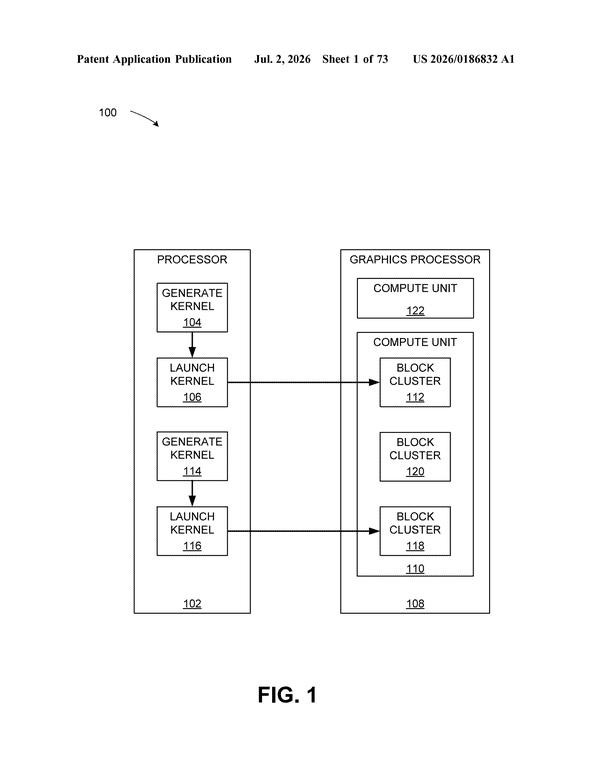
Patents on deciding which task runs first and on which part of the chip, so nothing sits idle. Intel, AMD, Xilinx, Nvidia, Samsung, Apple, Amazon and Qualcomm are all filing here.
Cameras and video feeds produce far more pixels than an AI chip needs. These filings skip unchanged frames, blank pixels and repeated work so image and video AI runs on less memory. Qualcomm, Nvidia, Sony, Samsung and Google lead it.
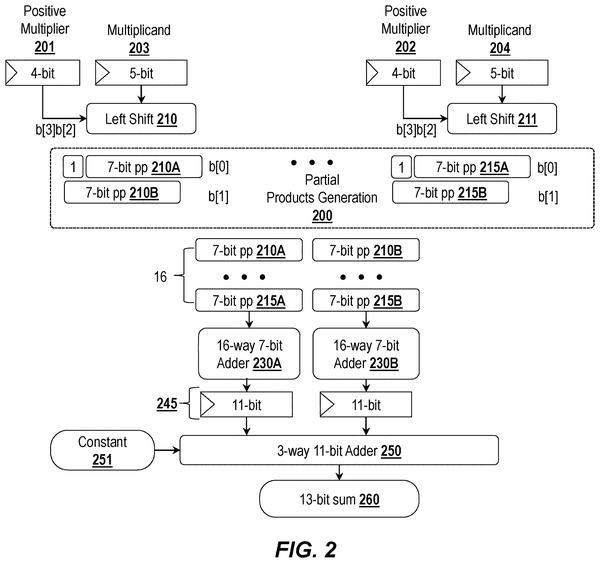
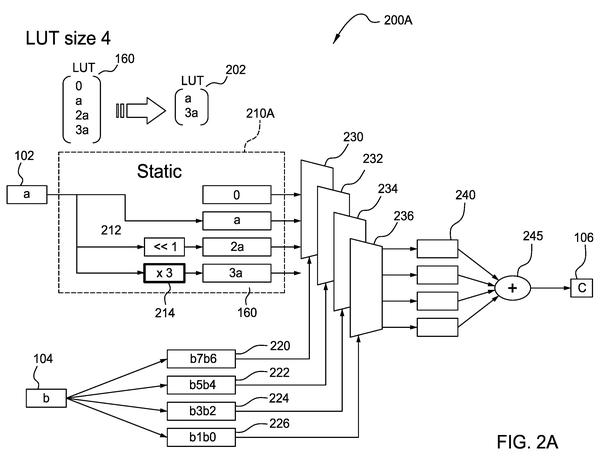
Specialized multiplication units shrink by reusing circuitry across multiple operations, letting Intel pack more compute into the same die area and lower the per-operation cost of running inference at scale.
Data compression corrupts model weights unevenly, and Qualcomm's approach prioritizes repairs on the most error-sensitive parameters first, directly addressing the quality degradation that has made compression a bottleneck for on-device AI deployment.
Variable input sizes force chips to idle or stall between batches. Intel's patent optimizes scheduling so chips stay busy regardless of data chunk dimensions.
Extends the data compression track with a method to preserve model accuracy during block-level quantization, addressing quality loss when shrinking neural networks for mobile deployment.
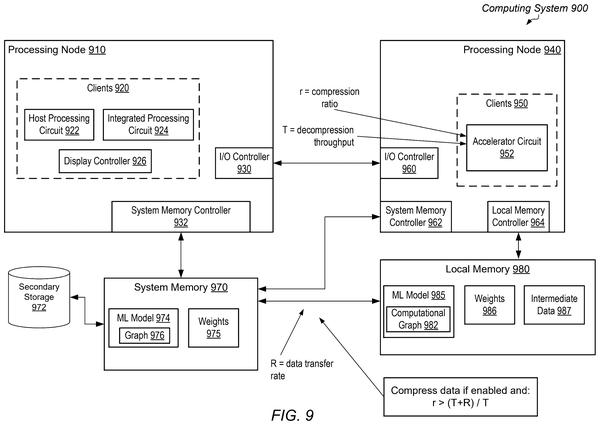
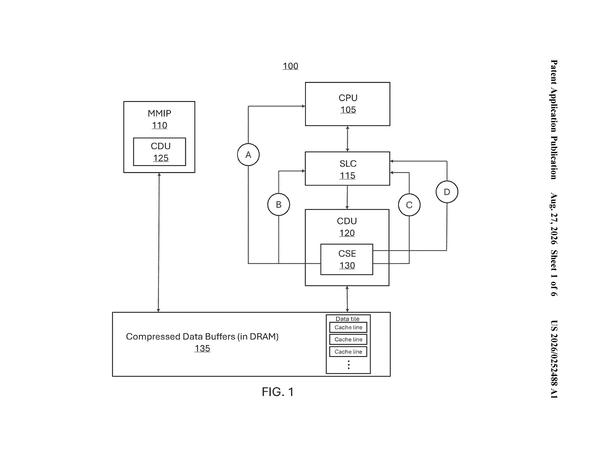
Faster memory speeds up multi-chip AI work only if data movement itself doesn't become the bottleneck. AMD's patent uses selective compression during off-chip transfers to cut bandwidth demands without the overhead of compressing everything.
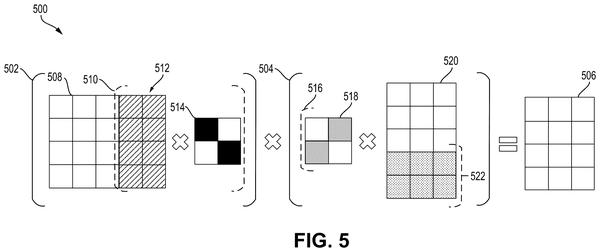
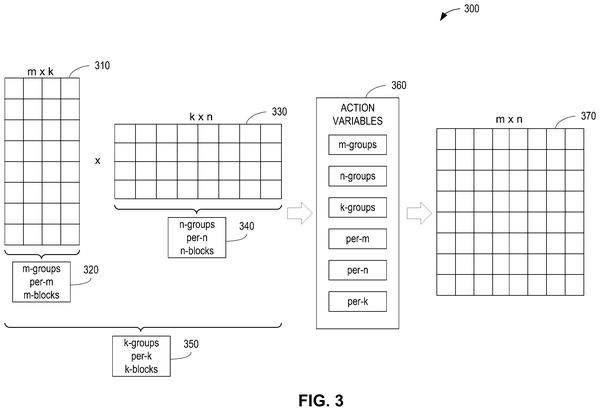
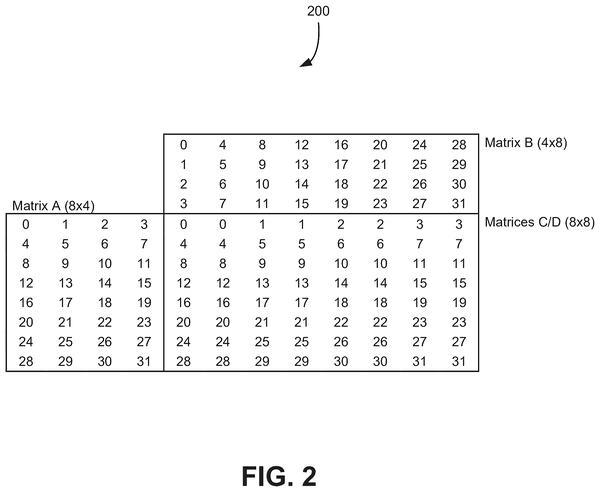
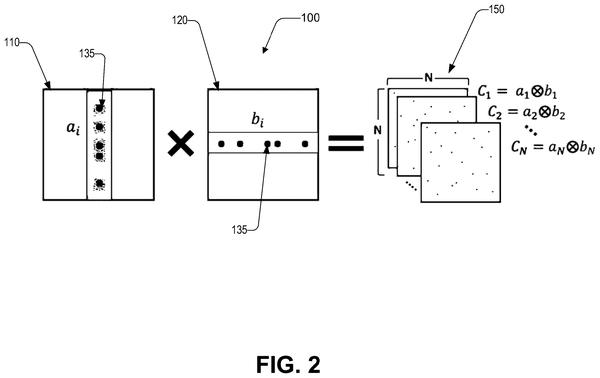
Matrix multiplication speed constrains AI chip throughput, and Intel's filing reveals a chip that learns to partition numeric grids more efficiently, automating optimization work currently done by hand at design time.
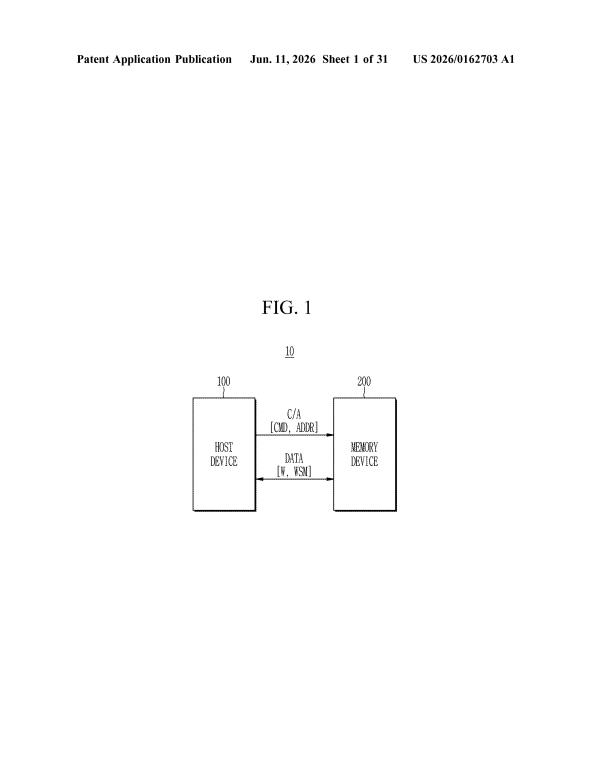
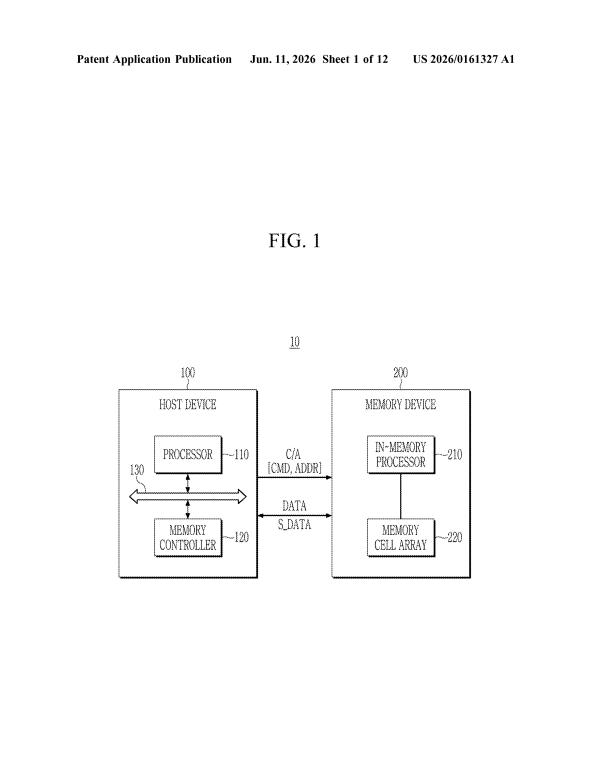
Memory chips handling their own address translation reduces round trips to the main processor, attacking the data shuttle bottleneck that drains power in mobile AI workloads.
The watchlist has tracked memory and coordination across multiple chips; this patent targets task scheduling by predicting downstream work rather than reacting to current queue depth, letting routers pre-position jobs before bottlenecks form.
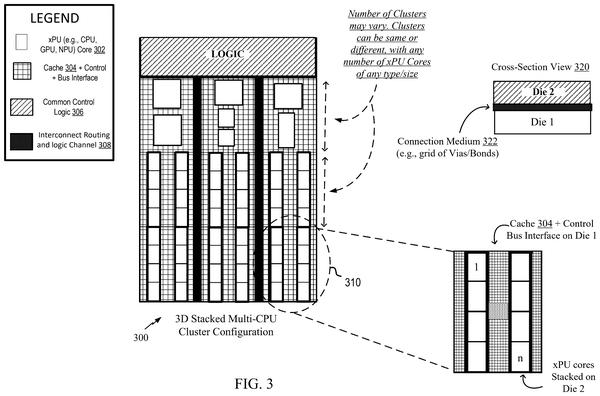
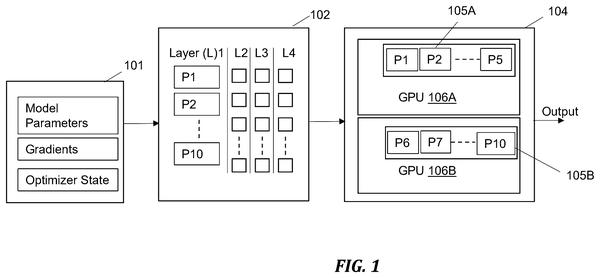
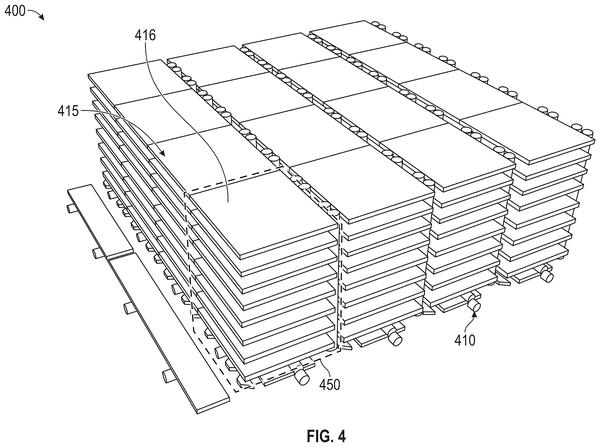
Vertical stacking of heterogeneous processors in a single package reduces the physical distance data must travel between compute cores and memory, directly cutting the latency that creates bottlenecks when coordinating work across specialized chip types.
Confirms the shift toward task scheduling through hardware splits: Samsung's dual-processor design lets inference jobs run concurrently rather than sequentially, moving the bottleneck from software queuing to physical chip layout.
Qualcomm adds a dependency-aware scheduling layer to the task scheduling problem, allowing out-of-order execution while respecting critical instruction sequences that cannot be reordered.
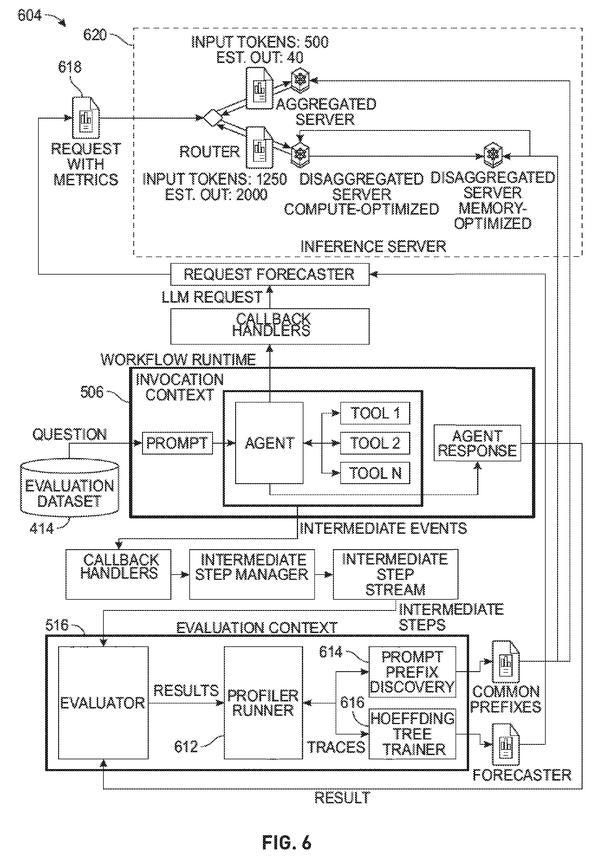
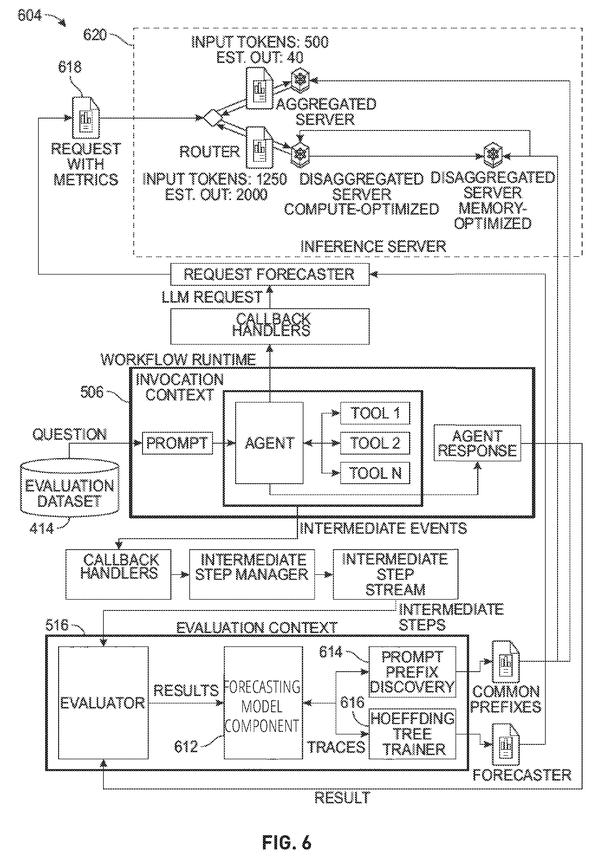
Predictive resource staging sidesteps the wait-and-allocate bottleneck by frontloading capacity decisions based on agent workflow patterns, directly addressing how multi-task coordination costs accumulate when servers react instead of prepare.
Reordering independent operations within dependency constraints speeds execution without stalling downstream tasks, directly addressing the scheduling bottleneck when coordinating work across AI accelerator cores.
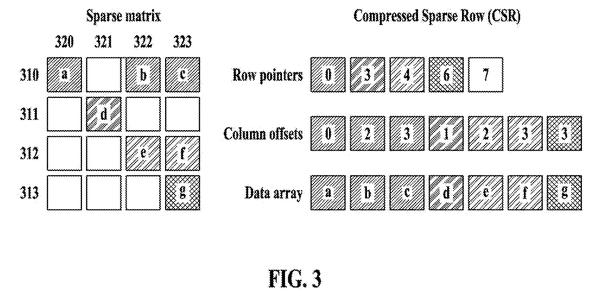
Sparse matrix compression via selective zero-skipping lets chips store and retrieve only non-zero values, cutting the memory and bandwidth waste that comes from moving mostly-blank data across multiple processors.
The memory bottleneck shows up here as a throughput problem: Qualcomm's design batches multiple calculations into single instructions, reducing the overhead of moving data in and out of the chip rather than shrinking the memory itself.
Overlapping two network phases instead of queuing them sequentially cuts idle time in text generation, directly confronting the scheduling bottleneck that makes autoregressive models wait between processing and token output.
Predictive rerouting of memory requests detects contention between data streams before bottlenecks form, moving traffic to idle chips rather than forcing sequential access to saturated ones.
Modern chips cram in performance cores, efficiency cores, and AI processors all at once, and deciding how much power each one gets is a genuinely hard math problem. Qualcomm has filed a patent for a system that hands out power in weighted "credits," adjusting on the fly when some cores are idle.
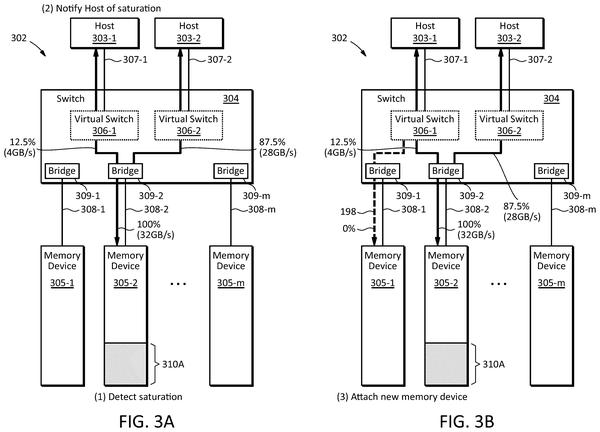
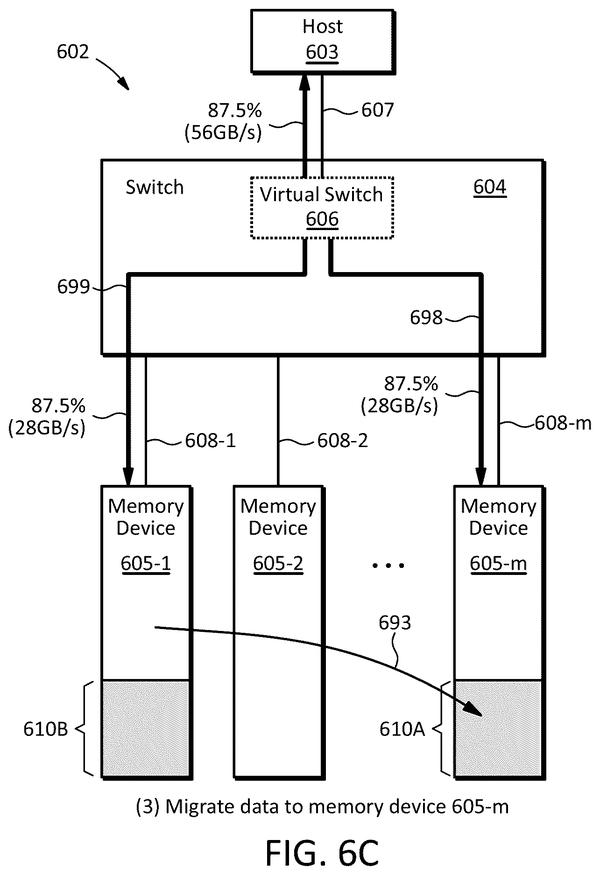
Within the memory bottleneck track, Samsung's switch moves data traffic away from congested chips in real time, shifting focus from static allocation to dynamic load balancing during operation.
A single hardware instruction that fuses two separate math operations cuts the computation cycles needed for SoftMax calculations, one of the most frequent bottlenecks in AI inference on Nvidia's processors.
Dynamic clock scaling in the memory controller reduces parasitic power draw when the chip services long latency operations, directly attacking the coordination overhead between processors and memory, a key bottleneck in multi-chip systems under heavy load.
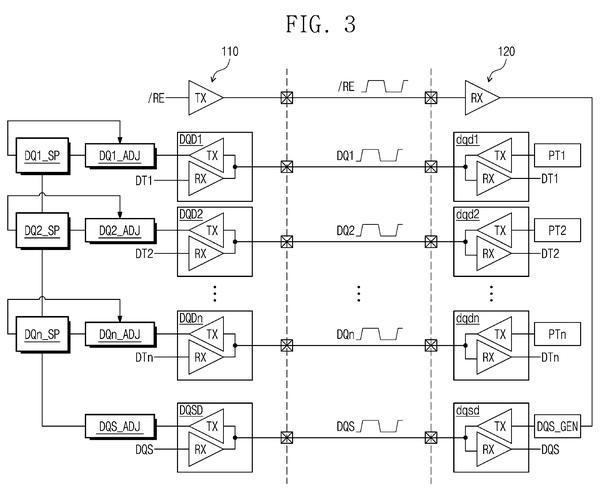
Per-wire timing correction isolates memory signal drift instead of applying blanket adjustments across all connections, cutting read errors at high speeds where sync loss compounds.
Runtime resource reallocation based on observed task behavior directly counters the memory bottleneck problem by shifting compute dynamically rather than front-loading it.
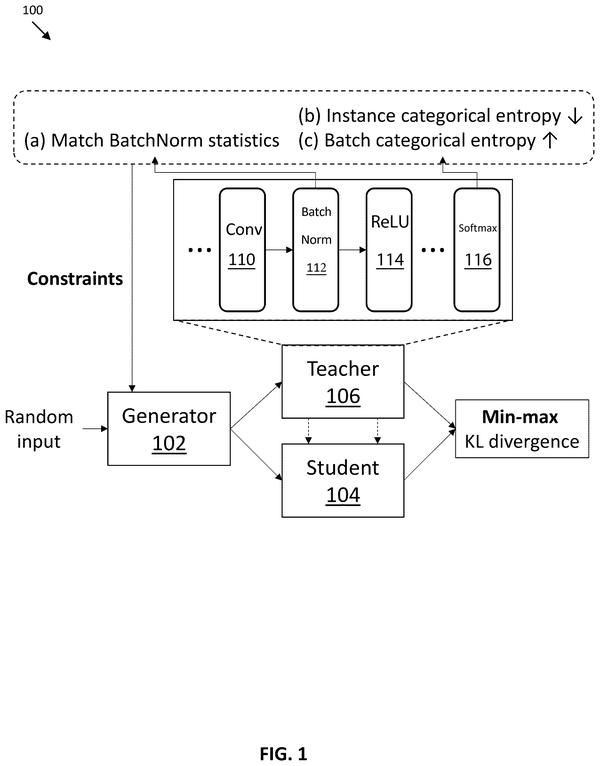
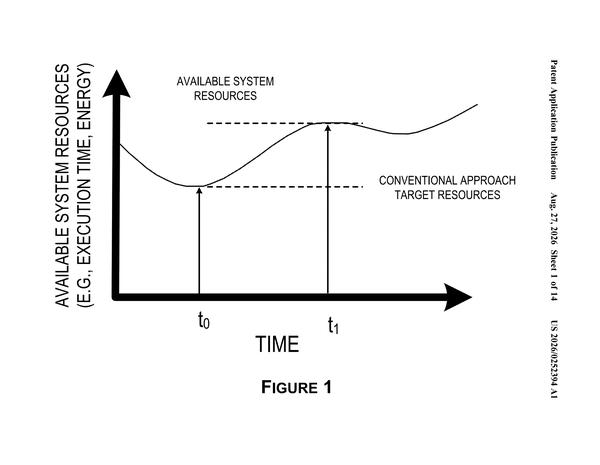
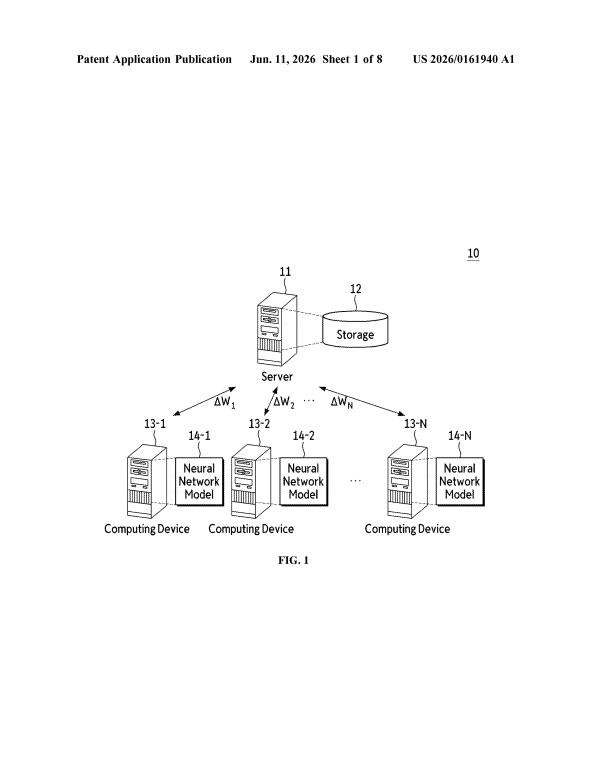
Smaller AI chips could run large models without needing access to the original training data, reducing both memory demands and the logistics of dataset sharing across devices.
Faster AI inference means chips spend less time idle, so memory errors go undetected longer. Qualcomm's approach catches failures during whatever downtime remains, keeping data integrity intact as workloads intensify.
Collapsing multiple processing layers into a single operation keeps intermediate data in fast cache memory instead of shuttling it back to slower storage, directly shrinking the memory bottleneck that slows multi-chip AI systems.
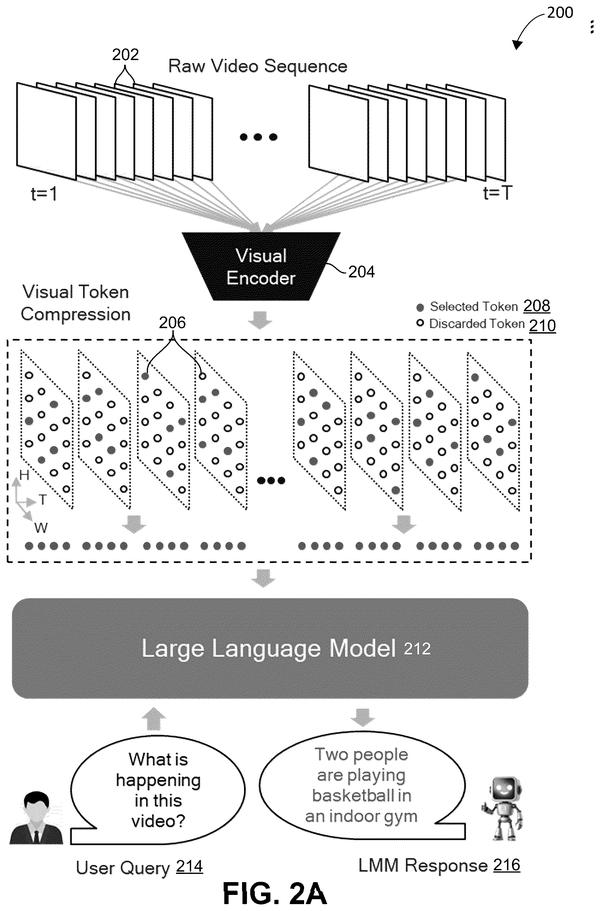
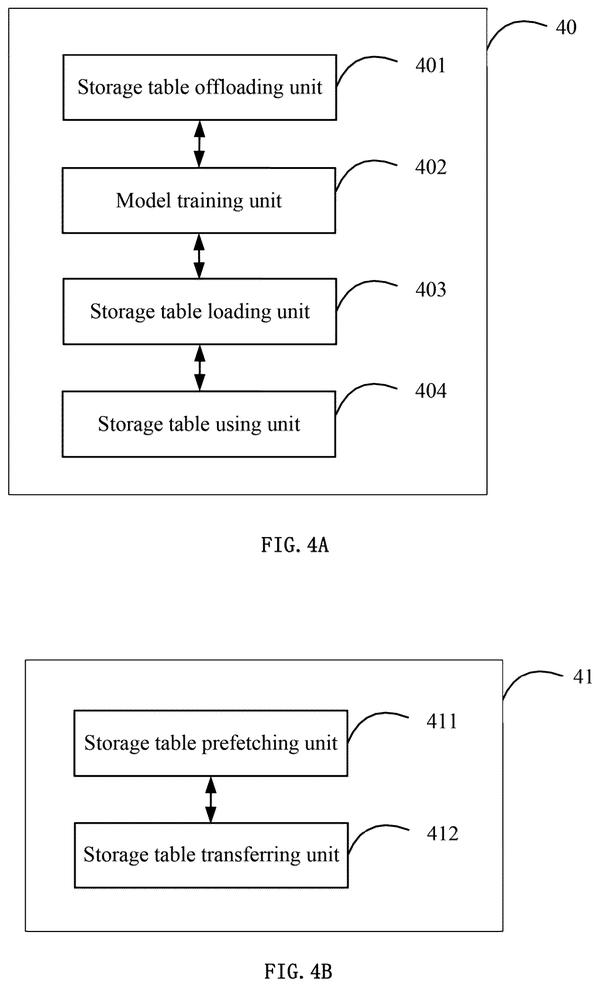
Data compression across transformer layers: Samsung's two-pass method filters low-relevance sentences before full processing, reducing the token volume that demands expensive attention operations on long documents.
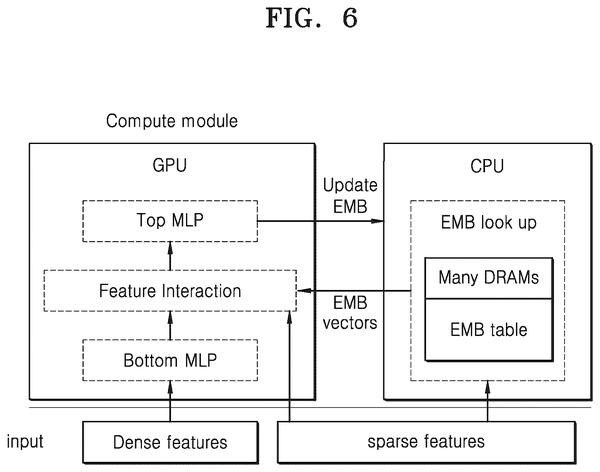
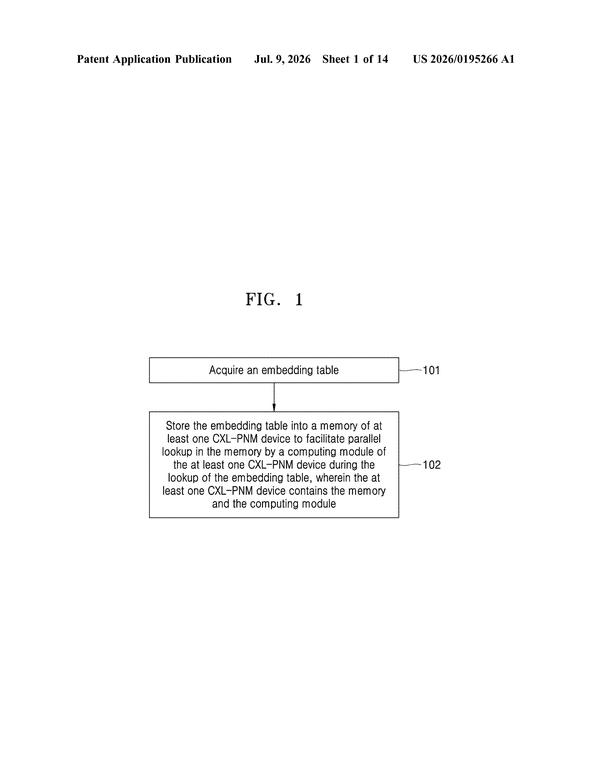
Memory bottlenecks in recommendation models stem from lookup tables too large for system RAM. Samsung's approach moves embedding vectors to specialized storage with direct GPU access, eliminating the fetch-and-wait cycle that starves compute resources.
Keeping distributed chip clusters synchronized across power state transitions. Apple's approach uses a dedicated broadcast layer so waking components can resync with current system state without full handshakes between every pair of chips.
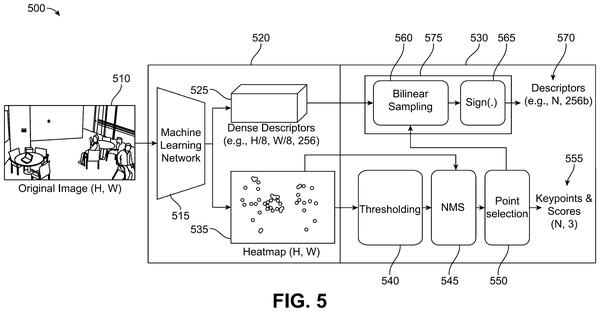
Cuts the data footprint for on-device visual matching by encoding image features into compact codes, reducing what needs to move between the chip's memory and processor during real-time recognition tasks.
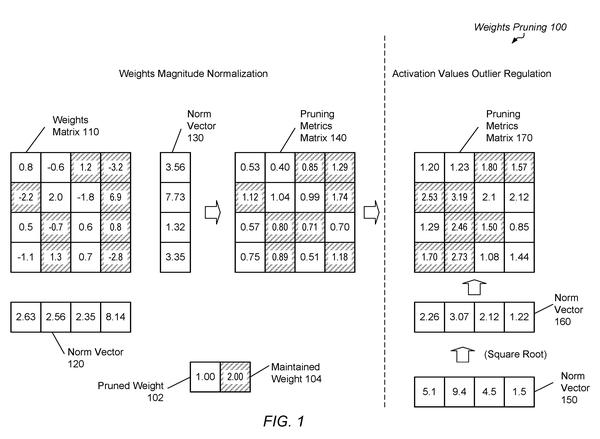
Data compression via pruning hits the memory bottleneck directly. Xilinx's dual-signal approach automates weight trimming across distributed inference, reducing the on-chip storage demands that currently force data movement between processors.
Data coordination across multiple chips hits a specific problem: managing predictable congestion waves during distributed training. Microsoft's central scheduler spreads traffic across network paths in advance, preventing bottlenecks before they form.
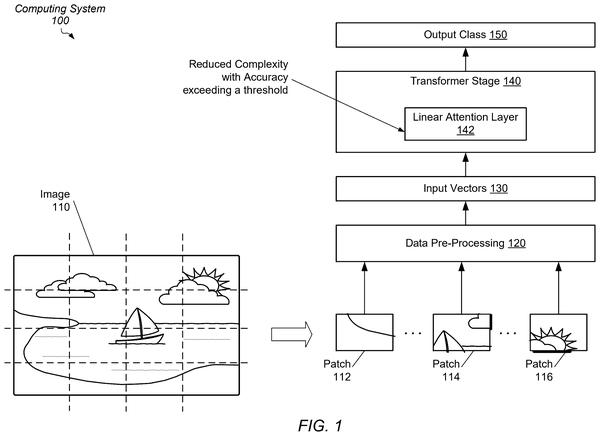
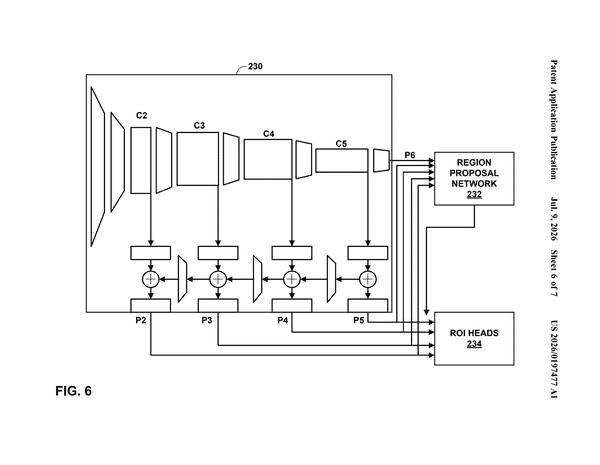
Cutting attention's math load directly shrinks the compute budget for vision inference, which matters because attention scales with image complexity and currently dominates the work inside these models.
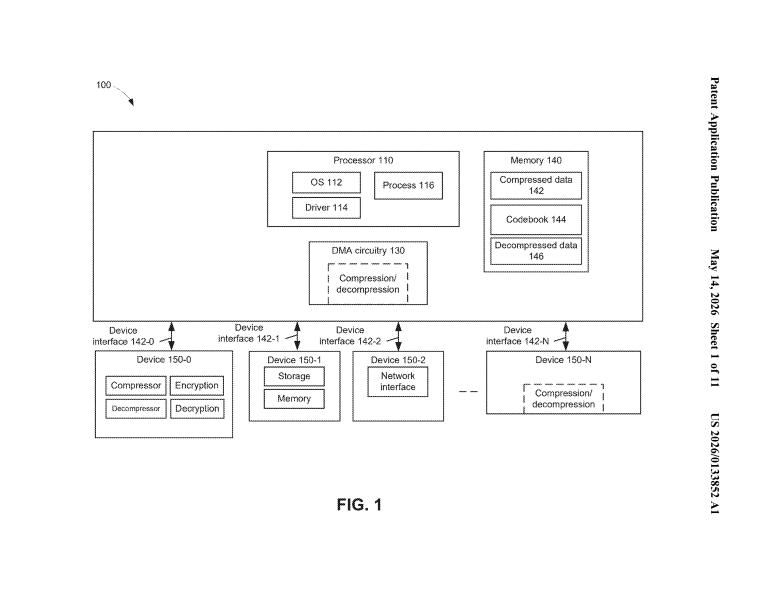
Data decompression method selection has been a software bottleneck; Samsung's filing moves that decision into hardware, letting chips automatically pick the right unpacking approach based on storage location rather than slowing down for software lookups.
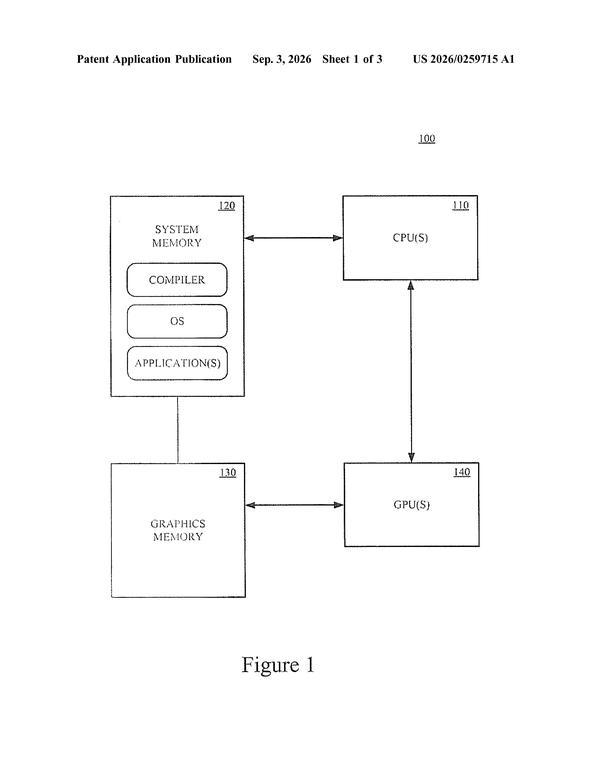
Task scheduling across heterogeneous processors gains a concrete use case: Intel's system routes graphics workloads between integrated and discrete chips based on thermal and power constraints, automating decisions that currently rely on fixed rules.
Memory bottlenecks drive up hardware costs when every layer of an AI model runs on premium chips. Microsoft's approach routes less critical computation through cheaper processors, keeping only the highest-value operations on expensive silicon.
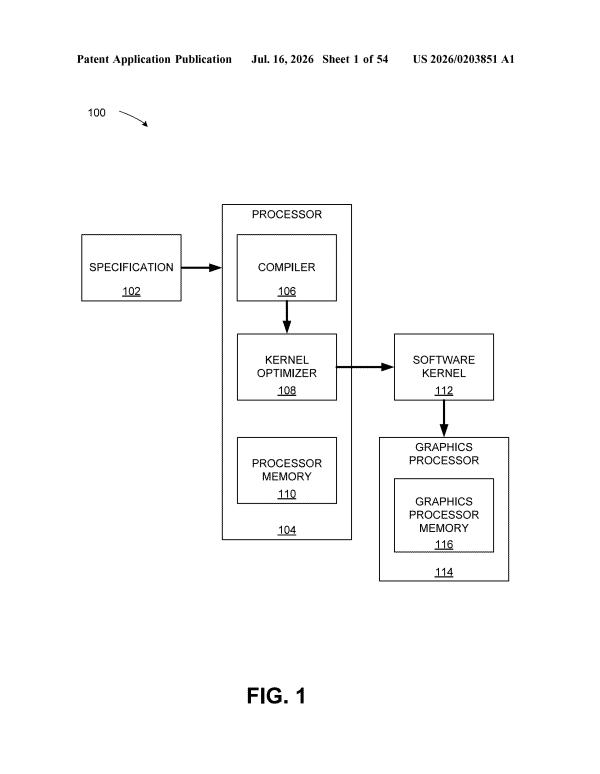
Task scheduling between compute and memory hits a bottleneck when compilers guess the operation order. Intel's approach uses a learned model to optimize sequencing instead of relying on heuristics.
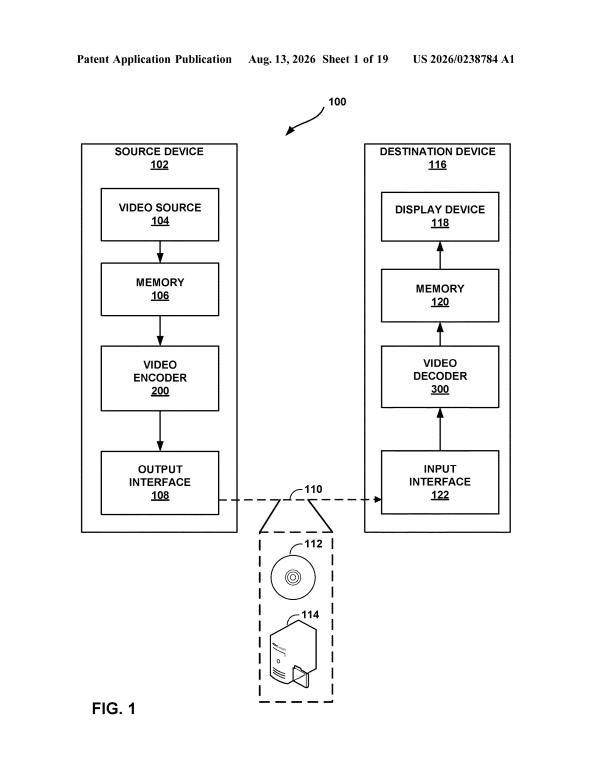
Data compression in video processing cuts what AI chips must ingest by filtering frames before they reach the processor, reducing the memory-to-compute bottleneck on resource-constrained devices.
Faster AI means switching execution modes mid-operation instead of picking one strategy upfront. Intel's filing shows hardware that detects phase changes and resets processor behavior automatically.
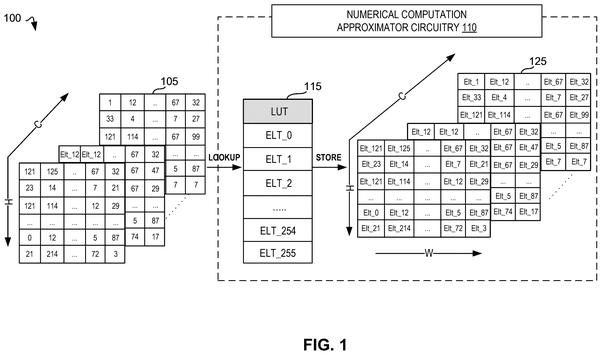
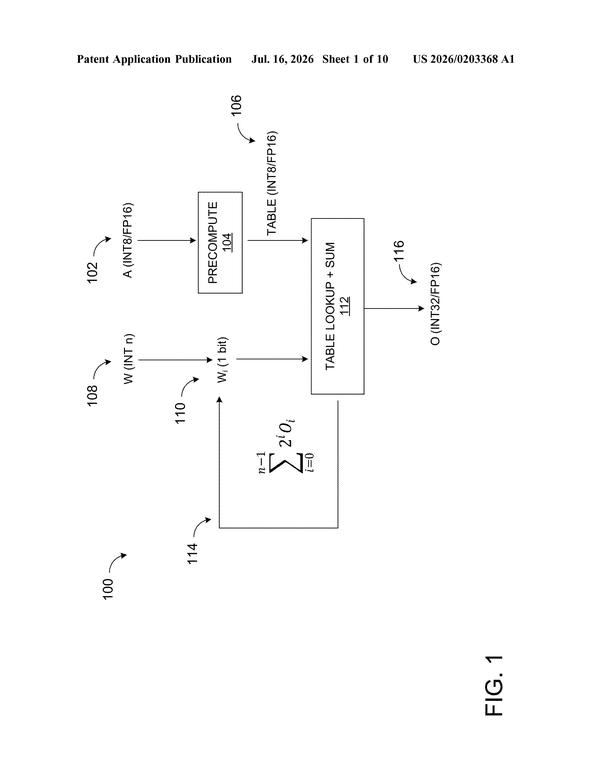
Data compression in AI chips moves from algorithmic tricks to hardware caching: Intel's lookup table approach pre-stores computation results to cut repeated math, trading memory space for power and latency gains.
Dynamic batch sizing before computation begins eliminates the fixed allocation overhead that leaves memory half-empty or overflowed during image processing tasks on AI chips.
Task scheduling across CPU and GPU cores gains a dynamic angle: rather than pre-compiled work division, the CPU can translate and offload GPU instructions during execution, eliminating idle time between processors.
Thermal management in stacked processors: Microsoft's modular heat sink design enables coolant flow across multiple axes simultaneously, addressing the constraint that single-direction cooling can't match modern chip density.
Coordination across multiple chips requires simultaneous visibility into processor states. Nvidia's parallel query system eliminates sequential checking delays that make real-time monitoring impractical at scale.
Predicting model architecture constraints before training lets engineers skip the costly trial-and-error cycle of testing dozens of designs on target hardware, moving the chip-to-model fit upstream.
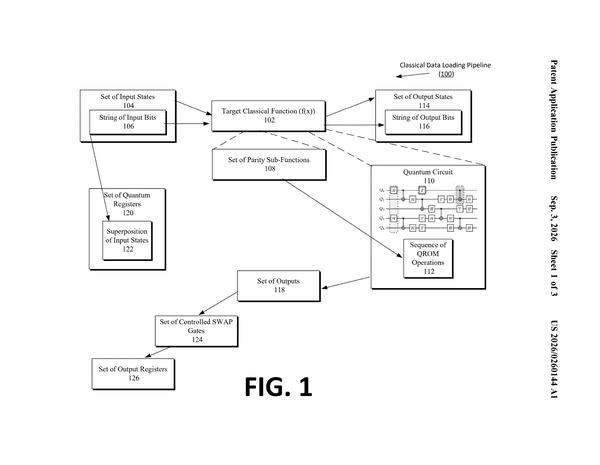
Faster data loading into quantum processors could preserve more of the speed gains quantum hardware promises, by parallelizing a translation step that currently runs sequentially and consumes significant resources.
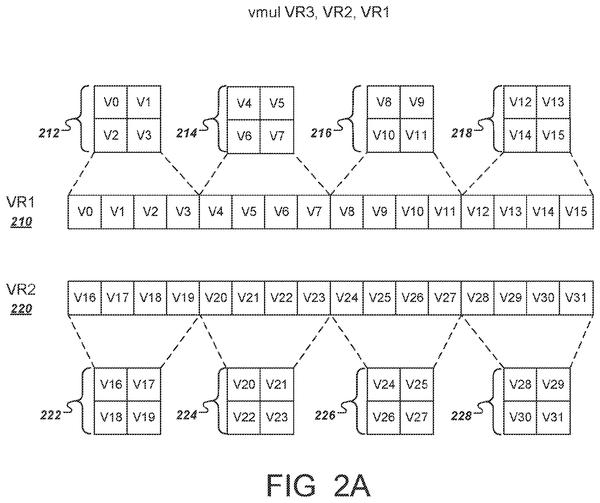
Repurposing existing vector CPU instructions as matrix operations eliminates the need for custom silicon, offering a software-only path around the memory and compute bottlenecks that plague general-purpose processors running AI workloads.
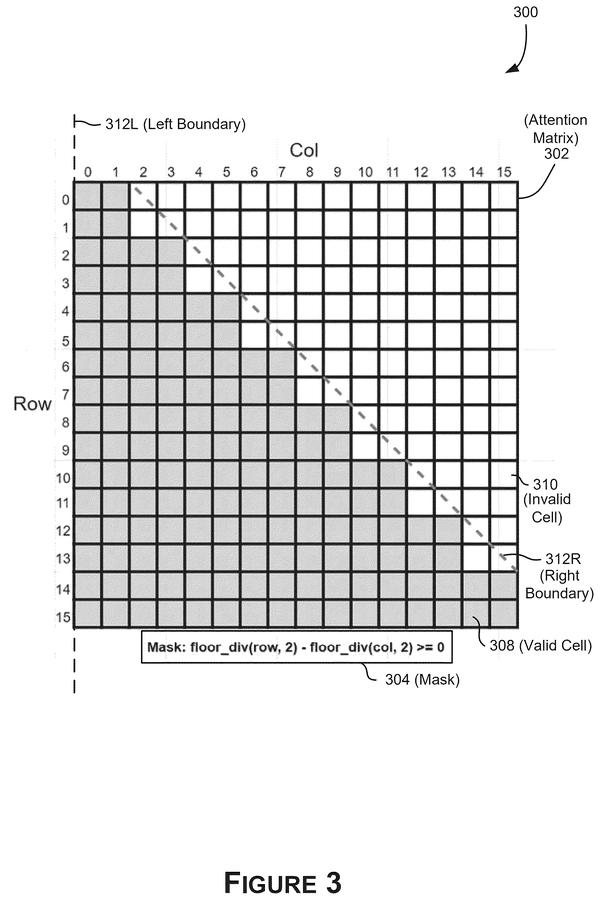
Faster AI inference means cutting wasted computation in attention mechanisms. Nvidia's compiler identifies masked-out matrix cells before runtime, eliminating calculations the model would skip anyway.
Power consumption compounds the memory bottleneck problem. Sony's approach powers down memory sections immediately after use rather than leaving them live, directly cutting wasted energy in densely packed chip designs.
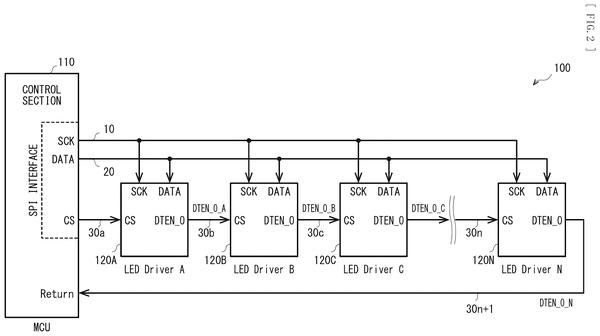
Cutting the control wiring between AI chips from N lines down to one lets system designers pack more memory and processors into the same physical space, directly easing the coordination bottleneck across multiple chips.
Memory bandwidth waste from speculative caching drains performance on multi-chip AI systems. Samsung's approach predicts actual data access patterns per application, reducing the false loads that fragment fast storage across distributed inference tasks.
Cache coherency across multiple processors demands a coordination layer that tracks which chips hold stale copies of shared data. Samsung's patent automates this synchronization to prevent processors from operating on outdated memory values.
Within the memory bottleneck problem, this constrains where video encoder reference data can live, keeping fetches local to single chips rather than cross-chip, reducing coordination overhead.
Dividing memory blocks to avoid split fetches between fast and slow storage shrinks latency in video encoding, a key bottleneck as AI inference demands coordinated access across distributed chip hierarchies.
Task scheduling on a single chip: Apple's approach preserves context when switching between concurrent AI workloads, suggesting the company is optimizing for efficient multitasking rather than dedicated processors per function.
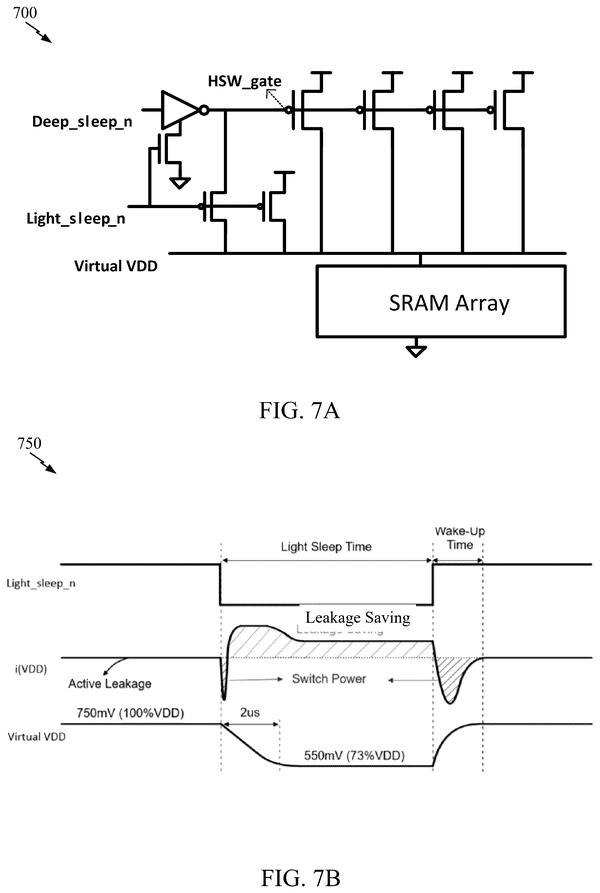
Cutting voltage to idle memory banks rather than powering them down completely reduces the wake-up lag that would otherwise slow performance, directly addressing the memory power drain that degrades battery life across millions of devices.
Extends the coordination problem beyond task scheduling to thermal management: keeping multiple AI models running simultaneously requires real-time power arbitration, not just workload distribution.
Memory bank conflicts force GPU threads to stall when they compete for the same data location. Intel's approach routes task scheduling to prevent simultaneous access to individual banks.
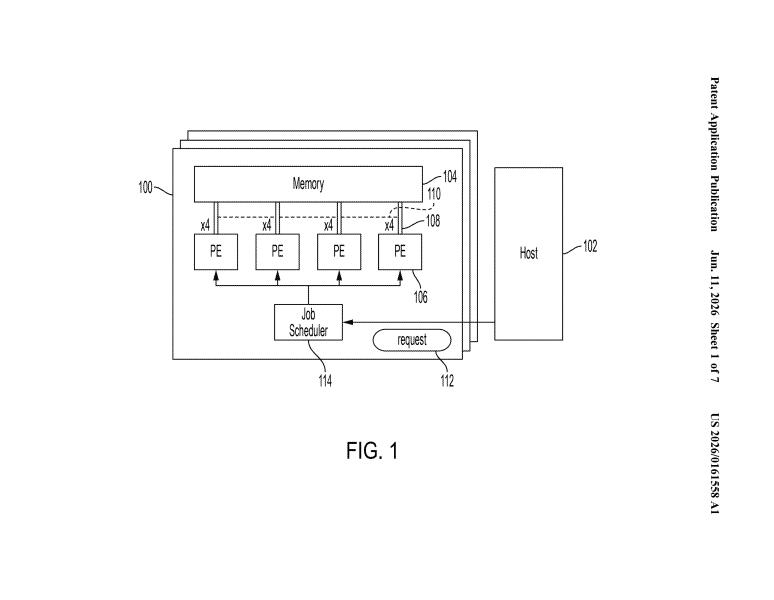
Automatic memory slot reclamation from stalled tasks prevents the cascading slowdown that hits multi-chip systems when one processor can't offload work to others, addressing a key coordination problem in distributed AI inference.
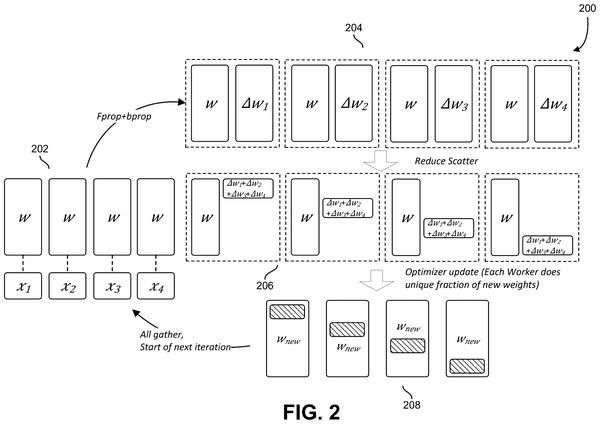
Task scheduling across distributed chips slows training when weight updates serialize billions of calculations. Nvidia's approach parallelizes this step by having multiple chips compute simultaneously rather than sequentially.
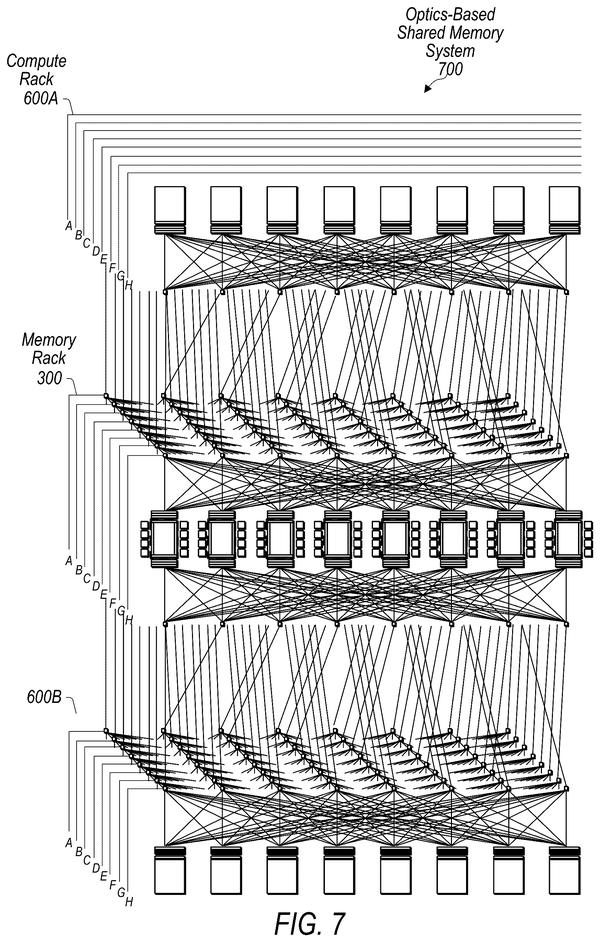
The memory bottleneck in multi-chip systems has pushed toward optical interconnects. Apple's light-based routing sidesteps the electrical wire constraints that plague distributed server memory, moving the coordination problem from copper to fiber.
Data compression in image processing: Nvidia's approach filters redundant pixels before computation enters the pipeline, reducing the math workload for downstream hardware.
Faster historical data ingestion across distributed workers means AI systems could move past single-machine bottlenecks during training, directly cutting the time needed to prepare models on long time-series datasets.
Faster softmax computation cuts power consumption during the probability-scoring step that happens billions of times across inference. Confirms the chip wars are shifting toward optimizing the inner loops of transformer math, not just memory bandwidth.
If Intel's approach works at scale, chips could resume interrupted memory operations without restarting, freeing up the stalled compute cycles that currently pile up waiting for data to arrive from scattered memory banks.
Task scheduling under resource contention: Nvidia's approach monitors real-time chip load and reconfigures model architecture dynamically rather than queuing or degrading performance.
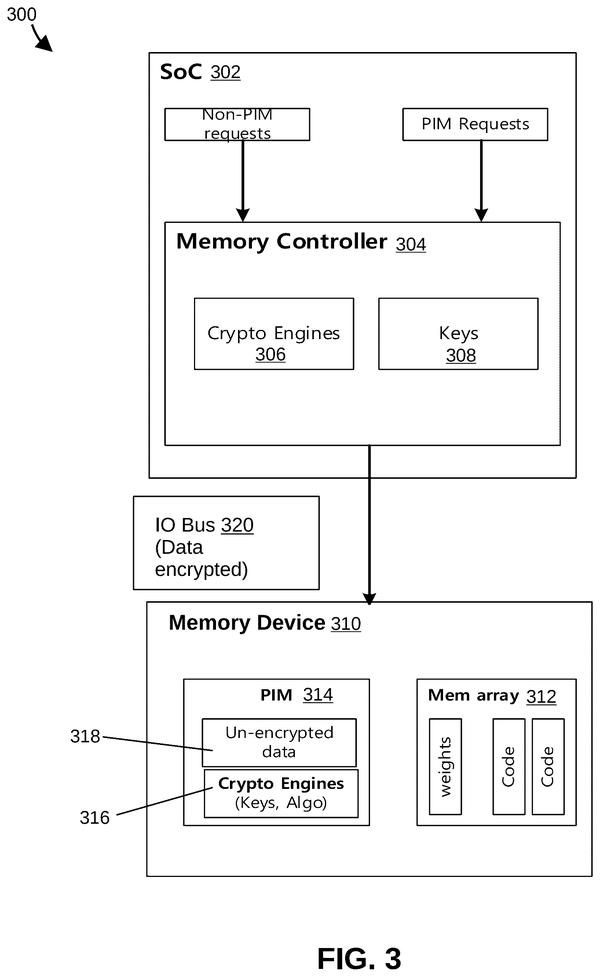
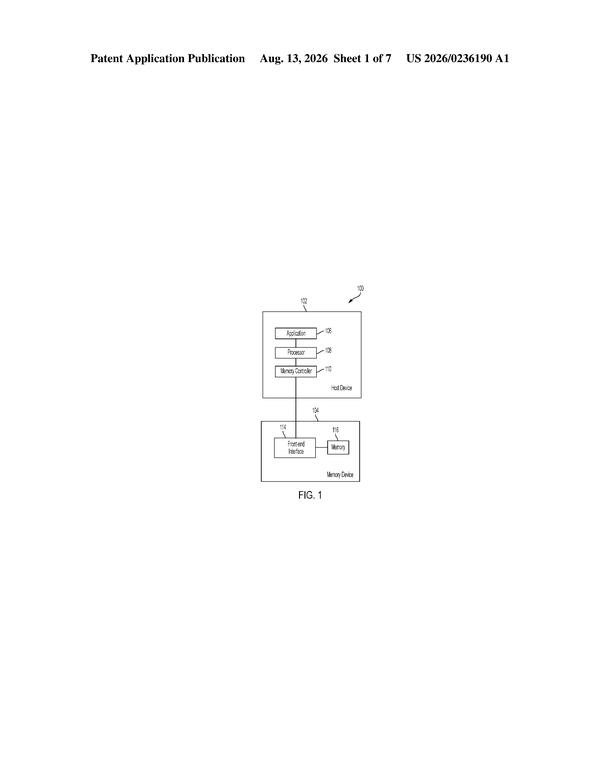
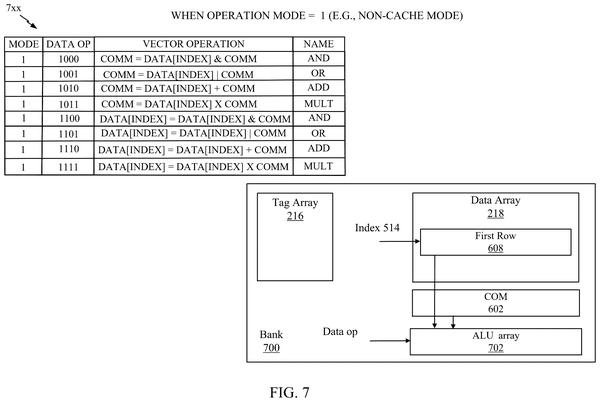
Decrypting data at the memory chip itself rather than on the main processor cuts the data movement between components, directly easing the memory bottleneck that slows AI workloads.
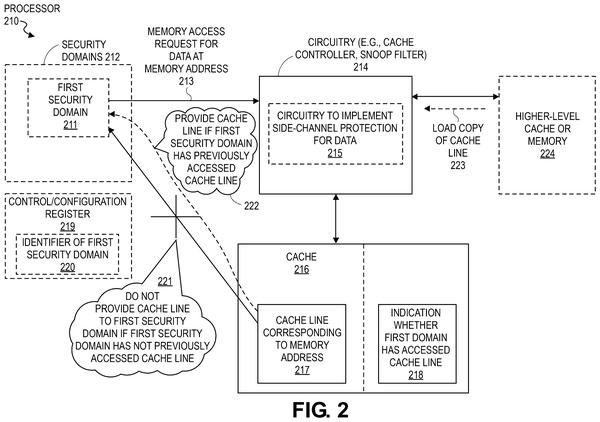
Isolating cached data between programs adds a hardware layer against timing-based attacks, confirming that cache arbitration is becoming a competitive feature in multi-tenant chip designs.
Faster data movement between chips could come from using light beams across transparent displays as a processing medium, sidestepping the conventional electrical pathways that create memory bottlenecks in multi-chip systems.
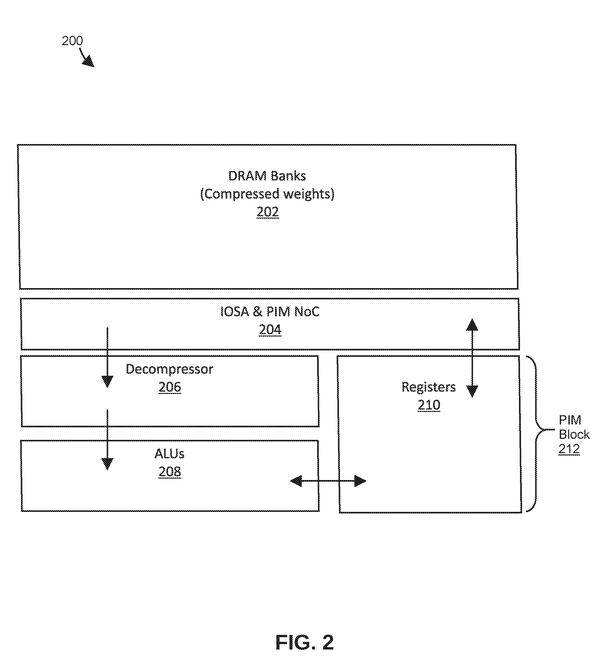
Decompressing data inside memory rather than shuttling it to a distant processor cuts the energy cost of the memory bottleneck, a core constraint in stacking more AI work onto mobile devices.
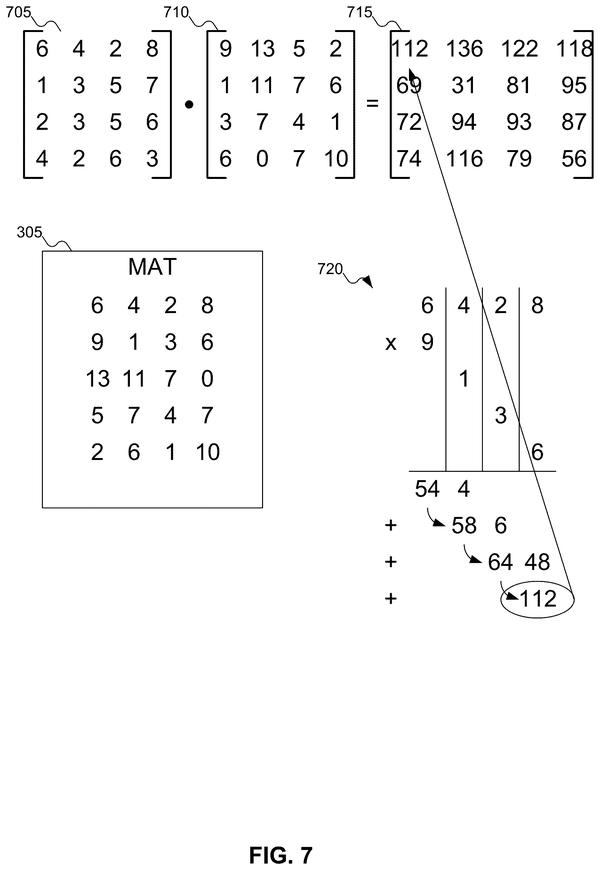
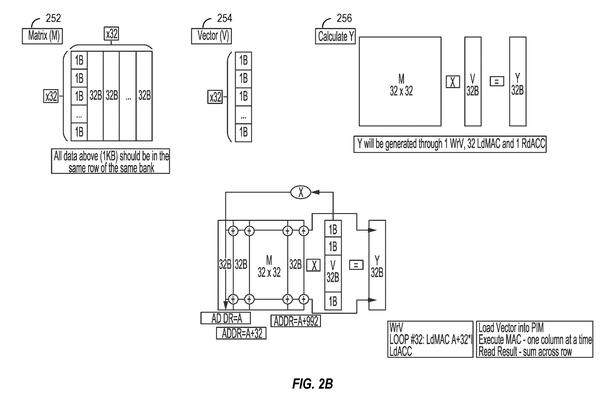
Faster matrix multiplication reduces inference latency directly, meaning AI models respond quicker without needing more chips or memory bandwidth to handle the workload.
Data compression in vision pipelines cuts storage by skipping redundant frame analysis. Confirms the chip wars are pushing deep into the sensor layer, not just core compute.
Data routing between specialized compute units constrains throughput on dense AI chips. Nvidia's circuit-level partition scheme routes matrix operations to matched hardware blocks, reducing idle cycles and data movement overhead across the chip.
Reducing what gets stored in memory rather than compressing it after the fact means AI video systems could run on devices with tighter memory budgets. This shifts the bottleneck from storage capacity to the speed of filtering decisions.
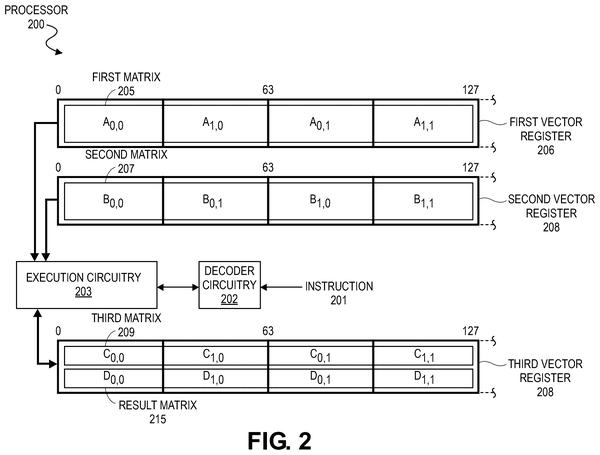
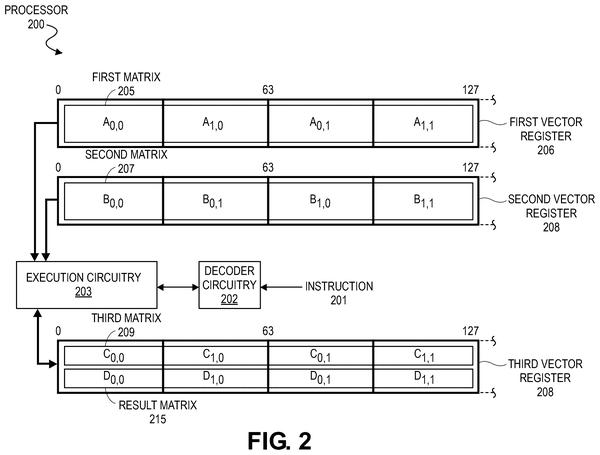
Parallel matrix ops within a single instruction reduce the compute cycles needed per AI calculation, directly loosening the memory bottleneck that forces chips to stall while waiting for data to arrive.
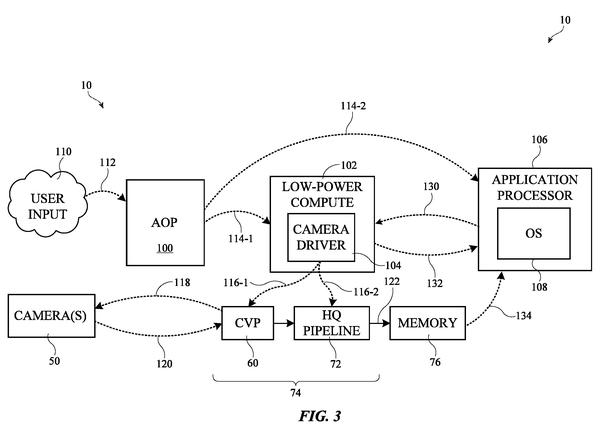
An always-on sensor chip wakes the camera controller and main processor in parallel rather than sequentially, eliminating the boot delay that slows photo capture on devices with dormant cores.
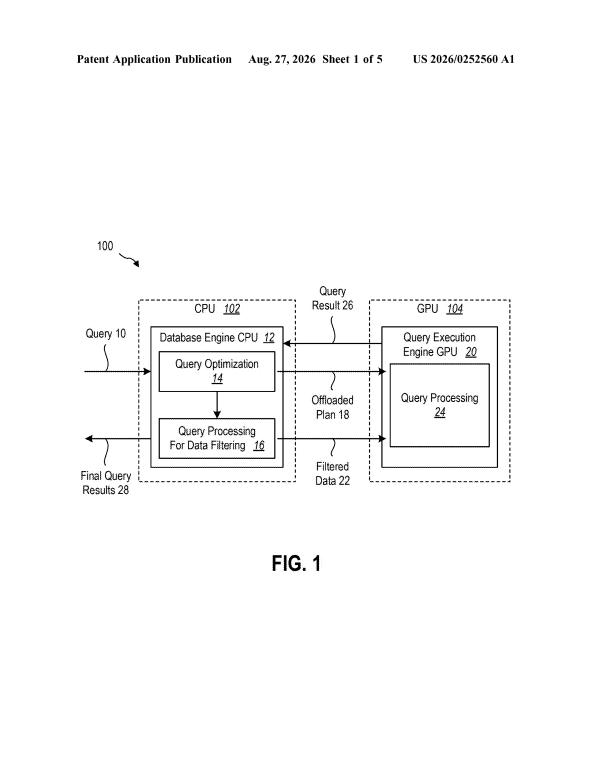
Memory bandwidth limits data lookups on CPUs alone. Microsoft's approach splits the work by having the CPU filter data first, then passes the trimmed set to the GPU for parallel searching, reducing total bandwidth demand.
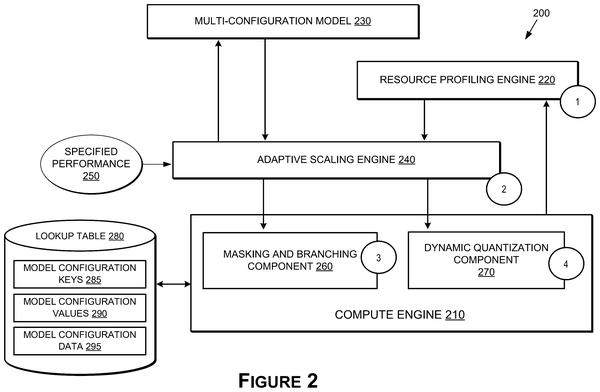
Dynamically resizing models based on chip load lets AI inference pull back during bottlenecks instead of forcing peak compute every time, easing the memory and scheduling crunch when multiple tasks compete.
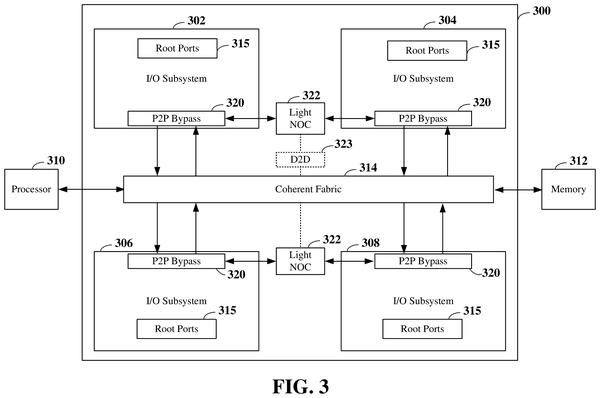
Data routing between chips can bypass the shared bus when point-to-point communication is detected, reducing congestion that slows multi-chip inference workloads.
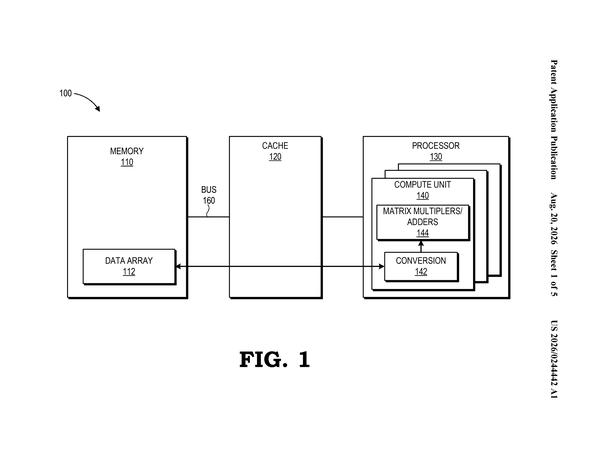
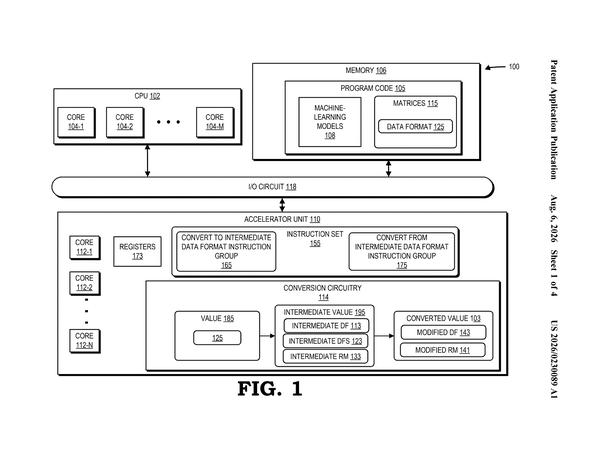
A conversion circuit embedded in the processor eliminates the software translation step between incoming data formats and what the AI engine expects, reducing latency and power waste before computation begins.
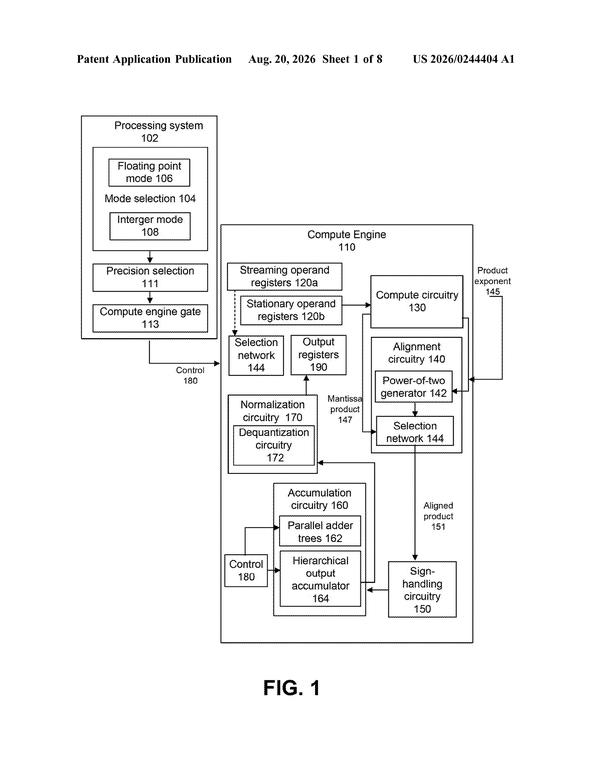
The memory bottleneck story gains a specific fix: unified compute blocks that process both floating-point and integer math without shuttling data between specialized units, cutting the coordination overhead that slows multi-format workloads.
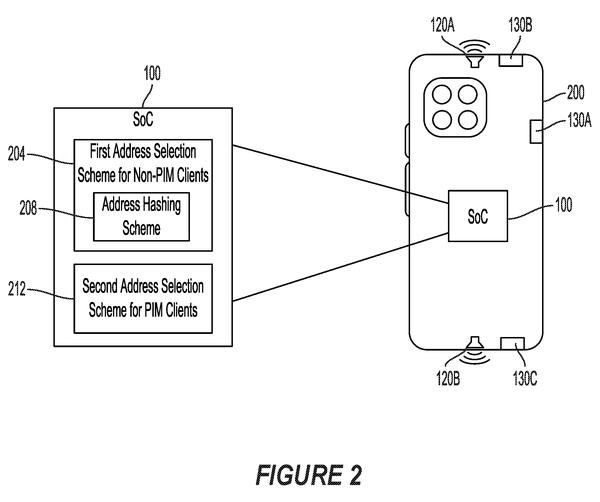
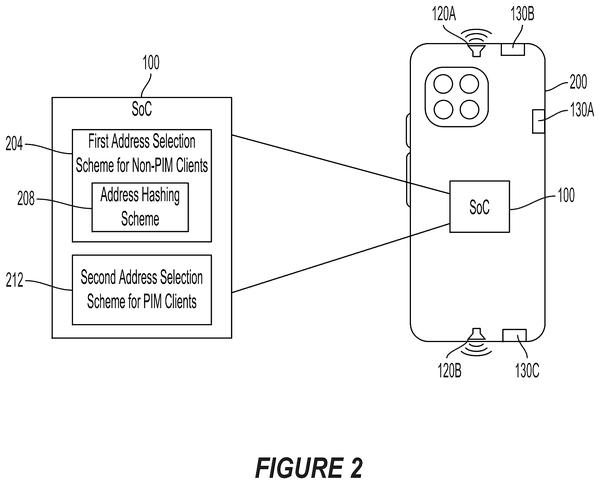
Swapping between two address-mapping schemes based on task type lets in-memory processing bypass the scrambling overhead that slows it down on conventional workloads, directly easing the memory bottleneck when computation moves closer to data.
Data compression has been a bottleneck in AI chip design, and Sony's filing shows how synchronization between parallel encoding threads can prevent slowdowns when multiple processors work on image compression simultaneously.
The timeline so far has centered on moving data between chips. AMD's filing shifts focus to splitting computation itself across chips on demand, treating multi-chip coordination as a scheduling problem rather than a bottleneck problem.
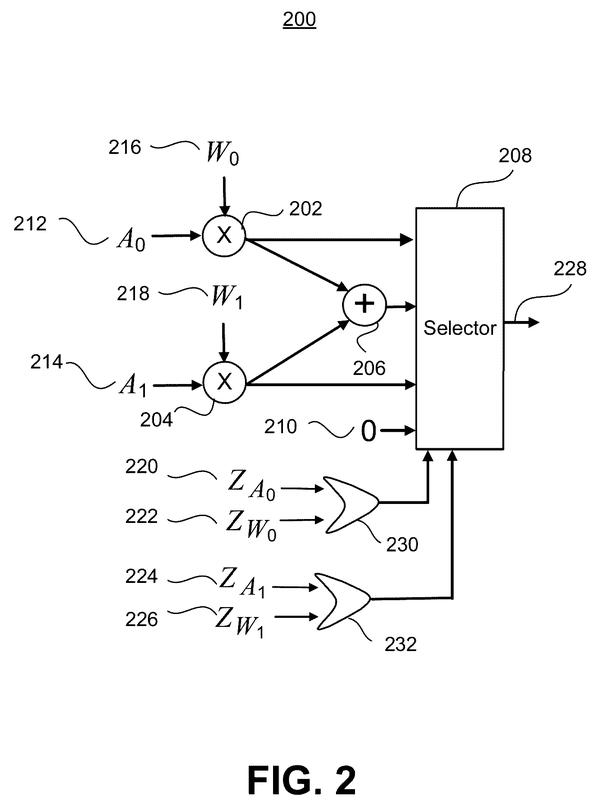
Memory bottlenecks shrink when chips stop moving zero values through their pipelines at all. OpenAI's design catches zeros before multiplication, cutting both data movement and computation waste.
The watchlist has focused on coordination across chips. This filing shows networks need feedback from individual devices about compression capacity, not just chip-to-chip handshakes, to distribute AI workloads efficiently.
The chip wars so far have centered on moving data faster. Intel's filing shifts focus to processing less data in the first place, by making skip-or-compute decisions in hardware rather than software, eliminating the guesswork that slows down shortcuts.
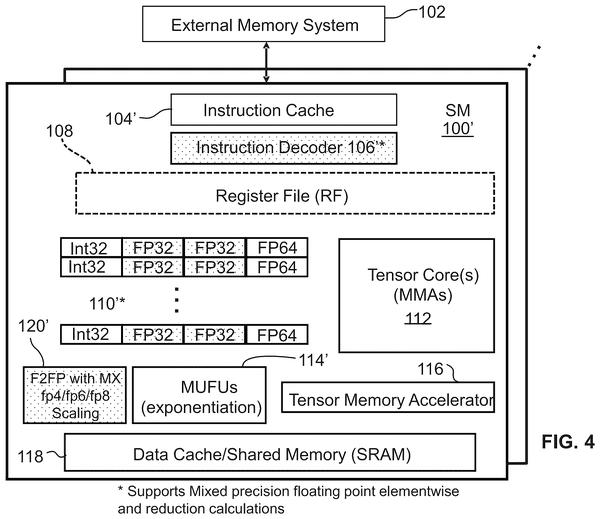
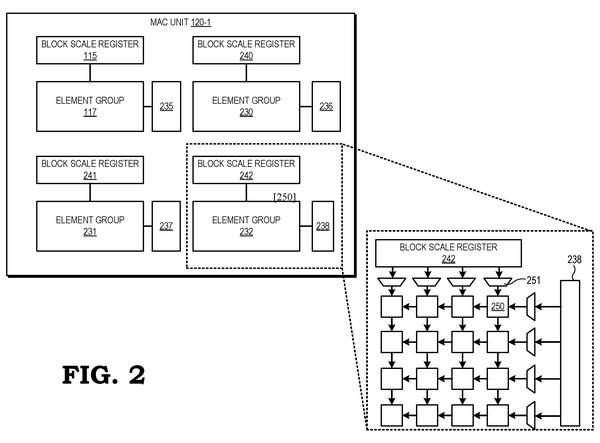
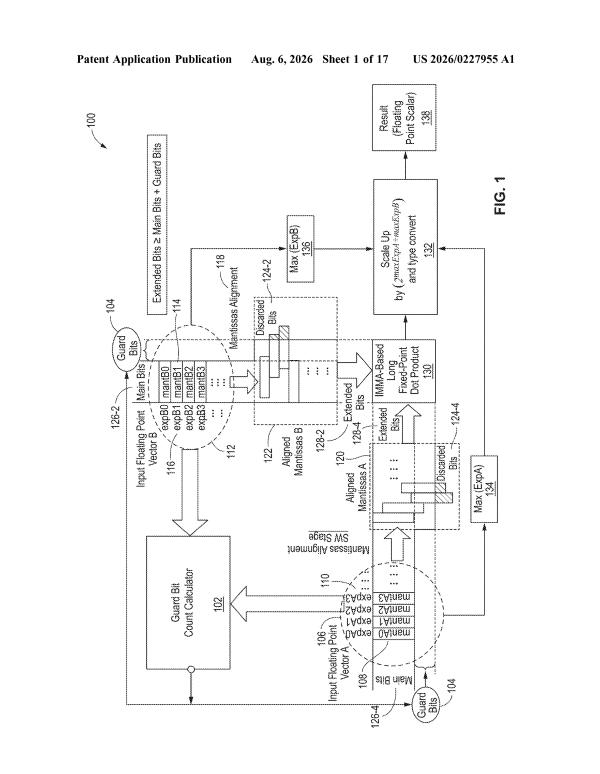
Letting separate processor clusters apply their own scaling factors to matrix operations cuts the accuracy loss from forced quantization while avoiding the silicon cost of duplicating full conversion hardware.
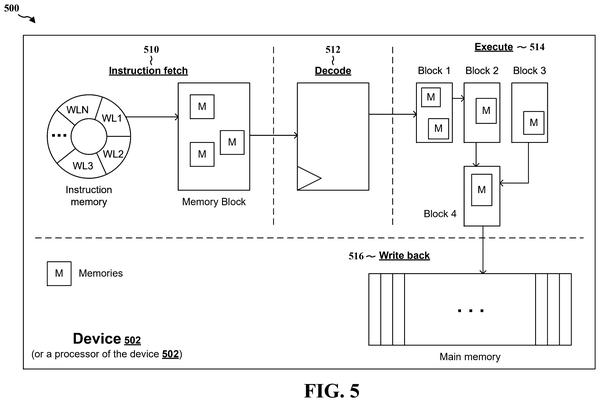
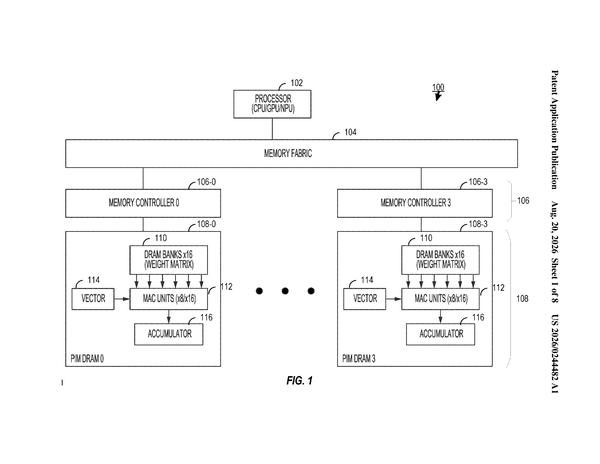
The memory bottleneck thread gets a direct solution: moving computation into the storage itself rather than shuttling data across the chip to a processor.
The memory bottleneck thread gains a hardware-level solution: rather than processors waiting their turn at shared memory, the memory chip itself manages task switching and state preservation, moving coordination from software layers into silicon.
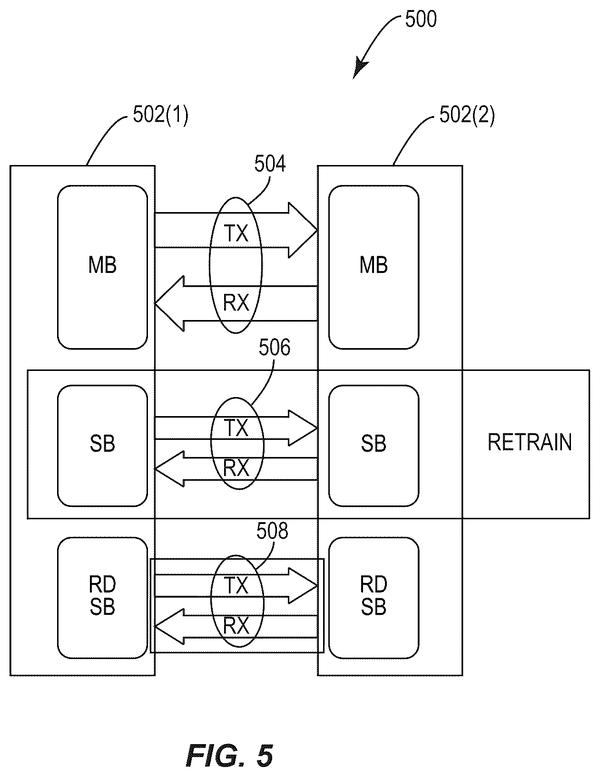
The chip-to-chip coordination bottleneck: Samsung routes signals through existing solder bumps rather than adding separate wiring, cutting parasitic losses in inter-chip communication.
Embedding compute directly in memory arrays cuts the energy cost of shuttling data between separate processor and storage units, addressing the memory bottleneck that drains power in dense AI workloads.
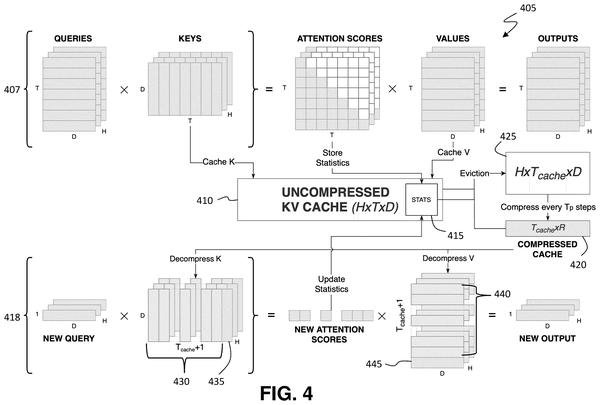
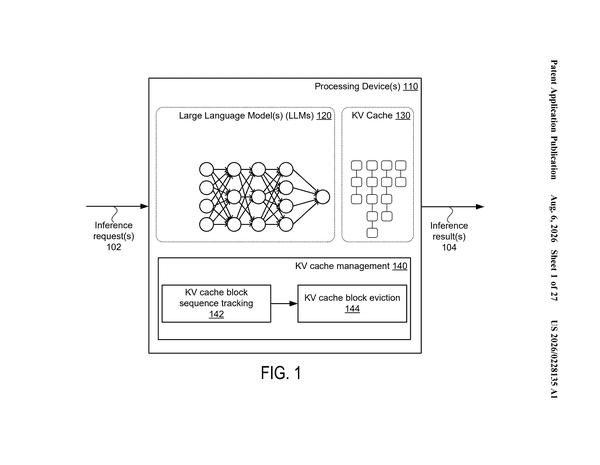
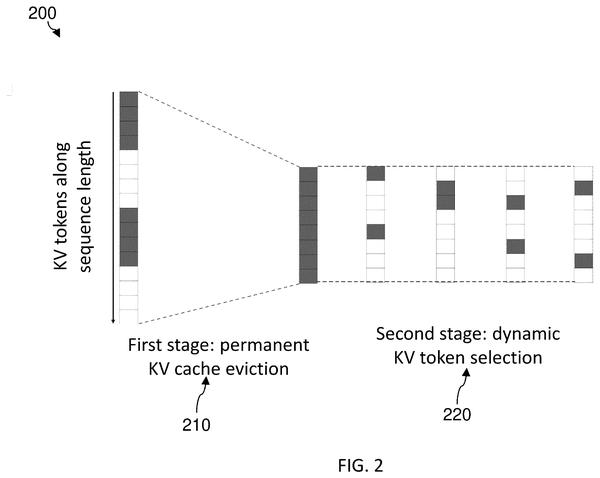
Storing the key-value cache during generation forces a memory-per-token tax that grows with sequence length. IBM's compression method prunes this cache on the fly, cutting the storage load before it stalls inference speed on long documents.
Memory compression already drives the chip wars. Google's filing shows a path forward: custom bit widths that break free from fixed power-of-two formats, letting engineers dial precision per layer instead of forcing every calculation into standard sizes.
Dynamic power allocation based on workload priority reduces idle consumption during low-intensity tasks, directly addressing the energy waste that constrains multi-chip AI training efficiency.
The memory-sharing architecture here sidesteps the coordination bottleneck by letting cores access neighboring cache directly, cutting the latency that kills error correction speed in distributed quantum systems.
A dedicated scheduling engine in hardware eliminates the software overhead when high-priority tasks arrive, shrinking latency in multi-chip AI systems where coordination delays compound across distributed processors.
The memory bottleneck thread gains a practical filter: Qualcomm's method identifies which data values actually compress well before wasting cycles on the rest, cutting wasted effort in moving model weights between storage and compute.
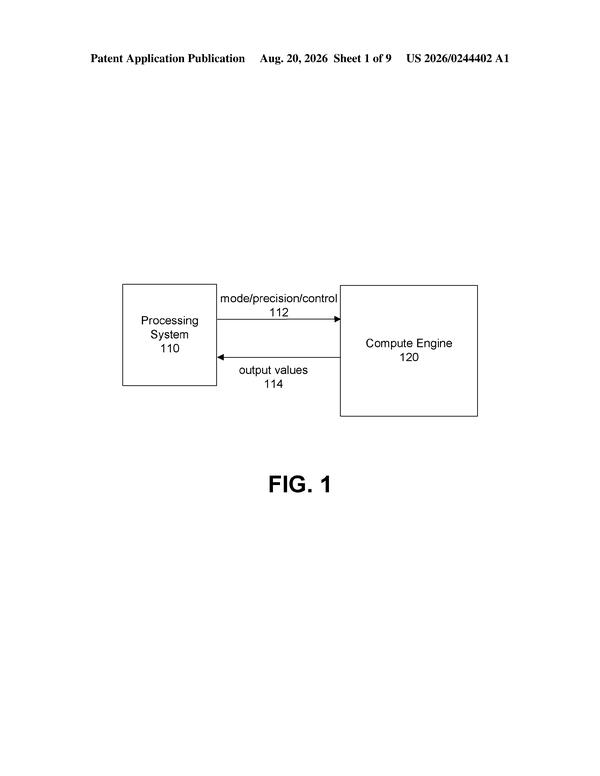
The memory bottleneck story gets a hardware angle: switching between floating-point and integer math mid-inference cuts the data moving between chip and memory, the actual constraint choking throughput in large models.
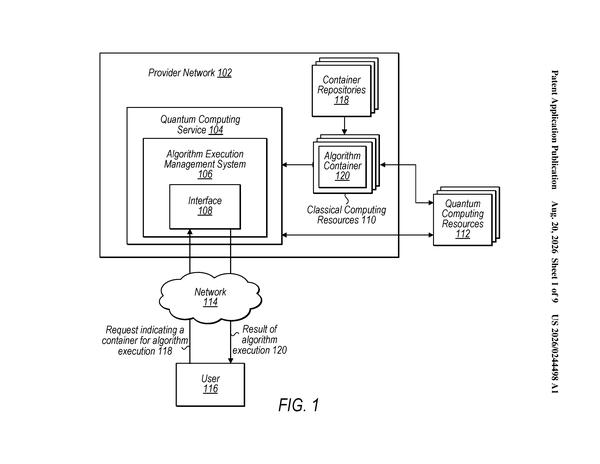
Automatic routing between quantum and classical processors moves the integration problem from user code into infrastructure, similar to how AWS already distributes conventional workloads across multiple machine types.
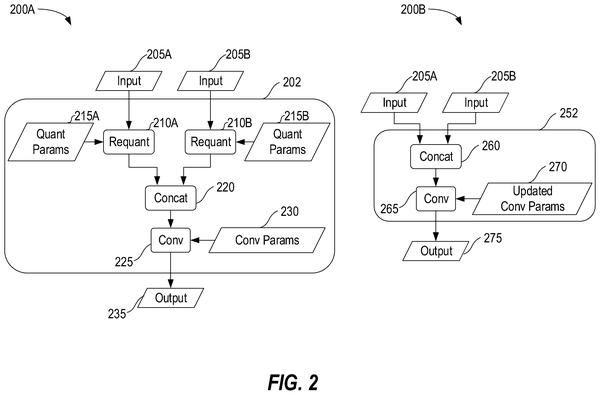
Fusing requantization into the data path itself rather than treating it as a separate pipeline stage cuts the conversion overhead that normally stalls sequential model execution on mobile processors.
Memory bottlenecks have pushed compute into storage itself. Qualcomm's translation layer lets multiple tasks virtualize a single in-memory processor, removing the serialization bottleneck that forces chips to choose between speed and coordination.
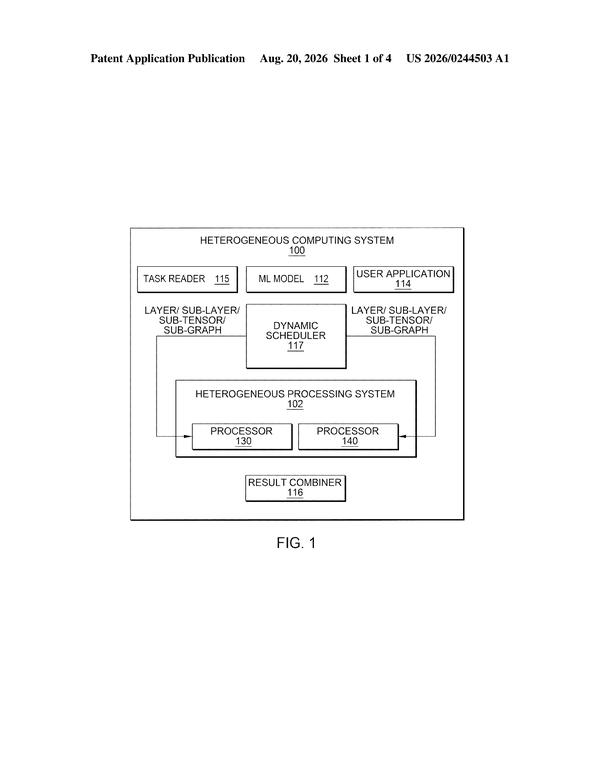
The coordination problem across heterogeneous hardware gets a concrete solution here. Intel's automatic workload distribution removes the manual engineering step that currently leaves chips underutilized in mixed-processor servers.
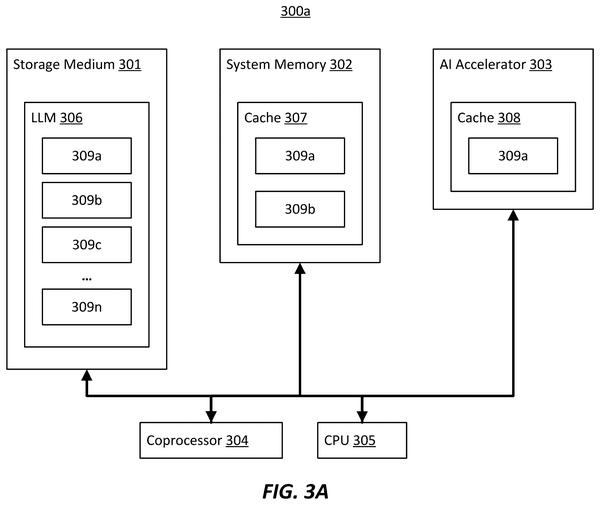
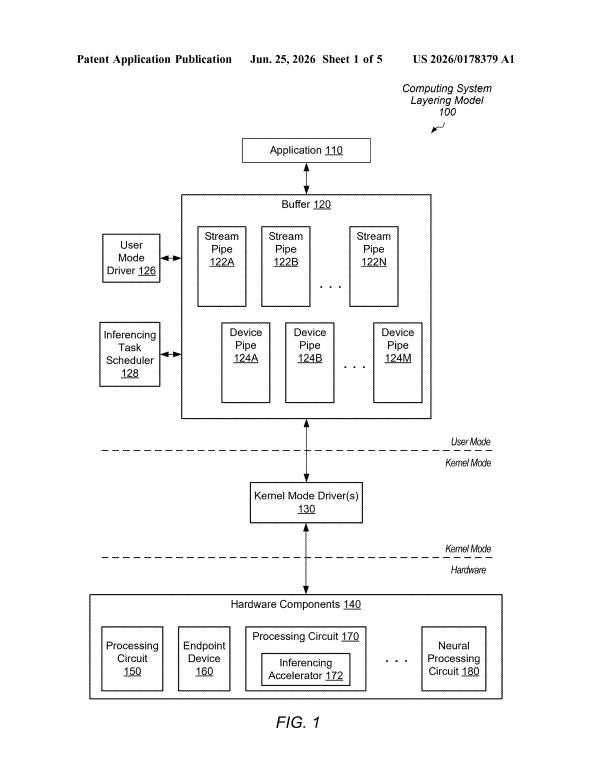
Faster AI responses depend on predicting which model weights the main chip needs next. This coprocessor prefetches data into cache, reducing the stall time between token generations.
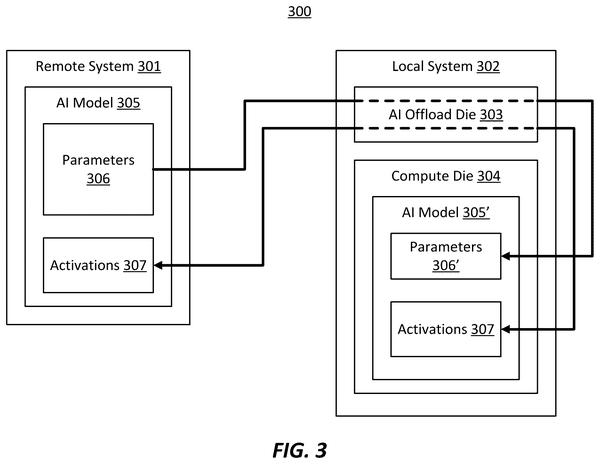
Task scheduling across device boundaries requires routing decisions in real time. Microsoft's offload die automates which model layers run locally and which ship to cloud, reducing the latency penalty of splitting computation.
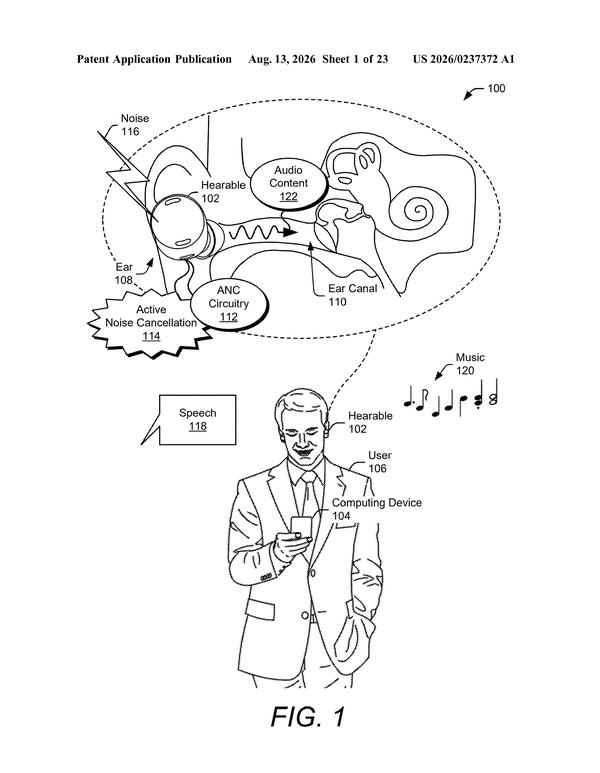
Data compression in audio processing: splitting noise cancellation into fast and efficient tracks lets chips skip full computation cycles and only run high-power operations when sound conditions change.
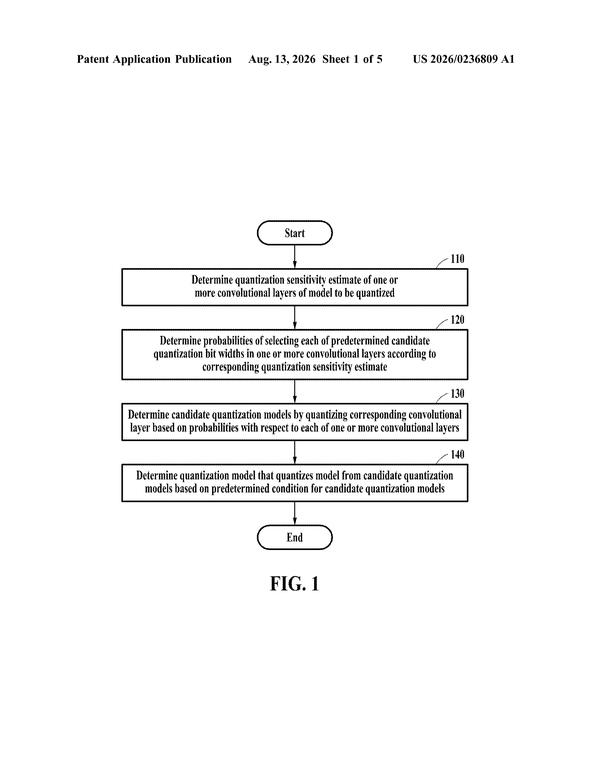
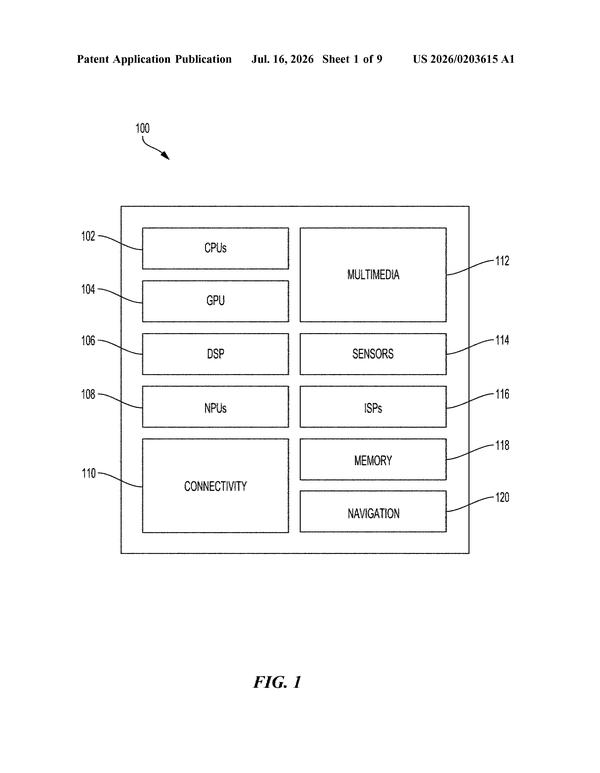
Data compression via quantization lets AI models run on phone chips by reducing mathematical precision while preserving accuracy, extending the chip wars into consumer devices where memory and power constraints are even tighter than data centers.
AI video processing needs to shed stored frames selectively rather than halt entirely. Qualcomm's method ranks frame snapshots by relevance, dumping redundant ones to keep models running on device.
Memory bottlenecks in AI training rely on sequential decompression of compressed images. Qualcomm's method parallelizes that decompression step, letting multiple image chunks decompress at once so processors stay busy rather than waiting for data.
Memory bottlenecks force choices between speed and capacity. Intel's system automates this by dynamically moving model layers between fast and slow storage at runtime, letting devices run larger models without redesigning hardware.
AI video restoration on phones has been bottlenecked by power consumption; breaking the filtering into sequential lightweight operations lets mobile chips deliver visual quality without exhausting the battery.
Memory interface translation has been a persistent friction point in multi-memory systems. Samsung's solution embeds a dedicated processor to handle protocol conversion between heterogeneous memory types, reducing the latency tax of asynchronous handshakes.
Memory access patterns during recommendation training consume enormous bandwidth. Samsung's method reorganizes how lookup data moves between storage and processors, reducing the fetch overhead that currently dominates training time.
Routing delays between processor sections drain energy even at microscopic scales. Google's patent embeds a dedicated dispatcher into the chip itself to shunt math operations directly to their target units without software overhead.
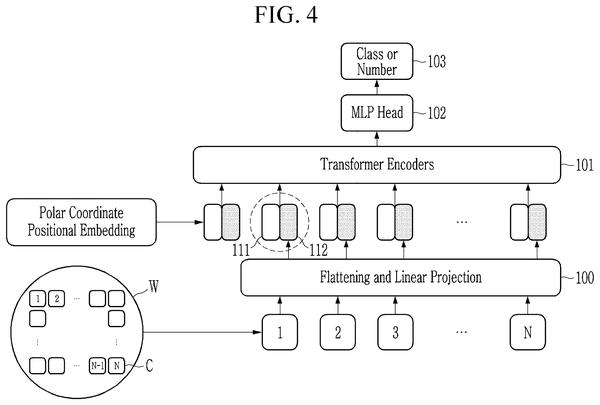
Chip localization on circular wafers requires the inspection AI to map physical position before defect detection. Samsung's polar coordinate approach solves this by establishing spatial reference before analysis begins.
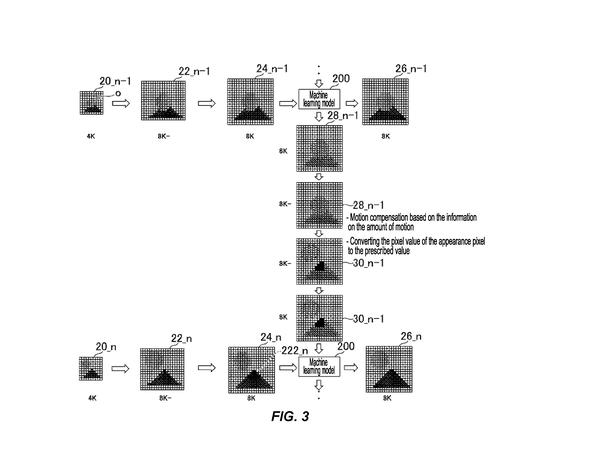
Data compression methods for maintaining temporal context across video frames reduce memory footprint in real-time inference, letting AI upscalers preserve multi-frame dependencies without sacrificing speed on edge hardware.
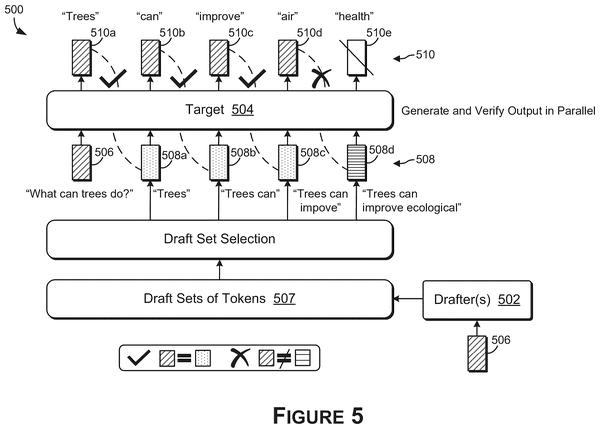
Faster inference means cheaper model serving at scale. Nvidia's draft-verify approach lets a smaller model propose token candidates before the main model validates them, cutting compute per output without sacrificing quality.
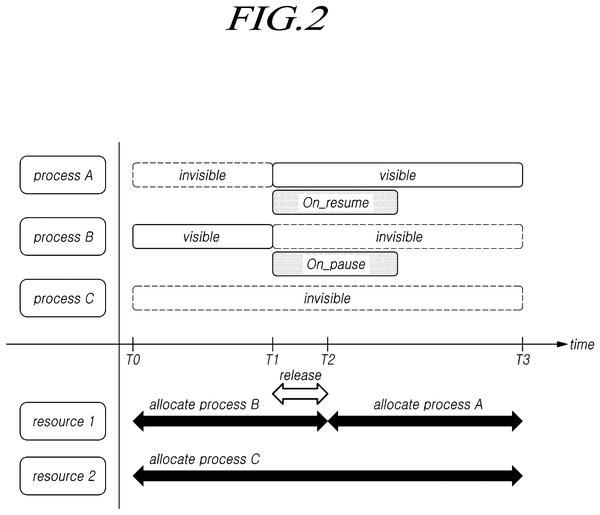
Task scheduling across competing processes keeps graphics smooth by letting the display process jump ahead when it needs shared resources, rather than waiting for background apps to finish.
Uneven memory use during training wastes space on dormant connections. IBM's approach identifies which neurons actually matter and reserves memory for those, freeing up space that typically goes unused.
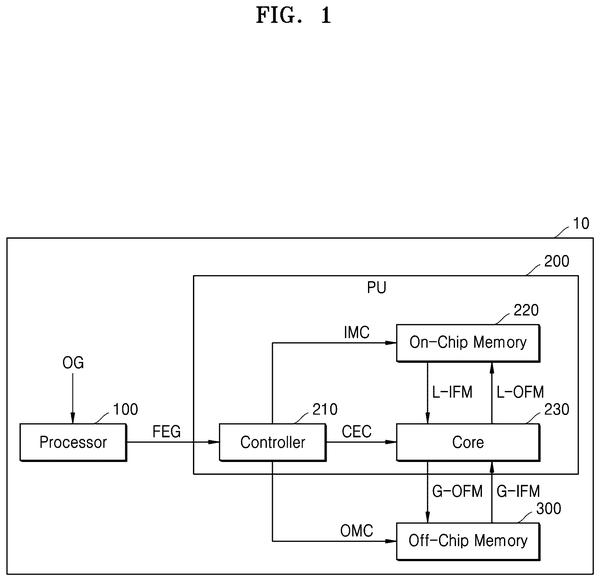
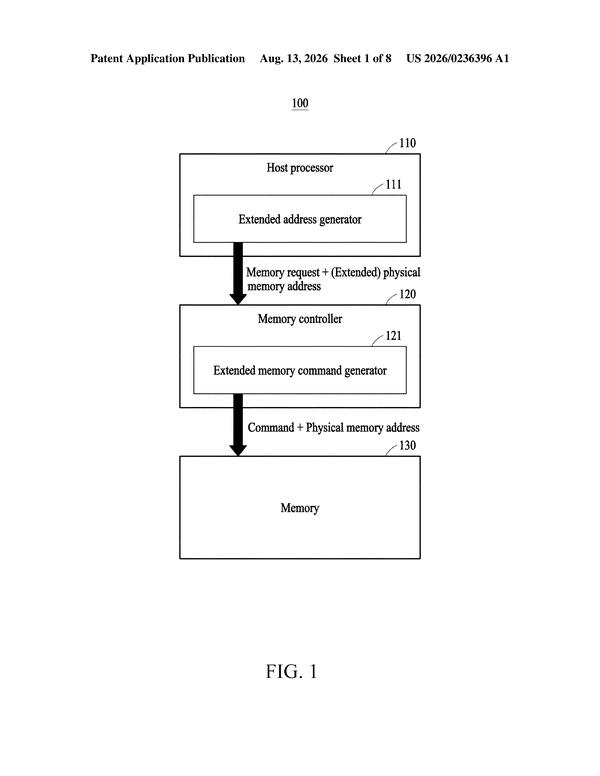
Offloading memory translation from the processor to a dedicated controller frees up CPU cycles for compute work, directly attacking the memory bottleneck that slows down AI inference on edge devices.
Data compression introduces unpredictable errors across different inputs. Qualcomm's approach pinpoints which layers degrade most and applies layer-specific corrections without retraining the model.
Distributing model storage across separate nodes reduces what any single machine must hold in memory, attacking the memory bottleneck that forces companies to buy expensive unified systems today.
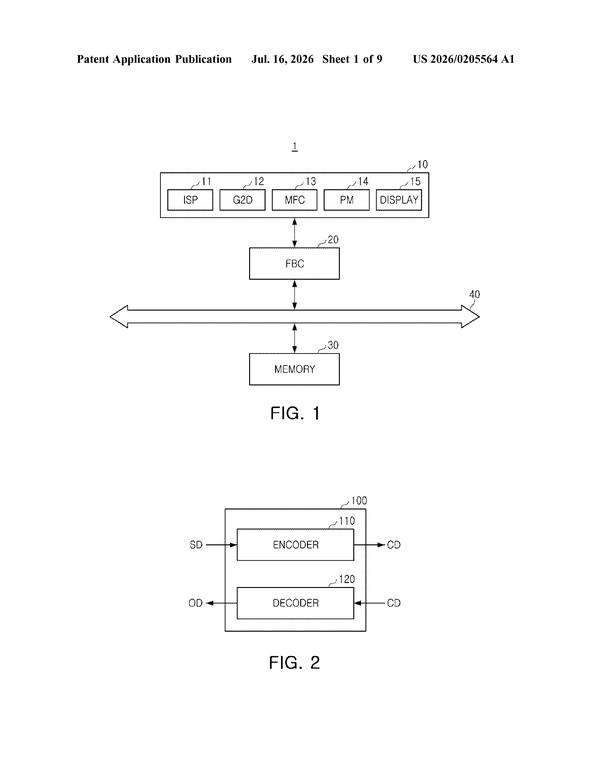
Better video compression in AI chips means less data shuttling between memory and processors, directly easing the memory bottleneck that slows multi-chip AI systems.
Better power prediction means chips burn less energy waiting for heavy tasks that never come, directly cutting the battery drain that comes from over-provisioning.
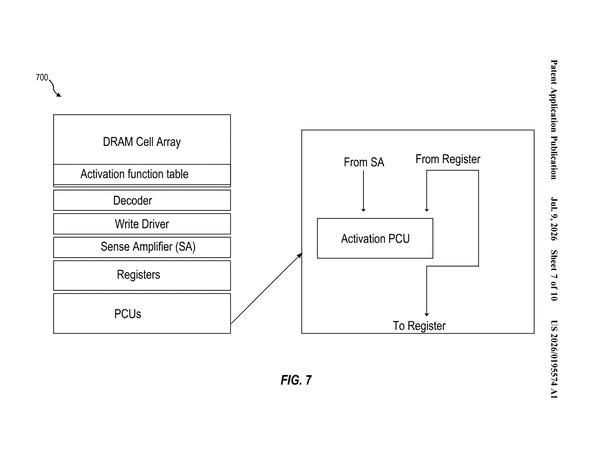
Faster AI inference on a single chip means less time waiting for math results. Xilinx's lookup tables let the chip skip repeated calculations of activation functions, cutting latency where models spend most of their compute time.
Dynamic hyperparameter adjustment during inference reduces the need for separate model versions tuned to different workloads, consolidating what the field has approached as a chip coordination problem into software control.
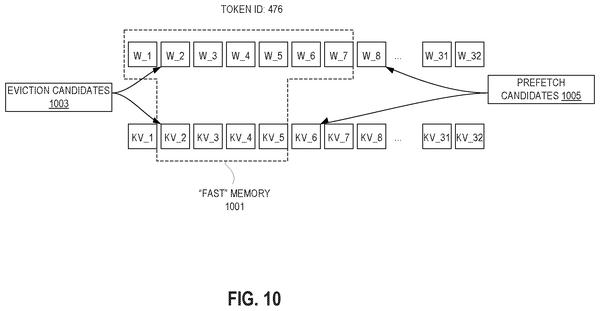
Memory bottlenecks continue to define AI chip design constraints. Samsung's patent targets KV cache growth during inference, showing how selective retention of attention data could let models run on memory-constrained devices without retraining.
Memory bandwidth constraints have forced chip designers to choose between raw speed and efficiency. Xilinx's approach lets a single chip dial down only when export rules actually require it, keeping performance where the math allows.
The memory bottleneck story gains a concrete solution: Intel shrinks the numerical payload of dot products down to 4-bit format, then converts on the fly rather than storing expanded data. Keeps the math tight without requiring new hardware primitives.
Staged conversion with single rounding point cuts accumulated errors during format shifts, a basic lever for preventing precision loss across long calculation chains on multi-chip systems.
Memory bandwidth has been the watchlist's throughline; this filing shows how on-chip parallelism can shrink the data movement required for a single operation.
A single hardware instruction that performs data normalization eliminates the multi-step software conversions that currently consume chip cycles between calculations, reducing the intermediate memory traffic that slows down AI workloads.
Offloading decompression to a separate hardware engine keeps the main processor free for calculations, addressing the data preparation bottleneck that slows throughput in multi-chip AI systems.
Automated calibration across process variation lets a single tuning profile work on chips with different electrical characteristics, shrinking the coordination burden in high-volume production.
The coordination problem deepens: AMD's method prevents GPU cores from sitting idle by pipelining calculations across separate core groups, shifting focus from memory bottlenecks to synchronization costs within a single chip.
The watchlist so far focuses on multi-chip coordination as a bottleneck. This filing shows how keeping that coordination alive through link failures prevents the restart delays that cascade across entire chip packages.
Memory bottlenecks have dominated this watchlist; Apple's compression method via lookup tables suggests the path forward isn't shrinking the weights themselves but reducing how often the chip retrieves them from storage.
Selective eviction from the KV cache lets models drop old context without forcing expensive reloads of recently used data, directly addressing the memory pressure that limits how long AI conversations can run.
Specialized cores sit idle while general-purpose ones bottleneck on AI workloads. Automatic routing keeps accelerator hardware fed with matching tasks, reducing scheduler overhead.
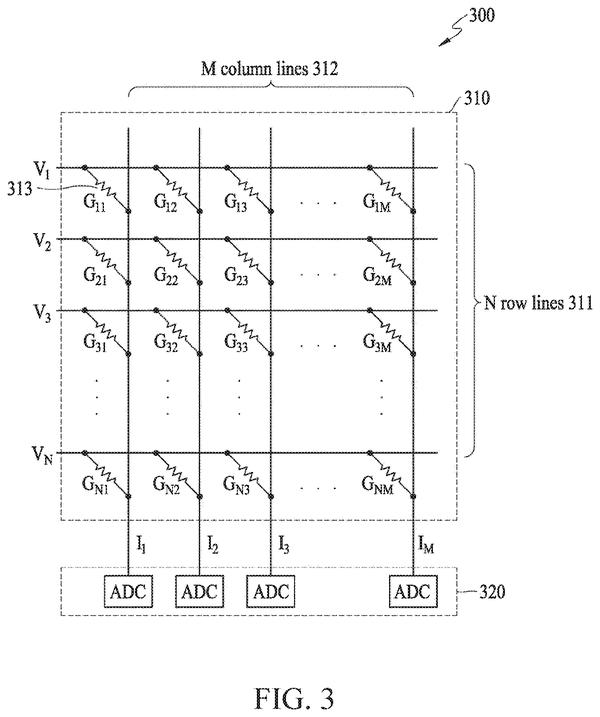
Sending voltage pulses through resistor grids to compute multiplication directly in hardware sidesteps the energy cost of shuttling data between memory and processors, one of AI chip design's recurring constraints.
The watchlist has focused on memory bottlenecks within single chips; this patent moves coordination outward, showing how to distribute model layers across multiple processors to sidestep the bottleneck entirely rather than optimize around it.
Heterogeneous chip pairing routes inference and training to specialized processors, reducing idle time on general-purpose silicon during large model development.
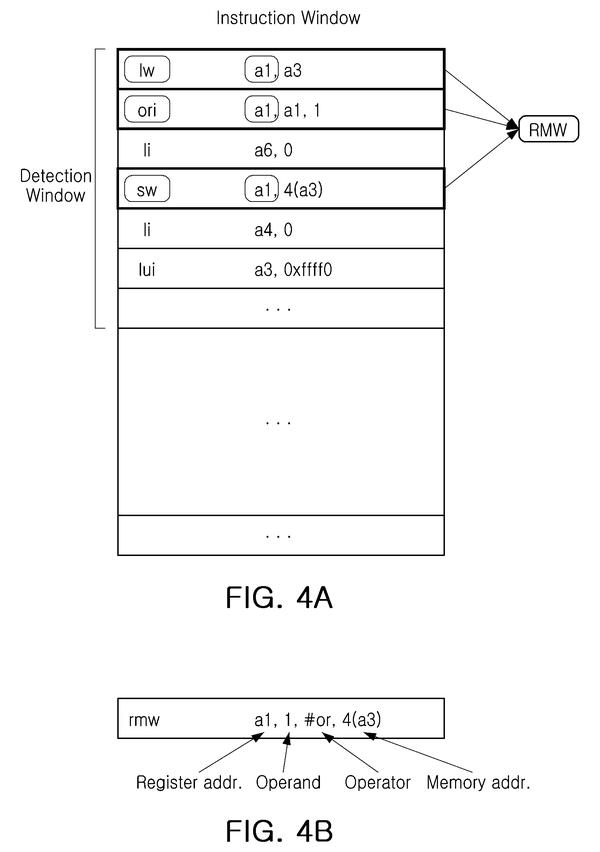
The memory bottleneck watchlist has focused on sequential task handling; Samsung's approach adds parallelism within a single core by dedicating hardware to overlap read-modify-write operations with other memory instructions, reducing idle cycles.
Memory bottlenecks force chips to pick between speed and precision. This filing shows how to switch between integer and floating-point math dynamically, letting chips avoid slow data movement while keeping calculations accurate.
Embedding computation directly into cache memory eliminates repeated data shuttling between storage and processors, reducing the energy cost of moving information around the chip rather than processing it.
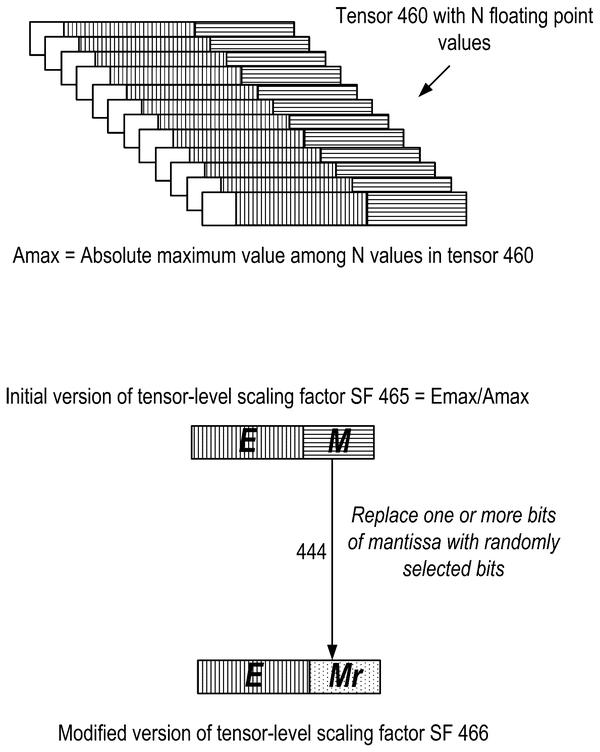
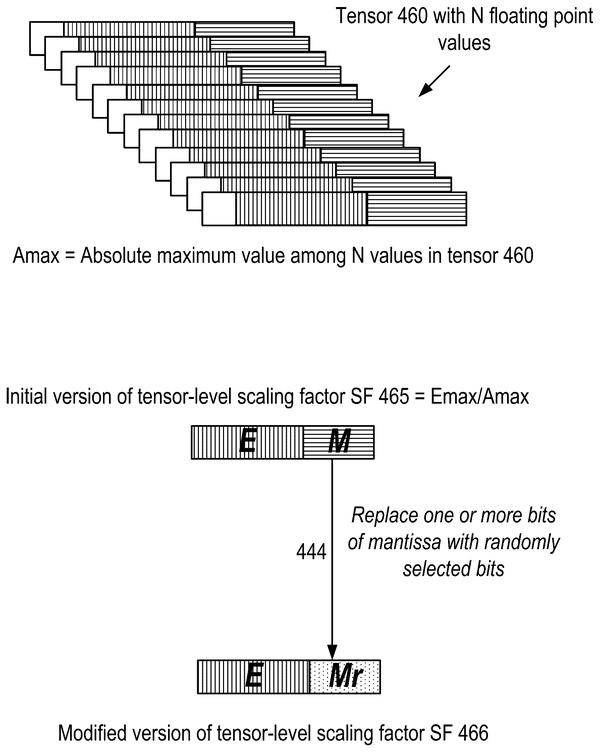
When AI models train on low-precision math to save power and time, tiny rounding errors pile up and degrade accuracy. Nvidia's new patent proposes injecting controlled randomness into the scaling step to fight that drift.
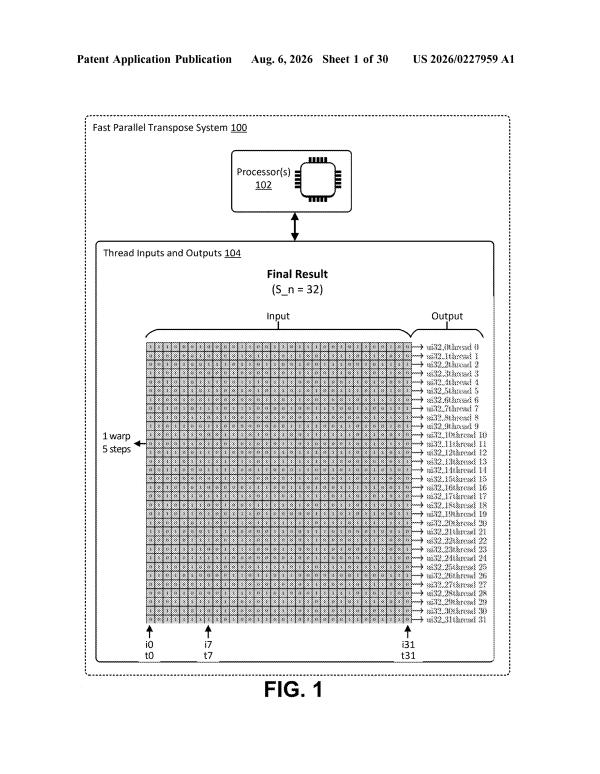
The memory bottleneck watchlist gains a specific solution: pre-transposing data to match how hardware naturally reads it, eliminating repeated skip patterns that slow training workloads.
Dynamic power gating of network ports based on traffic prediction directly targets the energy overhead of inter-chip communication, where idle connections waste power across the switching fabric connecting multiple AI accelerators.
Memory bottlenecks have dominated this watchlist; Samsung's patent adds a specific fix by pre-staging training data in cache to eliminate compute idle time during the load-and-format stages that currently stall GPU cores.
Memory bottlenecks have pushed chip designers toward computation shortcuts. Xilinx trades multipliers for lookup tables, converting a power drain into a storage problem that favors dense memory architectures.
The watchlist has focused on memory bottlenecks and data compression. This filing shows how to preserve calculation accuracy when chips use compressed numbers, keeping the math from degrading as it runs on resource-constrained devices.
Adaptive compression that lets deployers trade model size for accuracy on demand addresses the compression granularity problem: instead of one fixed compressed version, this approach generates multiple operating points along the size-quality spectrum.
Memory bottlenecks persist partly because power goes to both subsystems equally. AMD's approach dynamically reallocates power from memory to processors during compute spikes, treating the power budget as fluid rather than fixed.
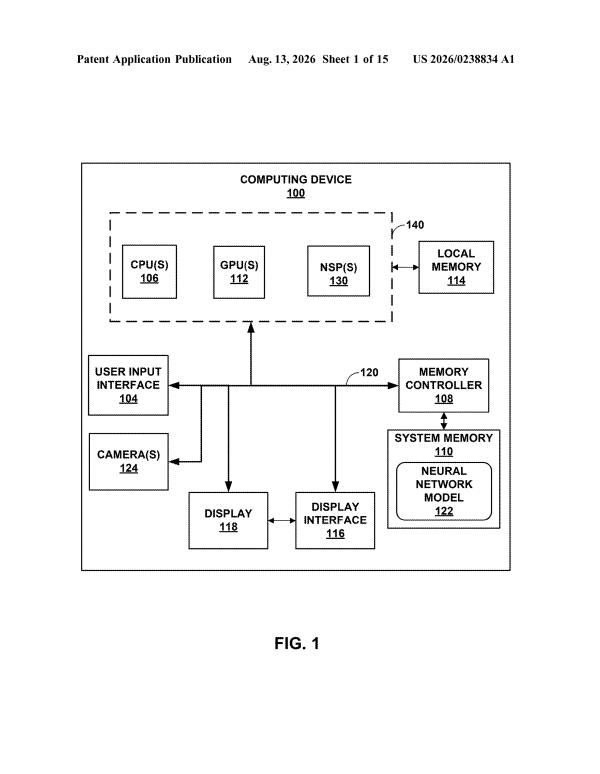
A selection layer that routes user-chosen models to a dedicated inference chip, rather than locking devices to a single factory-installed model. Solves the coordination problem of matching variable software (the model) to fixed hardware (the chip).
Pipelining model layers across chips so each processor handles one stage sequentially eliminates repeated trips to external memory, reducing the bandwidth bottleneck that slows multi-chip inference.
Memory bottlenecks on mobile chips force selective computation: this patent skips redundant AI work between frames, letting interpolation handle the cheaper frames while key-frame processing absorbs the real load.
The memory bottleneck watchlist gains a compression method that randomizes quantization factors rather than applying uniform scaling, potentially squeezing more efficiency from the data movement between chips and memory.
Memory overhead in vision models gets trimmed here: the patent removes a classification token that AI chips process even when the task doesn't require categorization, cutting wasted computation.
Letting programmers manually adjust number scaling before computation pushes back against accumulated rounding errors in compressed-number arithmetic, a direct way to manage precision loss across the data compression challenge.
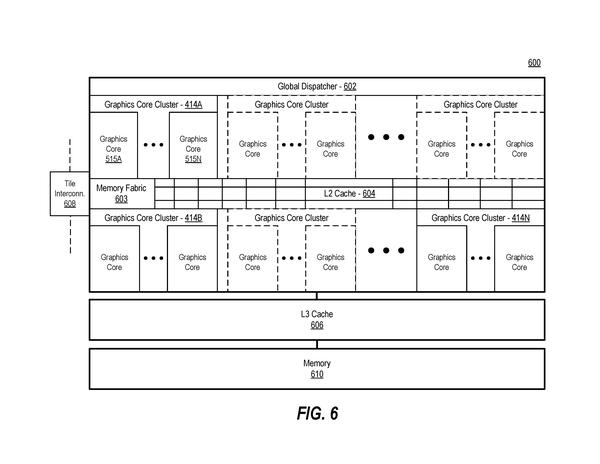
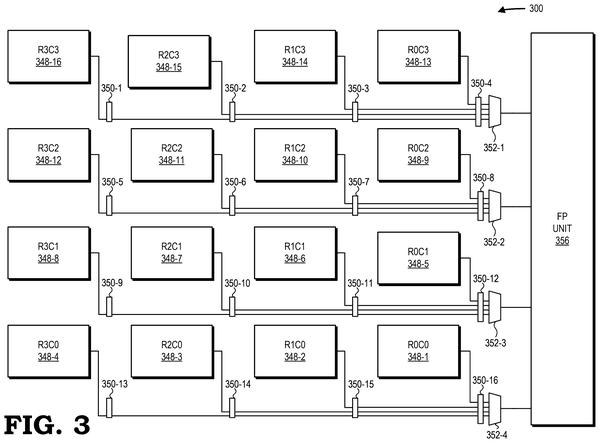
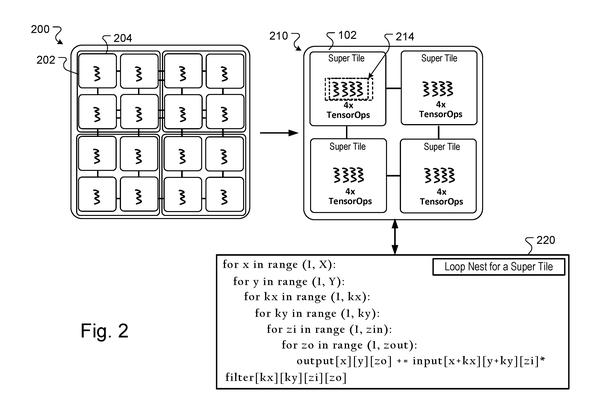
The watchlist so far has mapped memory as the constraint, chips struggle when processing units compete for data. Google's filing proposes pooling memory across tiles with coordinated access, moving from isolated buffers toward shared reservation.
Task scheduling across chips gets more concrete here: IBM moves from static division rules to adaptive partitioning that responds to actual hardware constraints and model structure in real time.
The watchlist so far has focused on memory bottlenecks and data movement between chips. This filing shifts focus to coordination within a single chip, adding ordered message delivery to the plumbing.
Caching intermediate results across repeated inference steps cuts redundant computation in image generation pipelines, directly reducing the memory and processing cycles that bottleneck multi-chip AI workloads.
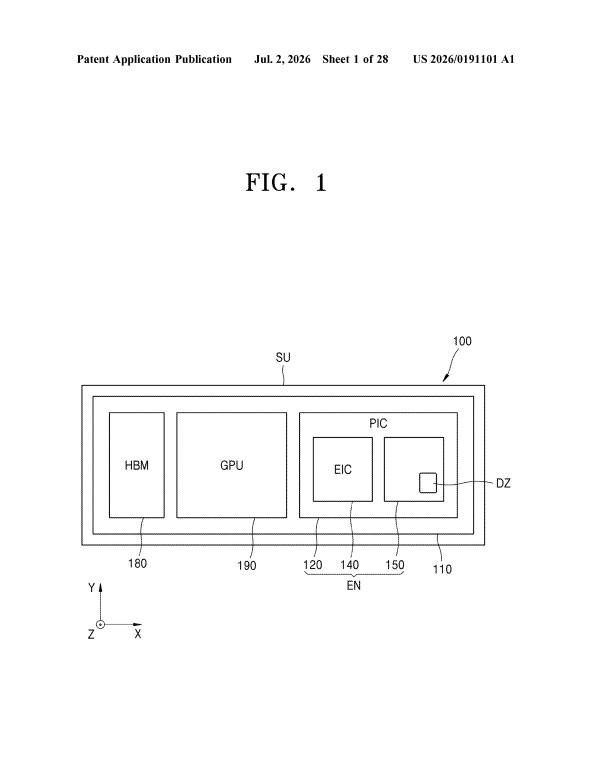
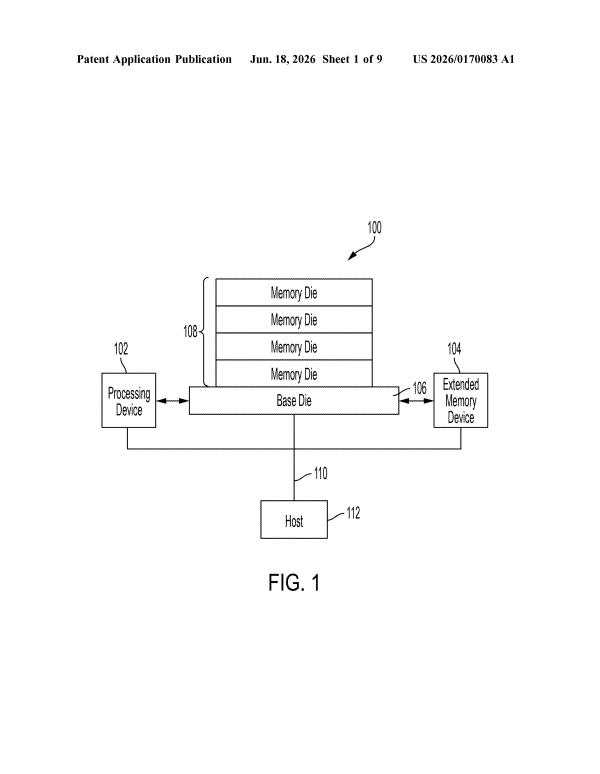
The memory-bottleneck problem gets a physical solution: Samsung embeds processors directly in the memory package to cut data movement distances and the energy cost that follows.
Data compression moves upstream: Intel wants to prune models on the control chip before they ever reach the accelerator, cutting transfer time and memory costs in the handoff between server and specialized hardware.
Skipping multiplication operations on zero and near-zero values reduces the actual compute load a chip must handle, directly shrinking the memory and power demands that constrain multi-chip AI systems.
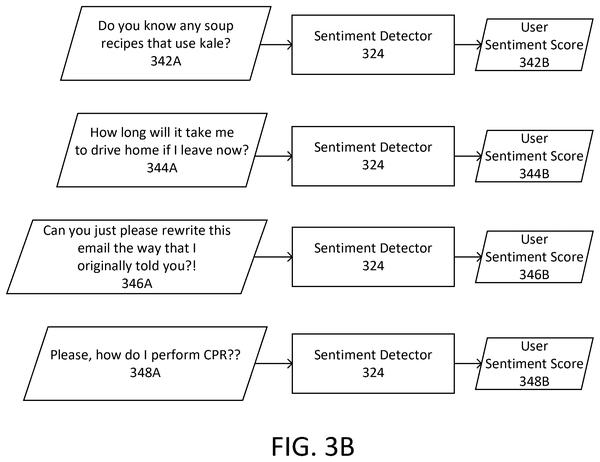
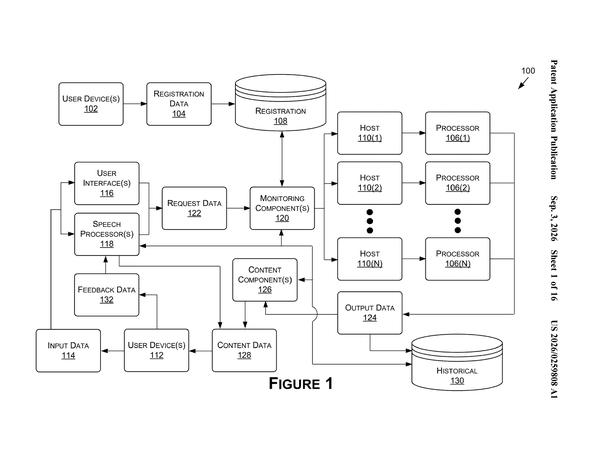
Detecting user frustration from repeated queries lets schedulers prioritize requests based on satisfaction signals rather than arrival order alone, shifting task ordering from pure queue management to behavioral feedback.
Splitting model layers between device and network based on what each can handle locally cuts memory overhead and lets phones run larger models without exhausting batteries.
Dual-mode matrix multiplication on fixed data eliminates the transpose operation that normally requires copying and repositioning values across the chip, cutting a major movement bottleneck in forward and backward propagation.
Splitting inference into a prefill stage that builds the KV cache and a decode stage that generates tokens lets the system discard intermediate attention data, shrinking memory footprint during the computationally cheaper second phase.
A software abstraction layer lets developers coordinate multi-machine training runs without writing low-level networking code, shifting the coordination burden from application developers to the infrastructure itself.
Moving image data between chips via embedded routing instructions lets the interconnect hardware handle stitching automatically, bypassing the software overhead that usually coordinates multi-camera feeds.
Predictive thermal throttling uses recent workload history to cut clock speed before temperature spikes, eliminating the lag between heat buildup and system response.
Predictive frequency scaling cuts the delay between incoming AI workload and power adjustment, moving from reactive throttling to proactive chip tuning based on job patterns.
Local memory coherence across chip boundaries demands constant synchronization overhead. Intel's design automates cache bookkeeping between chips, reducing the coordination work that would otherwise fall to software scheduling layers.
Automatic partitioning of neural network layers across heterogeneous processors removes manual configuration bottlenecks when distributing training workloads, shifting the coordination problem from human engineers to runtime algorithms.
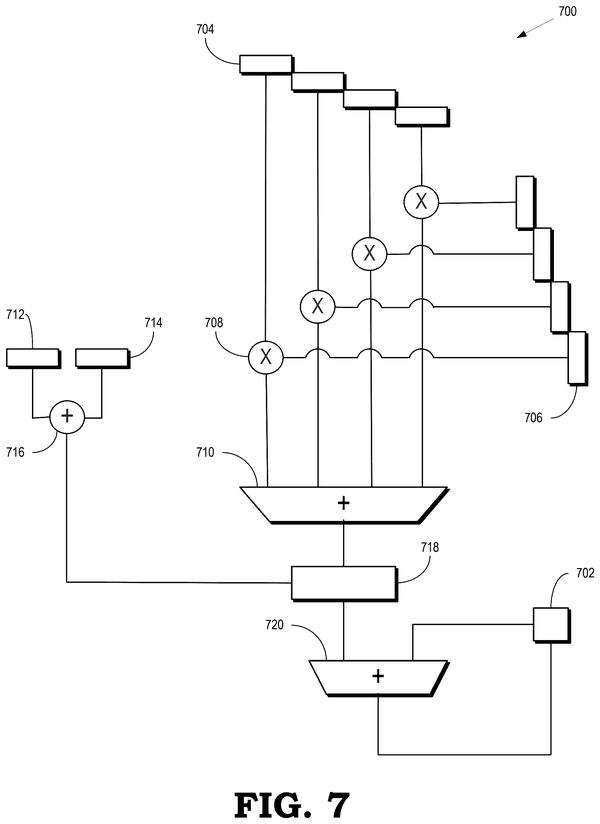
Merging matrix multiplication and accumulation into a single pipeline stage cuts round-trip delays between compute units, directly shrinking the memory-access overhead that slows multi-chip AI inference.
Within the task scheduling layer, this reveals how to move work between chips without losing state, solving the coordination problem when one path gets blocked.
Task scheduling across cores determines which processor handles each workload, directly affecting power consumption. Samsung's method scores cores on suitability to route work efficiently and reduce energy waste.
Direct paths between processing units for certain AI math operations bypass the standard routing layer, lowering latency and energy costs when heavy computational tasks communicate with specialized accelerators.
The watchlist tracks how chips reduce wasted cycles on routine tasks. Qualcomm's filing shows that selective approximation of math operations could cut energy costs without sacrificing accuracy, extending the gains beyond just memory and scheduling.
The memory bottleneck watchlist gains a concrete solution: pipelining data streams so processors never stall between batches. This confirms the approach of hiding latency through overlapped computation rather than just making memory faster.
Fusing matrix multiplication and rotary position encoding into a single kernel operation eliminates the intermediate memory write-read cycle that currently forces data out to slower storage between these back-to-back computations in language model inference.
Within the power-efficiency track, Intel's FP8 hardware design shows a vendor-specific bet on reduced precision as the path forward rather than algorithmic workarounds.
Dynamic model resizing based on available device resources addresses the memory bottleneck by letting a single AI model adjust its footprint rather than requiring separate lightweight and full versions.
Faster matrix multiplication through lookup tables shrinks the compute cost per inference, directly attacking the memory-bandwidth bottleneck that slows multi-chip AI systems.
Memory bandwidth during image rendering slows when compression treats all pixels equally. Samsung's approach varies compression strength by screen position, reducing the data shuttled between processor and memory.
Data reshaping on AI chips typically requires chained operations; Nvidia's single-instruction collapse reduces the overhead that slows down image processing pipelines.
Offloading work between a power-hungry processor and an efficient one without routing everything through shared memory could shrink the coordination overhead that currently forces chips to choose between speed and battery life.
AI audio models could train on consumer hardware if they stop caching every intermediate result and regenerate them as needed, freeing up the memory that currently forces training onto expensive server clusters.
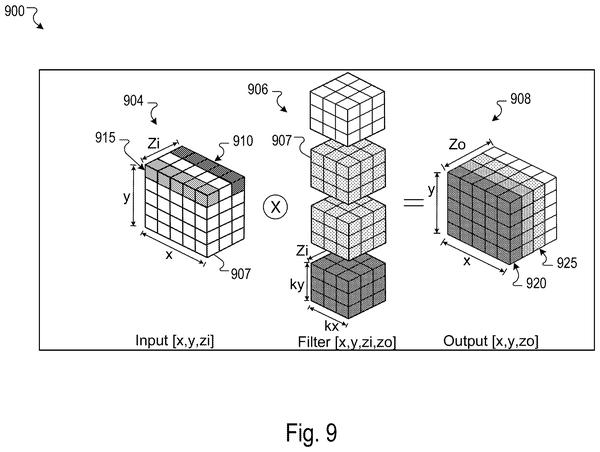
Data compression in neural networks gains ground through deduplication of near-identical filter kernels, reducing memory footprint without architectural changes to the model itself.
Parallel execution of matrix and vector math reduces idle time on the processor, since different calculation types no longer have to queue behind each other. This directly confronts the coordination problem between specialized circuits on a single chip.
Faster AI inference means models can process more data before hitting memory limits, directly attacking the coordination problem of distributing compute across chips.
Faster image processing means AI chips can handle vision tasks without choking on the comparison work that usually demands extra memory bandwidth. This patent shows a way to spread that load across the chip's spatial layout instead of serializing it.
Shrinking the numerical precision of deployed models cuts both computation and memory footprint, directly easing the data movement bottleneck that slows multi-chip AI systems.
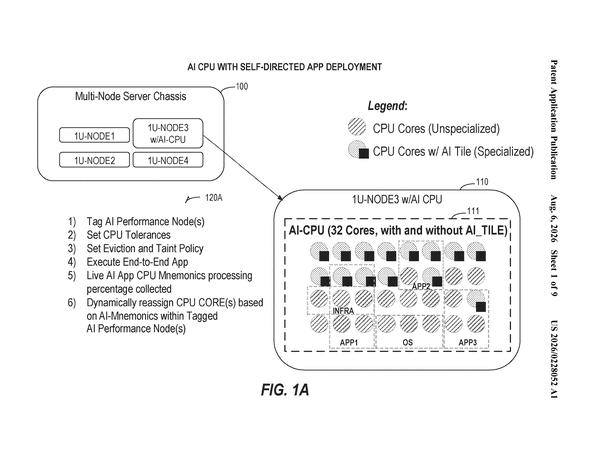
Task scheduling across CPU and accelerator resources becomes flexible when cores can migrate between them rather than stay locked in separate domains, letting workload demands drive allocation instead of fixed hardware boundaries.
Better scheduling of which model sections load into fast memory cuts idle time when multiple specialized AI functions run sequentially on a single chip, directly attacking the memory bottleneck problem across the AI chip timeline.
Memory bandwidth limits how fast GPUs can run AI workloads. Nvidia's system reduces redundant fetches by detecting when multiple threads request identical data and consolidating those requests, lowering power consumption in the process.
Memory bottlenecks on edge devices require shrinking the working dataset an AI model needs during inference. Qualcomm's approach merges consecutive processing steps into single fused operations, reducing the intermediate data that must stay resident on chip.
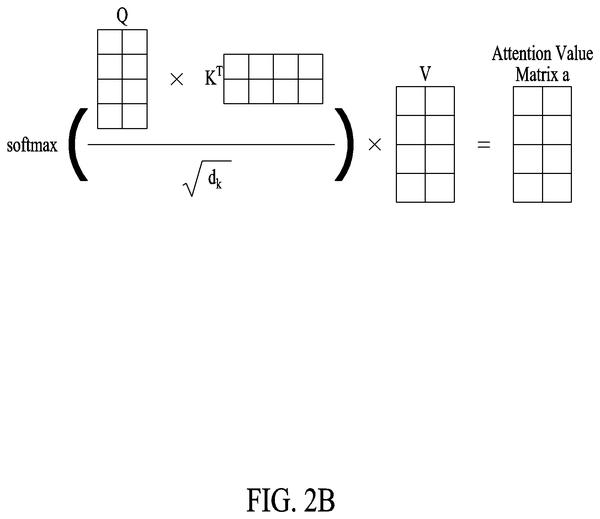
Faster inference on edge devices becomes possible if softmax, the calculation that ranks outputs in every AI model, can run without draining power. This filing shows a direct path to shipping capable AI locally instead of routing queries to distant servers.
Offloading cryptographic operations to idle matrix engines means AI chips could handle privacy tasks without dedicated crypto hardware, reducing die space and power overhead in accelerators optimized for training.
Dynamic model pruning during inference addresses the power-efficiency bottleneck by letting AI models shed unnecessary computation layers when thermal or battery constraints hit, keeping performance within acceptable bounds rather than forcing full shutdown.
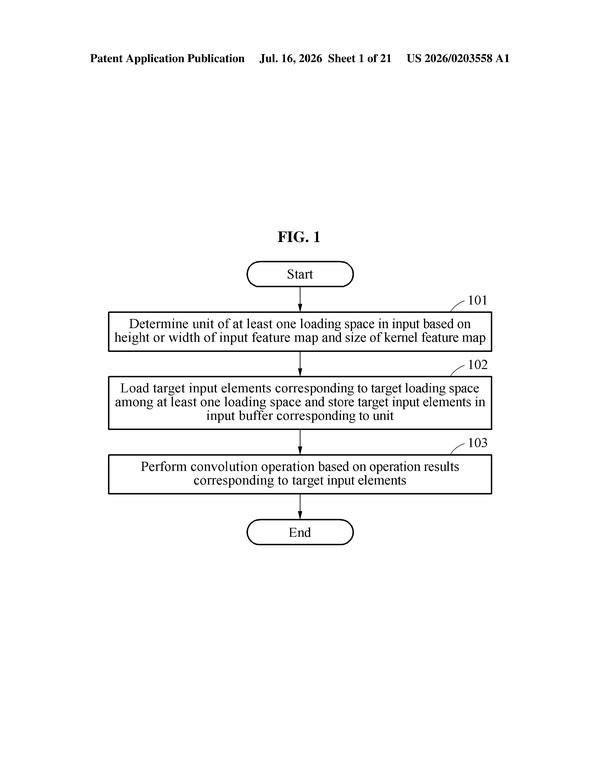
Redundant multiplication in convolution operations drains chip efficiency. Samsung's approach predicts which calculations yield zero before execution, freeing hardware cycles for productive work instead of wasting them on null results.
Better GPU utilization across chips reduces the power wasted on idle hardware, a key bottleneck when coordinating work across a multi-chip cluster running AI models.
The memory bottleneck watchlist gains a concrete solution: reorganizing how numerical values sit in storage so matrix multiplication pulls only necessary data, cutting wasted bandwidth during the operations that dominate AI workloads.
Predictive prefetching of database records into cache memory eliminates round-trip delays by staging likely-needed data before queries arrive, reducing stalls from storage access latency.
Within the coordination problem: Samsung's approach to latency hiding lets a processor switch away from stalled requests rather than block entirely, reducing the idle time that compounds when multiple chips coordinate across memory hierarchies.
Within the memory bottleneck problem, this filing proposes compute-in-memory as a solution: shift calculations into the storage layer itself rather than ferrying data back to the processor repeatedly.
Within the memory-and-speed bottleneck, this patent targets compute itself. By replacing multiplication operations with table lookups, Intel sidesteps the energy cost of arithmetic entirely, trading silicon space for clock cycles.
Memory efficiency joins the watchlist alongside scheduling and coordination: Intel's approach eliminates wasted slots when low-precision values don't align with standard memory widths, directly reducing the bandwidth crunch that hampers multi-chip AI systems.
Compressing intermediate calculation results on-chip and decompressing them on demand buys memory space without moving data off-chip, directly addressing the storage bottleneck that forces choices between model size and inference speed.
Memory bottlenecks have forced chips to shuttle lookup tables back and forth between processor and storage. Samsung embeds these tables directly in memory, eliminating that round trip entirely.
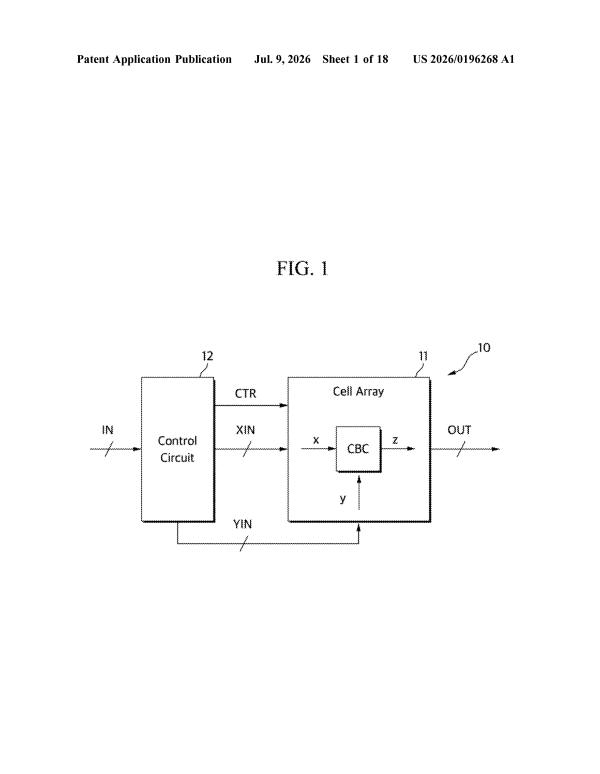
A computing bit cell that performs arithmetic operations inside the memory itself eliminates the energy cost of shuttling data between storage and processor, directly confronting the memory bottleneck that dominates power consumption in AI workloads.
Fusing layer normalization into the matrix multiplication operation itself cuts the arithmetic overhead that recurs across every training step, removing a bottleneck that compounds across billions of operations.
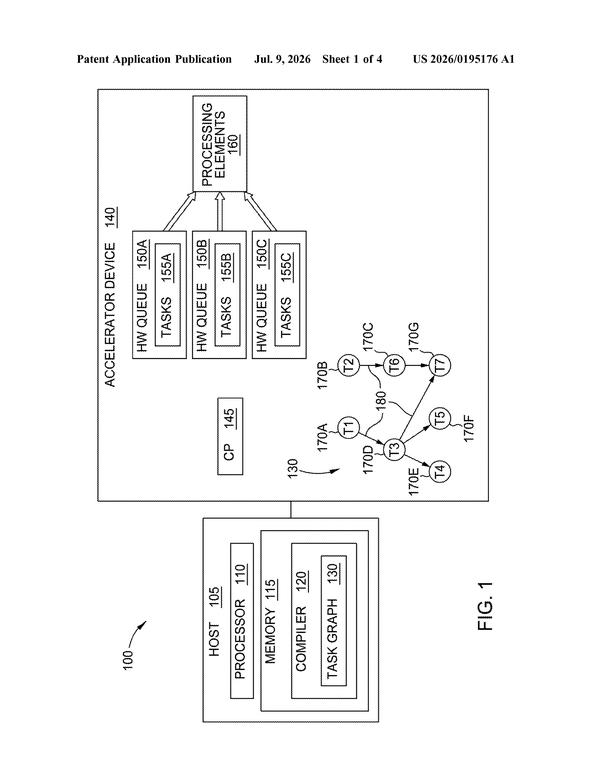
Autonomous task scheduling on accelerators reduces idle cycles by letting chips pull work when ready rather than wait for CPU handoffs, directly addressing coordination delays between processors.
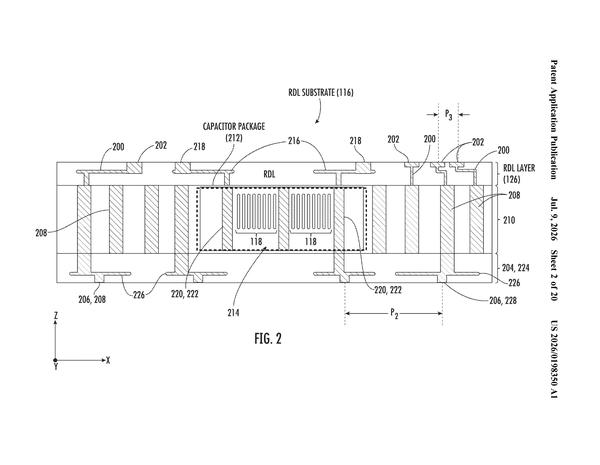
Memory and power delivery have separate demands. By embedding capacitors in the chip's wiring layer itself, Qualcomm cuts the distance power travels, reducing the voltage noise that degrades performance.
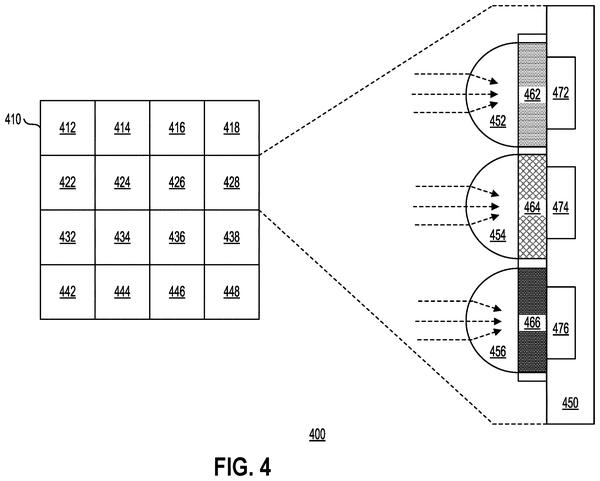
Performing analog multiplication directly in the pixel array cuts data movement to the main processor, addressing the memory bottleneck that limits real-time AI inference on edge devices.
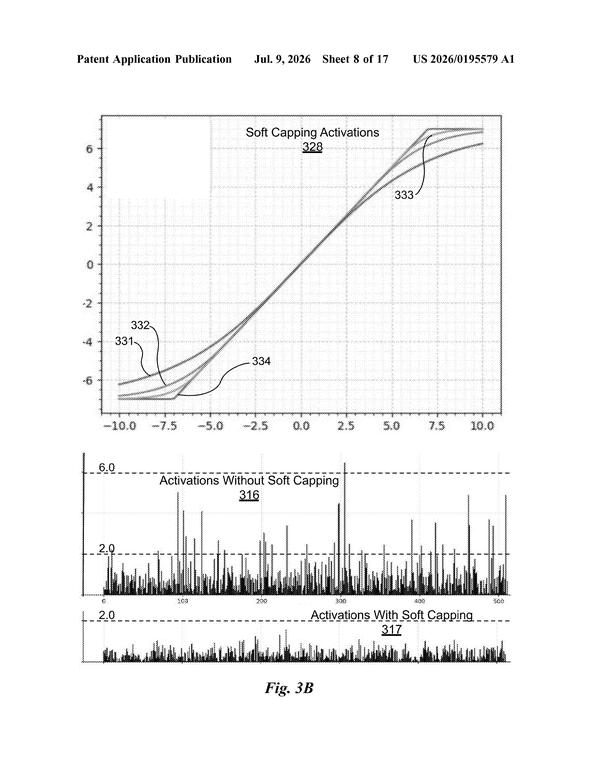
Reformulating softmax to avoid expensive exponentials cuts the compute time for one of AI's most repetitive operations, easing the load on resource-constrained inference chips.
Extreme quantization to one or two bits per number cuts the arithmetic workload in processor pipelines, directly addressing the compute bottleneck that forces current AI chips to spend cycles moving data between memory and execution units.
Memory bottlenecks slow training partly because stabilization checks run repeatedly inside each layer. Nvidia's method performs these checks less often, cutting memory traffic without destabilizing the math.
Dynamic scaling of interconnect bandwidth based on real-time workload demand cuts idle power waste in multi-chip systems, a key lever for improving energy efficiency in AI accelerators beyond just faster processing.
Embedding computation inside memory cells themselves eliminates the data shuttle between processor and storage, directly shrinking the bandwidth bottleneck that the watchlist tracks across multi-chip AI systems.
The watchlist has shown memory bottlenecks and multi-chip coordination as separate problems. Nvidia's filing merges them: routing tasks based on measured connection speed between specific hardware pairs, not assuming uniform bandwidth across the cluster.
The coordination problem gets concrete: keeping expensive accelerators fed means pushing data prep onto cheaper general processors in real time, not sequentially.
Offloading early-stage AI processing to edge devices shrinks the data stream sent between chips, directly attacking the memory bottleneck that plagues distributed inference systems.
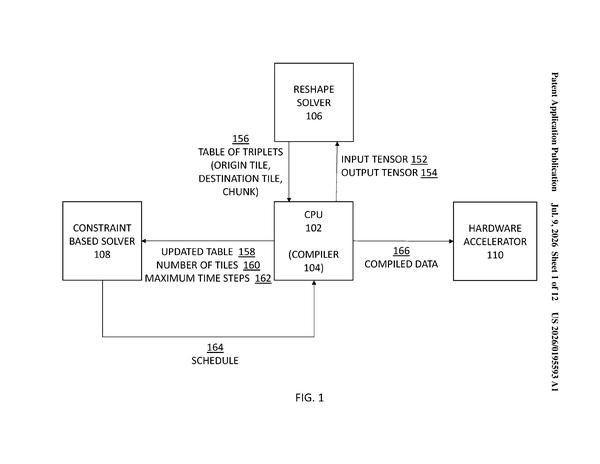
Predictive scheduling that identifies and eliminates circular data movements during reshape operations, shrinking the idle time chips spend shuffling memory instead of computing.
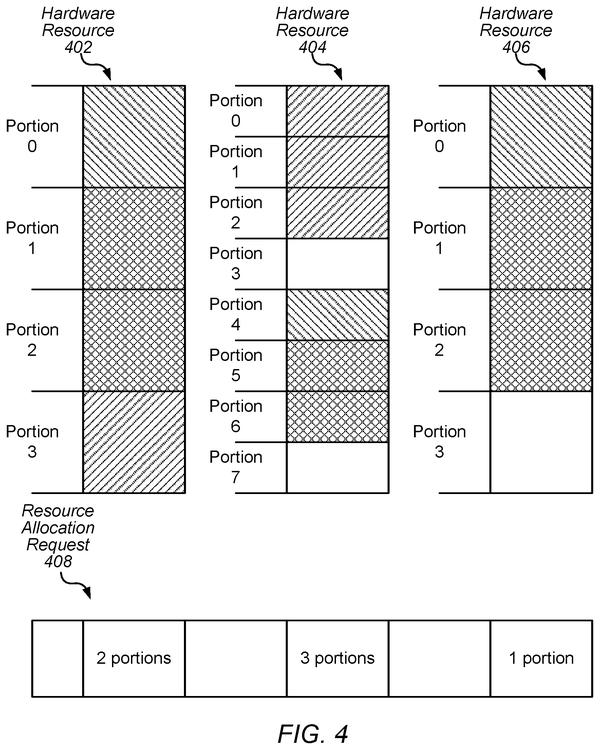
Memory contention among multiple workloads has emerged as a coordination bottleneck; IBM's approach predicts and pre-allocates scratch space to prevent the scramble that slows chips under load.
A prioritization layer that lets the network tell the phone which AI tasks matter most when multiple demands compete for the same wireless bandwidth and processor cycles.
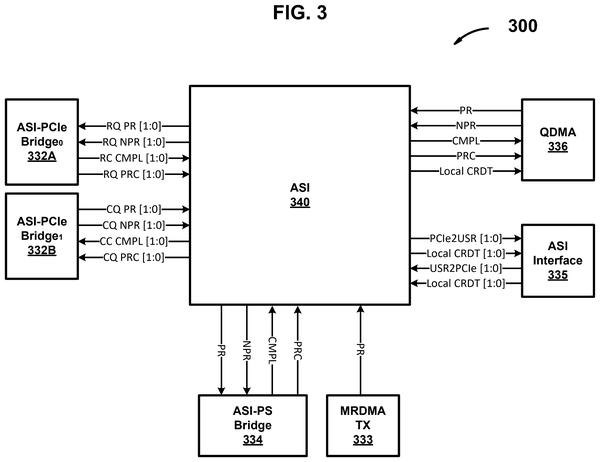
Interposer chips with built-in memory controllers let processors access distant storage without saturating the local interconnect, shifting the bottleneck from proximity to bandwidth management across the multi-chip system.
Memory bottlenecks have centered on moving data between chips and main storage. Samsung's filing shows a path around that: letting processors feed results directly to each other during computation, rather than shuttling everything back through a central hub.
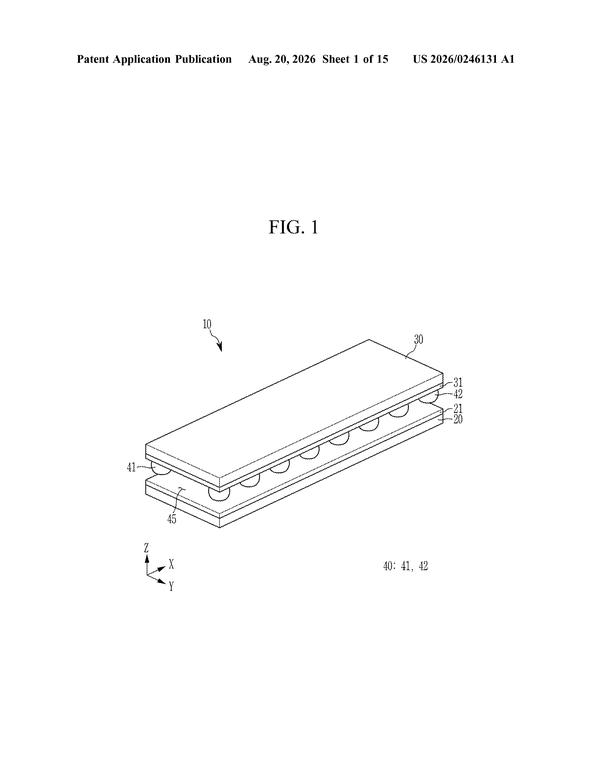
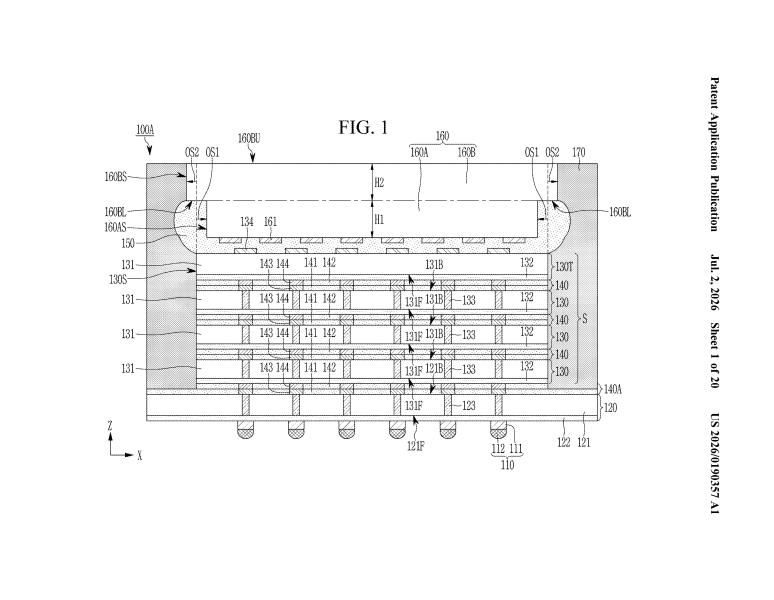
Dummy structures around memory contact points prevent mechanical stress from warping stacked chip layers during manufacturing and operation, directly addressing the reliability problem that arises when multiple HBM dies must maintain perfect alignment.
Coordination across multiple chips moves from centralized scheduling to peer-to-peer negotiation, eliminating the bottleneck that slows distributed training.
Direct memory access between thread groups cuts out the supervisor step, letting GPU workers exchange intermediate results without routing through shared caches or main memory. This directly reduces the serialization delays that plague multi-chip AI workloads.
Runtime feedback loops let the chip optimize its own voltage and frequency settings mid-operation, shifting the tuning problem from factory conditions to actual workloads, a way to squeeze efficiency gains without redesigning the silicon itself.
Memory isolation on a single die prevents cascading failures when one task crashes, keeping safety-critical functions intact during multi-workload operation.
A dummy die cap with reduced width lets resin cure evenly across stacked memory, preventing the warping that degrades electrical connections in high-bandwidth chips used for AI inference.
Prefetching model weights based on predicted token sequences cuts memory stalls by loading only active parameters ahead of execution, directly confronting the latency tax that makes inference slow on bandwidth-constrained devices.
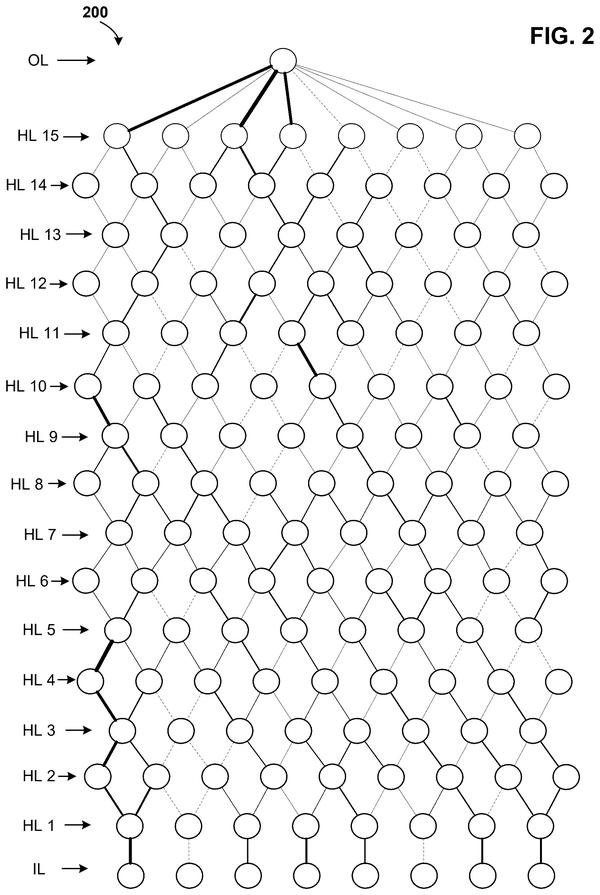
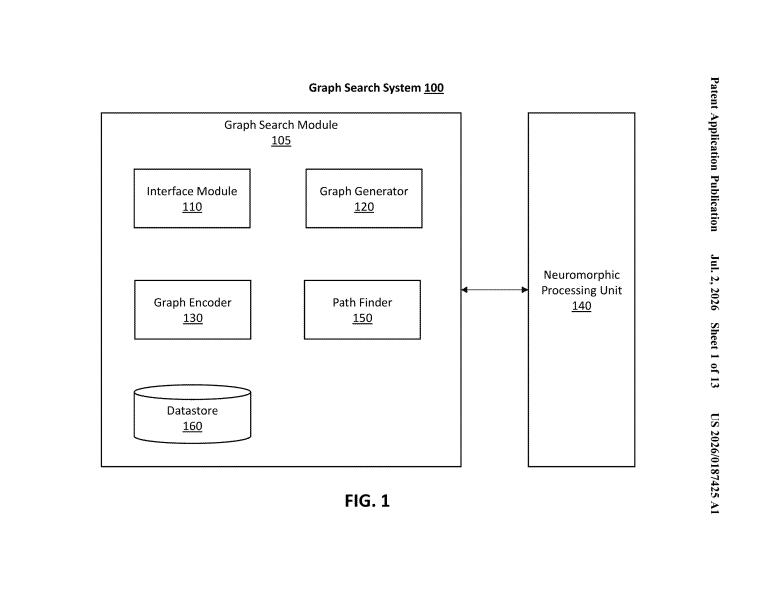
Within the coordination-across-chips subplot, neuromorphic routing reduces the computational load of pathfinding by distributing it across spiking neurons, sidestepping the serial bottleneck of conventional processors.
The chip wars need smart scheduling: where Intel bets is on learning which task migrations actually work, building feedback loops into the routing layer itself.
A chip that learns the rhythm of incoming device signals can sleep deeper between interrupts, cutting the idle power drain from processors stuck in shallow standby states waiting for unpredictable wake calls.
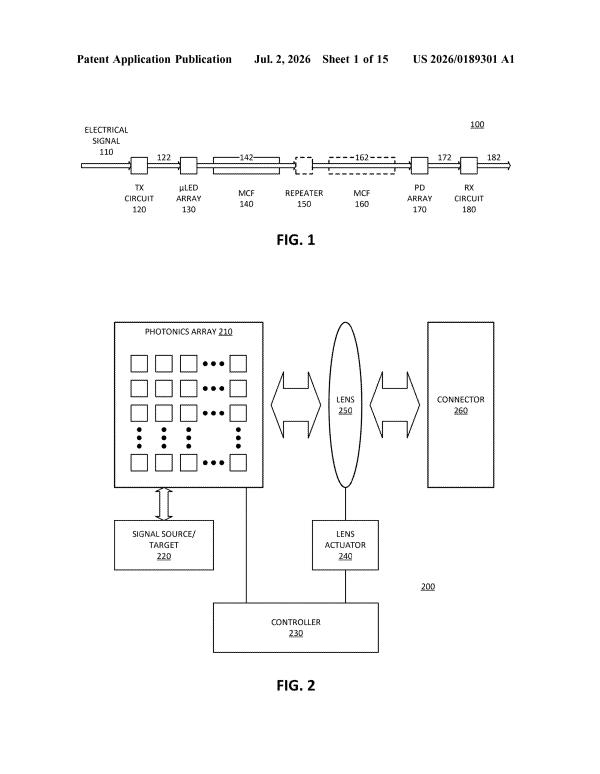
Parallel optical links replace single high-speed converters, distributing data across many simultaneous light paths to reduce the power and latency costs of inter-chip communication in multi-chip AI systems.
Reordering how training data gets packaged across processors prevents the fastest chips from stalling while slower ones catch up, directly improving utilization in multi-chip systems.
Memory protection joins the coordination problem: AMD encrypts models in transit between processor regions to stop software theft, adding a security layer to how data moves across chip architecture.
Memory bandwidth emerges as the core constraint across these filings. AMD's approach cuts redundant scale-factor reads, directly attacking the data-movement overhead that slows vector operations in neural networks.
Memory bottlenecks get worse when chips process zeros that sparse models contain. This filing proposes skipping them in hardware rather than compressing them away beforehand.
Predicting performance bottlenecks in real time shifts the burden from users guessing what to upgrade to hardware that identifies its own constraints, a foundation for dynamic resource allocation in AI accelerators.
Embedding an AI tuning loop directly in the chip itself sidesteps the need for external optimization software, letting the processor self-adjust memory bandwidth and power states in real time based on workload feedback.
Voltage scaling destabilizes memory during power transitions, so Microsoft's method synchronizes frequency and voltage changes to prevent data corruption when chips shift operating states.
Replicating in-flight data to fill unused compute slots lets the chip keep all its processing units fed rather than leaving gaps when workload geometry mismatches available hardware.
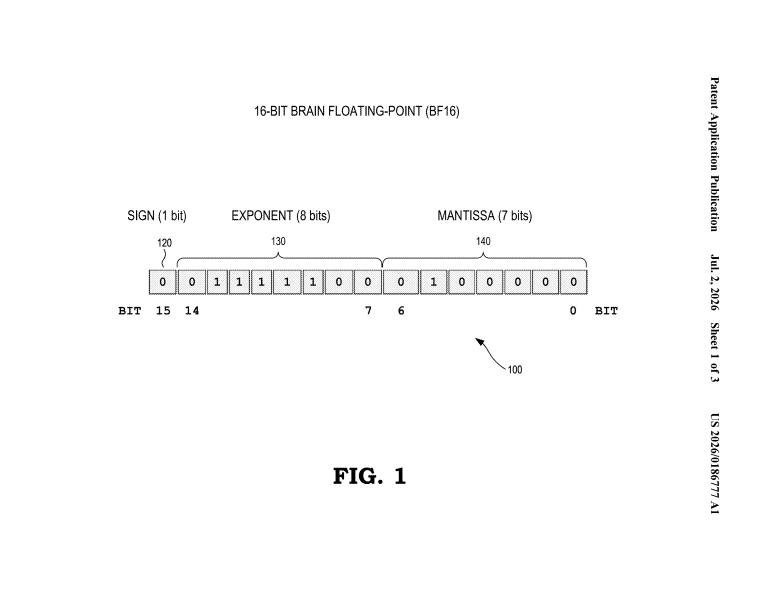
Memory bandwidth remains the core constraint in multi-chip AI systems. AMD's dedicated BF16 circuitry reduces the data volume moving between chips and between chip and memory, directly easing the bottleneck that slows down distributed training.
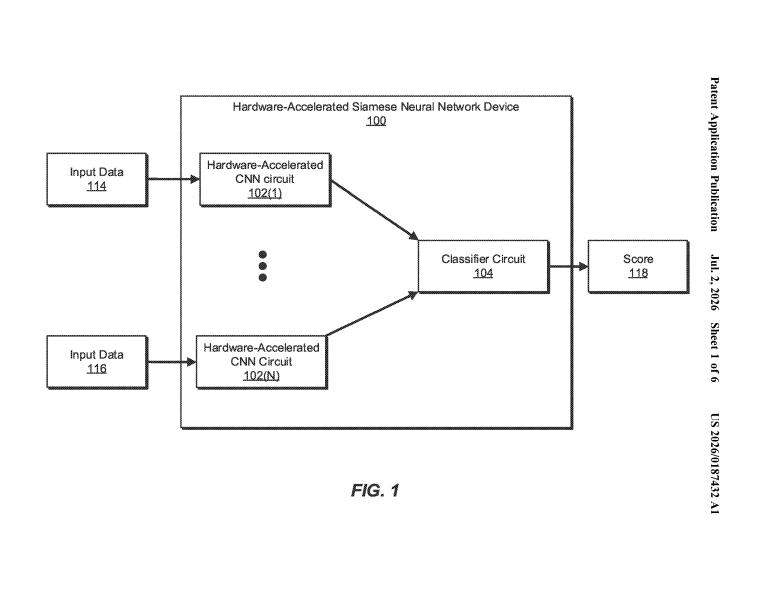
Dual synchronized neural networks let the chip compare data streams in real time rather than sequentially, cutting latency when matching pairs of inputs like images or audio samples.
Optical interconnects built into the package base cut the distance data travels between processor and memory, reducing latency and power loss compared to traditional electrical signaling across longer board traces.
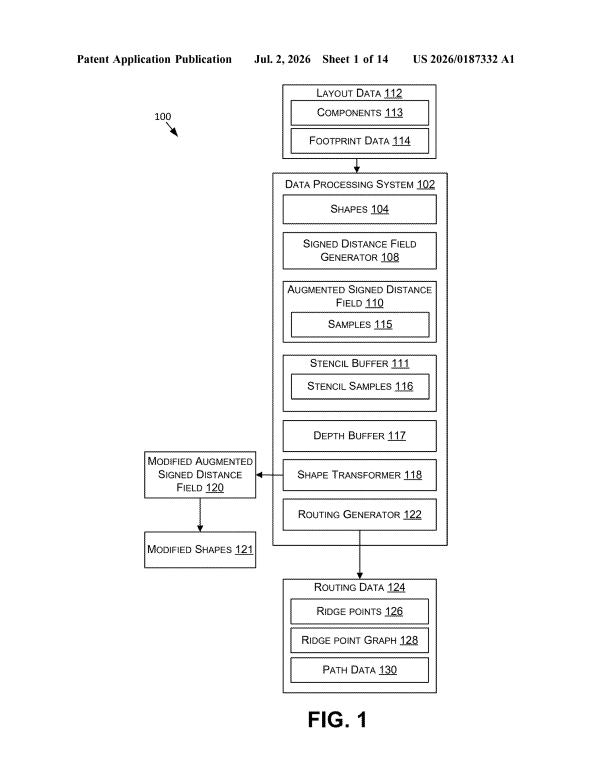
The coordination problem extends upstream: before chips can talk to each other, their internal wiring must be laid out efficiently, and Nvidia's automation system handles that geometric puzzle automatically rather than by hand.
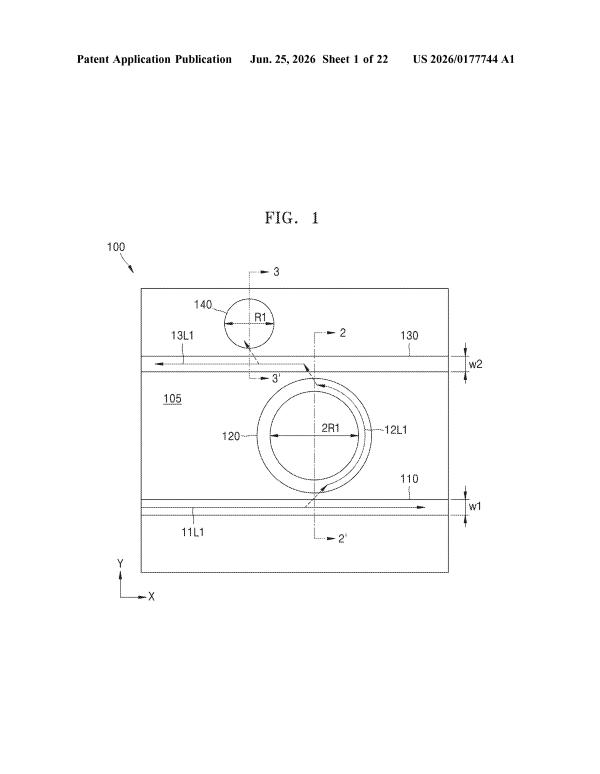
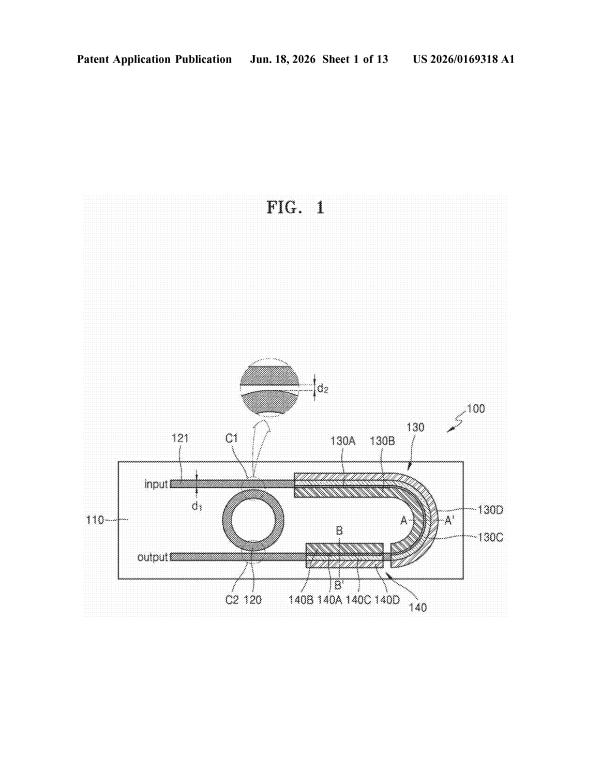
A two-stage resonator design shrinks the optical receiver while keeping sensitivity high, addressing the real bottleneck: fitting fast light-to-electrical conversion into the tight spaces between processor cores.
Chips need to match workload intensity, not run at peak for every request. AMD's patent routes different AI tasks to different silicon based on power state, cutting waste when the battery runs low.
The chip-to-chip communication layer gets a new lever: dual waveguides let Samsung route light signals with finer control, potentially squeezing more data density into optical interconnects without the heat penalty of electrical paths.
Faster AI inference means removing software queuing layers that cause hardware to sit idle even when resources are available. Intel's direct scheduling system would let workloads reach compute units without waiting in the operating system's queue.
Filtering sparse matrices before computation reaches the arithmetic units cuts wasted cycles on meaningless data, a hardware-level efficiency gain that bypasses software-level sparsity handling.
The chip wars have centered on memory bandwidth and raw compute, but Intel is betting the real bottleneck is coordination: keeping heterogeneous processors fed with work in the right sequence so nothing idles while waiting on another chip's results.
GPU memory latency kills throughput in real-time AI workloads. Intel's buffer sits between the media engine and compute core to serve data without the full round-trip to main memory, cutting both access time and power spent on fetches.
Network switches performing intermediate calculations during data movement replaces the centralized aggregation step, shifting from a hub-and-spoke bottleneck model to distributed computation across routing infrastructure.
Faster inference means cheaper chips. Amazon's approach skips zero values entirely during computation, freeing up memory bandwidth for the calculations that actually matter in running trained models.
Hardware-native random forest evaluation cuts the software overhead that slows inference on general processors, shifting the bottleneck from CPU cycles to silicon gates, a bet that decision trees warrant their own silicon rather than borrowing GPU cycles.
Routing overhead in heterogeneous chip clusters can kill efficiency gains. Amazon's filing moves the routing logic into hardware rather than leaving it to software schedulers.
Hierarchical data routing lets servers prioritize fast local exchanges over slower cross-server transfers, reducing idle time when thousands of machines coordinate during training.
Faster AI inference hinges on moving data around efficiently. Samsung's prefetch approach cuts the idle time chips spend waiting for memory by predicting data needs a few steps ahead, reducing a major bottleneck in real-world model execution.
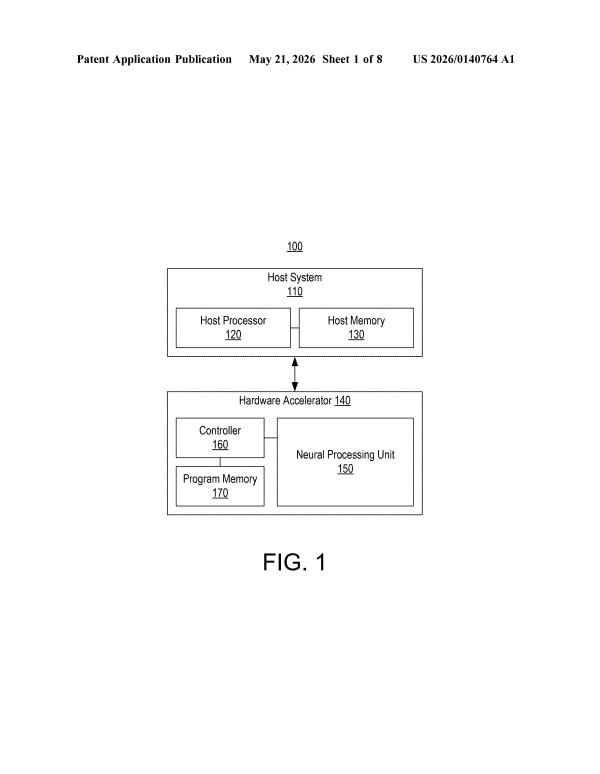
Splitting GPU compute into two tiers lets inference run on the efficient engine while the heavy engine stays dormant, directly lowering the battery drain that keeps mobile AI from becoming routine.
Memory placement emerges as the real constraint in chip design. Samsung bets that pre-organizing data layouts beats faster processors for overall speed.
The chip wars so far have focused on memory and scheduling. This patent suggests power efficiency becomes a hardware lever too, AMD is building granularity into which cores even turn on.
Power delivery bottlenecks force AI workloads across multiple GPUs to either crash or slow down. AMD's filing proposes load-balancing between cards so peak power demands stay within supply limits instead of stacking on top of each other.
Dynamic task migration between heterogeneous processors sidesteps the bottleneck of static workload placement, letting the system rebalance jobs in real time based on actual resource contention rather than upfront human prediction.
Chip scheduling under load requires knowing task signatures upfront. Samsung's filing bets that automatic classification of compute-heavy versus memory-heavy workloads can route each to the right core type without human tuning.
Embedding weighted sum calculations inside memory eliminates the data shuttling that drains power in standard AI chips, pushing the compute-memory bottleneck directly into the storage layer itself.
Faster AI inference means squeezing latency out of memory access patterns. Samsung's design lets the processor send higher-level requests instead of micromanaging every read and write, cutting the overhead that slows down real-time model execution.
The chip wars so far have focused on moving data faster and storing it cheaper. Samsung's filing shifts focus to cutting wasted computation during training itself, proposing selective weight updates that skip inactive neurons and batch their corrections later.
Chip idle time from memory misalignment cuts into throughput. Samsung's design co-opts the actual request patterns of AI workloads to reshape memory organization, reducing fetch latency.
The chip-scheduling problem gets concrete here: Intel is betting that dynamic reconfiguration beats static hardware. Reshaping the processor array between layers avoids the waste of fixed architectures designed for peak demands across all layer types.
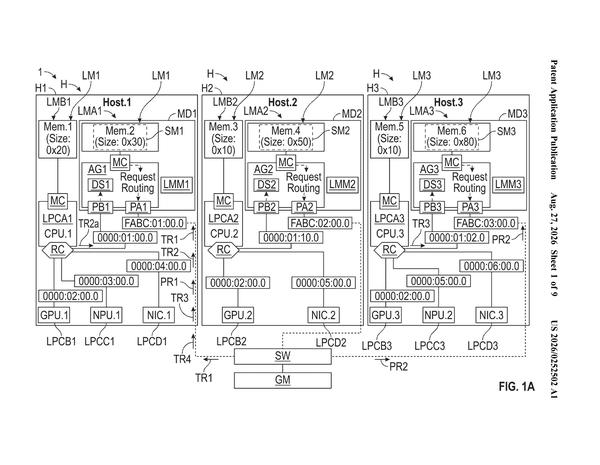
Spreading AI work across multiple chips only works if they can read shared data without copying it back and forth repeatedly. Samsung's patent puts a coordination layer between the chips and one common memory pool to cut that copying overhead.
Compressing activation tensors on-chip before they spill to memory reduces the conveyor-belt congestion that slows inference, betting that the math cost of shrinking data pays back faster than waiting for bandwidth-bound writes.
Keeping GPU workloads balanced across frames without waiting for driver updates cuts a real bottleneck in real-time graphics, where fixed scheduling policies often mismatch what's actually running on screen.
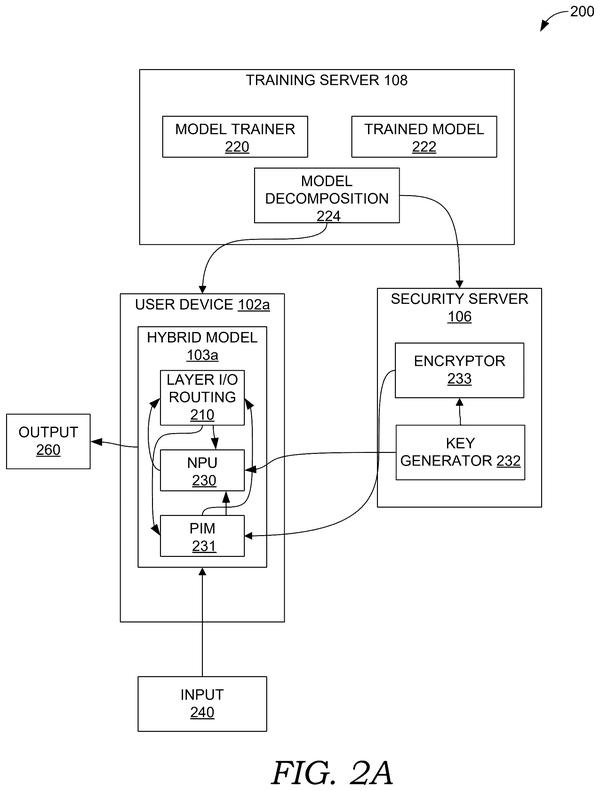
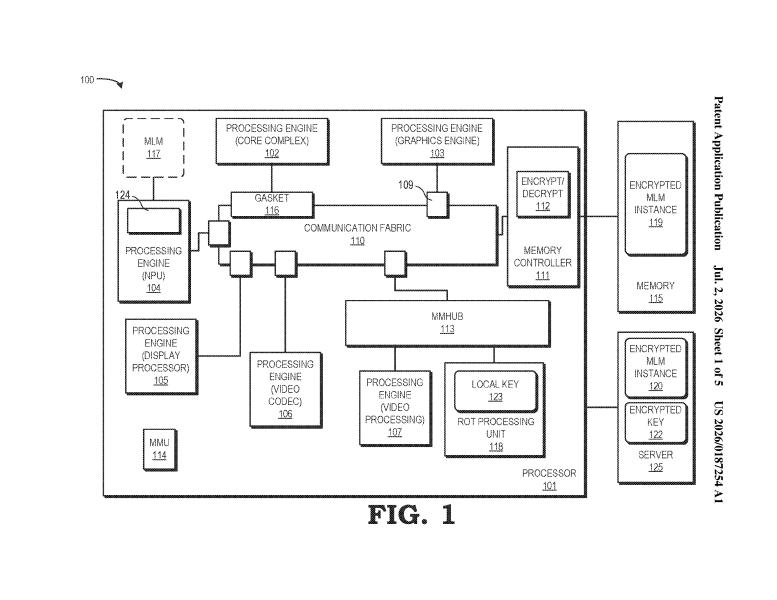
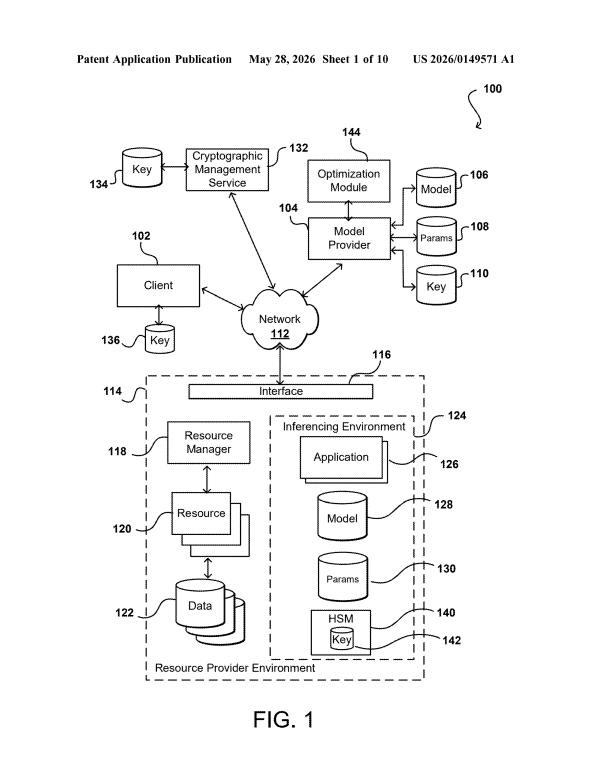
Customers could run vendor-optimized models at full speed while the weights stay encrypted, solving the tension between performance and IP protection in outsourced AI inference.
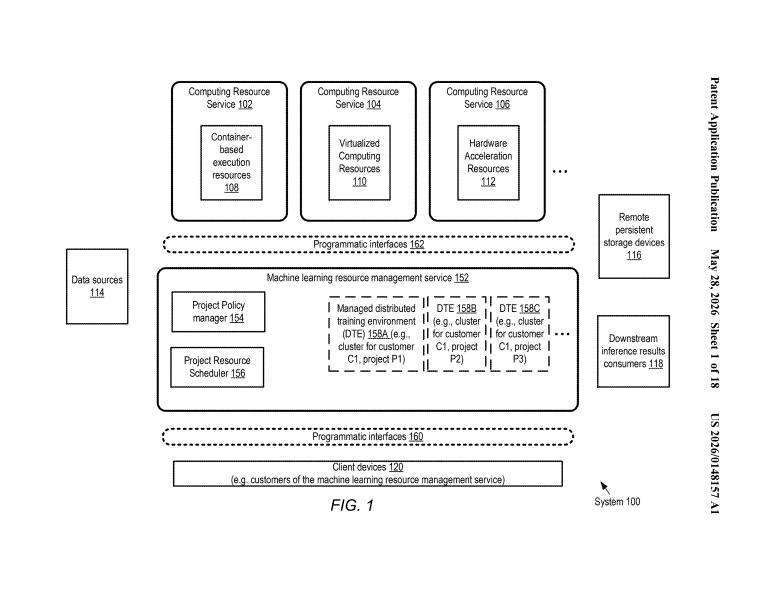
The chip wars so far have focused on memory and scheduling. Amazon's filing shifts to how GPUs get carved up when multiple ML projects run in parallel, automating the reallocation of compute that otherwise sits wasted.
Splitting neural workloads into smaller interruptible chunks lets the scheduler pause background inference mid-operation rather than wait for natural task boundaries, shrinking latency for time-critical requests on shared hardware.
Memory bottlenecks slow AI inference when weights travel from storage to compute. Intel's patent compresses weights in flight and decompresses them on arrival, shrinking the data pipe without extra latency.
Questions readers ask
What is the AI chip wars patent watchlist?
This watchlist groups patent filings from Intel, Amazon, Samsung, AMD, and Xilinx that all touch AI chip hardware, from memory management to task scheduling to data compression. It's a running collection, not a single product line, so it grows as each company files new patents on how AI computing should work under the hood.
Do these patents mean the chips are already being sold?
No. A patent filing describes an idea a company wants legal protection for, not a shipped product. Some of these filings, like Amazon's cryptographic key locking of model weights or Intel's reconfigurable chip array, describe directions the company is exploring rather than features you can buy today. Think of this watchlist as a signal of research priorities, not a product roadmap.
Which companies show up most in this watchlist?
Intel, Amazon, Samsung, AMD, and Xilinx all appear regularly, with Amazon and Samsung showing up across several different sub-problems, from memory sharing to task routing to data compression. That spread suggests both companies are patenting broadly across the AI hardware stack rather than focusing on one narrow piece of the chip.
Why do so many patents focus on memory instead of processing speed?
Several filings, from Intel's memory-waiting fix to Samsung's preloading and memory layout patents, target the same bottleneck: chips finishing their math faster than data can reach them. When a chip sits idle waiting for numbers to arrive, faster processors don't help, so companies are patenting ways to move and store data more efficiently instead.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.