
Google Patents an AI System That Researches Topics From Scratch
Google has filed a patent for a system that doesn't just answer your questions, it figures out what questions to ask in the first place, then goes and finds the source documents to back them up.
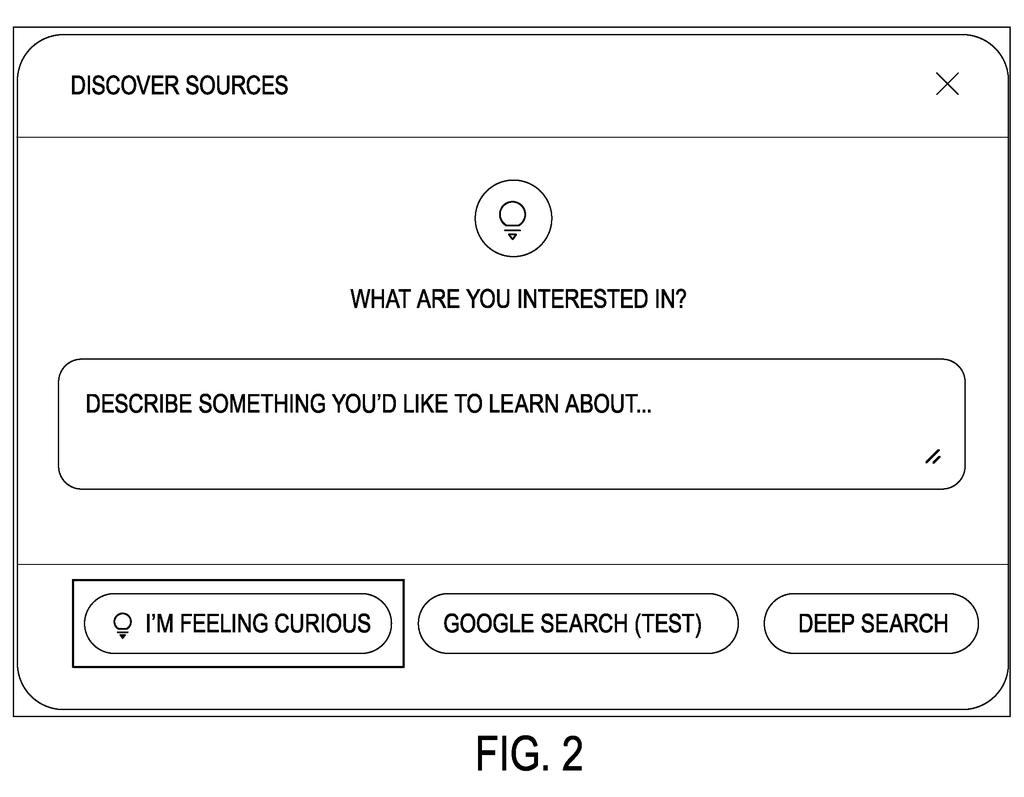
What Google's automated topic explorer actually does
Ever tried to research something you barely understand yet? You don't even know what to search for, let alone where to look. That blank-page moment is exactly what this patent is trying to fix.
Google's system starts with a request to explore a topic, then hands the job to an AI model that generates a clear statement of what that topic actually is. From there, a second step kicks in: the system creates a whole set of search queries and fires them at one or more information-retrieval systems, think databases, document stores, or search indexes, to pull back a collection of candidate source documents.
The end result is a proposed pile of sources that a person (or another AI system) can then dig into. You don't have to decide which keywords to try. The system does that work for you, collecting the raw material for a research effort before you've typed a single query yourself.
… processing, by the computing system, a model input with a machine-learned topic generation model to generate a topic statement as an output of the machine-learned topic generation model …
Translation: An artificial intelligence model creates an initial research topic based on user input.
How the AI picks a topic then goes hunting for sources
The patent describes a pipeline with two main stages: topic generation, then source retrieval.
In the first stage, a machine-learned topic generation model takes some kind of input (the patent calls it a "model input," which could be a seed phrase, a domain, or a prior context) and outputs a topic statement, a structured description of what the topic is about. This is the system deciding, with some AI-driven reasoning, what the exploration should focus on.
In the second stage, that topic statement drives the creation of multiple information retrieval queries (essentially a batch of search requests, not just one). Those queries run against one or more information retrieval systems, any backend that can return documents in response to a query, such as a search engine, a document database, or an enterprise knowledge base.
The returned documents are called candidate source documents. The system then collects at least a subset of them into a proposed set, which is the deliverable: a curated starting library for the topic.
The patent does not specify what happens to that proposed set afterward, leaving open whether a human reviews it, another AI summarizes it, or it feeds directly into a downstream workflow.
… generating, by the computing system, a plurality of information retrieval queries that query for source documents related to the topic statement …
Translation: The system writes multiple search queries to find documents matching the generated topic.
What this means for AI-powered research tools
For anyone who uses AI assistants for research, the gap between "ask a question" and "find reliable sources" has always been a weak point. This patent addresses that gap by making source-gathering an automated, multi-query process rather than a single lookup. The result, if it works well, is an AI that hands you a reading list rather than a paragraph.
On the product side, Google keeps filing on AI-assisted research and information retrieval, and this fits squarely into that pattern. A system like this could sit behind a tool like NotebookLM, a Workspace research feature, or a Search experience that goes deeper than a single results page. The practical value depends heavily on how good the topic generation model is, if it drifts from what you actually wanted, the whole source set goes sideways.
Google's 42nd filing we've tracked since May in our AI agents acting for you watch builds on earlier applications like reading your screen to run apps and knowing when to snap a photo.
Everything described here runs on software alone. There is no new chip to design, no sensor to manufacture, no physical product to ship. The pieces, an AI that picks a topic, a system that writes search queries, a document store that retrieves sources, already exist inside large technology infrastructure.
The shortest path from this filing to a working feature is mostly a wiring job: connect those existing pieces in the order the patent describes. That is a meaningful engineering effort, but it is a different kind of challenge than inventing something from scratch.
Where the hard work actually lives is in accuracy. If the AI slightly misreads what a user meant by their topic, every search query it writes afterward drifts in the wrong direction, and the final pile of sources feels useless. This document does not describe how that error gets caught, which is the real problem anyone building this feature would have to solve.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
15 drawing sheets from US 2026/0288882 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in