
Google Patents an AI That Reads Web Page Layouts to Find Prices and Dates
Google's patent teaches a model to read a web page the way you do: by noticing both the words and where they sit in the layout. The goal is to pull out a price, date or title from pages that look nothing alike.
What Google's web page reader actually does
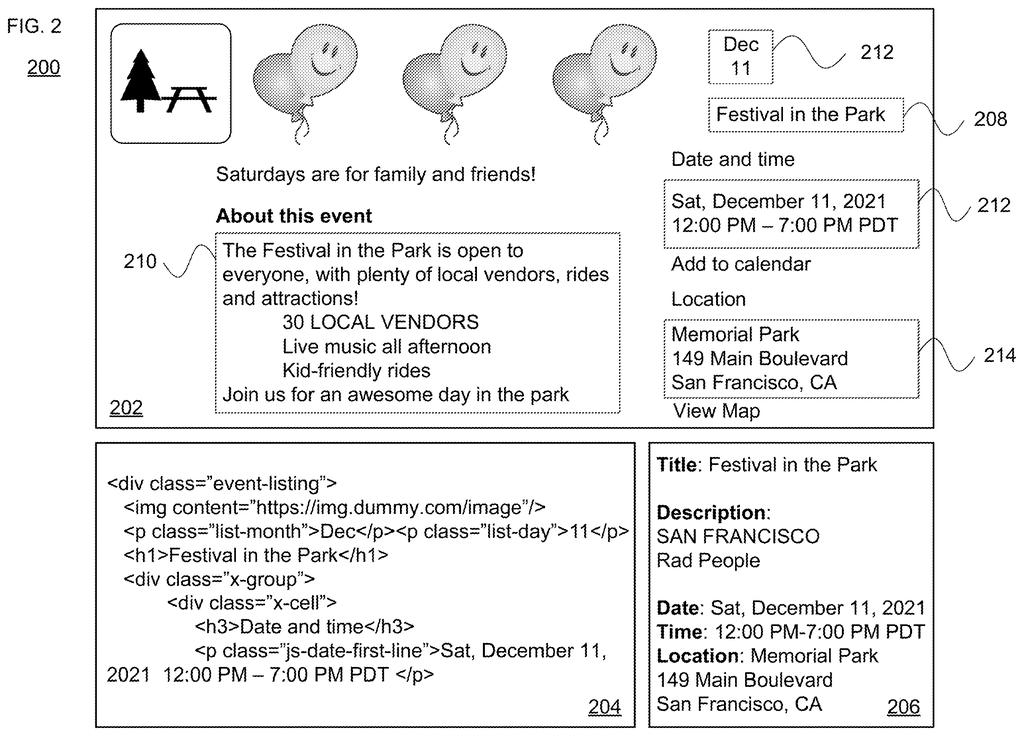
Ever tried to find the date and location of an event on a cluttered web page? You scan past ads, menus and repeated headings until something looks right. You do it by glancing at the layout: big text at the top is probably the title, small text near a calendar icon is probably the date.
Google's patent describes a computer model that does something similar. Instead of reading a page as one long string of words, it also reads the page's hidden structure, the outline that says which piece of text sits inside which box. Then it pulls out the fields you ask for, like title, price, brand or location.
The filing says older methods either needed a custom recipe for every website, which breaks when a site changes its design, or ignored the layout altogether. This one aims to work across many sites, including ones it has never seen.
… each text token within the text sequence is computationally restricted to attending only to surrounding text tokens residing within a localized sequence radius of itself within the text sequence …
Translation: Words on a page only pay attention to their nearby neighbors to understand context.
How the model uses a page's HTML family tree
The model takes in three kinds of input. Text tokens are the page's words, chopped into small units a model can process. Structural tokens stand in for the page's DOM tree (the nested outline of boxes that HTML, the web's page language, builds behind the scenes). The filing also feeds in field tokens that name what to look for, such as title, brand or price.
A transformer (the same family of AI model behind modern chatbots) then connects these pieces using attention, a way of deciding which pieces should influence which. The filing describes four patterns:
- Outline to outline: page elements pass information along the tree to their parents, children and siblings.
- Outline to text, and text to outline: each element is tied to its own words, and words absorb page-level context.
- Text to text: each word looks only at words within a set radius of itself (the example uses 64).
That last limit matters because the cost of letting every word look at every other word grows very fast as pages get longer. Claim 1 is built around this local-radius rule.
Finally, an output layer picks the start and end positions of the text for each field. The results are stored so they can be returned for a search query, analytics or another request. The filing also describes training on one type of page and then extracting from a layout the model has not seen.
… extracts a final text span for the each of the respective fields from the set of text tokens. The extracted final text span for each of the respective fields is stored in memory …
Translation: The system finds specific answers like prices or dates and saves them for later use.
What this means for search results and shopping data
If you have ever searched for a product or event and gotten a clean price, date or location back, something has to read those details off messy pages first. This filing describes one way to do that across many different sites without writing a custom rule set for each. Rule sets like that tend to break whenever a site changes its design.
The filing reports that its model, called WebFormer, scored best among the compared methods on every dataset it tested. On product pages, exact-match scores rose 7.8% over one rival and 5.8% over another. With zero training examples on a new page type, it found names and descriptions about 75% of the time but almost always missed locations, until it saw just one or two examples.
Google's 50th filing we've tracked in AI vision since May follows patents like dropping products into lifestyle scenes and fixing sleep misreads on fitness trackers.
Claim 1 is wider than the headline example suggests. It asks for the page's outline turned into tokens, the page's words turned into tokens, a transformer that reads both, and a rule that each word looks only at neighbors within a set distance. It then pulls out a piece of text for each target field. It says nothing about shopping pages, event pages or even HTML in particular; the wording covers any document with a tree-shaped structure.
Several of the most distinctive features sit in the dependent claims: the graph-style links between page elements (claim 2), the field labels fed into the model (claim 3) and the test on layouts it never saw in training (claim 7). If granted as written, claim 1 would reach any extraction system that combines structural tokens with that local-window rule, with or without those extras.
The local-window rule is the one narrowing detail, and it is a way to keep long pages affordable to process. A claim that leans on it is broad on document types and narrow on one mechanism, so how much it covers depends heavily on how a phrase like "localized sequence radius" gets read.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
19 drawing sheets from US 2026/0350103 A1 · click any drawing to enlarge


Show the other 11 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in