
Adobe Files Patent for Training AI to Spot Actions in Compressed Video
Hours of store camera footage are expensive to send anywhere. Adobe's filing describes teaching an AI to figure out what people are doing from a shrunken copy of the video, so only a short label needs to travel.
What Adobe's compressed-video patent actually does
Ever tried to email a long video and watched the progress bar barely move? Now multiply that by a store chain with cameras in hundreds of locations, all recording all day. Sending every minute of that footage to headquarters would clog the internet connection and cost a lot.
Adobe's filing describes a shortcut. A camera, or a small device next to it, first shrinks the video into a compact code. Then an AI model reads that shrunken version and works out what is happening, such as people walking. Only that short label has to travel to the central computer.
The claims cover the training side: how you teach the AI to do this. It practices on clips whose actions are already labeled, and it keeps adjusting itself until its guesses match the labels.
compressing a plurality of frames of a training video using an encoder network to obtain compressed frame features; classifying the compressed frame features using a classification network to obtain action classification information for an action in the training video that spans the plurality of frames of the training video; …
Translation: The system shrinks video frames and then analyzes them to figure out what activity is happening across those frames.
How the encoder shrinks frames before sorting
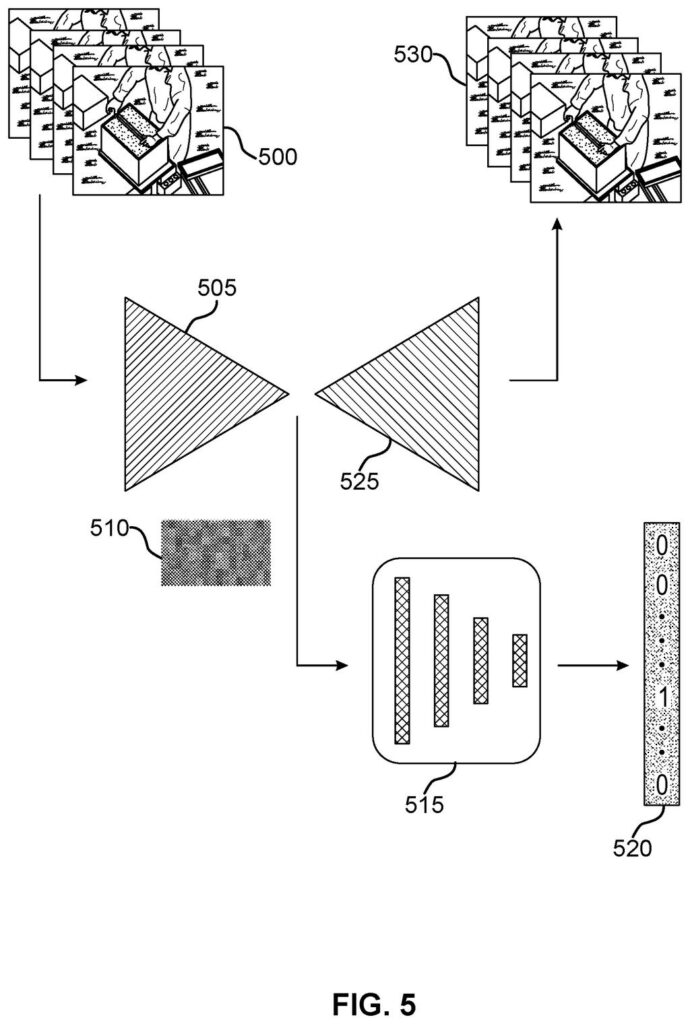
The claims describe a training recipe with three moves. First, an encoder network (a neural network that squeezes data into a smaller form) compresses the frames of a training video into compressed frame features. Second, a classification network reads those features and guesses which action the clip shows. Third, the system compares that guess to the known correct label and adjusts the classification network until it improves.
The dependent claims add variations:
- The encoder can be trained first. A decoder rebuilds the video from the compressed version, and the copy is compared to the original. The filing says the decoder is used only during training.
- Some frames act as key frames, compressed one at a time. The frames between them are filled in by interpolation (estimating from the neighbors). One example uses every 12th frame as a key frame.
- The classifier can use 3D convolution (filters that scan across both space and time, so it picks up motion), a 2D look at one frame for color and objects, or a recurrent network (one that remembers earlier frames).
The compressed code can be a string of binary digits, and one version describes a compression ratio of at least 2. In the wider description, a camera-equipped edge device (a gadget at the place where video is recorded) runs both networks and sends only the label to a central server.
… updating parameters of the classification network by comparing the action classification information to ground truth action classification information.
Translation: The AI learns to improve its accuracy by checking its guesses against known correct answers.
Why store cameras could keep footage local
If you run a chain of stores, the appeal is plain: you could learn how shoppers move through the aisles without hauling every hour of footage to a data center. The filing says analysts could then ask questions across all locations, such as which paths people repeat and which spots they visit most, and use the answers to rearrange layouts and item placement.
For everyone else, it is a reminder that a lot of AI work comes down to moving less data. The filing says analyzing compressed video lets the AI model be smaller and use less computing power and bandwidth. This is a divisional filing tied to an earlier application, and its claims cover training, so it describes a method rather than a product you can buy.
That makes this Adobe's ninth filing in the AI training and infrastructure work we've tracked since May, following filings like AI models grading each other and routing tricky data to humans.
Video is the heaviest data most businesses collect, and a store chain with cameras running all day piles it up fast. The filing itself says that sending all of it to one place can be too expensive or even impossible with the available internet capacity. That makes the problem real and costly.
The approach fits the size of it. If a camera reports only a short label for what it saw, the data leaving the store shrinks from a flood to a trickle. Training the AI on shrunken video also means the model can be smaller and cheaper to run on modest equipment at each location.
The catch is that the claims cover only the training recipe, and the filing names a compression ratio of just "at least 2," a modest squeeze. Whether this saves real money depends on how accurate the labels turn out to be, and the document gives no accuracy numbers.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
16 drawing sheets from US 2026/0343003 A1 · click any drawing to enlarge


Show the other 8 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in