
Google Patents a Way to Ask Questions About a Video While It's Playing
Google has filed a patent for a system that turns any video into a searchable, AI-queryable document, so you can ask a plain-English question mid-playback and get a direct answer pulled from the video itself.
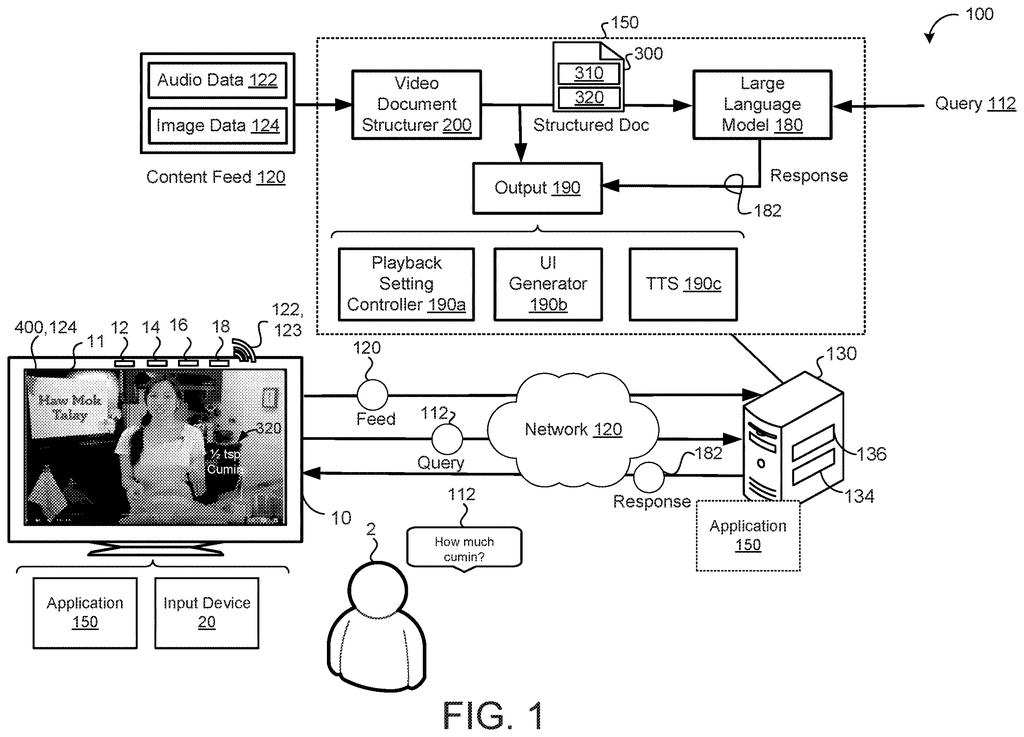
What Google's video Q&A system actually does for you
You're watching a long tutorial video and the speaker mentions a setting you want to find again, but you've already scrubbed past it and can't remember where it was. Normally, your only option is to rewatch chunks until you spot it.
Google's patent describes a system that listens to a video as it plays, transcribes everything said, and links each word back to the exact moment in the video when it was spoken. It also reads any on-screen text, like slide titles or captions added by the creator, and folds that in too. All of this gets organized into a structured document that an AI language model can read.
When you type or speak a question, the AI reads both your question and that document together to give you a direct answer, not a list of search results. The goal is to make video content as easy to query as a webpage.
receiving a content feed comprising audio data and image data, the audio data corresponding to speech utterances; processing the content feed to generate a semantically-rich, structured document …
Translation: The system takes in a video and turns it into a detailed text file.
How Google builds a searchable document from audio and video
The patent describes a pipeline with a few distinct stages.
First, the system ingests a content feed containing both audio and video frames. It runs automatic speech recognition on the audio to produce a word-level transcription, where each word is time-stamped to the audio segment in which it appeared. It also runs optical character recognition (OCR) on video frames to capture text that the creator has placed on screen, like slide text, lower-third labels, or on-screen annotations.
Second, the system groups the transcribed words and the recognized on-screen text into sections based on time. Think of it like chaptering a book: content that appears around the same moment in the video gets consolidated into one section. This time-aligned structure is what the patent calls a semantically-rich, structured document.
Third, when a user submits a query during playback, a large language model (LLM) receives both the natural-language question and the structured document as context. The LLM then generates a response that directly answers the question using the information in the video, without requiring the user to scrub through the timeline.
The time-alignment detail is important: because each word is anchored to a specific audio segment, the system could, in theory, surface not just an answer but also the exact timestamp where that answer lives in the video.
… processing, by a large language model, the query and the structured document to generate a response to the query.
Translation: An AI reads the text file to answer questions about the video.
What this means for how you watch and search video
Search inside video has always been a weak spot for platforms like YouTube. You can search for a video, but searching within a video is mostly limited to auto-generated captions that you scroll through manually. A system that lets you ask a plain question and get a direct answer could change how you interact with long-form content, whether that's a two-hour lecture, a product review, or a recorded meeting.
Google's steady investment in LLM-integrated search makes this a natural extension of the direction it's already moving. For creators, a system like this could make their videos far more discoverable on a per-detail level, since individual facts buried inside a video could become directly answerable from a query.
This is the 81st Google filing in Language AI we've tracked since May, a topic that includes work like one summarizing skipped video and one separating similar search questions.
The building blocks this patent describes already exist and work: turning speech into text, reading text from video frames, and using AI to answer questions about long documents. The engineering challenge is connecting those pieces into one pipeline that runs reliably at the moment someone asks a question during playback.
The real friction is cost and scale, not invention. Running this process across a library the size of YouTube means indexing an almost incomprehensible volume of video, and the patent says nothing about how that gets paid for or prioritized.
That gap aside, the path from this filing to a working feature looks like an infrastructure project more than a research one, which puts it closer to shipping than most patents ever get.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
6 drawing sheets from US 2026/0267916 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →