
Google Patents a Way to Train Image AI Without Matched Photo-Text Pairs
Training an AI to generate images from text usually demands enormous matched datasets, where every photo has a caption written for it. Google's new patent describes a way to skip that bottleneck entirely, by teaching two AI models to check each other's homework.
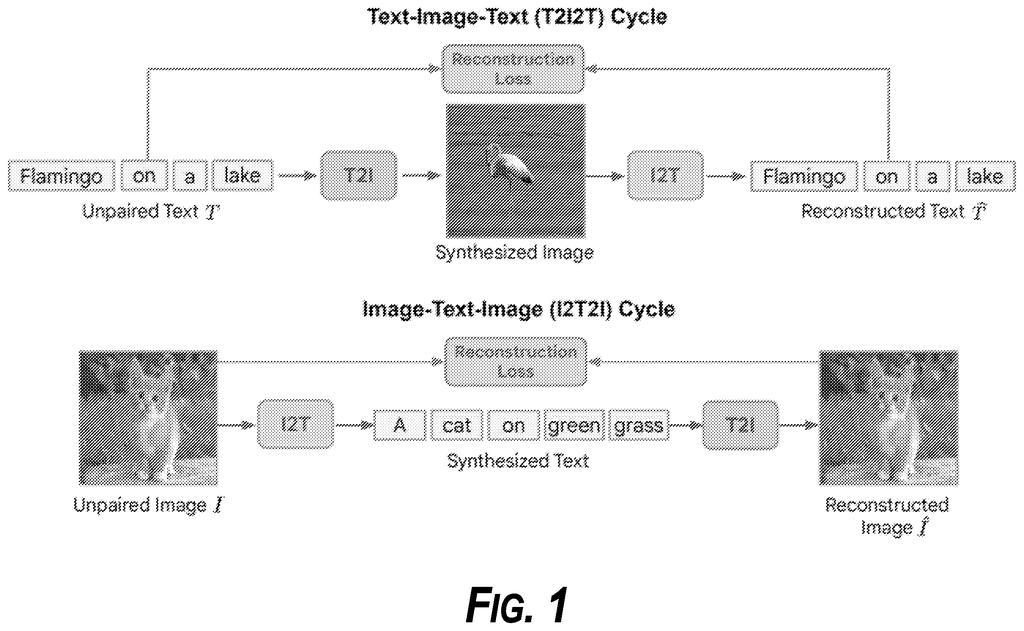
What Google's cycle-training trick actually does for image AI
Ever tried to describe a photo to someone who can't see it, and found that no matter what you said, they drew something slightly off? That's roughly the problem that haunts today's text-to-image AI: the model sees a description and generates a picture, but there's no guarantee the picture actually captures what you meant.
Google's approach here is a feedback loop. Take a text prompt, generate an image from it, then feed that image into a second AI that writes a description of what it sees. If the second AI's description matches your original prompt, the first model did its job. If not, both models get nudged in the right direction.
The clever part is that this loop works with unpaired data: plain text that was never matched to a specific photo. That's a much larger pool of raw material than labeled datasets, which means the models can keep learning from far more text than was previously possible.
… processing, by the computing system, the unpaired text input with the text-to-image model to generate a synthetic image; processing, by the computing system, the synthetic image with the image-to-text model to generate predicted text; …
Translation: The system turns text into a fake image, then translates that image back into text to check the results.
How the text-image-text loop catches and corrects model errors
The patent describes a training method that runs two models in a loop. The first is a text-to-image model (it reads a description and produces a picture). The second is an image-to-text model (it reads a picture and produces a description). Together they form a cycle.
Here's the sequence for each training step:
- The system picks an unpaired text input, meaning any piece of text with no associated photo.
- The text-to-image model generates a synthetic image from that text.
- The image-to-text model then reads that synthetic image and produces a new description.
- A loss function (a mathematical score that measures how wrong the output is) compares the new description against the original text. The bigger the mismatch, the higher the penalty.
- Both models adjust their internal settings to reduce that penalty on the next pass.
This is known as cycle consistency, a technique borrowed from image translation research, where the idea is that if you translate something from English to French and then back to English, you should land close to where you started. Here, the "translation" runs from text to image and back to text.
The practical advantage is data efficiency. Matched text-image pairs are expensive to compile. Plain text is everywhere, so a training method that uses it without pairing requirements can scale much further.
… evaluating, by the computing system, a loss function that compares the predicted text to the unpaired text input to generate a loss value; and modifying, by the computing system, one or more parameter values of one or both of the text-to-image model and the image-to-text model based on the loss function.
Translation: The AI grades its own work by comparing the new text to the original input and adjusts its settings to improve.
What this means for AI that turns your words into pictures
For you as someone who uses AI image generators, better training data means the tool produces images that more faithfully match what you typed. Fewer regenerations, less prompt engineering, and results that don't require you to guess what phrasing the model responds to.
Google keeps filing on AI training efficiency, and this patent fits that pattern. The deeper shift here is that the bottleneck for improving these models may no longer be the size of expensive labeled datasets. If unpaired text can drive meaningful improvements, the ceiling on how good image generation gets moves significantly higher, and that affects every product built on top of these models, from search to creative tools.
Google's 34th filing in the AI image and video work we've tracked since May follows earlier applications like a text-driven photo editor and on-device image generation.
If you've ever typed a detailed, specific description into an image generator and gotten back something that looked plausible but missed half the point, this patent is about fixing that. Google is working on a way to train these models using raw written descriptions alone, without needing someone to manually match every sentence to a photograph first.
That matters because the model can now learn from far more varied and precise language, which means it has a better chance of actually rendering the unusual details you typed rather than smoothing them into something generic.
Whether this shows up in a product you can use soon is an open question, but the failure it targets is one most people have already hit.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Google patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
13 drawing sheets from US 2026/0278464 A1 · click any drawing to enlarge


Show the other 5 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in