
A New OpenAI Patent Describes a Chip That Keeps AI Model Data in Place
OpenAI has filed a patent for a chip design built around one trick: leave the AI model's numbers parked inside the chip and stream the data past them. It is the clearest look yet at how the company thinks about hardware for running chatbots.
What OpenAI's matrix-math chip actually does
Ever tried to cook a big dinner while running back to the garage freezer for every ingredient? That is roughly what many AI chips do. They keep fetching the same model data (called weights) from memory over and over, which burns time and electricity.
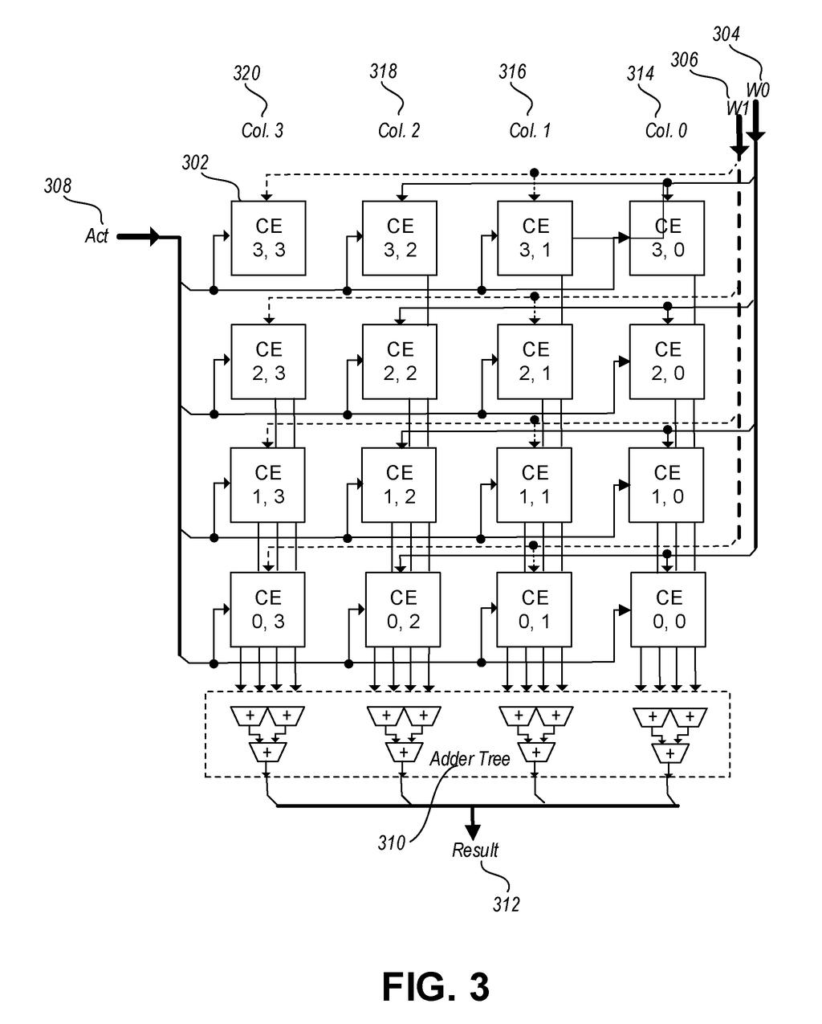
OpenAI's filing describes a chip that does the opposite. The weights stay put inside small calculating units, and your question, turned into numbers, flows past them. Each unit also holds two sets of weights, so it can load the next set while still working on the current one, with no pause.
The chip also shrinks the incoming numbers to a rougher, smaller format before the math starts. Smaller numbers mean less to move around and more math per second. The filing says this targets data centers running chatbot-style AI for answering questions.
… a quantization block coupled to the compute engine array, the quantization block being configured to receive activation values and provide quantized activation values to the compute engine array …
Translation: A special hardware block shrinks the incoming data numbers to make math faster and more efficient.
How the chip stores weights and shrinks numbers
The filing describes a system-on-chip (a whole computer system on one piece of silicon) split into domains, each holding 16 compute tiles and a stack of high-bandwidth memory (very fast memory sitting right next to the chip). Each tile has a matrix-multiply engine, which does the grid-style multiplication at the heart of AI models. The description mentions 4 to 8 domains and 2 to 4 peta-operations per second (a peta is a thousand trillion).
Inside each engine is a grid of compute units. Each one stores its own weights and multiplies them against incoming data, which is called a weight-stationary design. Every unit has two weight banks (small storage slots), so one bank can be refilled while the other is in use. Two separate weight channels feed alternating columns of the grid, so loading happens in parallel.
- Quantization block: converts incoming numbers from a 16-bit format (BF16) to smaller block formats (MXFP8, MXFP6 or MXFP4). Groups of 32 numbers share one scale value, found by comparing their exponents (the part of a number that sets its size).
- Adder trees: sum the results down each column.
- Accumulator: holds running partial totals, such as a 128×128 grid, so big problems can be solved in pieces.
Claim 1 covers the whole system. Claims 11 and 17 cover a method and just the dual-bank compute unit by itself.
… employ a weight-stationary dataflow in which weight values remain stored in compute engines while activation values are streamed through the system …
Translation: The chip keeps the core AI model data sitting still in one place while running the active data right past it.
Why OpenAI's chip design matters for AI costs
The practical point is cost. Running chatbots for millions of people takes huge amounts of electricity and memory traffic, and a chip that moves less data can answer the same question for less money. That is what this design is aiming at: less fetching, less waiting, and smaller numbers to carry around.
It also shows how much work goes into the hardware side of AI. OpenAI's interest in building its own AI chips matters because the company depends on others for the processors that run its models. A design like this suggests it wants control over the details, from number formats to memory layout. The filing does not name any product, so treat it as a design sketch.
OpenAI's seventh filing we've tracked in the AI chip wars since July builds on one that skips re-reading instructions and one on searching memory in place.
Claim 1 is broad. It asks for a computing system with processors, a memory setup, several compute tiles, and in each tile a grid of compute units, a block that converts incoming numbers, and an accumulator that stores results. It does not require the two weight banks, the alternating-column loading or the exact 32-number grouping. Those details sit in later claims.
That breadth means the first claim reads like a description of how many modern AI chips are already organized. If granted as written, it would cover any chip with that basic lineup, which is a lot of ground, and a patent examiner will likely push back on it.
The narrower claims are more interesting. Claim 17 covers a single compute unit with two weight banks that load and work at the same time. It is a clean, easy-to-picture idea, and it is where this filing has the best chance of holding something distinct.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time OpenAI patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
6 drawing sheets from US 2026/0329966 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in