Salesforce
Salesforce · Security · Filed Apr 13, 2026 · USPTO published Aug 13, 2026 · Aug 13 release
Salesforce Patents a System That Flags Harmful Data Requests Before They Execute
Most database attacks succeed because a malicious query looks like any other SQL command until it's too late. Salesforce has filed a patent for a system that builds a statistical profile of normal queries and automatically blocks anything that falls too far outside the pattern.
- Publication number
- US 2026/0236470 A1(US20260236470A1)
- Applicant
- Salesforce, Inc.
- Filed · Published
- Apr 13, 2026 · Aug 13, 2026
- Inventors
- Anup Ghatage, Colm McHugh
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 707/719
- Parent application
- Continuation of 19/018,006 (filed Jan 13, 2025)(19018006)
How Salesforce's query-screening system actually works
Every large company's database fields thousands of queries per day, and most security tools only check whether a query is technically valid, not whether it's behaving strangely. A query asking for an unusual number of columns, or one that would cost the server far more computing power than normal, can slip right through.
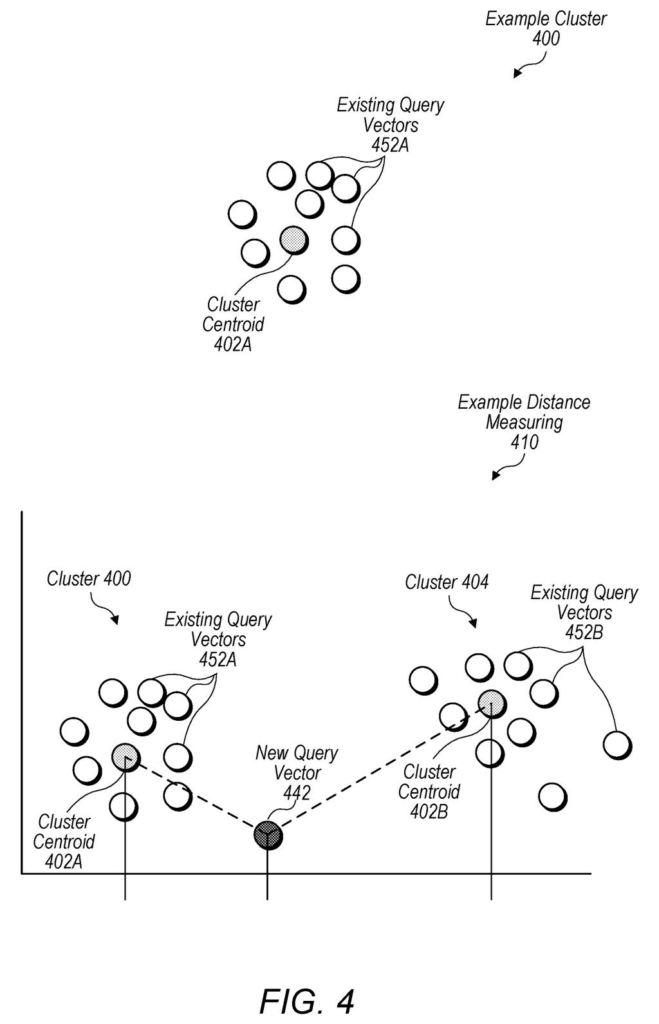
Salesforce's patent describes a way to change that. Before any query actually runs, the system converts it into a kind of fingerprint made up of measurable traits: how many columns it touches, how expensive it would be to execute, and other factors pulled from the database's own query planner. That fingerprint is then compared against a map of all the fingerprints the system has seen before, grouped into clusters of similar queries.
If your new query lands too far from every existing cluster, it gets flagged or blocked automatically. The further it sits from anything "normal," the more suspicious it looks. The system uses tiered distance thresholds, so a slightly unusual query might just get logged, while a wildly outlying one gets stopped outright.
… retrieving, by the server system prior to execution of the new query, an estimated execution plan from a query optimizer, the estimated execution plan specifying a plurality of estimated metrics; generating, by the server system, a multi-dimensional query vector for the new query based on a set of query aspects …
Translation: The system analyzes a query's predicted performance and technical characteristics before it actually runs.
How the clustering engine scores and flags each query
The patent describes a multi-step pipeline that runs between the moment a query arrives and the moment the database engine actually executes it.
Step one: query vectorization. When a new query comes in, the server intercepts it and asks the database's own query optimizer (the internal component that estimates how long a query will take before running it) for an "estimated execution plan." That plan includes metrics like the number of rows the query would scan, the computational cost, and the columns involved. These metrics are combined into a multi-dimensional query vector, essentially a point in a mathematical space where each dimension represents one measurable trait of the query.
Step two: cluster comparison. The system maintains a library of clusters, where each cluster is a group of previously seen query vectors that resemble one another. For each new query vector, the system calculates the distance to the nearest cluster's center point (centroid). A short distance means the query looks like queries the system has handled many times before. A long distance means it's an outlier.
Step three: tiered classification. The distance is compared against a multi-level threshold, not a simple pass/fail. Queries that fall within a tight range are approved immediately. Queries at medium distance may trigger a review or a log entry. Queries far outside all known clusters are blocked before execution.
The whole process runs before execution, so the database never even tries to carry out a potentially harmful command.
Based on the comparing, specifically a distance between the query vector and the plurality of clusters of previously generated query vectors, the system classifies the query. Based on a classification of the query determined during the classifying, the system manages the query.
Translation: The software compares new requests against patterns of past activity to decide how to handle them.
What this means for cloud database security
For companies running Salesforce's cloud database products, this kind of pre-execution screening could catch a category of attacks that traditional access controls miss entirely. A user who has legitimate credentials but is running a query that would scrape the entire customer table, or one designed to overwhelm the server, would still trip the anomaly detector because the shape of the query is wrong, even if the user's identity checks out.
The approach is mostly software-based, which means it could be deployed as a feature update rather than requiring new infrastructure, and the core mechanism (clustering against a learned baseline) is well-established in fraud detection and network security. The newest Big Tech patents in database security increasingly bet on behavioral baselines rather than rule lists, and this Salesforce filing fits squarely in that direction.
Source: US 2026/0236470 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Salesforce patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 8 sheets
8 drawing sheets from US 2026/0236470 A1 · click any drawing to enlarge


More from Salesforce
All 108 Salesforce patents →
More in Security
All 341 Security patents →
IBM
IBM Patents an AI Security Agent That Asks Questions When It's Uncertain
Microsoft
New Patent Judges Apps by the Company They Keep to Catch Malware
Microsoft
Microsoft Patent Reveals Local AI Secretly Sends Your Prompts to Cloud for Screening
Nvidia