
Microsoft Patents a Way for AI Models to Share Memory Instead of Starting from Scratch
Every time two AI models handle the same conversation, each one rebuilds its memory of that conversation from zero. Microsoft's new patent describes a way to stop that waste by letting models share the work they've already done.
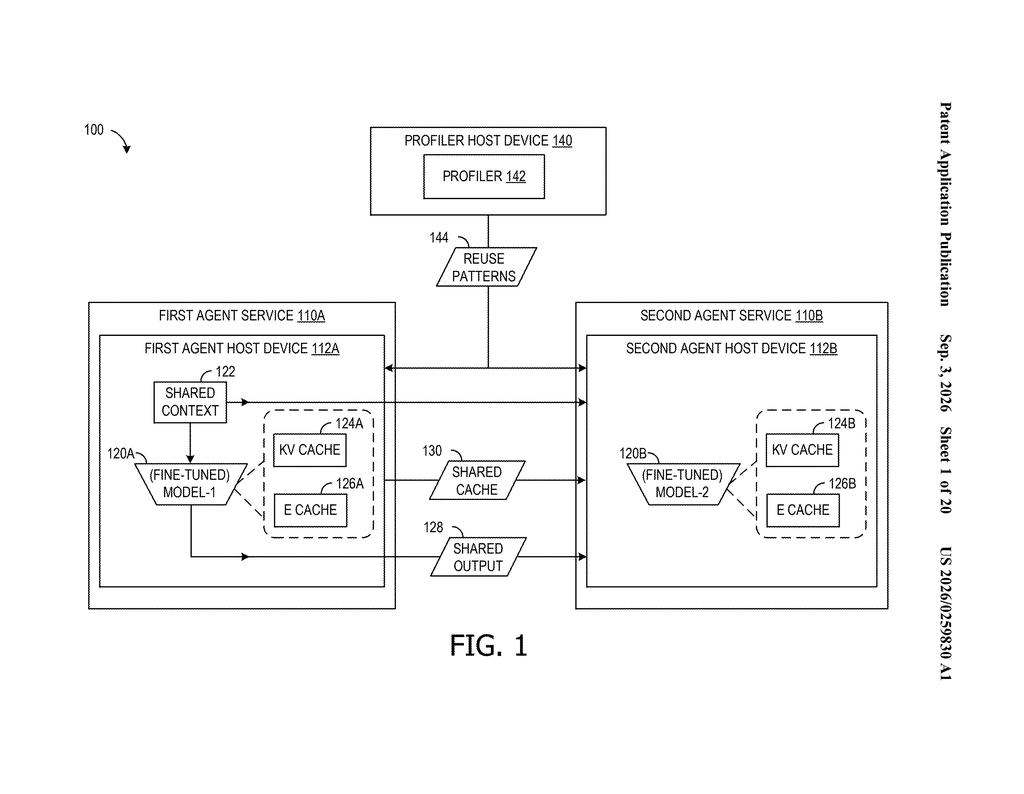
How Microsoft's AI cache-sharing cuts repeat work
When you chat with an AI assistant, the model builds a kind of running notes file in memory, tracking everything said so it can respond in context. Today, if a second AI model needs to handle the same conversation, it has to rebuild those notes entirely on its own, even if a very similar model already did that work.
Microsoft wants to change that. The patent describes a system where two AI models can share parts of that memory file. The first model's notes are handed to the second model, which reuses the sections that transfer well and only rebuilds the parts that don't. A scoring system checks whether the second model's answers are still accurate after the handoff, so quality doesn't slip.
The result is that running multiple AI models on the same task uses far less computing power. That matters whether you're a business running many AI agents at once or a platform trying to keep response times fast without spinning up extra hardware.
… populate a second KV cache of the second model with one or more layers of the first KV cache layers; recompute one or more other layers of the second KV cache; generate an output performance score for the second model based on comparison between (a) an output generated by the second model while using the second KV cache and (b) a baseline metric …
Translation: The system copies some memory layers between AI models, recalculates others, and checks how well the second model performs.
Inside Microsoft's KV cache reuse and scoring system
AI language models store their working context in a structure called a key-value (KV) cache, which is essentially a compressed record of everything the model has processed so far in a conversation. Building that cache takes significant compute. When a second, different model needs to handle the same conversation, it normally has to build its own cache from scratch.
Microsoft's system works by treating that cache as something that can be partially donated. The process goes like this:
- The first model generates its KV cache as normal.
- Layers of that cache (think of them as sections of the notes file) are copied into the second model's cache.
- The second model recomputes only the layers where the two models diverge significantly.
- A scoring step compares the second model's outputs against a baseline to measure how much accuracy was lost or preserved.
- The system records a reuse pattern: a map of which layers can safely be borrowed, sent to a host device so it can apply the same shortcut at runtime.
The key insight is that many AI models share architectural similarities, especially models from the same family. Layers in the lower part of the network often capture general language structure, while upper layers are more model-specific. The system figures out empirically which layers transfer cleanly and which don't, rather than assuming.
… transmitting a reuse pattern to a host device for use in context sharing between an instance of first model and an instance of second model, the reuse pattern identifying the plurality of first KV cache layers to be reused …
Translation: It sends a blueprint to the computer telling it which specific memory layers can be safely shared between the two AI programs.
What this means for the cost of running AI at scale
Running multiple AI agents in parallel is increasingly how businesses use AI, whether that means customer-service bots, coding assistants, or document-analysis pipelines. Each agent traditionally carries its full memory overhead. Microsoft's push into multi-agent AI systems makes this kind of memory efficiency a practical necessity, not just an optimization.
For end users, the effect is indirect but real: faster responses and lower infrastructure costs that don't require buying more hardware to get the same throughput. For cloud providers and enterprises, it means the same server can handle more simultaneous AI tasks. The patent doesn't guarantee all of this ships as described, but the engineering problem it targets is a genuine and growing bottleneck.
Microsoft's 22nd filing we've tracked in our AI agents working together space since May adds to work on auto-building missing agents and rewriting instructions from errors.
Every time a business runs multiple AI assistants at once, each one re-reads the entire shared background material independently, as if the others don't exist. At the scale companies now deploy these systems, that redundancy adds up fast: more memory, more computing power, more time, with nothing gained from the duplication.
Microsoft's patent targets that waste by letting one AI hand off its intermediate work to another, reducing repeated effort even when the two assistants aren't built identically.
The approach requires working out the sharing rules in advance for each specific pairing of assistants, so organizations with varied or unpredictable workflows won't see automatic savings. For those running consistent, repeating operations, though, a concrete and costly problem gets a proportionate answer.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
20 drawing sheets from US 2026/0259830 A1 · click any drawing to enlarge


Show the other 12 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in