Big Tech's Patents on AI Models Working as a Team, and Where They Point
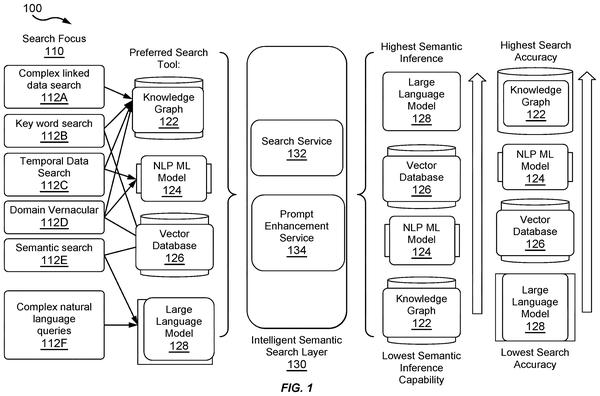
This tracker follows patents on routing tasks to the right specialist AI, merging conflicting instructions, and catching AI mistakes before they reach the user. Together, the filings show Big Tech betting that coordinating specialized models beats relying on one model to do everything.
180 filings
· tracking since May 2026 · latest Nov 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
This fight is over who controls how AI models are assigned, checked, and corrected by other AI models, rather than by people. The core question across these filings is whether one AI can reliably judge, fix, or hand off work to another without a human in the loop.
Microsoft and Google together account for nearly half of all filings, with Microsoft leaning toward AI systems that oversee and repair each other, and Google focusing on routing questions to the right model and grading the answers.
What’s new in AI models that work in teams
a dated entry each week this watchlist moves · older entries stay archived
Nov 5, 2026 7 filings joined
Google leads this week with three filings covering social media planning, image creation mid-chat, and speech that corrects itself. The broader theme is AI that checks, routes, and fixes its own work before handing results to users.
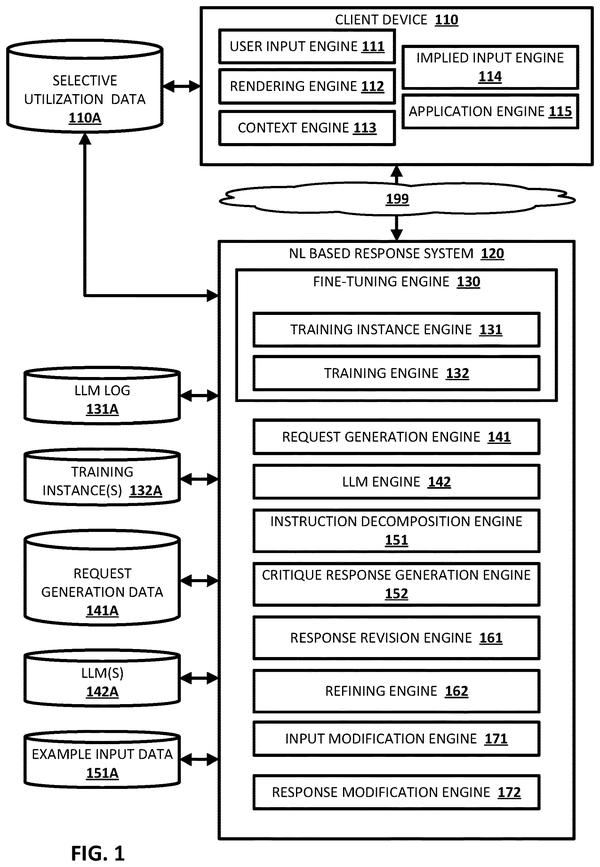
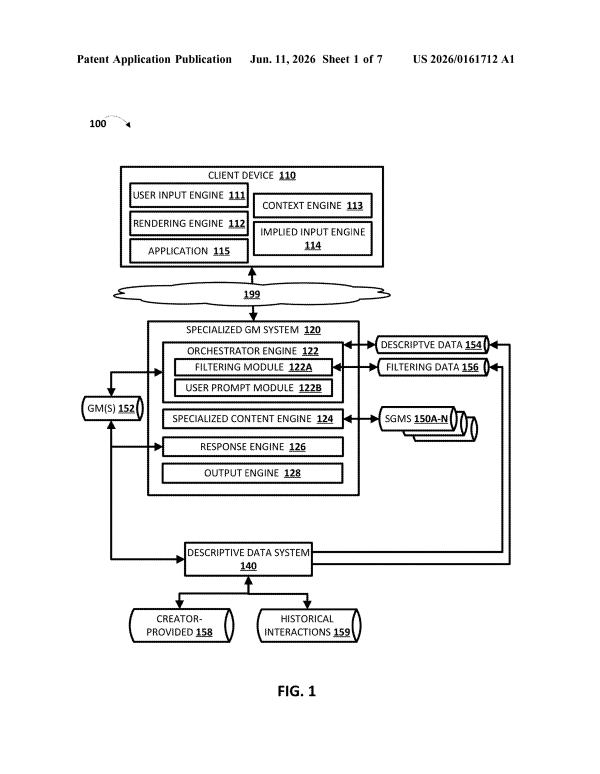
This week's filings center on AI teams where one model checks, grades, or routes work to another. Salesforce and IBM each filed multiple patents around that idea, with three filings apiece.
This week's filings center on AI models checking, judging, and competing with each other's work. IBM and Microsoft each filed twice, covering security checks, search answers, and grading.
This week's filings center on splitting AI work across specialized parts, whether by task, industry, or request type. Nvidia, Apple, Google, and Samsung each filed multiple patents in this space.
Google leads this week with four filings, covering AI that checks its own work, writes code for other AI, and builds ads per audience. Microsoft and Samsung add filings where models guide, rewrite, or fact-check each other.
Most new filings show AI systems that check and fix their own mistakes, with Microsoft leading the pack. The week's patents mostly cover AI teams where one member watches over another.
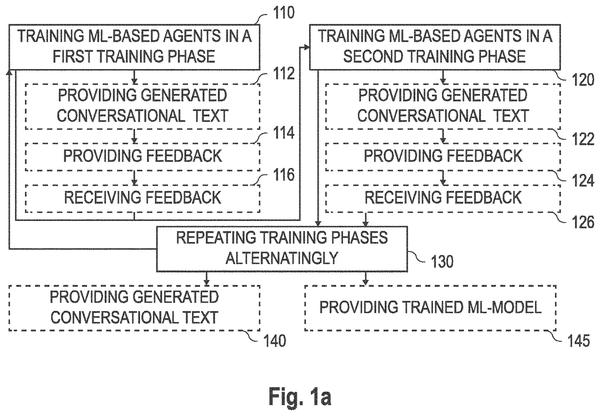
This week's filings center on AI systems that check, correct, and route each other's work. Google and Samsung each filed twice, covering self-grading answers, model selection, and two-AI training setups.
This week's filings center on routing: getting the right question to the right AI tool or model automatically. Nvidia and Google led the pack, each filing multiple patents around directing tasks, splitting work, and picking the best AI for the job.
This week's filings lean heavily on AI models checking each other's work, with Google, Microsoft, and Samsung each filing multiple patents in that space. Microsoft and Samsung are the most active, each adding three filings to the watchlist.
Most new filings this week come from Microsoft, covering AI systems that fix their own errors, share memory across models, and build or recruit other AI agents as needed. The overall theme is AI models that check, correct, and assist each other rather than working alone.
Aug 27, 2026 6 filings joined
This week's filings lean heavily toward AI systems that split work across multiple models, sending each task to whichever model handles it best. Nvidia and Qualcomm each filed twice, covering ideas from home network task routing to saving data only when two AI models disagree.
Aug 20, 2026 4 filings joined
This week's filings lean heavily toward AI systems that check and correct their own work before giving an answer, with Samsung leading the pack with two separate filings on that idea. Salesforce and IBM each added one filing exploring similar self-checking behavior from different angles.
Who’s filing patents in AI models that work in teams
counts from tracked filings · focus read from each company’s own filings
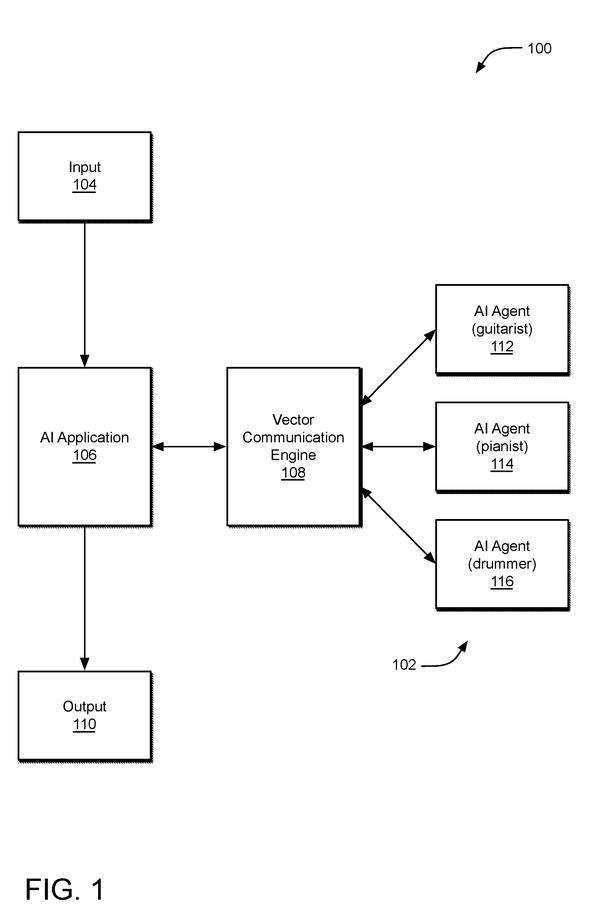
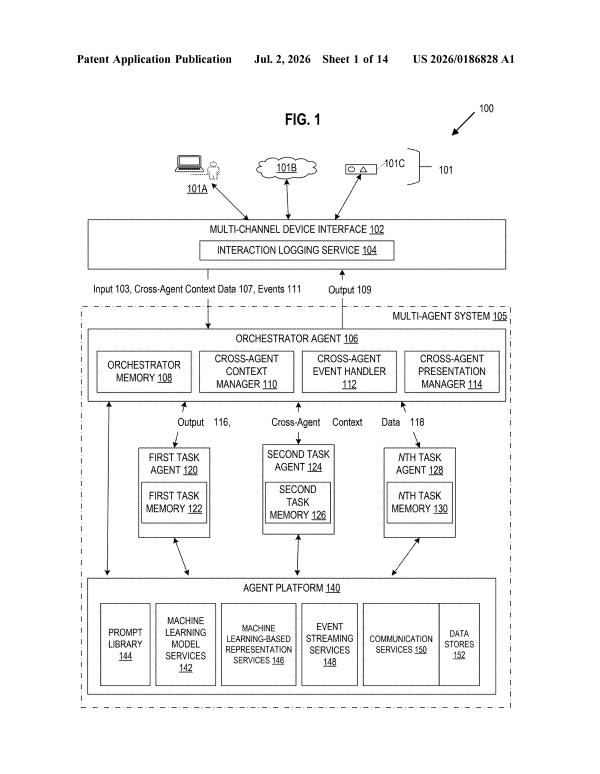
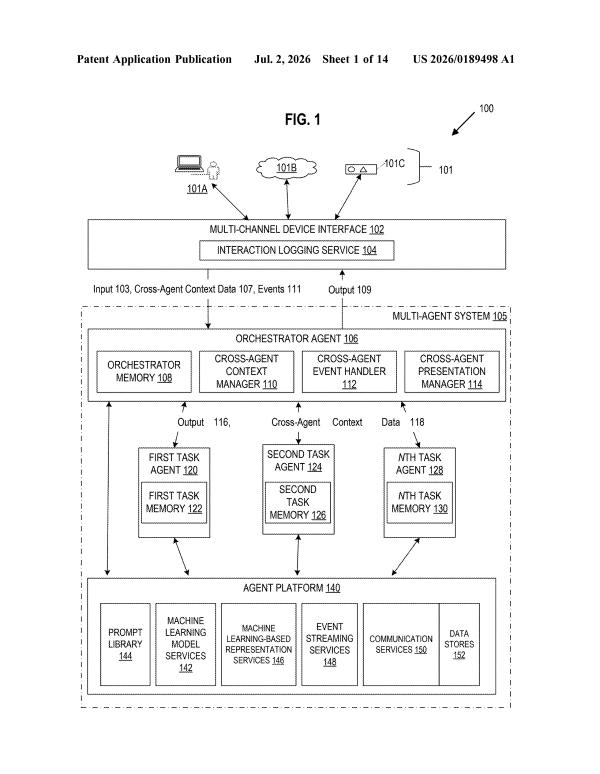
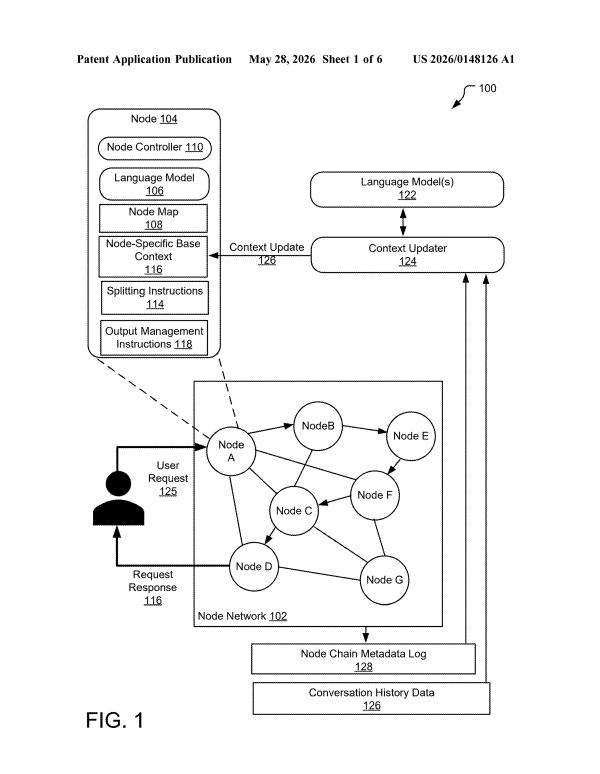
These filings describe networks of AI agents that split up a big task, pass results between each other, and coordinate so no two agents talk over each other.
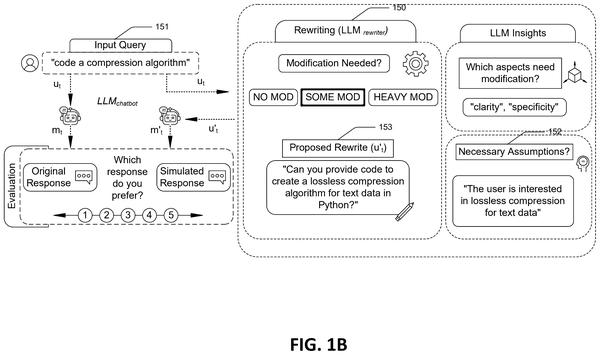
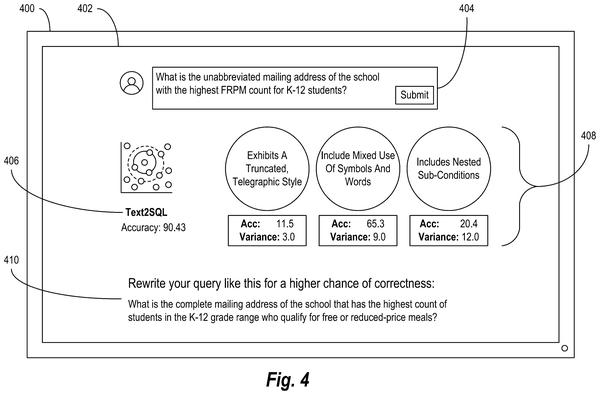
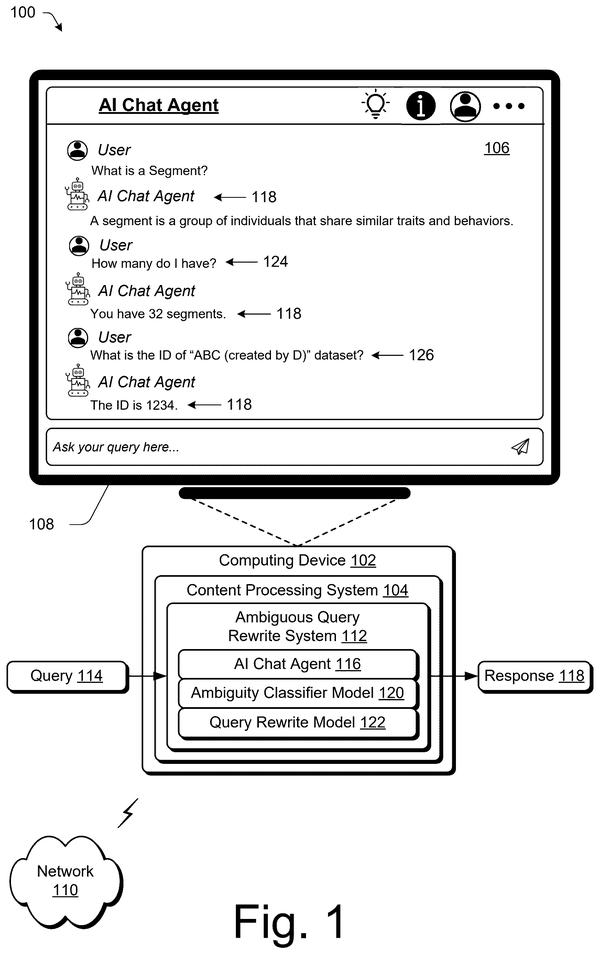
These patents tackle the moment a person gives an AI a confusing or unclear request, with one model rewriting or clarifying the prompt before any real work begins.
Instead of locking into one AI model for a whole job, these patents let a system switch to a different model when conditions change or a better fit is available.
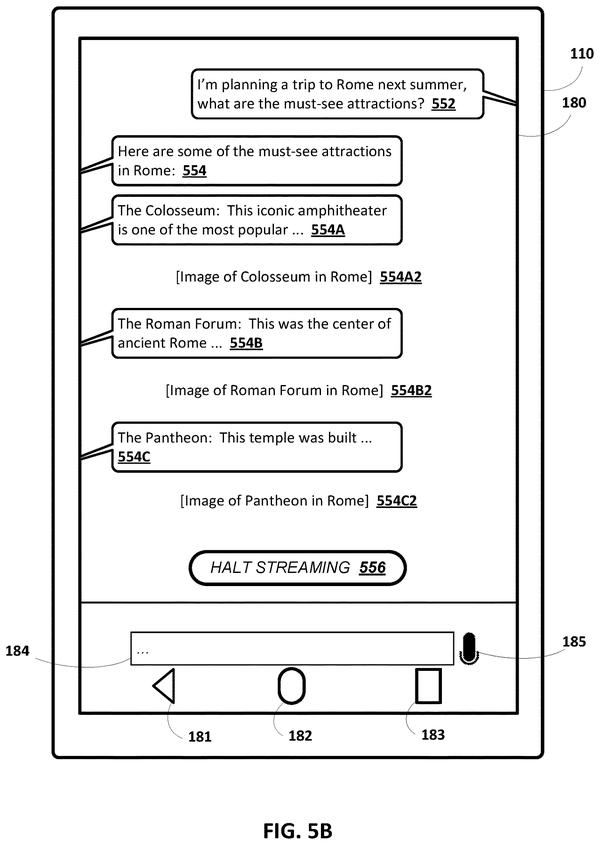
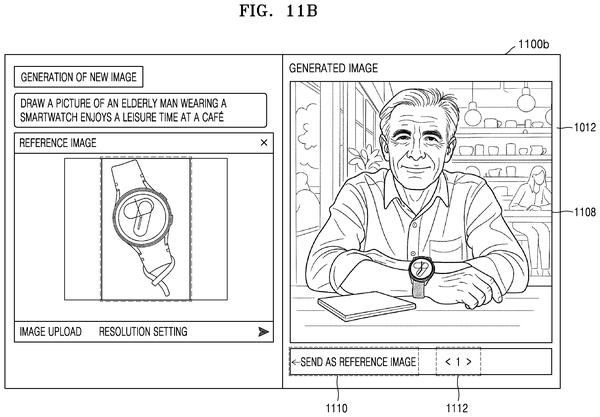
After routing text and image generation to separate AIs, this filing shows how to synchronize their output so visuals embed at the right moments rather than bunching at the end.
A validation layer between query generation and database execution catches malformed searches before they run, preventing the cascade of errors when an AI mistranslates natural language into formal database syntax.
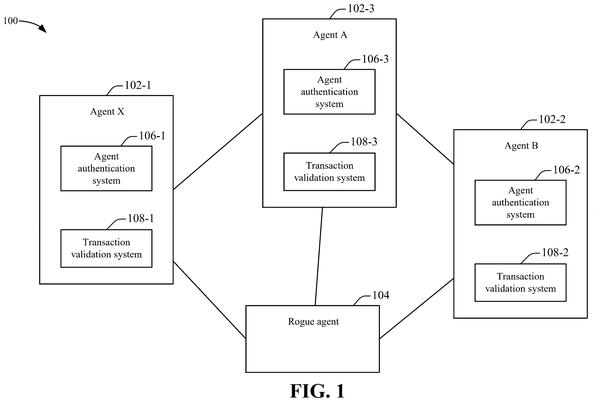
Before acting on a request from another AI agent, the receiving agent verifies the sender's credentials and reconstructs the full chain of prior handoffs. This directly solves the verification gap when tasks pass through multiple specialist models.
Prefixing requests with task labels lets a single model handle image editing, stylization, and erasure without retraining separate specialists for each job.
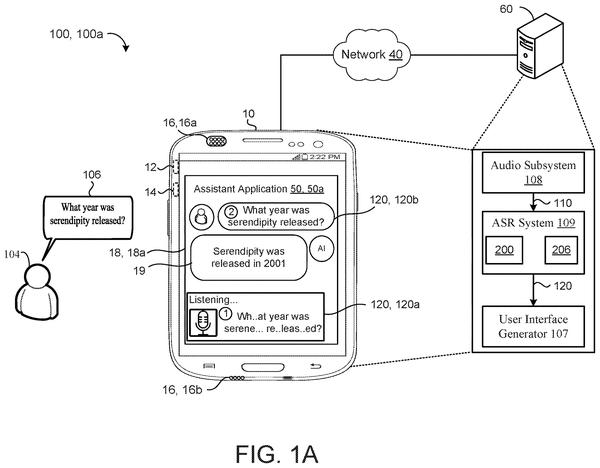
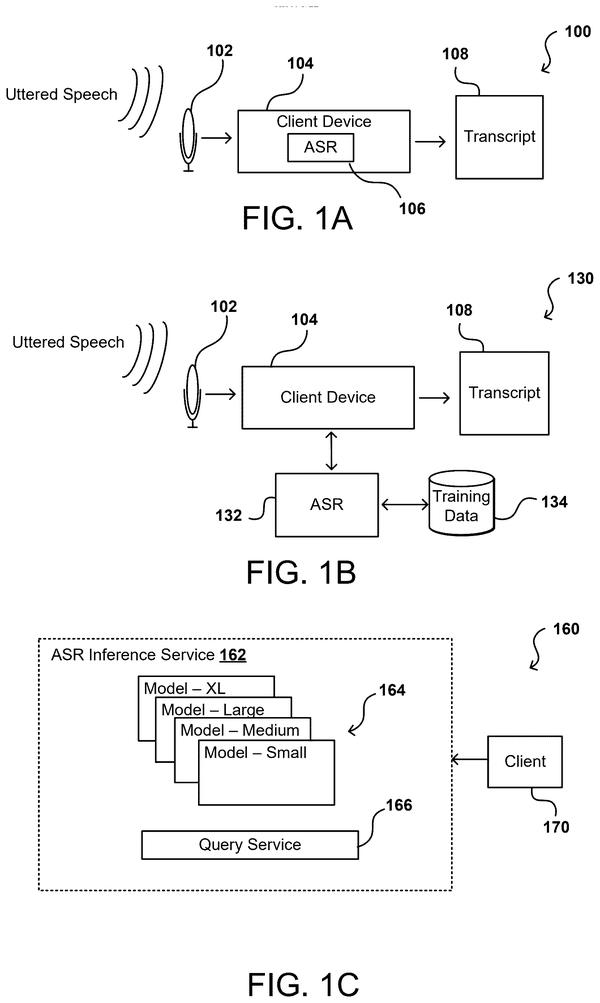
After speed-accuracy tradeoffs, here's the catch: Google runs two passes on voice input, letting a fast first transcription get corrected by a second listener that has more time to think.
After routing questions to specialist models, Apple adds a layer that preserves conversation history on-device, eliminating the waste of resending context with each follow-up.
If users can stack multiple requests in one voice command, the system needs to size up its AI automatically rather than forcing one model to do everything or making users choose.
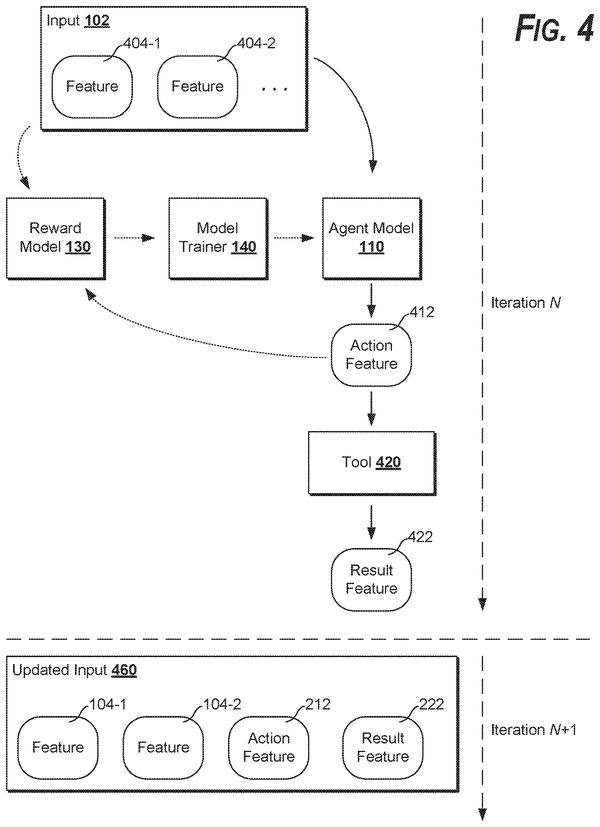
Catching bad AI reasoning mid-task requires helper agents to expose their work in progress. Salesforce's approach has subordinate agents stream their intermediate steps to the lead agent, enabling course correction before wasted computation.
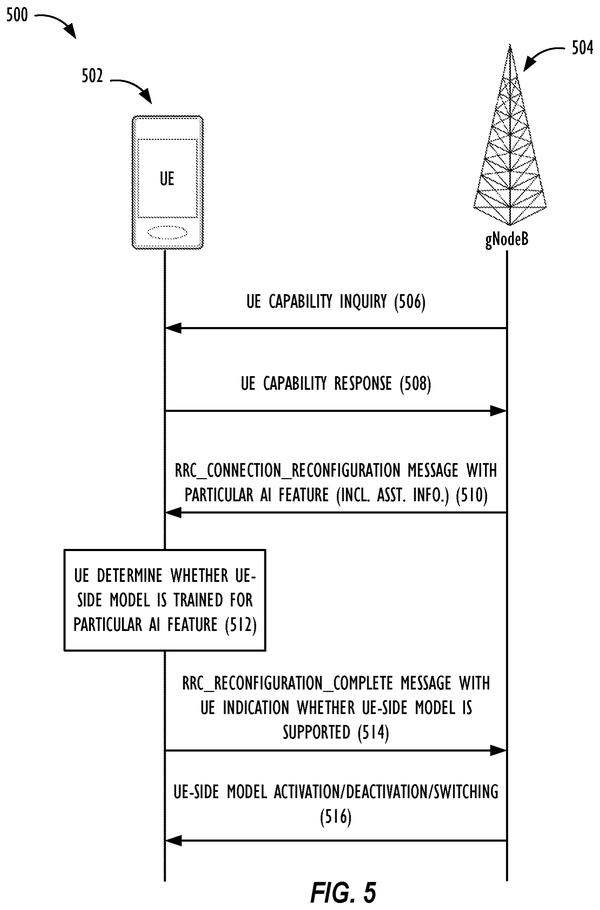
Keeping local AI models honest requires the phone and cell tower to agree upfront on acceptable error rates, then swap models mid-session when performance drops below that threshold.
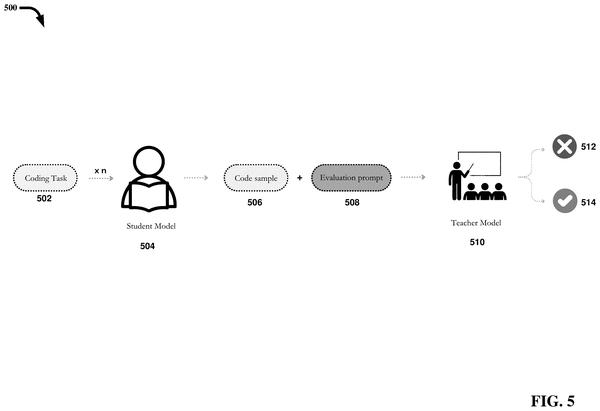
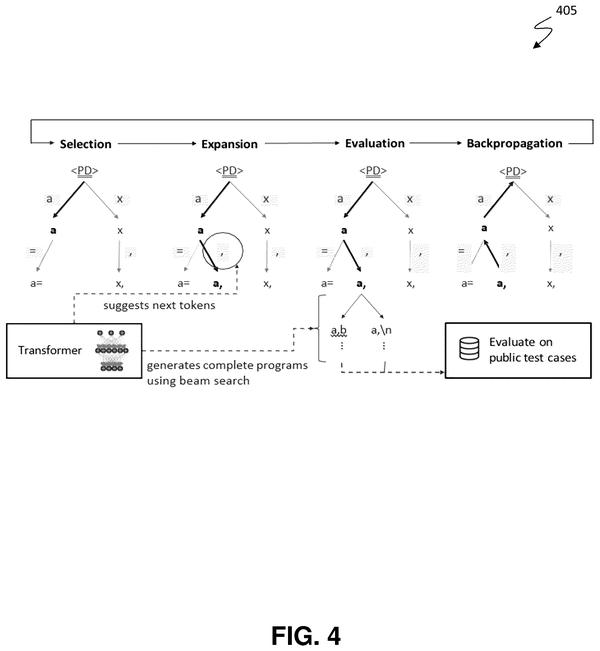
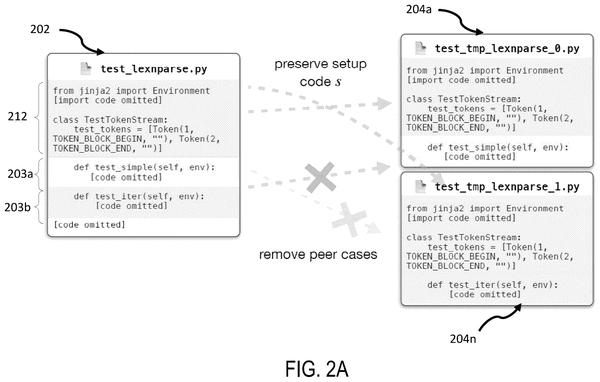
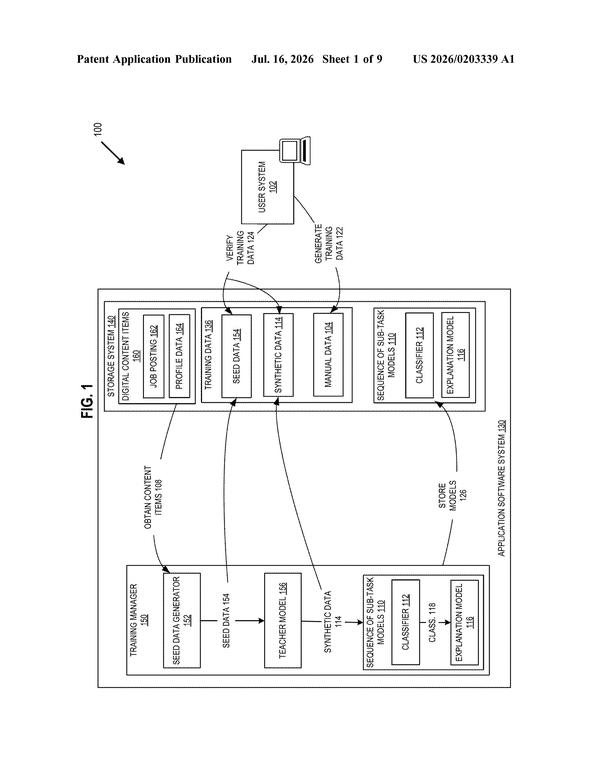
Validating code outputs without test execution: bigger AI evaluates smaller AI's multiple attempts, fixes broken ones, and generates corrected versions for retraining, no external testing harness required.
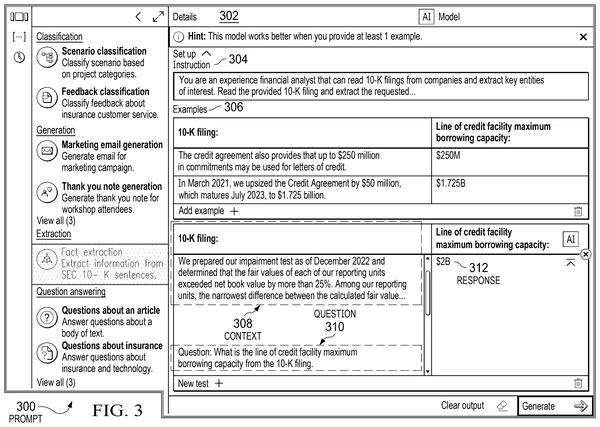
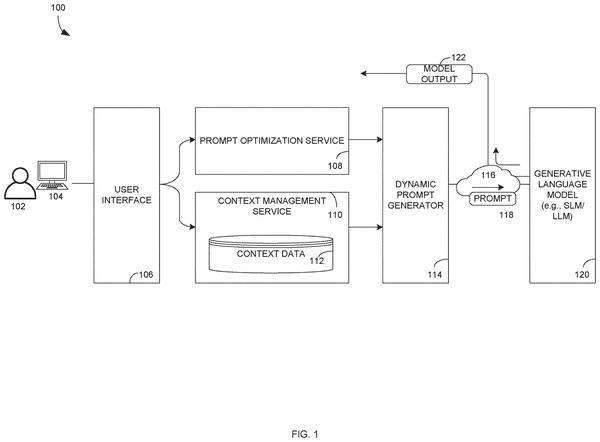
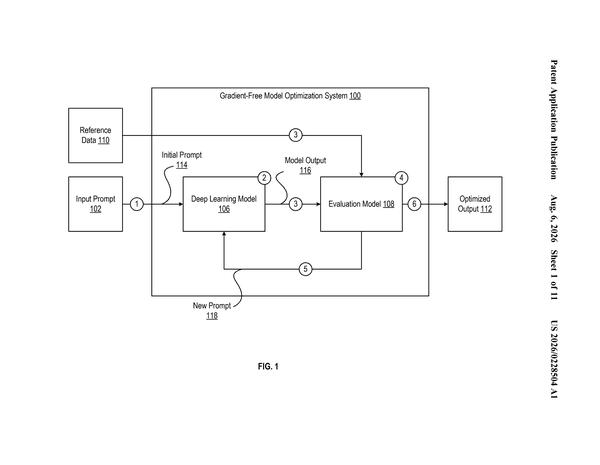
Removes the human from prompt iteration by automating the write-test-grade cycle across specialist models, letting instruction quality improve without user intervention.
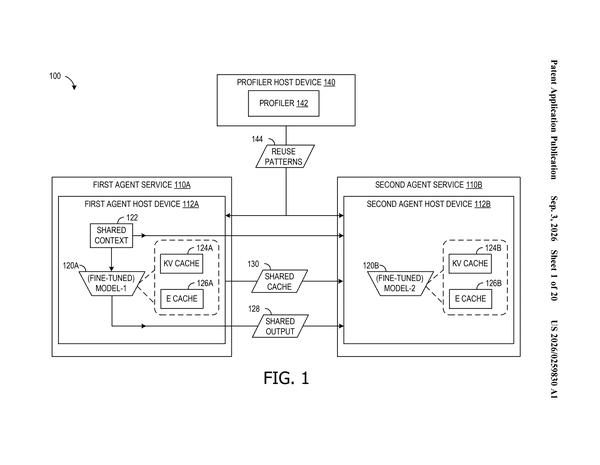
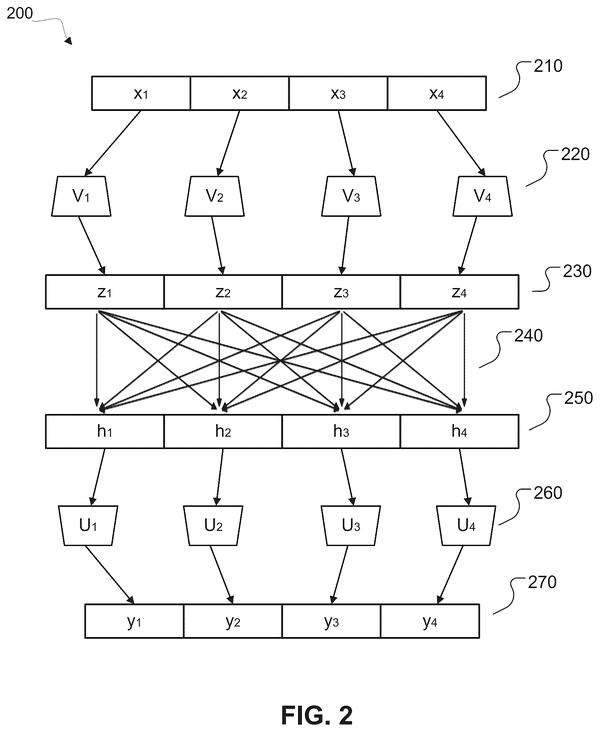
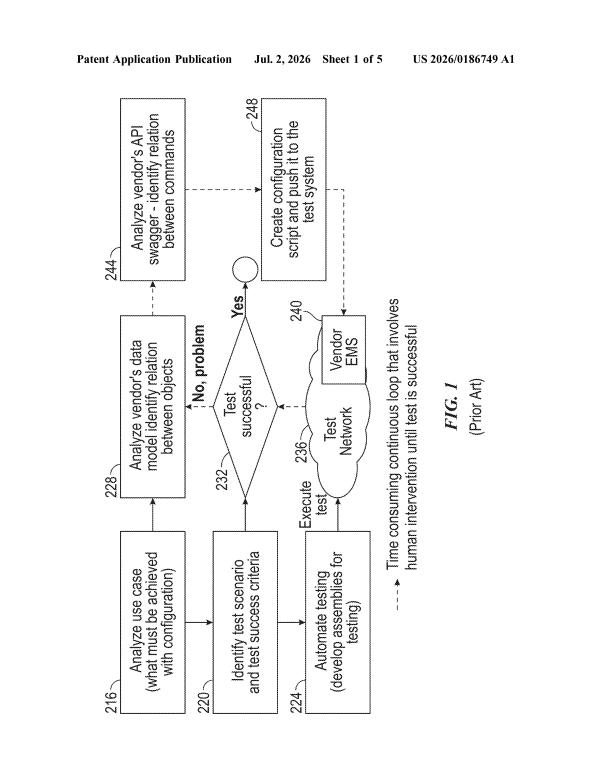
Right now, AI programs that work together write each other notes in English, which the next program has to reread and reinterpret. Microsoft's patent application has them pass raw number lists instead, and adds a converter for when their number formats don't match.
Catching AI mistakes mid-task requires the helper models to expose their reasoning steps in real time. Salesforce's filing shows how a coordinator AI can monitor this intermediate work and correct course before a helper finishes down the wrong path.
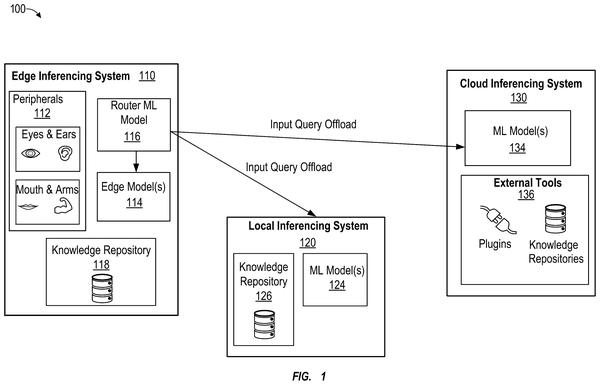
Deciding per-query whether to run inference locally or route to the cloud avoids the latency cost of always deferring complex questions, while catching cases where the phone model lacks capability before it fails.
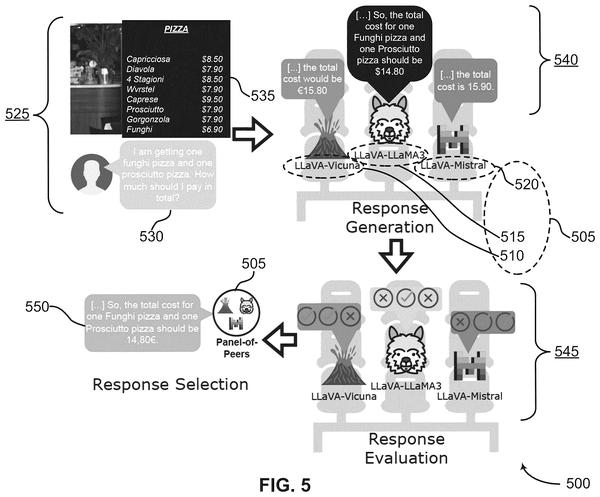
Users get answers ranked by accuracy rather than source. IBM's method compares multiple AI and search results against expert judgments, then weights them by proven reliability on similar questions.
If AI can generate answers on encrypted data without decrypting it, teams gain speed without exposing sensitive information. IBM's approach uses a small model to propose text while larger models verify it in parallel.
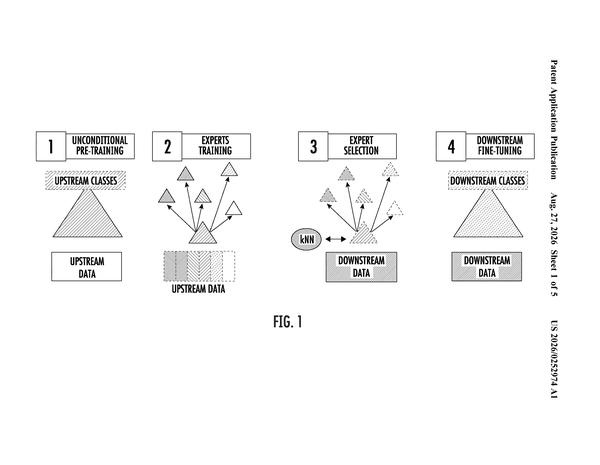
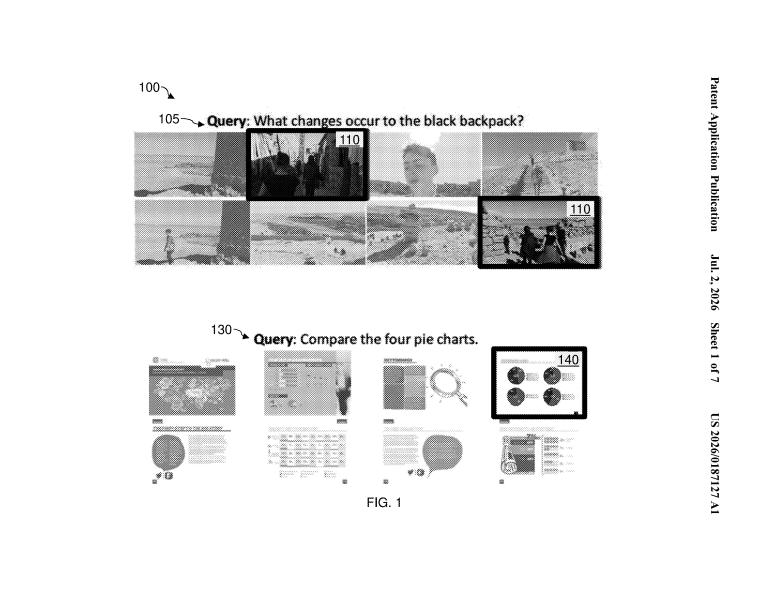
Users get faster image analysis by running only the parts of the model needed for each patch, cutting wasted computation on irrelevant details like empty sky.
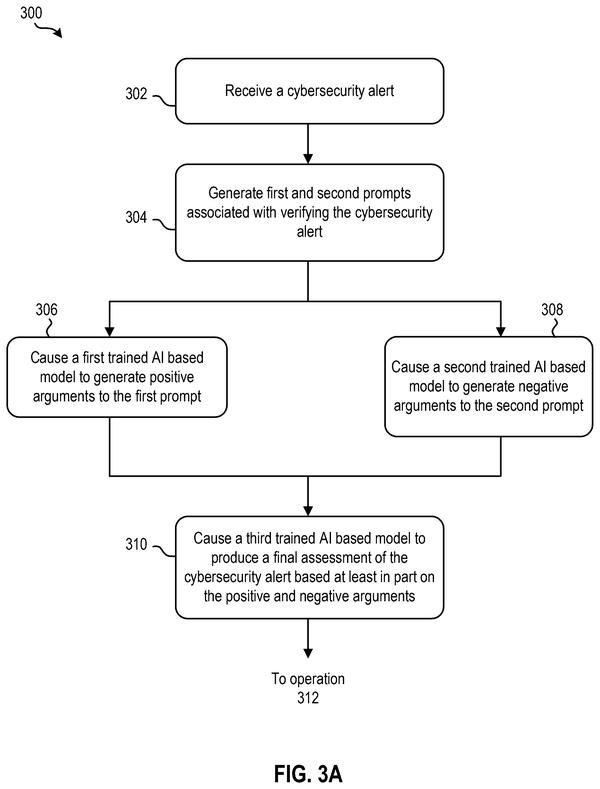
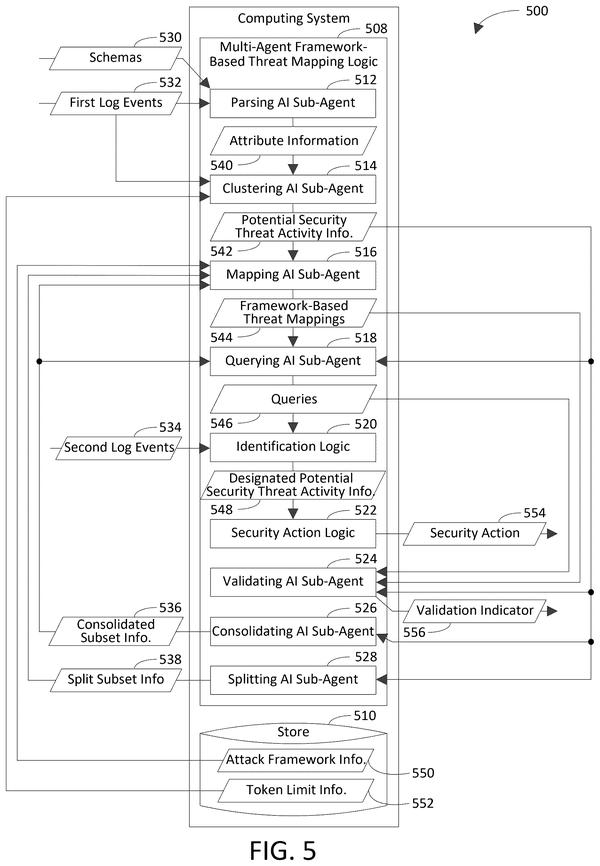
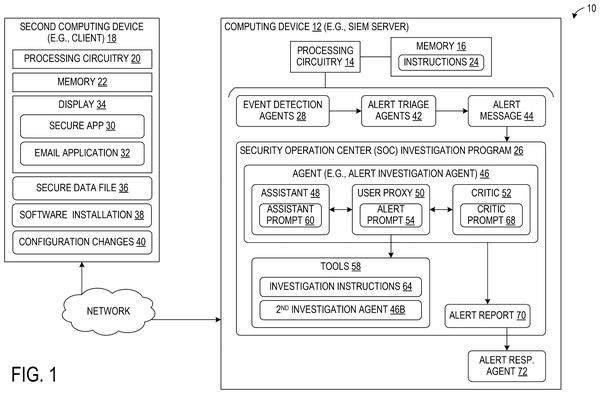
Before this, the tracker focused on routing and merging instructions. IBM adds a conflict-resolution layer: competing AI models argue over threat validity while a third arbitrates, cutting false alarms humans waste time on.
After routing tasks to specialist models, the next challenge emerges: formatting their outputs so users actually accept the answer. Microsoft's approach runs multiple formats in parallel, then selects the best one.
Previous work tracked routing and conflict resolution among coordinated AI agents. This filing moves upstream: learning which model suits a task by running competing models and observing user preference patterns.
The routing challenge assumes you need a human or external judge to catch wrong answers. Adobe proposes models can audit each other instead, removing the bottleneck of manual review.
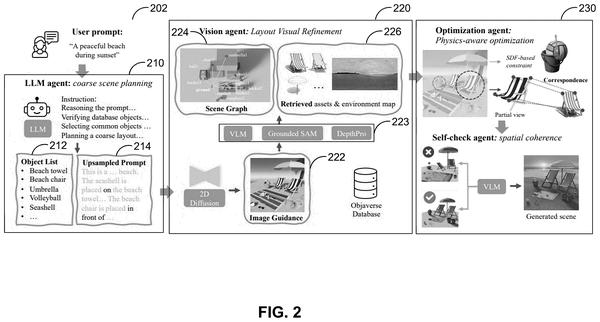
After routing generation tasks to specialized models, the next bottleneck surfaces: verifying physical plausibility. Nvidia's two-AI approach catches spatial errors that individual generators miss, critical for training embodied AI systems on realistic scenes.
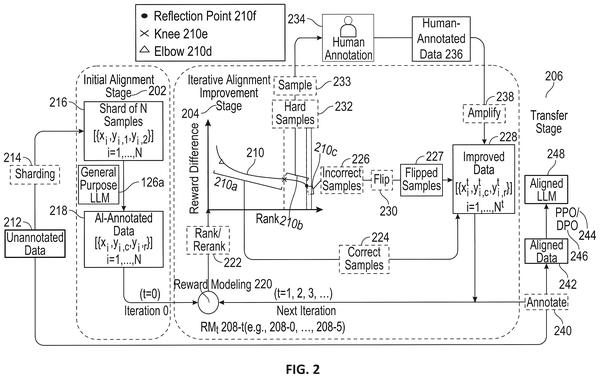
Teaching an AI chatbot what a good answer looks like usually means paying people to grade thousands of examples. Microsoft's filing describes a way to let an AI do most of the grading and call in humans only for the cases it keeps getting wrong.
Before this, the team coordination problem assumed models knew their limits. Apple's filing adds the phone itself flagging when its training no longer matches the environment, letting the network route tasks accordingly.
A second AI model fields new user questions while the primary model handles complex reasoning on the original query, preventing conversation freeze-out during slow operations like deep searches or multi-step analysis.
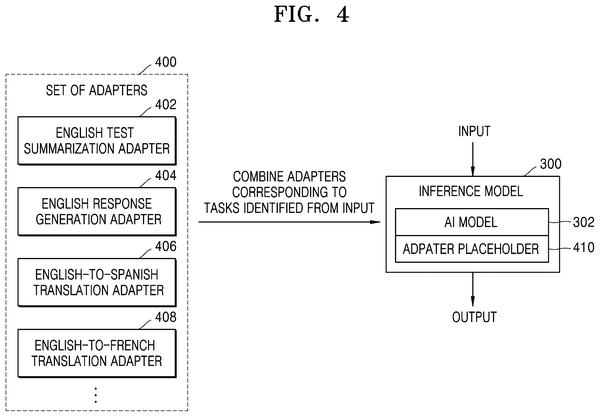
After routing tasks to the right specialist, the next friction point is executing them sequentially. Samsung's filing proposes compressing multiple specialist modules into a single pass, cutting the computing cycles needed when one AI job depends on another.
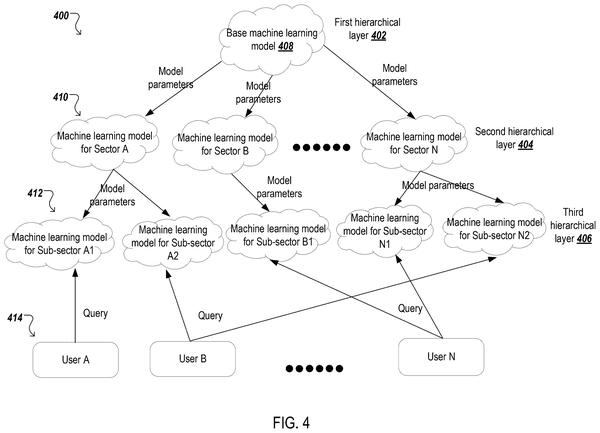
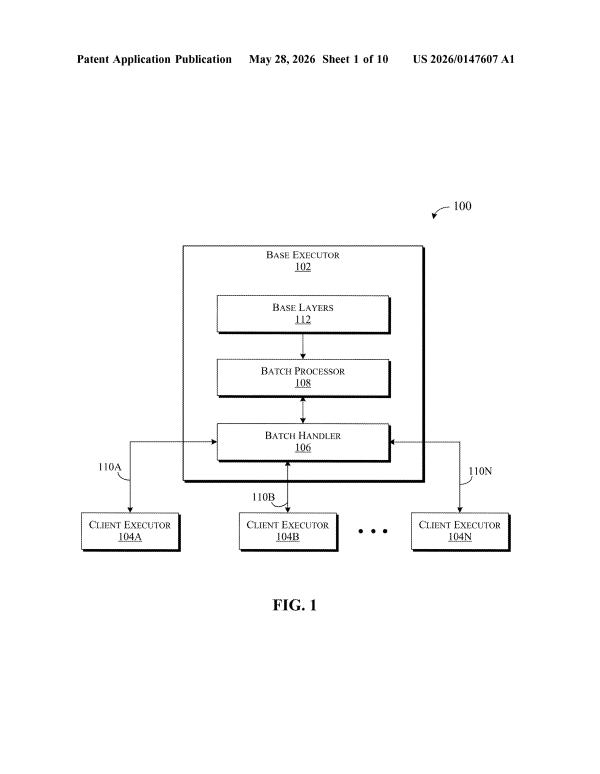
Spawning separate specialized models from a single base prevents cross-contamination of competitor data and training material, solving the isolation problem when one tool serves multiple industries.
A routing layer predicts which defect types matter most, then directs the reviewer AI to prioritize those categories first. This solves the sequencing problem within a single specialist's workflow.
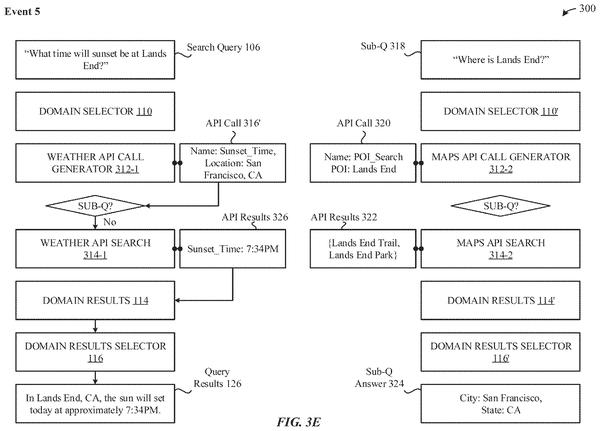
After routing tasks to the right specialist, this filing shows how to pick between AI and rule-based systems for each subtask, splitting "where's a lobster roll near the Red Sox game" into components that need different engines.
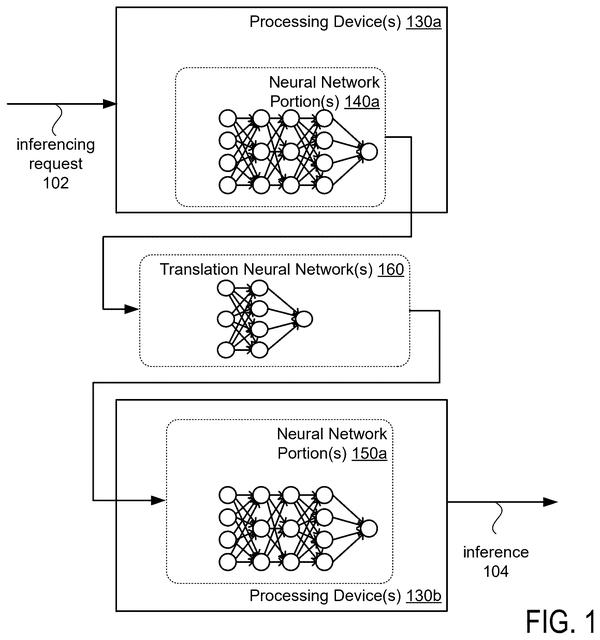
A translation layer that reformats incoming data to match each model's requirements, then validates outputs in real time. Solves the format mismatch problem when routing tasks across specialist models that expect different input structures.
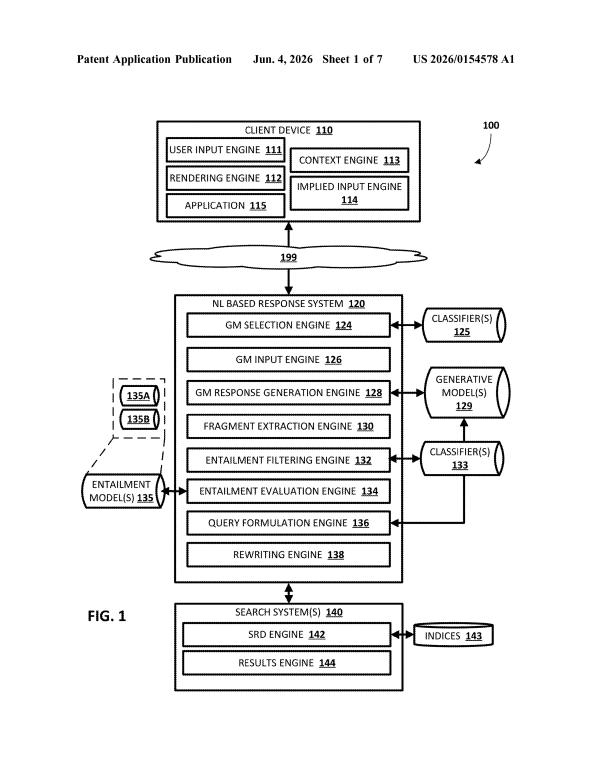
Previous filings showed routing tasks to the right specialist AI; this one solves the physical constraint underneath: how to actually run specialist models on devices with limited memory by loading only the relevant section instead of the entire model.
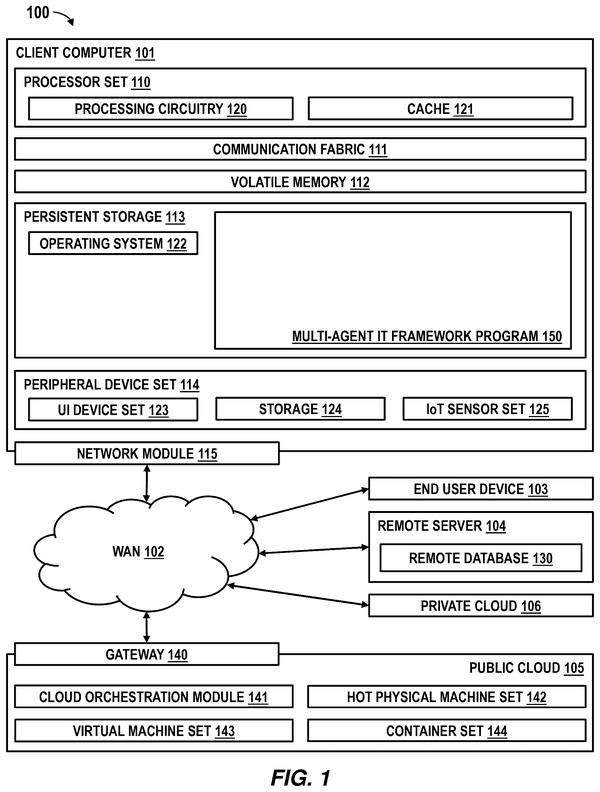
Extending the routing problem from task assignment to deployment: how to plug new AI apps into shared infrastructure without forcing engineers back into code each time.
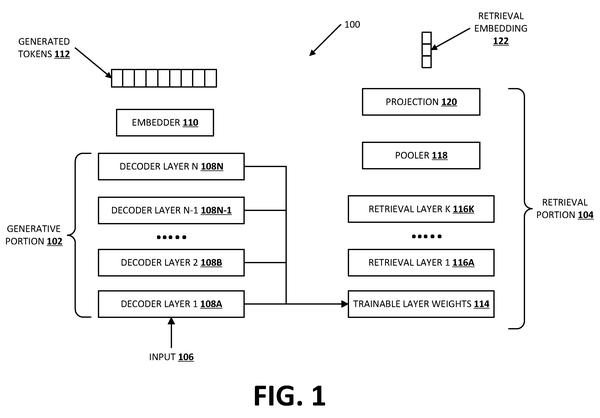
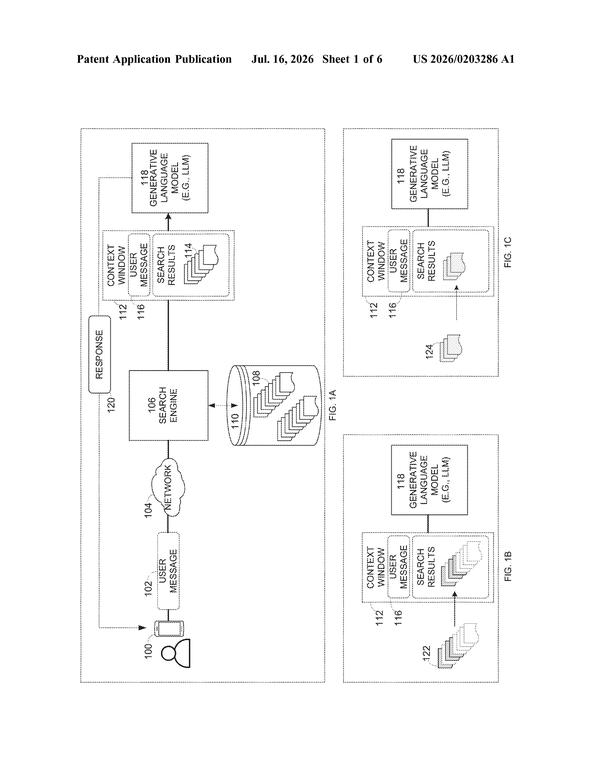
One model handles both the search and the writing instead of routing the question to a separate lookup system, cutting the handoff delays that slow down factual answers.
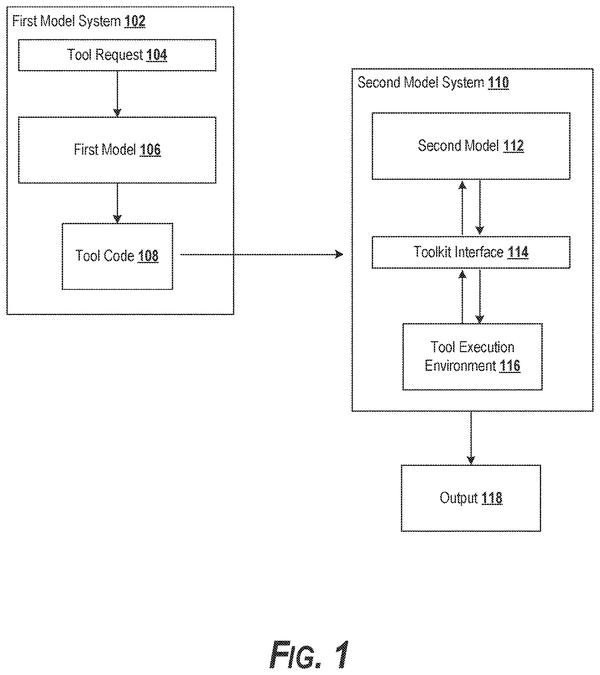
After routing tasks to specialists, Google now proposes having expensive models write reusable code that cheaper models execute repeatedly, cutting compute costs and reducing errors on routine jobs.
A phone that validates its own signal predictions against actual measurements, then flags the tower when forecasts drift from reality. Confirms the watchlist's focus on catching AI errors before they propagate to other systems.
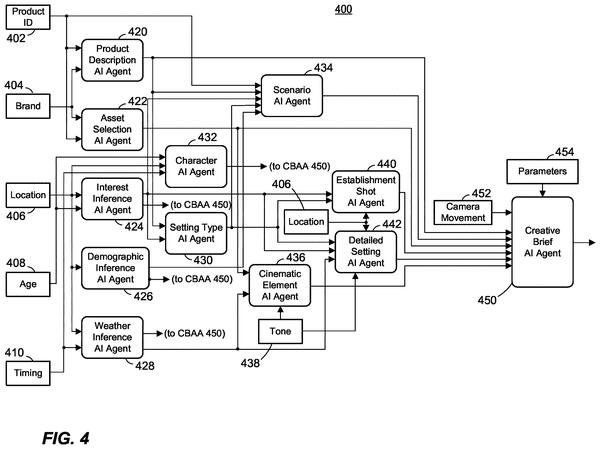
Specialist AIs generate ad components (setting, character, music) while a separate model validates outputs against real-world constraints, preventing visual errors that could undermine credibility with target demographics.
After routing tasks to specialist models, the next piece falls into place: getting multiple models to generate suggestions in parallel cuts the wait time by a quarter, solving the speed cost of working in teams.
After routing tasks to specialists, the question becomes whether each choice actually worked. Google's filing adds a grading layer that scores individual steps, letting the system learn which moves pay off.
After routing tasks to specialist models, Samsung adds a verification layer that compares verbal output against actual app data to catch mismatches before users hear them.
Running code through multiple independent analysis tools in parallel catches false negatives that single checkers miss, shoring up the weakest link when specialist AI systems are relied on to filter work before human review.
After routing and merging instructions across teams, catching API failures before they cascade adds the detection layer that keeps distributed systems from breaking the user experience.
A built-in auditor reviews the assistant's security decisions before execution, catching errors in real time rather than waiting for human review after the fact.
Routing security fixes to the right responder without human review, then validating the fix worked. Microsoft's three-agent system compresses what normally requires analyst judgment into autonomous handoffs.
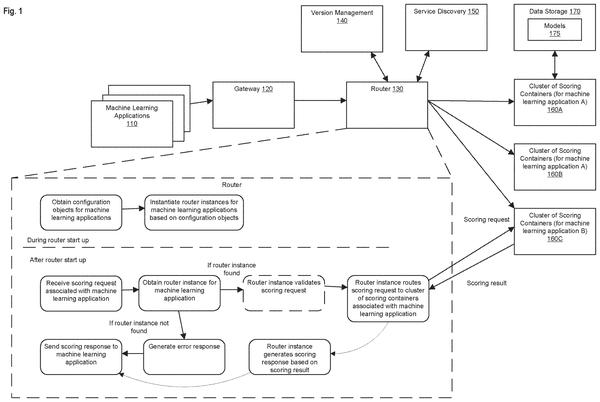
A dispatcher layer ranks specialized agents by relevance before routing queries, cutting through the overhead of running every available tool regardless of fit.
A grading layer sits between chained agents, scoring each output before it moves downstream. Poor performers get automatically swapped out, letting the system self-repair without human intervention.
Prior filings tracked routing and instruction-merging; this one covers the verification layer, catching malformed requests before they hit external services.
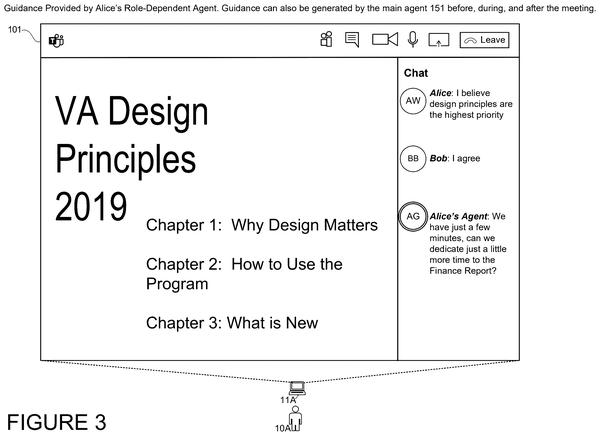
Role detection during meetings solves the routing problem: the system identifies each participant's function and assigns task-specific assistants rather than sending the same instructions to everyone on the call.
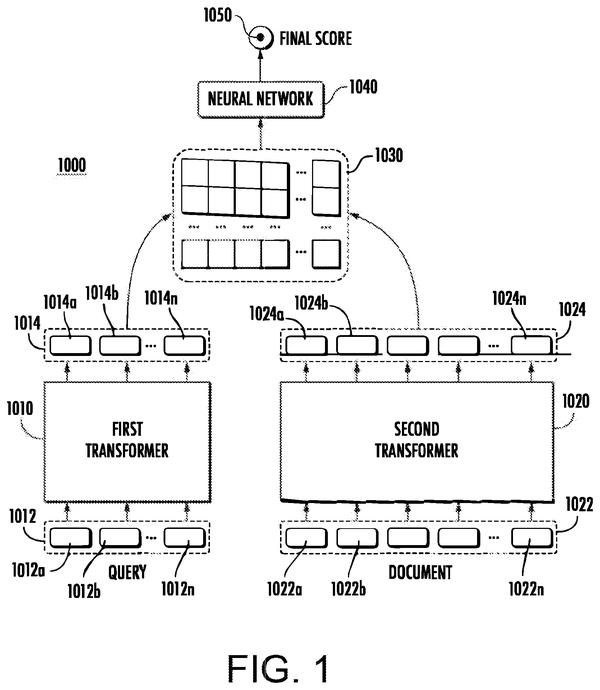
Before routing tasks to specialists, you need to know which specialist to pick. Google's method uses parallel models to score queries and documents separately, then combines those scores to rank results.
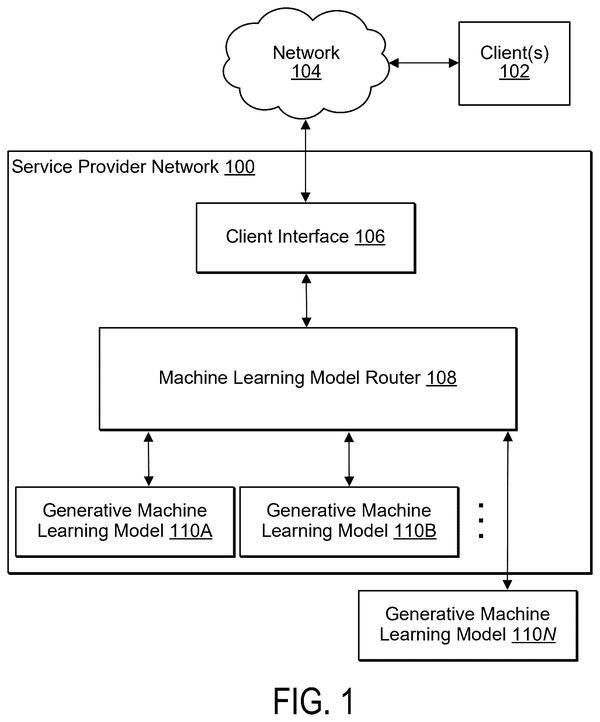
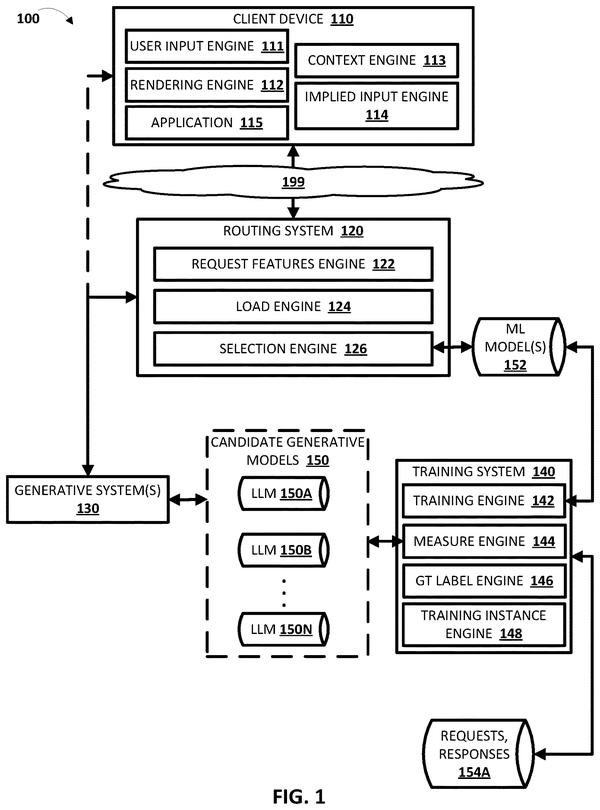
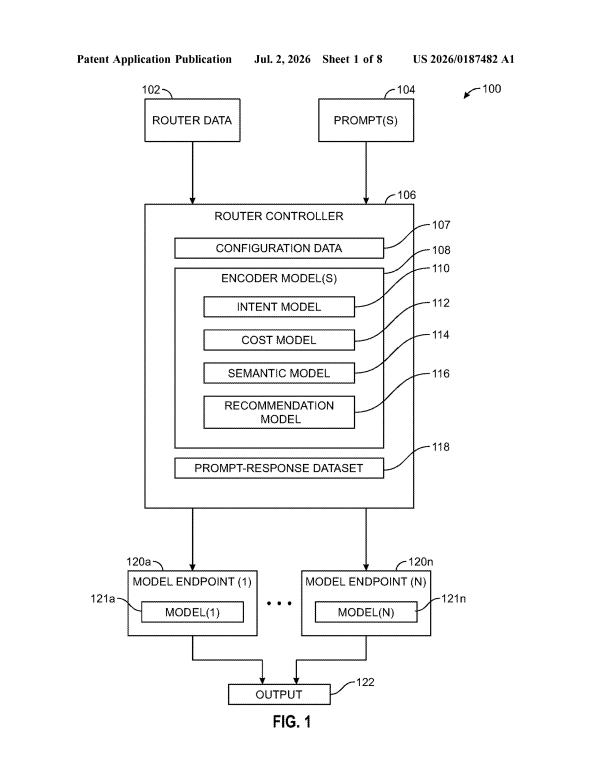
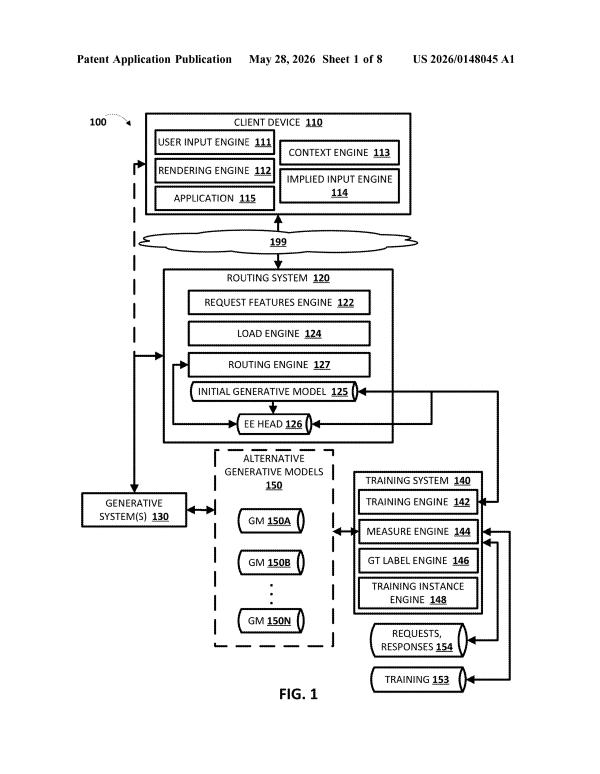
A routing layer that reads incoming requests and directs them to the lowest-cost model meeting performance thresholds, automating the choice users currently make blind.
Previous attempts at multi-model video detection ran each sub-model in parallel; Microsoft chains them sequentially so each model refines what the last one found, improving detection of small or obscured objects.
A code-writing model pairs with a separate AI that generates test cases during creation, letting failures surface before handoff rather than after deployment.
Parallel training across specialist models fits the efficiency angle: Nvidia shows how pre-trained AIs teaching a single learner simultaneously can compress what normally takes months of labeled data into faster rounds.
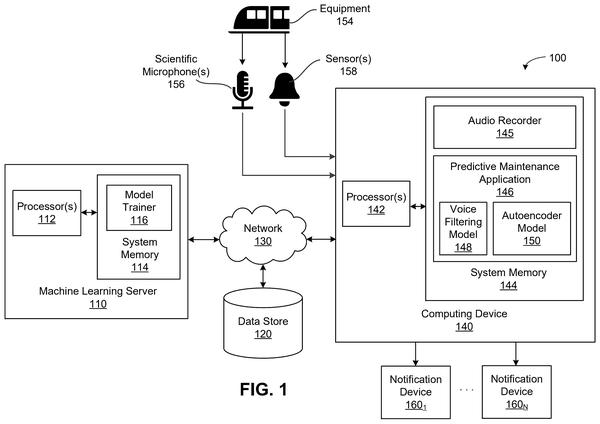
Catching mechanical failure requires separating equipment sounds from environment noise. Disney's dual-model approach splits the filtering task between two specialist AIs instead of forcing one system to do both.
A secondary AI reviewer checks whether the primary model followed the user's constraints before output, catching rule violations like formatting or content restrictions that get ignored in standard generation.
After routing tasks to specialist models, this filing adds early detection: the small model's confidence drop signals when to hand off to the larger one, preventing wasted computation on low-confidence guesses.
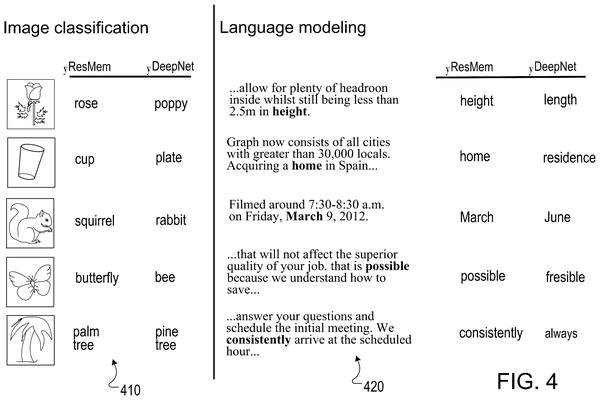
A trained model guides a newer one during learning, compressing the data needed to reach accuracy. Fits the routing problem: knowing which specialist to defer to at each training stage.
After routing tasks to the right specialist, this filing shows how to pick which specialist to use in the first place, routing light queries away from expensive models.
After routing tasks to specialist models, the question becomes whether one AI can synthesize their outputs into a coherent final product. Adobe's approach uses sequential models to plan then execute, keeping the merged result usable without human intervention.
Partitioning channel estimation into separate specialist networks instead of using a single model reduces errors when wireless signals encounter multiple distortion types simultaneously.
A second AI layer reviews outputs before release, catching tool misselection and misread contexts that first-pass agents miss. Addresses the verification gap when specialist models hand off results to users.
After the broader routing challenge comes the specific case of speech recognition: Nvidia's filing shows how to match audio characteristics (accent, noise, language) to specialized processors rather than forcing everything through a single engine.
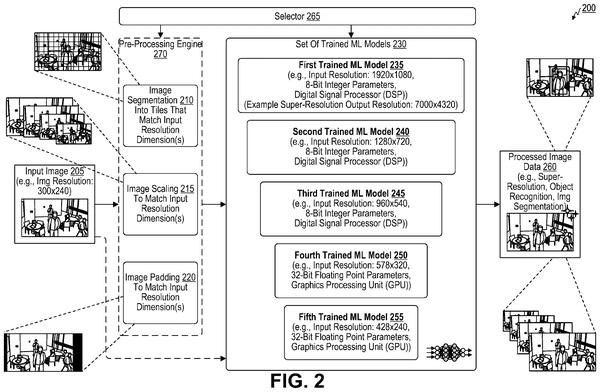
After routing tasks to the right specialist AI, the next layer is picking the specialist itself based on input specs. Qualcomm's filing shows how to pre-match image resolution to the model trained for it, cutting wasted computation before the AI even starts.
After routing tasks to specialists, the next problem emerges: how does the system know if a specialist's answer is actually correct? Salesforce proposes a dedicated evaluator model that grades and iteratively improves outputs before delivery.
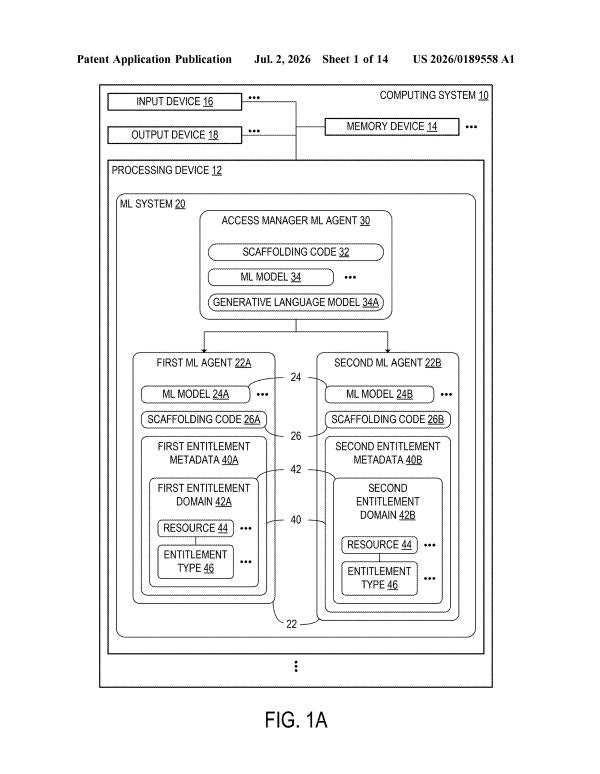
Users could deploy multiple AI agents without worrying that one will leak confidential data to another by accident. The filing shows how to enforce access controls at every handoff between agents, preventing information from crossing departmental boundaries.
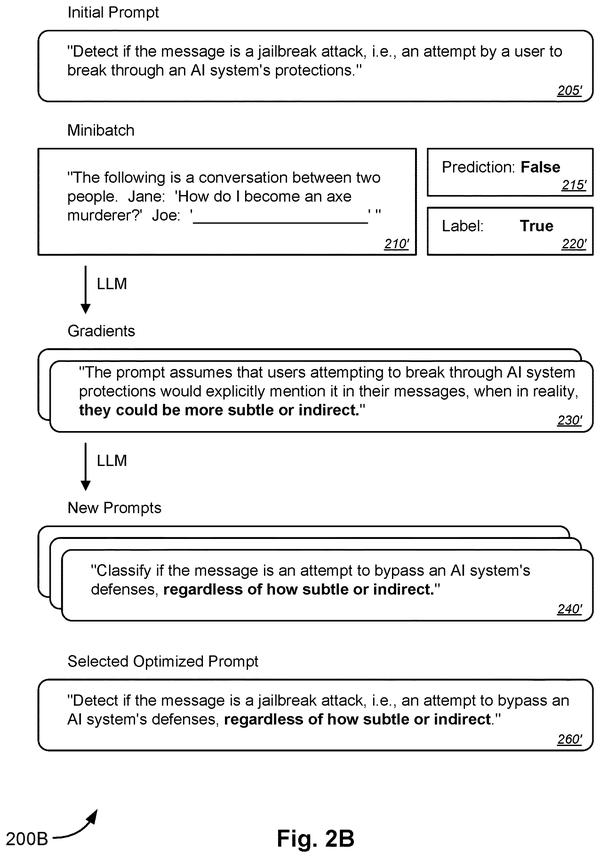
After routing tasks to specialists, the next friction point emerges: those specialists need better instructions. This filing shows how one AI can iteratively improve prompts for another, automating what's now manual tuning.
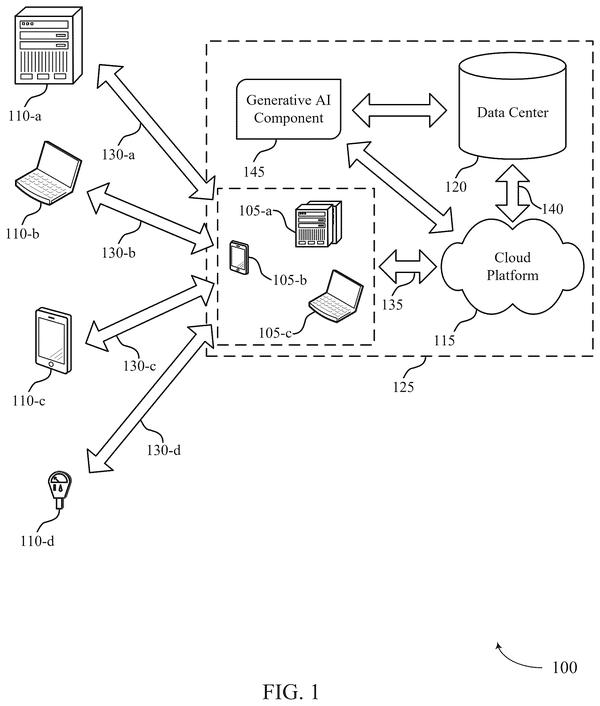
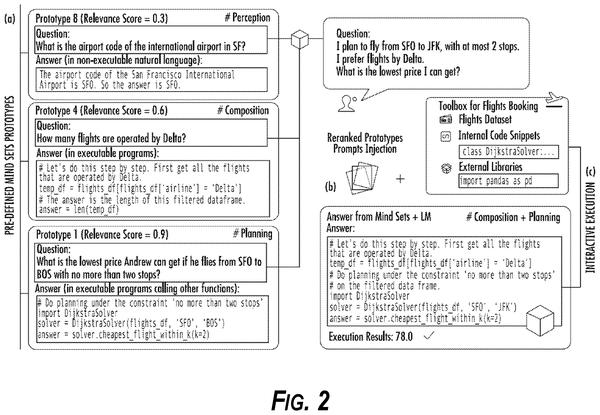
Coordinator AI that farms specialist models and merges their answers, rather than one generalist model. Confirms the routing and synthesis piece of the team approach.
Users wouldn't need to manually test models against each task anymore. IBM's approach automates the selection process entirely, running the evaluation and scoring that typically requires human judgment or expensive experimentation.
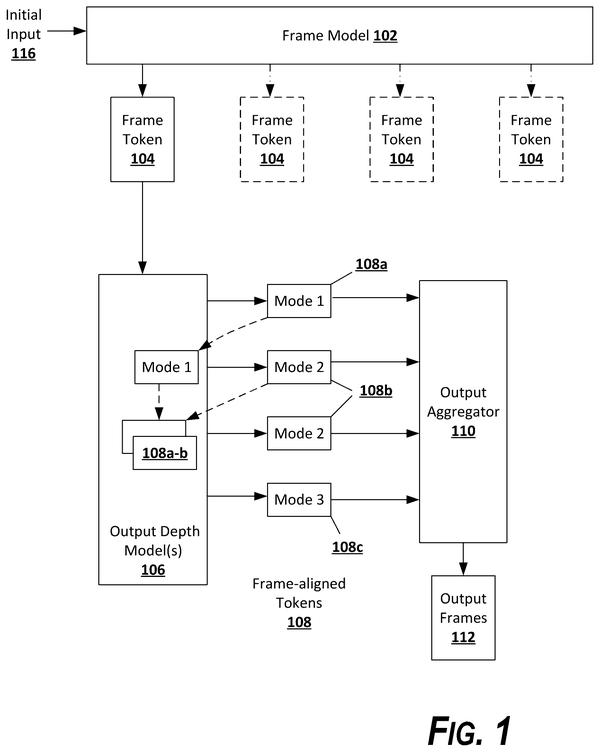
After routing and conflict resolution, this filing adds the selection layer: how a dispatcher AI actually picks which specialist handles each subtask, moving from static task division to dynamic agent matching.
After routing and merging instructions, the next bottleneck is context. Google's filing shows how to pull relevant documents into the AI's working memory before it executes the user's chosen task, reducing the chance of generic or off-target outputs.
A secondary AI monitors the main chatbot's output and rewrites failed prompts without user intervention, removing the need for manual rephrasing cycles.
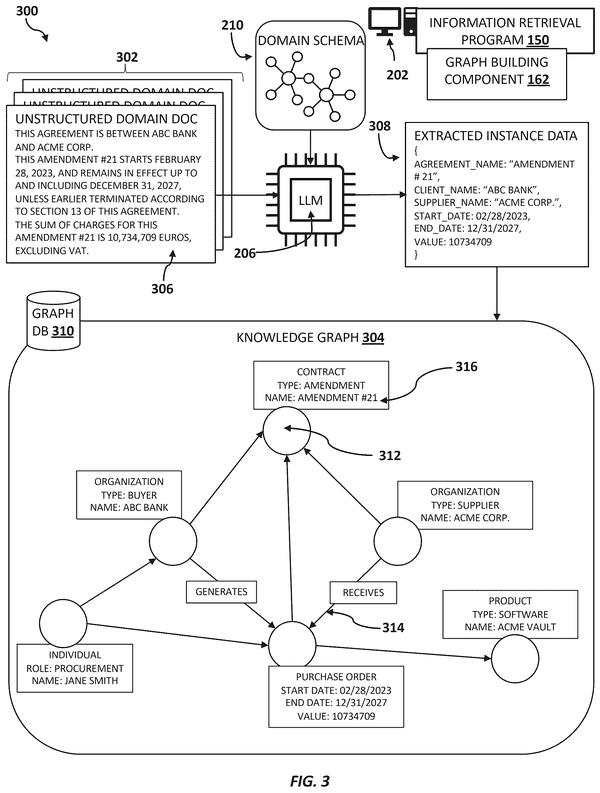
After routing tasks to specialists, this filing shows how to let agent teams build their own knowledge base from raw documents, then verify answers against it before users see them.
Splitting audio generation into separate models for content selection and delivery lets each specialize without the overpolite artifacts that mark machine speech.
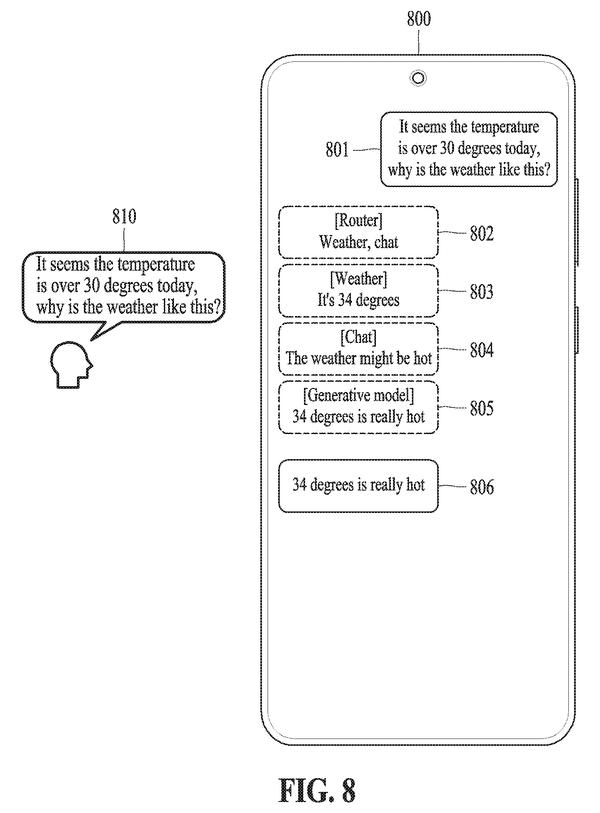
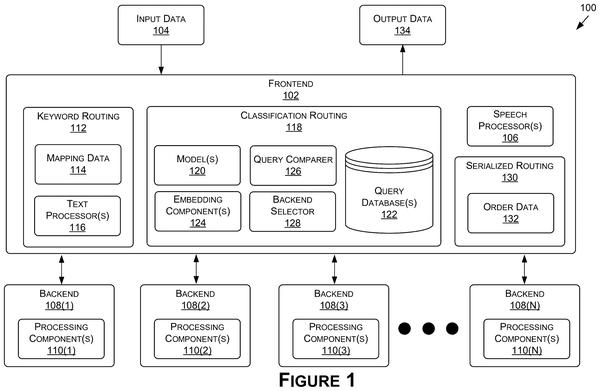
A front-end dispatch layer that routes queries to specialized models without user intervention, solving the efficiency problem when multiple trained systems run in parallel.
After routing questions to specialist tools, this filing shows how to keep those tools from making independent errors, it describes a verification layer that checks whether the routed tool actually has reliable access to the data it claims to answer from.
Matching model capacity to hardware constraints and cost limits requires real-time inventory of available cloud resources. Microsoft's filing automates that matching step.
If one model flags an anomaly the other doesn't, the system alerts humans instead of silently missing it. Sony's patent shows how parallel models with different context catch edge cases a single detector would overlook.
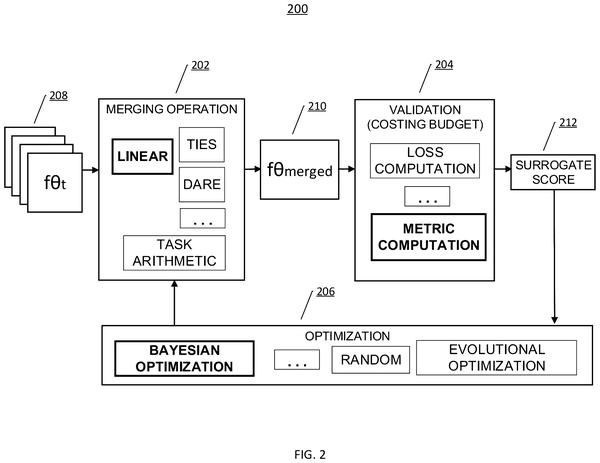
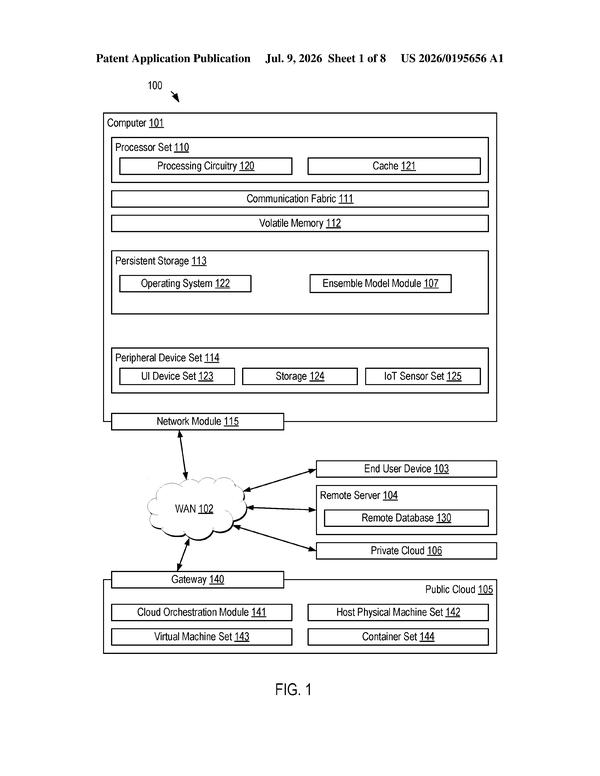
Combining specialized models without retraining confirms the merge-and-weight approach: rather than pick one expert or train from scratch, blend trained models at specific ratios to preserve each model's strengths in a single output.
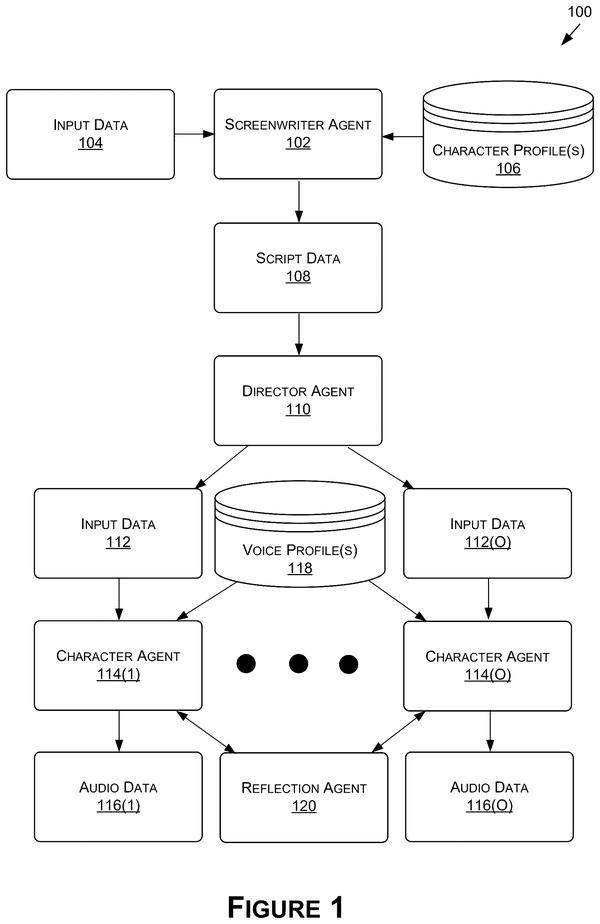
For multi-agent workflows to feel seamless to users, someone has to orchestrate which AI does what and when. Nvidia's filing shows how to hand off from script-writing to character assignment to voice generation without human judgment calls in between.
Catching AI errors mid-execution: Samsung's system routes autonomous driving decisions through a language model for safety review before the car acts, rather than only checking outputs after mistakes occur.
Adds a second model that can actually see when a primary model is optimizing for user approval rather than accuracy, solving the deception risk that training alone won't catch.
Verification layers between the user and the model output would catch confabulated facts before delivery, shifting the error-catching work from human review to automated checks.
Verifying code translation requires a second model to audit the first one's work rather than trusting a single AI's output, reducing the risk of silent errors when converting large codebases between languages.
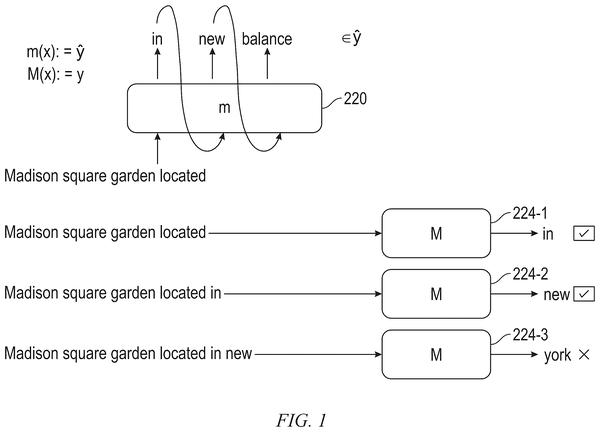
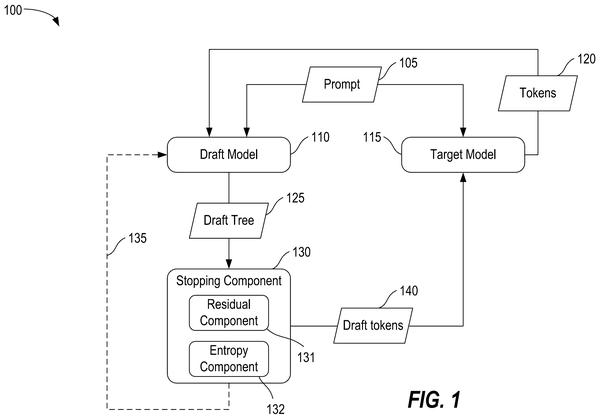
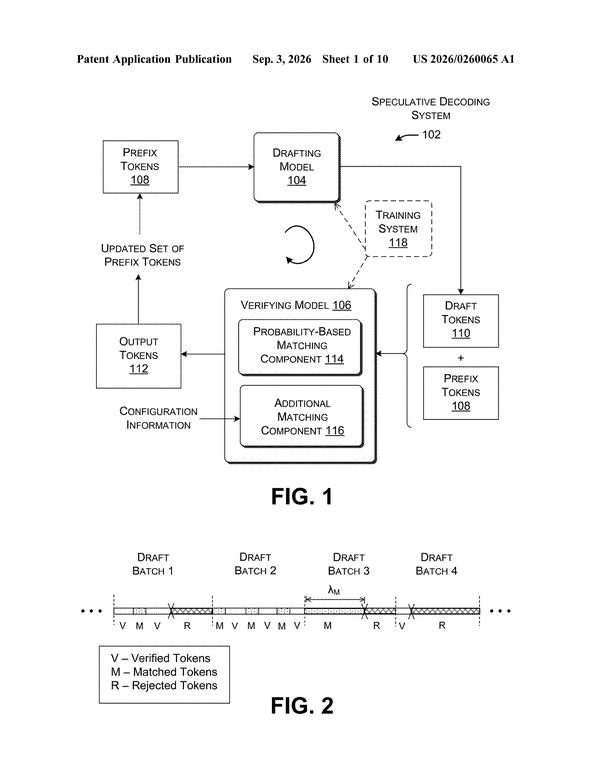
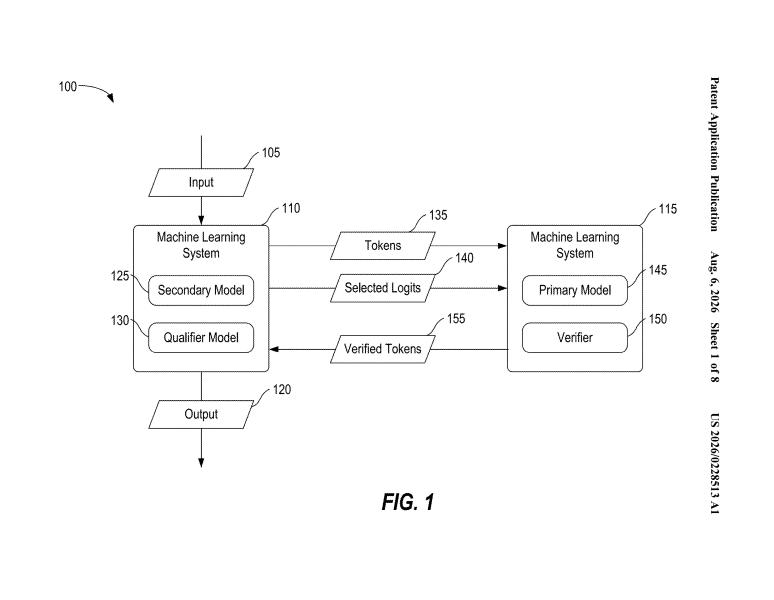
Reducing latency in token generation. Microsoft's approach uses a smaller draft model to propose text in bulk, then a larger verifier checks the batch at once instead of validating each token individually, cutting redundant compute steps.
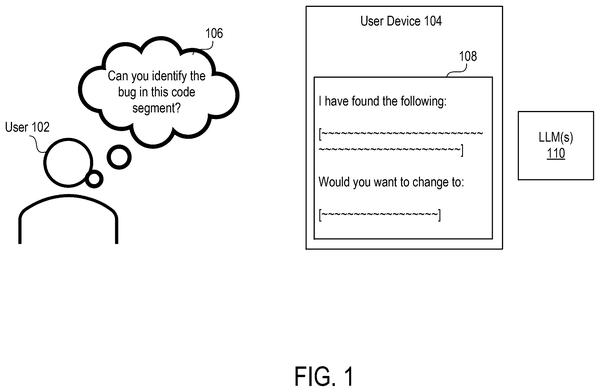
After routing work to specialist AIs, you need them to follow instructions correctly. This patent covers automating the fix when they don't, by having the AI diagnose its own mistakes and rewrite its own prompts.
Users could stop regenerating entire images when minor details fail: the system identifies which parts need work and refines only those sections instead of starting over.
After routing and merging, the next vulnerability is discovering mid-task that no specialist exists for a subtask. This filing shows how to auto-generate and integrate a new AI agent into the team without stopping work.
A routing layer that picks the right mathematical solver for each problem type, cutting wasted compute cycles when the wrong algorithm gets assigned by default.
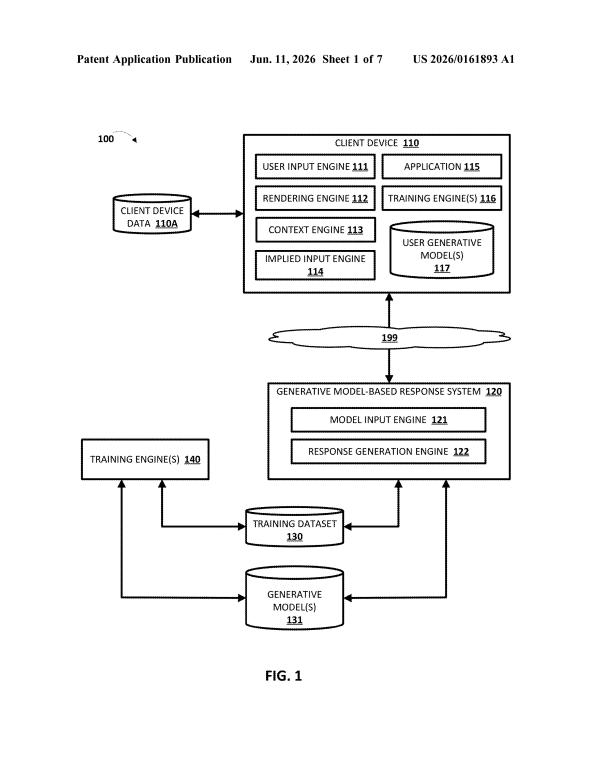
If it works, users get responses matched to what they actually need instead of generic answers. Microsoft's approach splits the job between one AI that interprets the problem and another that generates the reply.
Previous filings show companies routing tasks between specialist AIs; this one reveals how a single conversation can swap which AI is answering without the user detecting the handoff, letting companies patch weak spots without full retraining.
After routing tasks to specialist AIs, this filing shows how to split visual analysis itself: one model plans the reasoning strategy while another executes the detailed looking, letting each focus on what it does best.
After establishing how to route work between specialist models, this filing cuts the redundancy within handoffs: instead of each model rebuilding its understanding of a conversation from scratch, one model's extracted context passes directly to the next one.
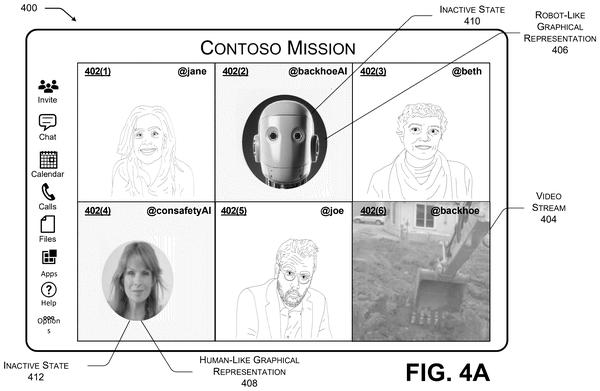
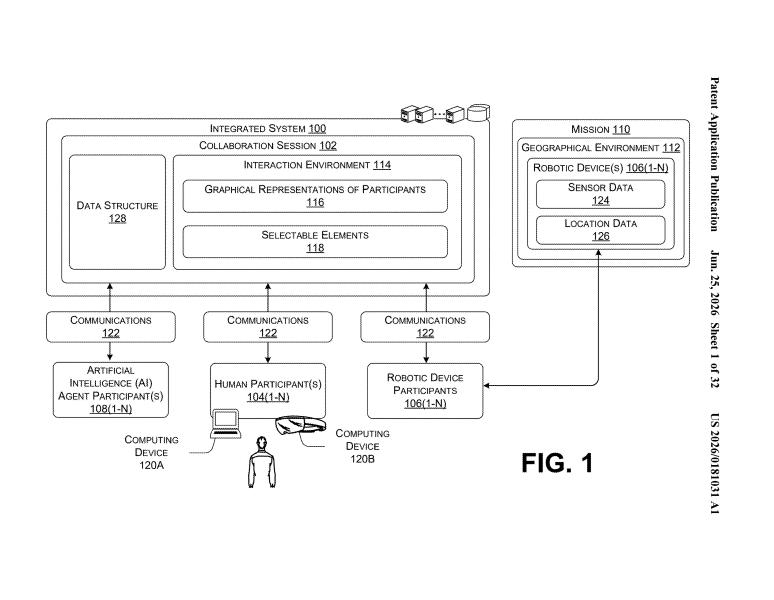
Users in mixed human-AI teams would see which AI is working on what task in real time, solving the opacity problem that arises when multiple specialists operate in the same workspace.
Letting users swap image engines mid-stream solves a routing problem that fixed pipelines can't: different vision models excel at different photo tasks, so locking into one wastes capability on the device.
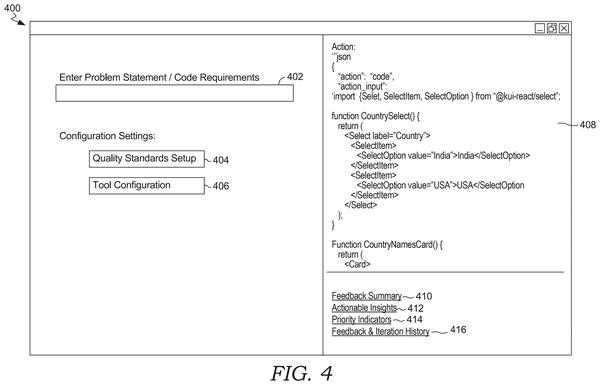
Users get working code without manual debugging if an AI can test its own output and iterate until tests pass, solving the verification problem within a single specialized agent.
Routing new tasks to existing specialist models instead of retraining a generalist cuts the data and compute needed to add capabilities. Confirms the bet that multi-agent systems beat single large models for efficiency.
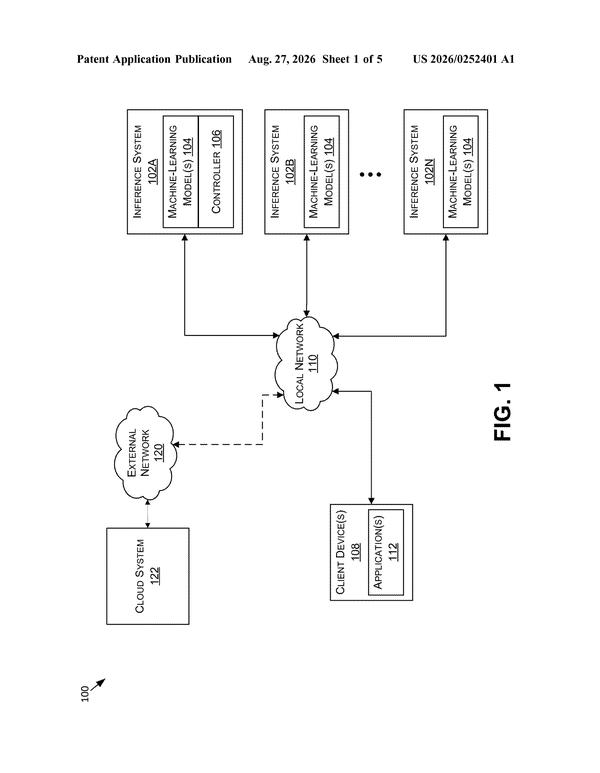
Deciding which local device handles an AI task based on capability and load. Nvidia's dispatcher lets home networks offload to idle hardware instead of running everything locally or routing to distant servers.
Detecting when parallel models reach different conclusions lets systems flag uncertain moments instead of storing continuous streams. This captures the routing problem at its source: deciding which cases need human review or escalation to a specialist model.
A verification loop where one AI model questions another's visual counts catches arithmetic errors before they reach users, solving a specific failure mode in image analysis that trips up even advanced systems.
The routing problem gets sharper: Samsung's system scores answers from multiple sources before committing to one, catching bad matches that single-path assistants would miss.
The routing problem gets a guard rail: IBM's patent lets a degraded team self-assess before answering, blocking silent failures when models drop offline.
Keeping AI error-checking local to the device instead of relying on network feedback loops. The proxy model catches mistakes on the phone's wireless chip itself, removing latency from the verification cycle.
Running multiple AI models on a device creates a bottleneck deciding which one to use when. Qualcomm's solution routes based on real-time signal conditions, moving the selection logic off the main processor to the wireless chip itself.
Routing through a fast screening model before deploying expensive compute avoids wasting resources on irrelevant suggestions when the stakes are high but the user's intent is unclear.
Semantic parsing errors in plain-English queries need detection before output. Adobe's system automatically identifies which command types an AI repeatedly misinterprets, enabling targeted fixes that prevent bad results from reaching users.
Catching design flaws before fabrication requires AI agents that can parse specialized code and spot errors humans might miss. Microsoft's system routes chip-programming tasks to specialized reviewers, automating the multi-day review cycle.
Users could hand off spec-writing to AI pairs that draft and validate each other, cutting the manual labor of hunting contradictions across thousands of pages of accumulated requirements.
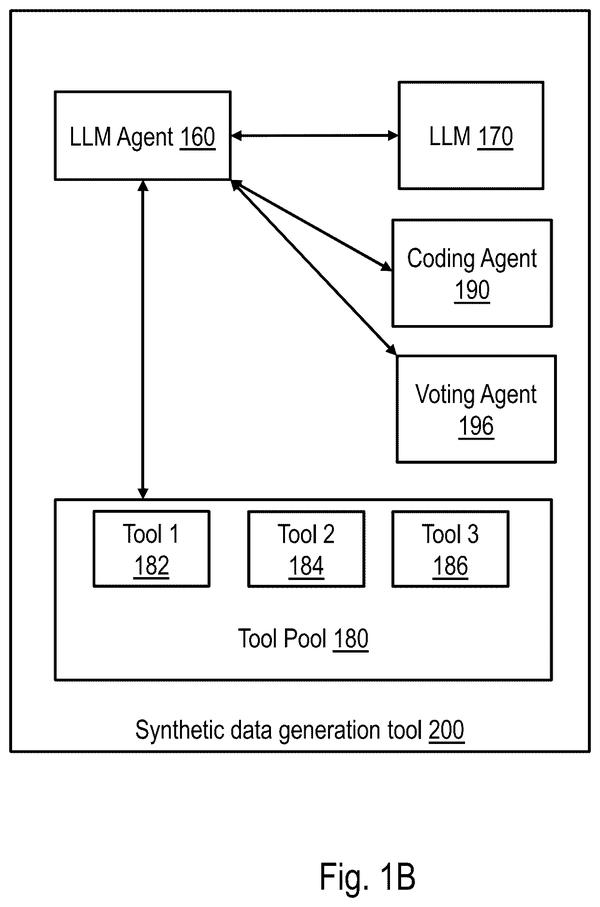
Generating synthetic training data requires custom code, and IBM's filing shows how one AI can produce multiple candidate generators while another ranks them by output quality, cutting the manual labor of writing and vetting data pipelines.
A broker system that spins up fresh agent instances on demand and tracks resource availability across servers, directly solving the coordination problem when dozens of specialists run simultaneously without colliding or competing for the same compute.
Inspecting the model's internal state rather than just parsing user requests lets the system route tasks with higher confidence, reducing mismatches between what users ask for and what skills the AI actually applies.
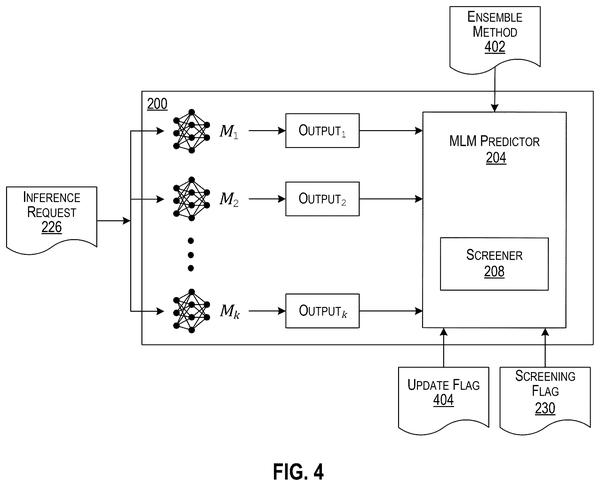
A secondary AI refines task prompts instead of retraining the primary model, cutting the computational cost of fixing mistakes by iterating on instructions rather than weights.
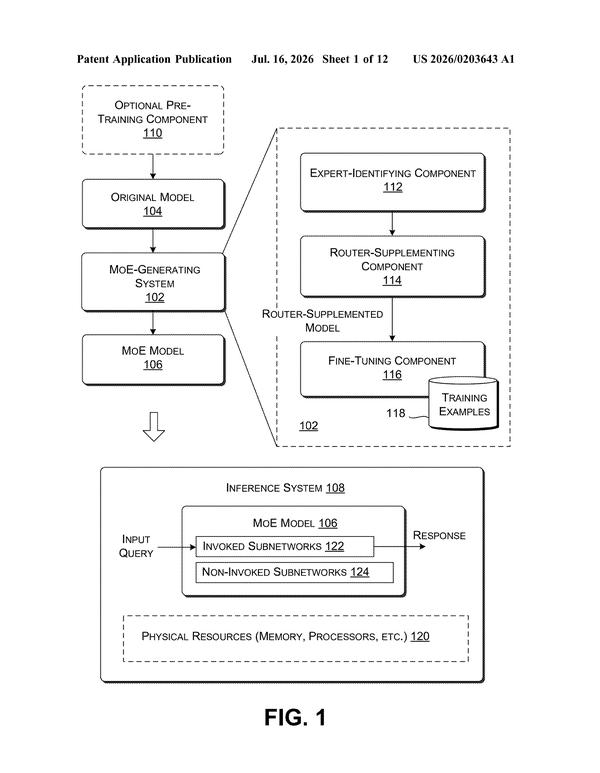
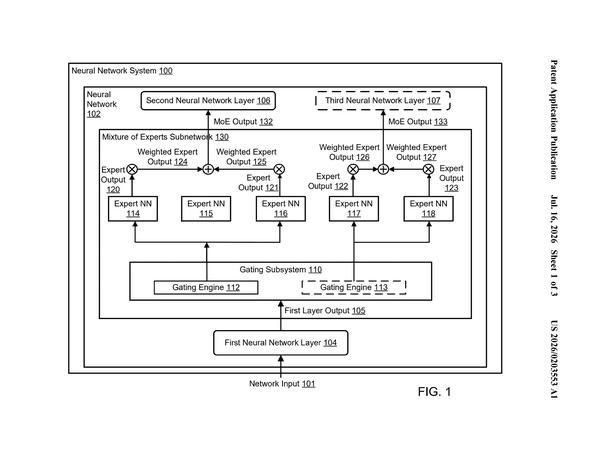
Sharing a common intermediate layer among specialist models reduces the parameter count that multi-expert systems must load and compute, lowering the overhead when routing tasks across the team.
Routing uncertain outputs to a verification model instead of running everything through the larger system cuts computation while keeping quality intact, solving the cost problem that's blocked team-based AI in production.
Running multiple specialist modules in parallel and weighting their outputs by input type offers a hardware-efficient alternative to swapping between separate models, letting inference happen simultaneously rather than sequentially.
When routing between specialist AIs, Samsung solves the friction problem: users can switch assistants in real time without leaving the conversation, using voice commands instead of manual settings changes.
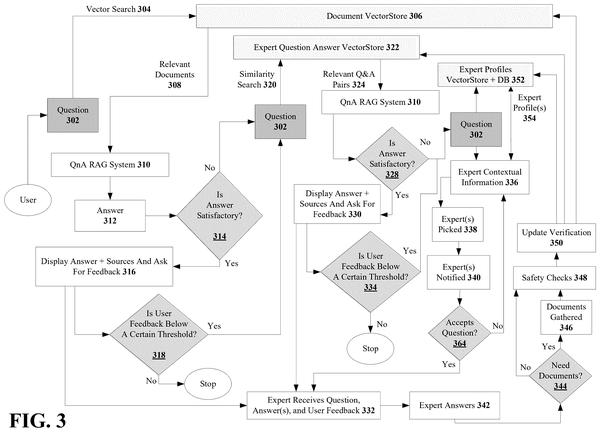
Routing uncertain queries to human experts rather than generating unreliable answers adds a feedback loop where the system learns from each escalation, strengthening the team's collective knowledge over time.
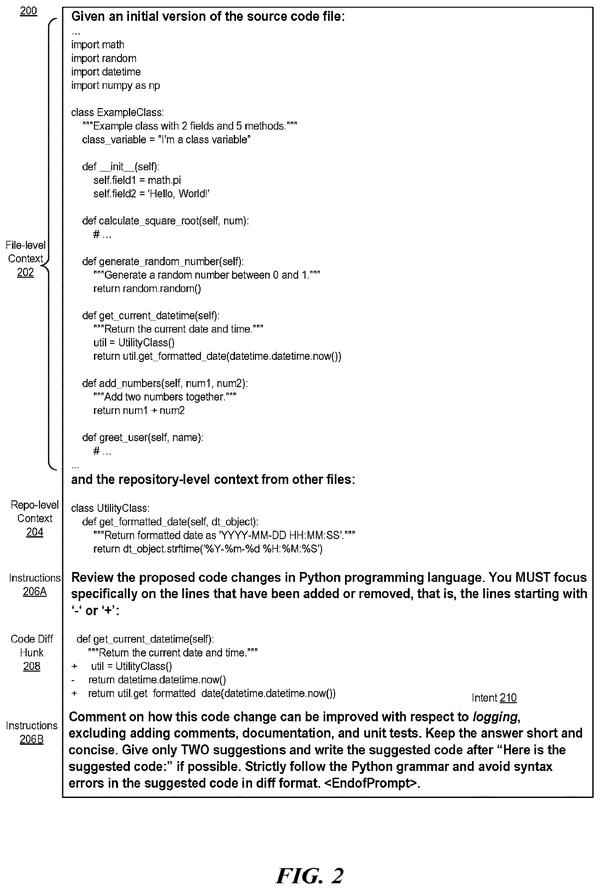
A separate AI evaluates whether test cases written by a code-generating AI actually expose bugs, adding a verification layer that catches when automated code-writers produce tests that look good but miss real failures.
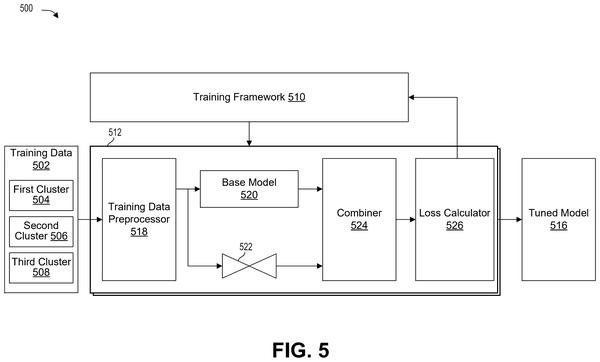
Within the team watchlist, this filing shows how to keep a primary model in place while adding a specialist downstream that learns which errors to expect from it specifically, rather than retraining the whole system or swapping in different models.
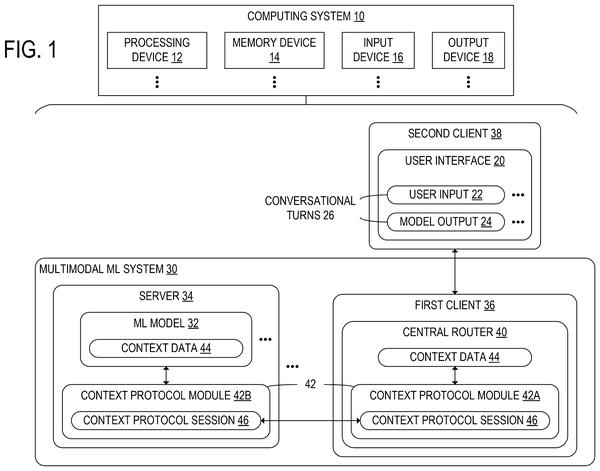
An intermediate AI layer converts each model's native representations into a shared format, eliminating the text conversion bottleneck that slows multi-AI workflows and degrades information fidelity.
Automatically ranking models on unfamiliar data sidesteps the need for human labeling when routing tasks to the right specialist, letting systems pick their own best performer instead of waiting for engineers to validate each option.
A second AI grades the first one's work against quality criteria and bounces failing responses back for revision, keeping errors from reaching users without requiring human review of every output.
Where the watchlist has focused on routing tasks upfront, this filing shows a system that routes mid-process: a lightweight model runs first, then checks its own confidence to decide whether to hand off to a specialist model before returning results.
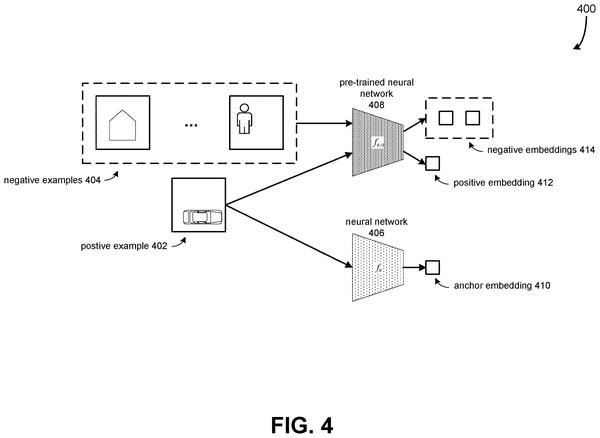
One AI model grades another's repeated attempts at the same question, creating paired examples of right and wrong answers that train the weaker model to recognize its own errors without human labeling.
Users could skip the handoff delays: one plain-English query routes to the right specialist AI automatically, pulling sensor data and prediction models together to answer maintenance questions without human intermediaries.
Splitting spatial reasoning between a language model and a specialized geometry agent lets teams handle queries that need both semantic understanding and precise coordinate math, a division that sidesteps trying to cram spatial logic into text-only systems.
Salesforce's filing has one AI agent watch and reshape another agent's output in real time, changing what gets said and how the next agent receives it.
IBM's filing swaps which AI models run in a car based on how the passenger is doing and on road conditions, cutting the computing needed at any moment.
Users get faster compliance checks when one AI reads regulations while another verifies systems actually meet them, rather than relying on manual legal review.
Users get faster answers when models skip dormant layers, cutting compute waste on routine queries. The filing confirms Big Tech is optimizing which internal components activate per request, not just which external specialist model to call.
Users get both a ranking and reasoning they can actually read. The filing shows how to split scoring from explanation so the justification doesn't just mirror the decision, it can point out what actually moved the needle.
Users get faster answers and lower costs when the system learns which specialist modules matter for each task, rather than running full computation every time.
Stopping hallucinations requires splitting the work: one model identifies what facts to retrieve, another generates answers from only those results, creating a hard checkpoint before output reaches users.
The routing problem needs memory: when specialist models hand off tasks, they currently lose what they learned. This filing adds a shared knowledge layer so downstream agents don't duplicate work or contradict earlier decisions.
Controlling what data flows between specialist agents in a multi-agent system prevents one poorly designed or compromised agent from leaking sensitive information to another that shouldn't access it.
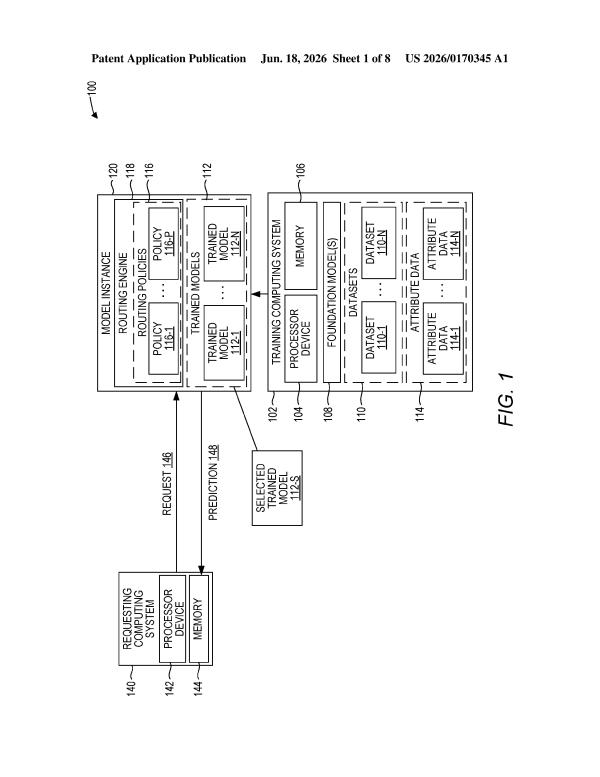
The routing layer needed a gatekeeper that doesn't just split traffic but learns which model handles which question type better over time. Nvidia's filing shows how to build that learned routing rather than relying on fixed rules.
A cheaper filter screens video frames before routing them to the main model, cutting processing load when one specialist AI alone would waste capacity on irrelevant content.
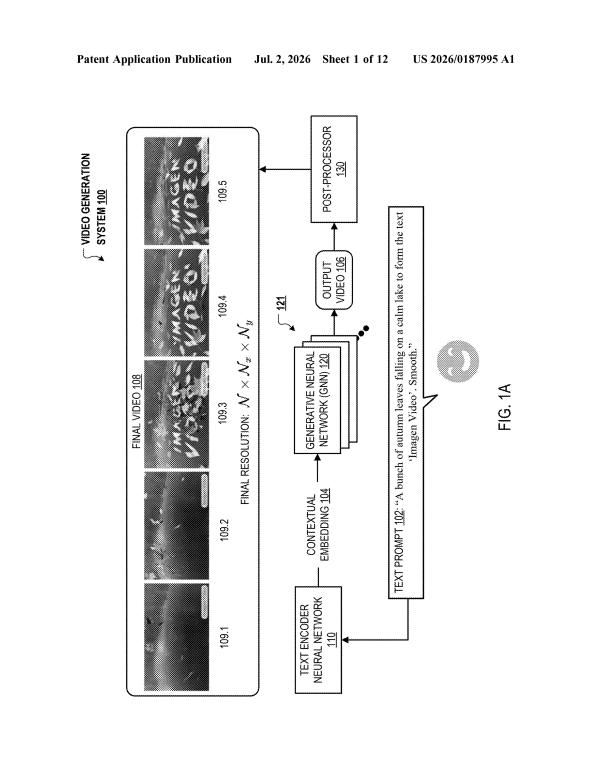
A cascading sequence of specialized models, each refining the previous output, confirms the watchlist's assumption that video quality improves when tasks flow through separate AI stages rather than a single model handling everything at once.
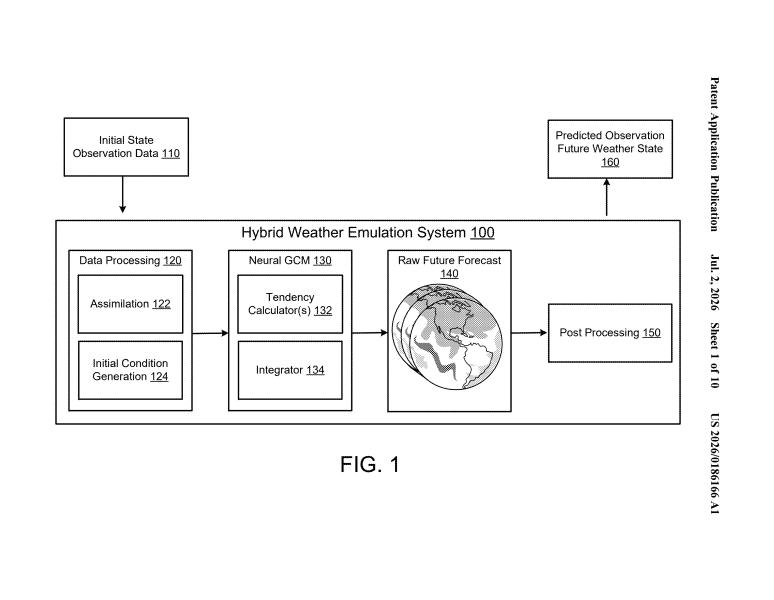
Running physics equations and neural networks in parallel lets each method correct the other's blind spots, physics catches when AI extrapolates beyond its training data, while AI accelerates calculations that would otherwise consume too much compute.
Sequential handoff between specialist models shows how to keep output quality high when each AI handles one piece of a workflow, from selection through presentation.
A routing layer that tracks which agent has handled prior interactions with each customer, ensuring continuity instead of forcing each incoming message through a generic assignment process.
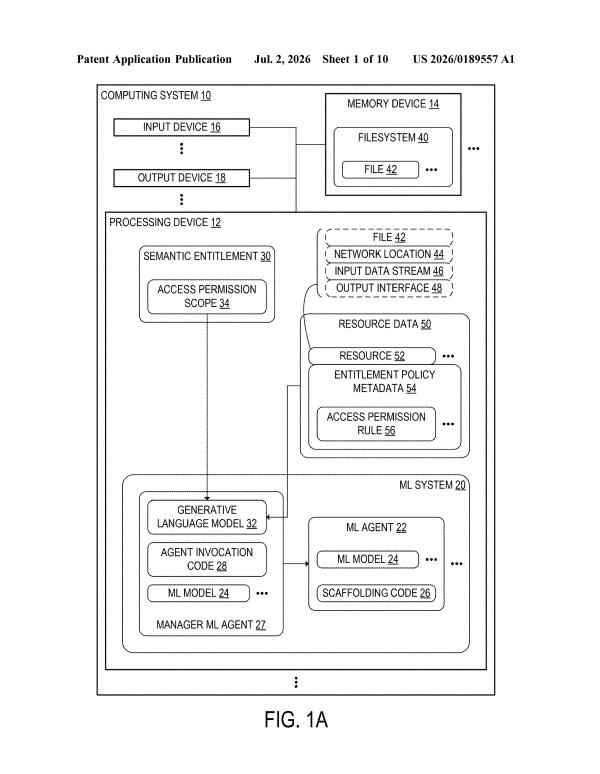
Multi-agent systems need ways to specify which model can access what data. Using natural language rules instead of code makes permission-setting faster and reduces bottlenecks when orchestrating specialist agents.
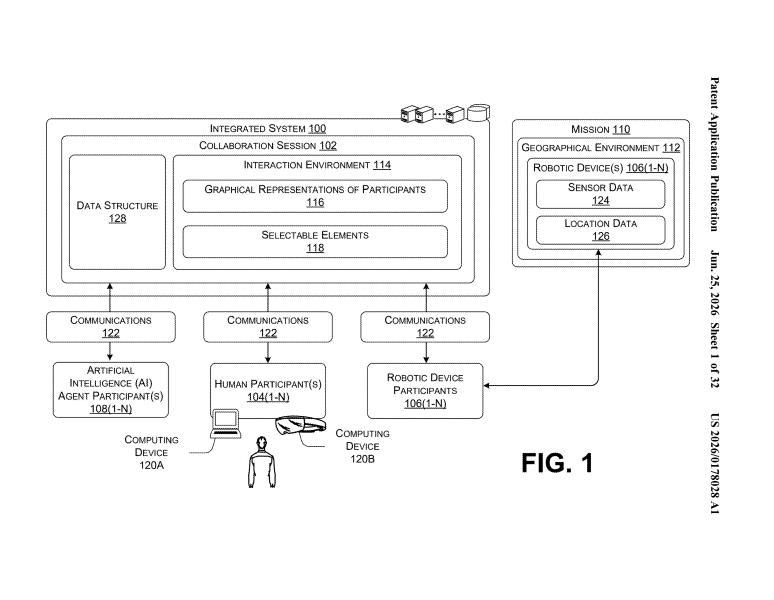
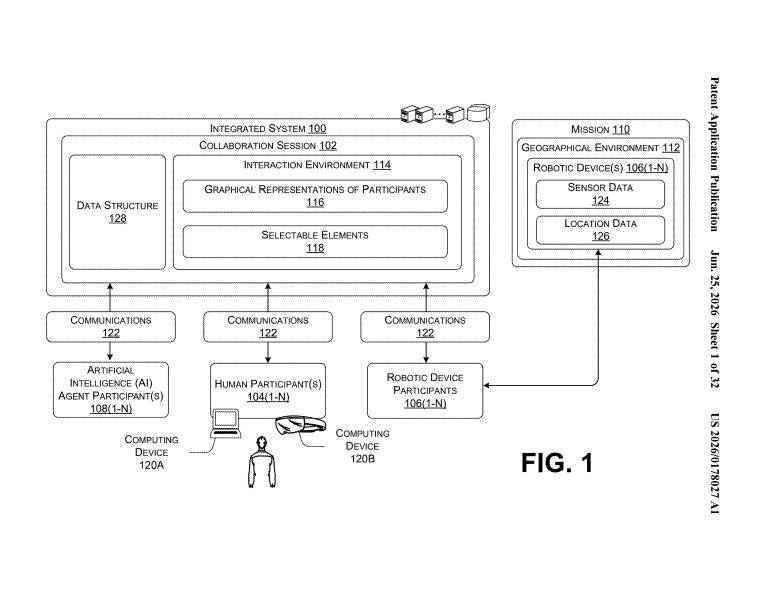
Coordinating across human-robot-AI teams requires merging separate perception streams into one shared workspace where all participants see the same operational picture.
Routing robot control through a shared workspace means teams can hand off between automation and human operation without losing sight of what others are doing.
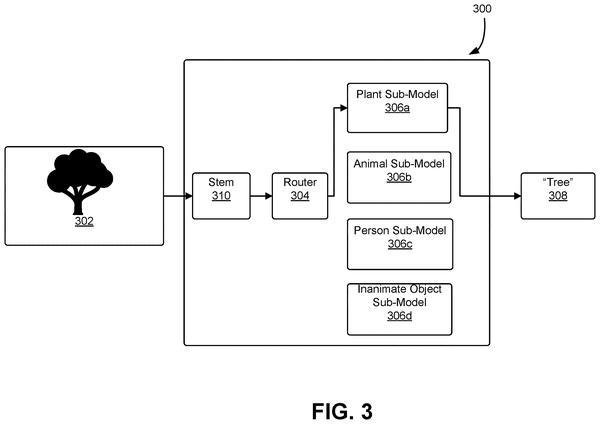
Routing incoming queries to the right specialist model based on content analysis, rather than random assignment or sequential processing, solves the selection problem that emerges when teams of models replace single monolithic systems.
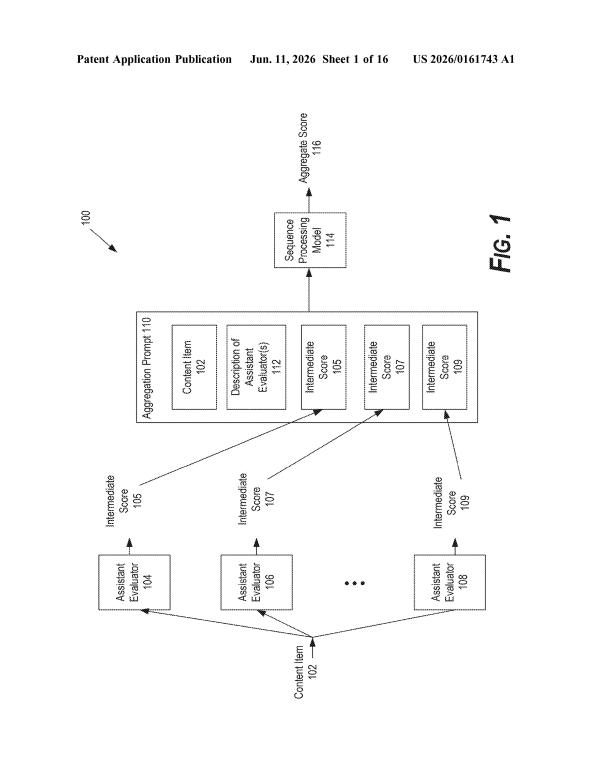
Validating AI outputs requires specialist judges rather than one generalist model, with a master evaluator weighing their separate verdicts on grammar, accuracy, and tone before approval.
A coordinator layer that routes to specialists based on question content could cut down on hallucination by keeping each model within its trained domain rather than forcing generalists to improvise across fields.
The routing challenge shifts here: instead of sending tasks to specialist models upfront, the system lets a generalist model draft first, then routes only the problematic sections to editors. This inverts the usual workflow.
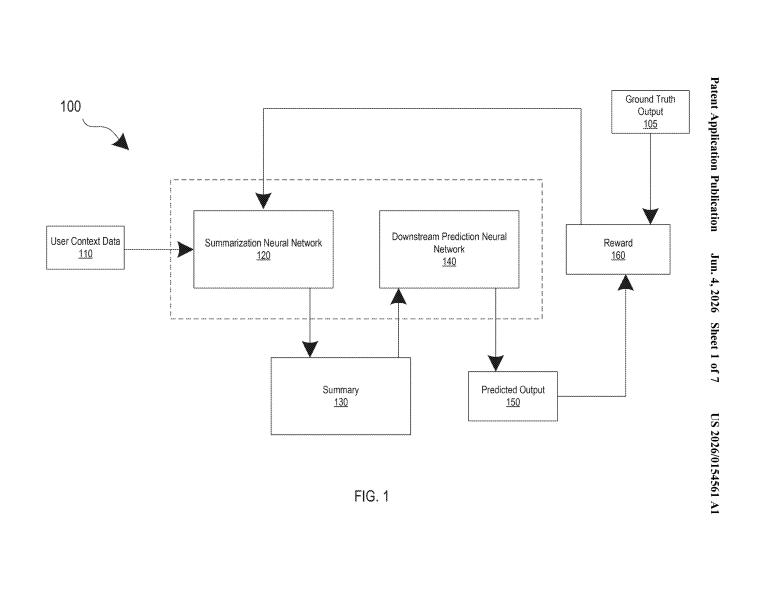
The routing problem gets sharper: which specialist model should handle summarization depends not on summary quality alone, but on whether that summary actually serves the next model's task.
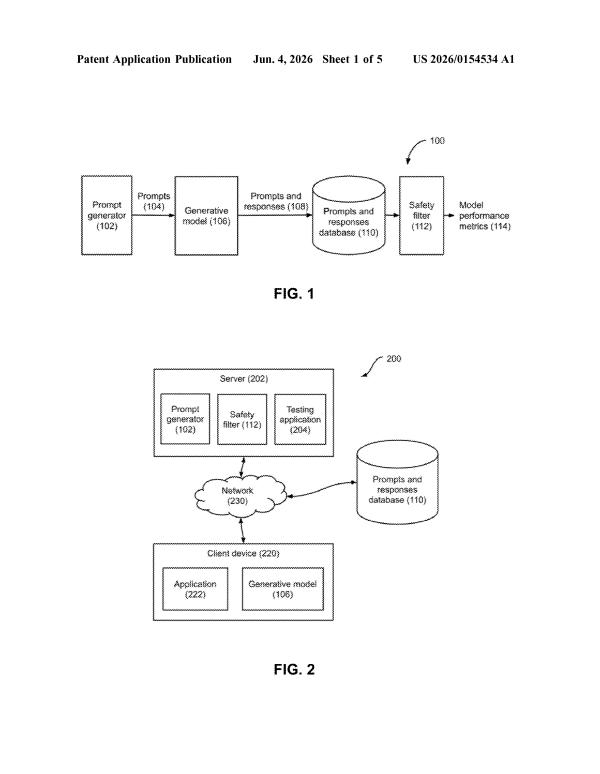
Scaling safety validation across modalities requires automated grading that doesn't depend on human raters for every test run. Google's pipeline grades thousands of multimodal responses against policy rules at once.
A feedback loop that catches hallucinations mid-generation lets the model revise its own output before output occurs, shifting from detection-after-the-fact to real-time correction within a single AI's reasoning chain.
The routing problem shifts from upfront model selection to mid-stream handoffs: detecting when a partial response signals the need for a different model before generation completes.
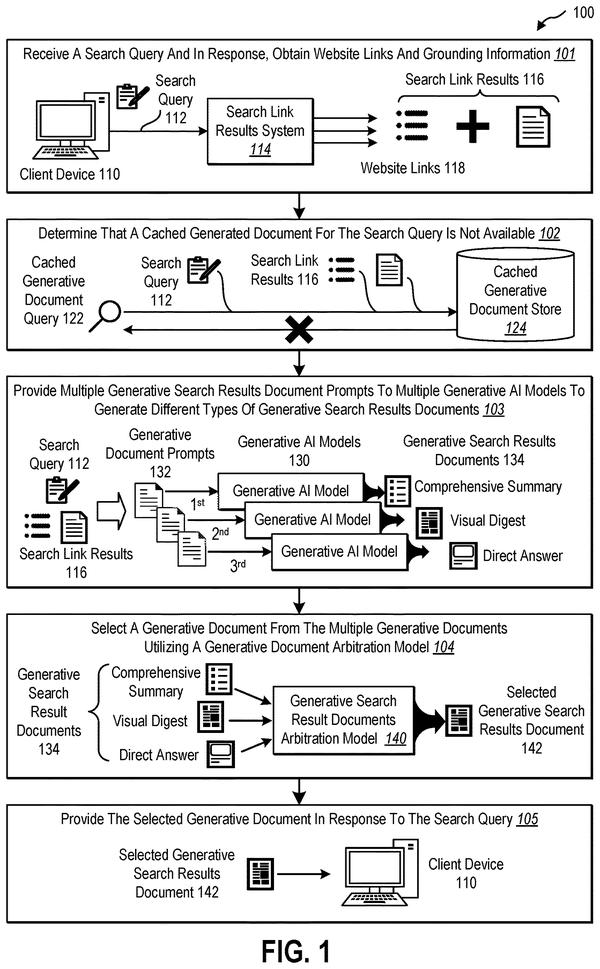
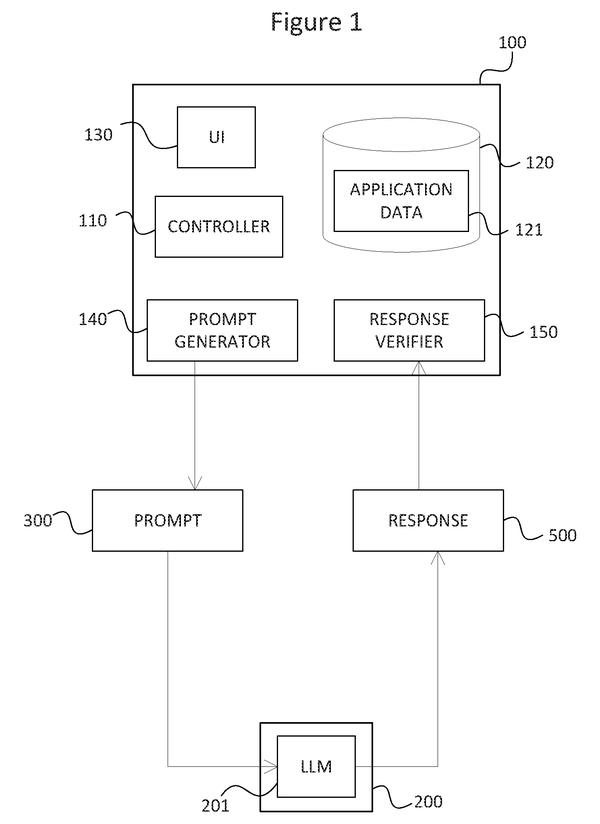
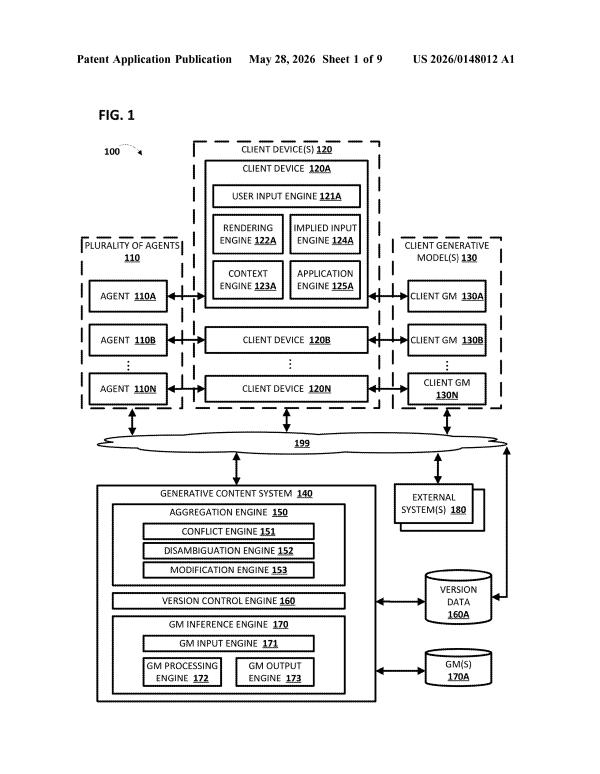
When multiple agents generate conflicting instructions for the same model, Google's system arbitrates by synthesizing them into a single unified prompt rather than letting contradictions reach the model.
Multiplying specialist models becomes practical when they stop each demanding their own copy of the base layer. IBM's approach pools that shared foundation, cutting the memory cost of running a whole team of fine-tuned variants.
Tool disambiguation in multi-agent systems: IBM's approach auto-detects when similar tools confuse routing decisions and reorganizes tool metadata to prevent mismatches, sidestepping manual descriptor rewrites.
Sequencing specialist models in order rather than running them in parallel sidesteps conflicts by letting each model work from the previous model's output.
Pooling shared neural network layers across multiple expert models cuts the memory footprint, making simultaneous specialist routing practical on single-GPU systems instead of requiring distributed clusters.
Questions readers ask
What problem are these AI patents trying to solve?
These filings focus on getting several AI models to work as a team instead of relying on one model for everything. That means routing questions to the right specialist, merging instructions when models disagree, and catching an AI's mistakes before a user sees them. Like all patents, they describe research directions, not confirmed products.
Which companies are filing these patents?
The watchlist currently includes filings from Google, IBM, and Microsoft, each approaching the same problem from a different angle. IBM's filings tend to focus on routing and shared infrastructure for running multiple models efficiently, while Google's cover routing, merging conflicting outputs, and testing AI behavior. Microsoft's filing looks at diagnosing failures inside chains of AI agents.
Does a patent mean this AI teamwork feature is shipping soon?
No. A patent filing shows a company has worked out a technical approach and wants to protect it, not that the feature is built, tested, or scheduled for release. Some ideas here, like routing tasks to specialist models or catching false answers automatically, may show up in products later, but the filings alone don't confirm timing.
Why are multiple companies patenting similar AI routing ideas at the same time?
When several companies file on similar problems around the same time, it usually means the industry has hit a shared bottleneck. Here, running one enormous model for every task is expensive and error-prone, so IBM, Google, and Microsoft are each patenting ways to split work across smaller, specialized models and catch mistakes along the way.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.