
Nvidia Patents a System That Tests Whether Its Own AI Search Is Giving Good Answers
Most AI search tools have no built-in way to check whether they're actually finding the right things. Nvidia has filed a patent for a system that configures, runs, and then grades its own AI-powered search pipeline automatically.
What Nvidia's self-evaluating AI search pipeline actually does
An AI assistant stares at a pile of company documents, trying to answer your question. The problem is: you have no good way to know if it found the right paragraphs before writing its reply.
Nvidia's patent describes a system for building and testing exactly this kind of setup, called a retrieval-augmented generation (RAG) pipeline. That's a technical phrase for an AI that looks things up before it answers, like a student who checks their notes during an open-book exam. The system lets engineers define the pipeline in a configuration file, feed it a set of documents and test questions, and then automatically measure how well it retrieved the right information.
The result is a performance score that tells developers whether the AI is actually finding useful content or just returning loosely related noise. Instead of guessing whether the pipeline works, you get a number.
… retrieve, from a vector database, at least one candidate content from the plurality of embeddings based at least on a similarity metric between the at least one candidate content and the at least one query; determine a performance metric based at least on the retrieved at least one candidate content; …
Translation: It searches a vector database to find matching content and measures how well the results answered the search query.
How the pipeline scores its own retrieved content
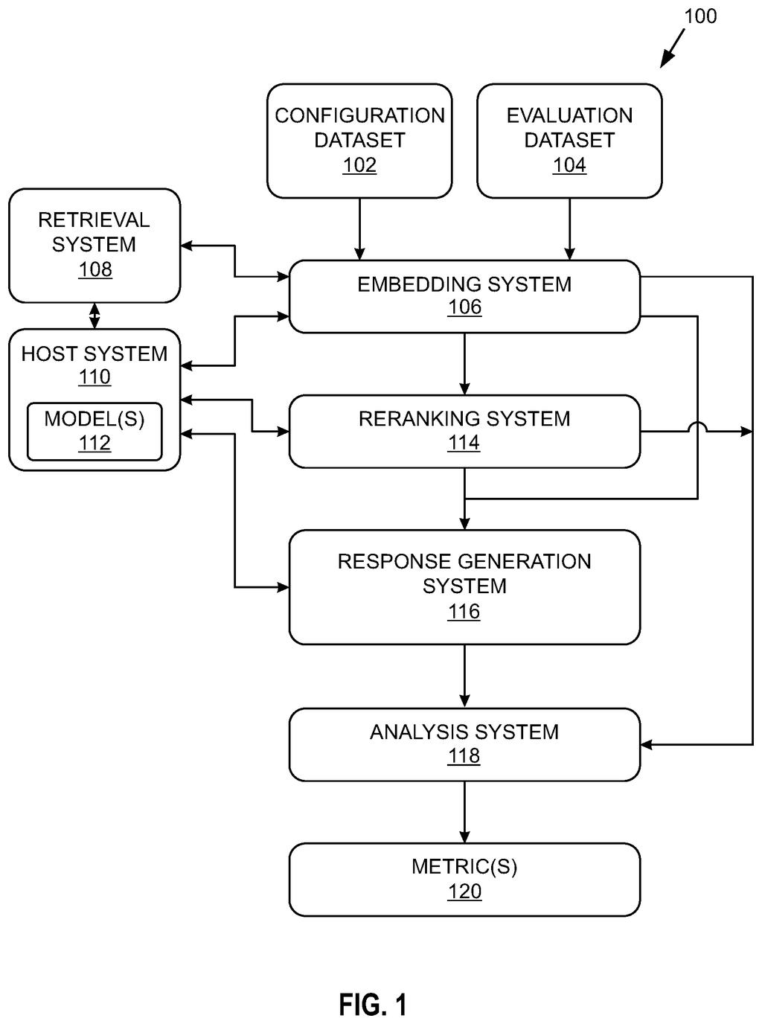
The system takes in two inputs: a configuration dataset (a file that describes how the pipeline is set up, which AI models to use, how many results to pull back) and an evaluation dataset (a collection of documents paired with test queries that have known good answers).
Using an AI model, it converts the documents into vector embeddings (mathematical representations that capture meaning, so that "car" and "automobile" end up close together in the math). Those embeddings get stored in a vector database, a purpose-built store for that kind of high-dimensional data.
When a query comes in, the system converts it into its own embedding and searches the database for content that scores high on a similarity metric (essentially: which stored passages are mathematically closest to the question). It retrieves the best candidates.
- The system then computes a performance metric based on what it retrieved, comparing those results against the known-good answers in the evaluation set.
- That metric gets returned as output, giving developers a concrete, repeatable measure of pipeline quality.
- The modular configuration approach means different AI models, chunking strategies, or retrieval settings can be swapped in and compared systematically.
Various examples, systems, and methods relate to configuring, executing, and evaluating retrieval-augmented generation (RAG) pipelines. A system can process a configuration dataset defining a pipeline and an evaluation dataset containing content and queries.
Translation: The technology focuses on setting up and testing AI search systems that combine database retrieval with text generation.
What this means for AI tools built on document search
RAG pipelines are everywhere right now: they power enterprise chatbots, internal document search tools, customer support assistants, and coding helpers that consult codebases. The hard part has always been knowing whether the retrieval step is actually working. Getting a fluent-sounding answer from an AI does not tell you whether it found the right source material first.
By making evaluation a built-in, configurable part of the pipeline rather than an afterthought, this system gives teams a repeatable way to compare setups. For anyone building or buying an AI tool that searches documents, a growing pile of Nvidia RAG-related filings suggests the company is working to own the infrastructure layer, not just the models on top.
Nvidia's eighth filing we've tracked since July in the AI guardrails race adds to a pattern that includes one on trusting expert authors and one on diagnosing AI app decline.
Claim 1 covers any system that reads a configuration file, runs content through an AI model to create searchable representations, pulls matching results from a database, and then scores how well the retrieval performed. That description fits a remarkably wide range of tools already in everyday use for building and testing AI search systems.
The breadth matters because whoever holds this claim would have a say over the basic feedback loop that engineers use to tune AI search quality. Every time a team adjusts their system and checks whether the results got better, they are doing exactly what Claim 1 describes.
The underlying bet is that controlling the measurement and configuration layer around AI search is as valuable as the search itself. That is a reasonable bet, and this patent is Nvidia's attempt to own that position.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
8 drawing sheets from US 2026/0277972 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in