IBM
IBM · AI / ML · Filed Feb 11, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
IBM's New Patent Targets Inaccurate AI Answers When Reading Technical Documents
IBM has a patent for a system that tests your documents before an AI ever reads them, scoring whether they're likely to cause the AI to hallucinate, then telling you how to fix them.
- Publication number
- US 2026/0236462 A1(US20260236462A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Feb 11, 2025 · Aug 13, 2026
- Inventors
- Mr. Colton Jarrett COX, Ms. Arielle Micaela GOLDBERG, Mr. Justin Paul LARGO, Mr. Jeffrey BISTI
- Status when we published
- Company responded; back with the examiner
- Document
- 20 claims
- US classification
- 707/767
- Examiner
- DAUD, ABDULLAH AHMED (Art Unit 2164)
What IBM's document 'searchability score' actually does
A technical manual sits in a company's document system, written for humans who already know the context. Then an AI gets handed that same document and asked to answer questions about it.
The problem is that AI models don't read the way people do. They break documents into chunks and search for relevant pieces, and content written for human readers often gets scrambled in that process. The AI ends up missing key information or, worse, inventing answers that sound plausible but are wrong.
IBM's patent describes a system that checks your documents before they go into an AI. It gives each document a "searchability score" based on whether an AI could realistically use it to answer questions correctly, and it tells you specifically how to rewrite the parts that would cause trouble.
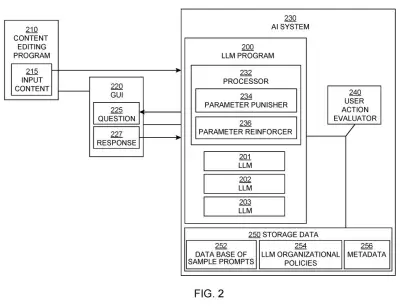
predicting, using a first LLM, a question which the input content may be used to answer in the future; generating, using a second LLM, an answer to the question based on the input content; and generating, using a third LLM, the search-ability score based on the answer …
Translation: The system uses three different AI models to test if a document can reliably answer future questions.
How three AI models team up to score and fix your content
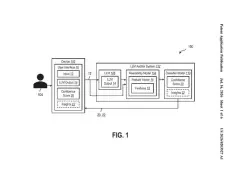
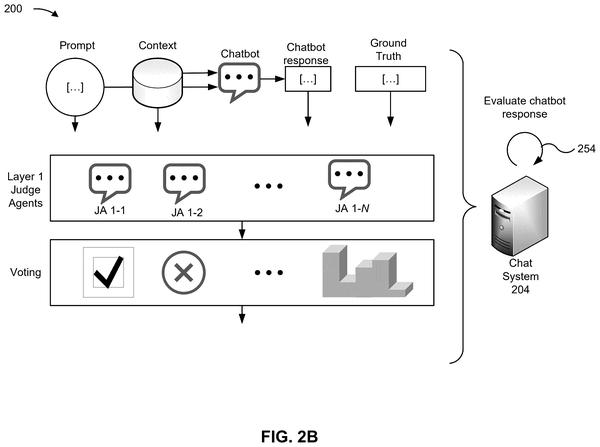
The system described in the patent uses three separate AI language models working in sequence, each playing a distinct role.
- Model one (the question predictor): reads your document and predicts what questions a user might ask that this document should be able to answer.
- Model two (the answer generator): tries to answer those predicted questions using only the content in your document.
- Model three (the scorer): compares the answers against the source material and produces a searchability score, a number that reflects how reliably the document will serve an AI model in practice.
If the score is low, the system generates a specific suggestion telling the author how to rephrase or restructure the content. The goal is to make documents work the way RAG-based systems (Retrieval-Augmented Generation, meaning AI that pulls from a document library rather than relying purely on its training data) expect them to.
The approach catches a real structural problem. Technical documents are written for domain experts who already hold a lot of context in their heads. AI models have no such background and can fail badly when a document assumes too much.
Certain types of documents, such as technical documents, are not inherently structured to meet the criteria of a predefined chunking strategy of various LLM models. Due to this, model accuracy can be negatively impacted, increasing the likelihood of hallucinations …
Translation: Technical documents are often formatted in ways that confuse AI, which causes the software to make up incorrect information.
What this means for companies feeding AI their own documents
For any company that has fed its internal documents, manuals, or knowledge bases into an AI assistant, this describes the source of a lot of frustrating wrong answers. The AI isn't broken; the documents just weren't written for it. IBM's approach puts a quality-control step between human-authored content and the AI that will eventually read it, which is a more targeted fix than retraining the model or rewriting every document from scratch.
The practical cost is real: running three AI models in sequence to score a single document is computationally expensive, and the system's own accuracy depends on whether those models are themselves reliable enough to simulate the question-and-answer loop correctly. That's a meaningful tradeoff. Still, for enterprises where a hallucinating AI assistant causes legal or safety problems, the overhead is likely worth it. IBM's AI-document pipeline work fits squarely in the wave of new Big Tech patents aimed at making enterprise AI more trustworthy before it ever touches a user's question.
Source: US 2026/0236462 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 5 sheets
5 drawing sheets from US 2026/0236462 A1 · click any drawing to enlarge