
Nvidia Files Patent for Robot Vision That Redraws an Object Until It Matches the Camera
Instead of training an AI to judge how an object is sitting, Nvidia's patent has the computer redraw a digital copy of it, again and again, until the copy lines up with what the cameras see. It also runs several attempts at once and keeps the winner.
What Nvidia's redraw-until-it-matches patent does
Every time a robot arm reaches for a part on a table, it has to know exactly how that part is sitting: how far away it is, which way it's tilted, whether it's turned around. Get that slightly wrong and the grip misses.
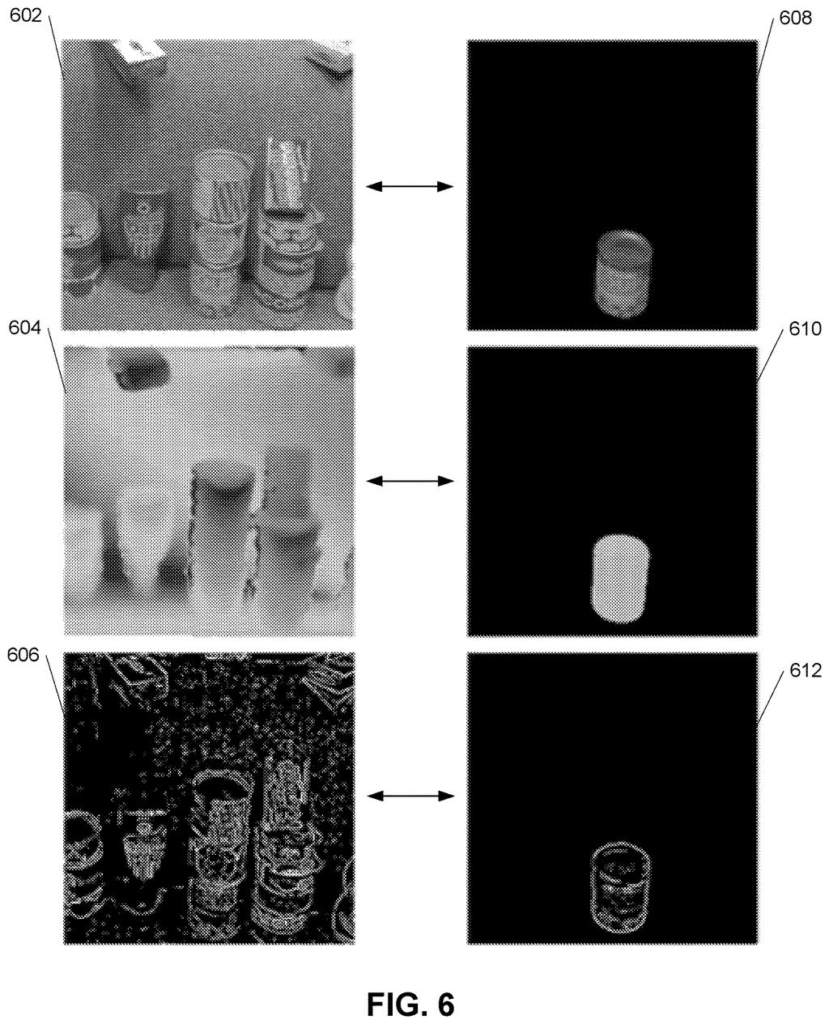
Nvidia's patent describes a try-and-compare approach. The computer starts with a rough guess, draws a digital copy of the object in that position, and checks it against what the sensors actually captured. It doesn't just compare color photos. It also compares depth, outlines, and other views of the same scene. If the drawing doesn't match, the system nudges the guess and tries again.
To avoid getting stuck on a wrong answer, it runs a batch of these attempts at the same time, each with slightly different settings, and keeps whichever one lands closest to reality.
… performing one or more first iterative optimization operations to determine a first 3D representation of an object based at least on comparisons of a plurality of differentiable renderings of the object …
Translation: The system repeatedly updates its 3D model by comparing computer graphics to real camera data until they match.
How Nvidia's system tunes the guess, step by step
The system takes sensor data in several modalities (different kinds of images of the same scene, such as a color photo, a depth map, an edge map, a surface-direction map, or a silhouette mask) plus a 3D model of the object. A first stage spots the object and makes a rough guess at its position and rotation.
Then a refinement stage takes over. It uses a differentiable renderer (a drawing engine that can report which way to adjust the object to make the drawing look more like the real image). Each round, it draws the 3D model in every modality, compares each drawing to the matching sensor image, and adds up the differences into one score called the loss. It then uses gradient descent (repeated small steps in whatever direction lowers the score) to update the pose.
To avoid settling on a wrong answer, the filing describes:
- Running many attempts in parallel, each starting with a different randomly chosen step size (the "learning rate") or a slightly shifted starting pose.
- Shrinking the step size over time so the answer settles instead of wobbling.
- Picking the attempt with the lowest final error.
The claims also cover using the same loop to refine an object's shape, texture, or material properties, not only its pose. In one example, the filing shows the result landing closer to the true pose than MegaPose, an earlier method that relies on a trained neural network.
… performing one or more iterative operations to determine a pose of an object based on one or more comparisons of (i) one or more renderings of a three-dimensional (3D) representation of the object in the first modality with the first sensor data …
Translation: It figures out where an object is by matching virtual pictures against multiple types of real sensor readings.
What this means for robots and AR headsets
The practical payoff is a machine that is less likely to misjudge where something is. The filing says it targets cluttered scenes, partly hidden objects, and plain or symmetric objects, which are the cases where a part can look nearly the same from several angles. The text names robot manipulation, augmented and mixed reality, and autonomous navigation as uses.
The filing also says the scoring recipe can be tuned for a specific scene without training or retraining a neural network. For a factory or warehouse that swaps in new parts often, that could mean less setup work. You'd notice it indirectly: a robot that fumbles less, or a virtual object that stays pinned to a real surface instead of drifting.
Nvidia's 35th filing we've tracked on our robot grasping and movement watchlist since May builds on faster robot training and warehouse item placement.
Most people would feel this technology rather than see it: a robot that picks up a plain, featureless part without fumbling it, or a virtual object that stays anchored to your real desk instead of drifting. Those are the exact failures this work is aimed at preventing.
The core approach is a guess-and-check loop, repeated until a simulated picture of an object matches what the camera actually sees. Running many guesses at once and keeping the best one helps avoid the trap of a confident wrong answer.
The open question is speed. Redrawing an object repeatedly, many times per second, is expensive work, and this filing says nothing about how fast it runs. If it cannot keep up with live use, the benefit stays in the lab and never reaches the product.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
9 drawing sheets from US 2026/0311365 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in