
AMD Files Patent for a Switch That Helps Serve Custom AI Models Faster
The chips that run AI chatbots spend a surprising amount of time waiting for data instead of crunching numbers. AMD's patent application hands part of the job to the humble switch that connects those chips.
What AMD's chip switch does for custom AI
Ever wondered how one giant AI model can act like a hundred different assistants, one for a law firm, one for a hospital, one for you? The trick is that each customer gets a small add-on, called an adapter, that tweaks the big model instead of replacing it.
The catch is where to keep all those add-ons. The AI chips (GPUs) have only a little fast memory, so the adapters sit with a separate main processor and get shipped over a busy data link whenever they're needed. That link gets jammed.
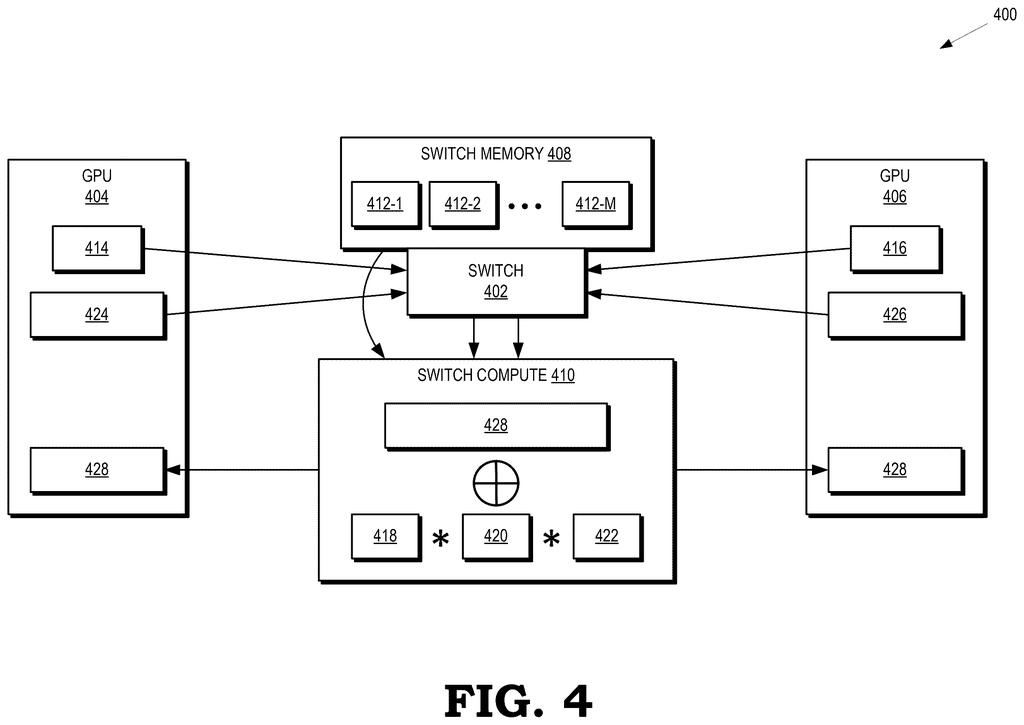
AMD's patent application moves them somewhere new: the switch that connects the chips. Normally a switch just passes data along. Here it gets its own memory and some math power, holds the add-ons, and does their share of the work while the chips handle the big model. Then it merges the two results and sends the answer back to the chips.
… a switch configured to receive a copy of each portion of the input matrix and each portion of the first matrix from the plurality of parallel processors, perform matrix multiplications of a subset of a plurality of adapter matrices and the portions of the input matrix to form a second matrix …
Translation: A dedicated switch handles custom model math separately to speed up processing.
How the switch adds the custom layer to the answer
The filing builds on low-rank adaptation (LoRA, a way to fine-tune a big model by training two tiny matrices, called A and B, instead of the whole thing). The big model's weights sit in a base matrix, split into shards (slices) across several GPUs (graphics chips used for AI).
In the claimed setup, three things happen:
- Each GPU multiplies its slice of the base matrix by the input, then sends the result, plus a copy of its input slice, to the switch.
- The switch, which stores the adapter matrices in its own memory, multiplies them against the input to produce a second matrix.
- The switch adds the two results together and sends copies of the final matrix back to every GPU.
The GPUs and the switch can do their multiplications at the same time. If the switch is short on memory or math power, the filing describes a split: the switch handles only the second adapter matrix (B), and the GPUs multiply the input by the first (A) and pass that result along. The description says this fallback applies when the switch can't finish in time.
The filing's own comparison shows far less data moving around than in the setup where a main processor feeds adapters to the GPUs. The same arrangement is described for both training and answering questions.
The switch includes memory and processing resources such as one or more compute units.
Translation: The hardware component has its own built-in memory and computing power.
What a switch with its own memory means for AI
If you use a chatbot tuned for a specific company, an app, or even your own writing, someone has to store and run that tuning. Today the number of tuned versions a data center can serve is limited by memory on the chips and by the data link feeding them. Moving the tuning into the switch could mean more custom versions per machine and fewer traffic jams, which could make these services cheaper and faster for the businesses that rent them.
For AMD, the interesting part is that the network gear between chips becomes a place to do useful work instead of a plain pipe. It's a filing about hardware inside data centers, so you'd never see it directly. Whether it turns into a real product is unknown.
AMD's 48th filing we've tracked since May in the AI chip wars continues a push toward memory efficiency, following work on running AI on less memory and chips sharing memory side by side.
Serving many custom versions of one AI model is an expensive headache. Fast chip memory is scarce, and every time a tuned version gets fetched from elsewhere, a busy data link slows everything down. At the scale of a big cloud service, small delays multiply into real money.
The fix matches the size of that problem well. Tuning add-ons are tiny compared with the main model, so storing them in the switch and letting it do their share of the math sends far less data around. The filing's own numbers show total data movement dropping sharply.
The limit is the hardware itself. It needs a switch with memory and math power, a different part from the plain switches the filing says are common today. Whether that matters beyond AMD's own data-center gear depends on adoption, and a patent application can't tell us that.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
5 drawing sheets from US 2026/0329964 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in