
AMD
AMD · AI / ML · Filed Dec 19, 2024 · USPTO published Jun 25, 2026 · Jun 25 release
AMD Patent Stores AI Model Data Efficiently to Speed Up Processing
Running a large AI model means constantly shuffling enormous amounts of data between storage, memory, and the chip doing the actual work. AMD's new patent describes a way to let the AI chip handle that data pipeline itself, skipping the CPU entirely.
- Publication number
- US 2026/0178964 A1(US20260178964A1)
- Applicant
- Advanced Micro Devices, Inc.
- Filed · Published
- Dec 19, 2024 · Jun 25, 2026
- Inventors
- Hisham Chowdhury
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/12
How AMD wants to feed AI chips without the CPU bottleneck
Imagine you're cooking a huge meal, but every time you need a new ingredient, you have to ask a single assistant to walk to the pantry, get it, and bring it to you. That assistant becomes the bottleneck. AMD's patent is the equivalent of giving the chef direct access to the pantry.
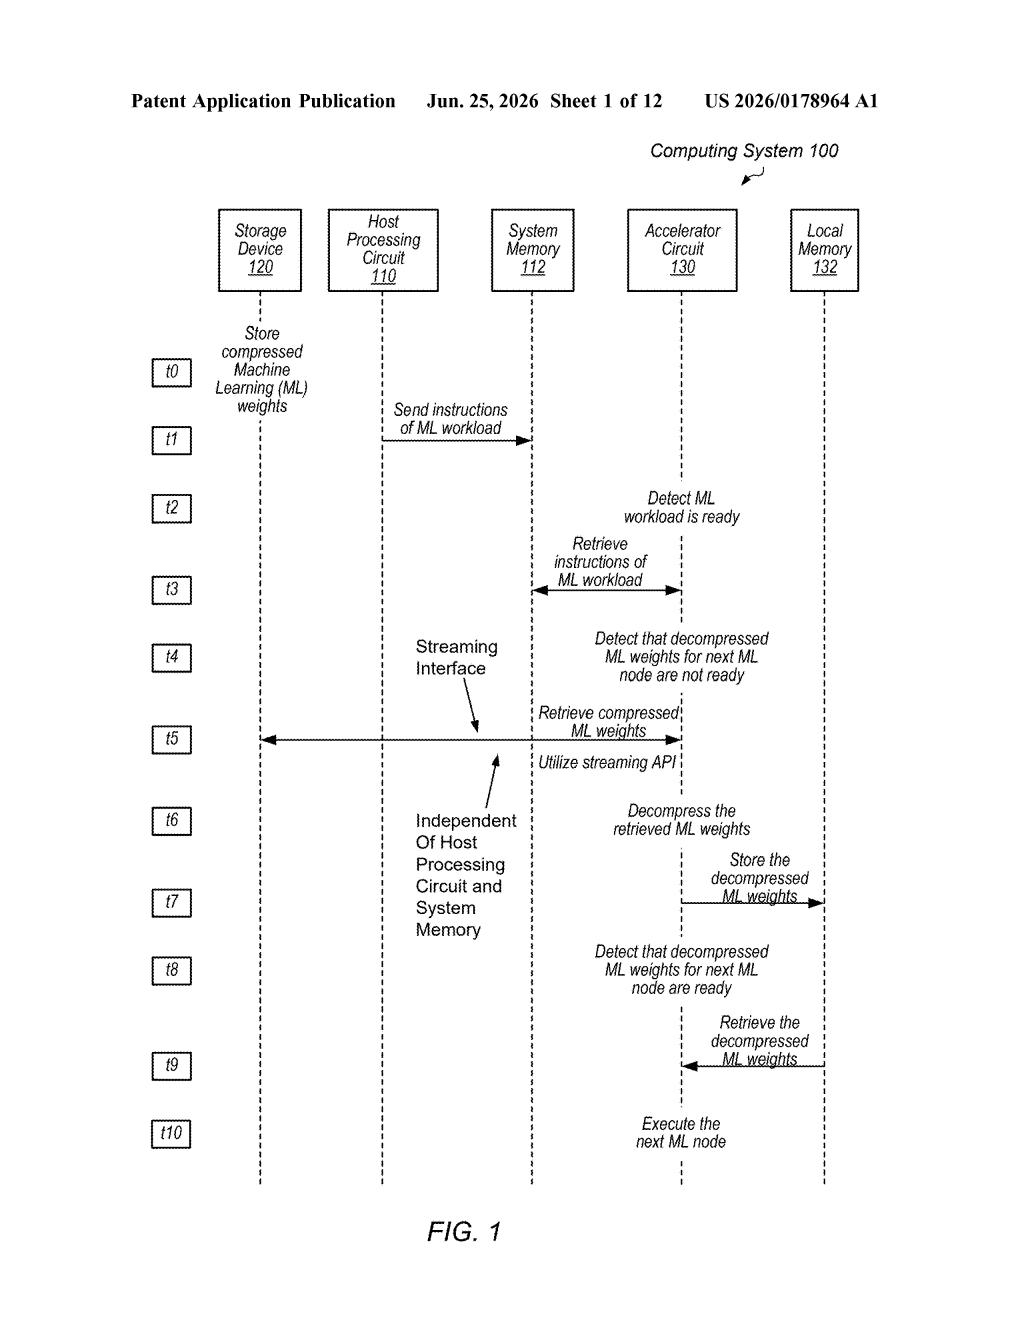
When an AI model runs, it depends on billions of stored values called weights that tell it how to behave. Normally, the main processor (the CPU) has to orchestrate fetching those weights into memory before the AI chip can use them. AMD's approach lets the AI accelerator chip pull the weights directly from storage on its own, in compressed form, and unpack them locally.
The result is that the CPU is no longer a traffic cop between storage and the AI chip. For systems running large AI models continuously, that could mean faster responses and less memory strain, since you only load what you need, when you need it.
How the accelerator fetches, decompresses, and runs weights on its own
The patent describes an accelerator circuit (think: AMD's GPU or a dedicated AI chip) that takes on the job of managing its own data supply. Here's the flow:
- The host CPU translates an AI application's instructions into commands the accelerator understands, then largely steps aside.
- The accelerator uses a streaming API (a direct software channel to storage, bypassing the CPU and system RAM) to fetch only the model weights it needs for the next set of calculations.
- Those weights arrive in compressed form, reducing how much data has to travel across the system bus.
- The accelerator decompresses them on-chip and executes the relevant part of the AI model immediately.
The system uses a computational graph (a map of the AI model's operations in execution order) to predict which weights will be needed next, allowing it to preload them before they're actually required.
This design targets inference workloads, meaning AI models that are already trained and just running predictions, which is the most common real-world scenario for deployed AI today.
What this means for AI inference speed and memory costs
The size of AI models has grown faster than the memory inside most chips. Keeping an entire model in local memory is increasingly impractical, so systems need to stream data in as they go. AMD's patent addresses that directly by making the accelerator the active agent in that process rather than a passive recipient waiting on the CPU.
For data centers running AI inference at scale, this kind of architecture could reduce the cost of high-bandwidth memory by relying more on cheaper storage, while keeping the chip fed at the speed it needs. For AMD, which competes with Nvidia for AI chip market share, demonstrating this kind of system-level efficiency is a meaningful part of the argument for choosing their hardware.
Source: US 2026/0178964 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
More from AMD
All 119 AMD patents →

More in AI assistant & agent
All 413 AI assistant & agent patents →
Qualcomm
Qualcomm Patent Enables AI to Learn New Categories Without Restarting Training
Qualcomm
Qualcomm Patents a Way to Run Multiple AI Personalities in Parallel

Google
Google Patent Splits How AI Networks Read and Write Their Own Memory

Google