IBM
IBM · AI / ML · Filed Nov 8, 2024 · USPTO published May 14, 2026 · May 14 release
IBM Patents a Context-Expanding System That Makes AI Database Queries Smarter
When you ask an AI a question about a database, it often grabs only the obvious fields — missing crucial related data sitting just one column over. IBM's new patent tries to fix that by teaching the AI to look around the neighborhood before it answers.
- Publication number
- US 2026/0134223 A1(US20260134223A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Nov 8, 2024 · May 14, 2026
- Inventors
- Andrew R. Freed, Luyuan Gao, Jasmeet Singh, Jonathan Springer, Marvin Limpijankit
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 704/9
- Examiner
- AGAHI, DARIOUSH (Art Unit 2656)
How IBM's query expansion feeds AI better database context
Imagine asking your company's AI assistant, "What's our ESG governance score?" A basic system finds the one database column labeled 'governance score' and hands that to the AI. But the score is meaningless without knowing the peer average, the percentile group, or the methodology behind it — all of which live in nearby columns that the simple lookup missed.
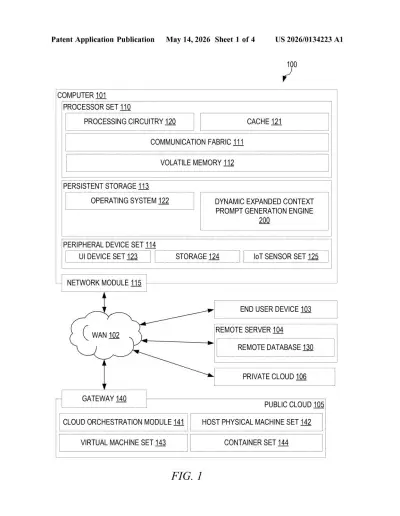
IBM's patent describes a smarter approach: after the system finds the direct matches to your question, it automatically scans adjacent fields in the database's data dictionary — a kind of index that describes what every column means and how they relate. It then pulls in the relevant neighboring fields and includes all of that enriched data in the prompt it sends to the AI.
The result is that the AI gets a fuller picture before it writes its answer — less like handing a chef one ingredient and more like giving them the whole pantry inventory for that dish.
How IBM's data dictionary traversal builds richer prompts
The patent describes a pipeline with a few distinct stages:
- Field matching: The system parses your natural-language input and maps keywords to specific fields in a data source schema (think: the structural blueprint of a database or data warehouse). These become the "first fields" — the direct hits.
- Adjacency analysis: For each matched field, the system inspects the data dictionary — metadata that describes each column's name, type, and relationships — and identifies "second fields" sitting nearby. Nearness here is defined semantically or structurally (neighboring columns in the same table, or fields linked by schema relationships), not just physical proximity.
- Expanded context assembly: The relevant second fields get merged into an expanded field listing, and actual data values from all those fields are pulled and packed into the context portion of a prompt sent to a generative AI model.
- AI response generation: The generative model (think a large language model) processes that enriched prompt and returns a response grounded in the fuller dataset.
The "learned context" in the title suggests the adjacency relevance scoring isn't purely rule-based — the system presumably trains on query-response pairs to get better at knowing which neighboring fields actually help.
What this means for enterprise AI querying structured data
Enterprise AI assistants querying structured data — think Salesforce analytics, SAP reports, or internal BI tools — constantly suffer from incomplete context. A single matched field is rarely enough to answer a business question correctly, which leads to confidently wrong AI answers. IBM's approach is a practical fix for that brittleness.
For you as an end user, this means fewer follow-up questions and less "the AI gave me a number with no context" frustration. For IBM, it fits squarely into their push to make watsonx and related enterprise AI platforms genuinely useful on top of real corporate databases — structured data being one of the hardest places to deploy LLMs reliably.
Source: US 2026/0134223 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
More from IBM
All 470 IBM patents →
More in AI / ML
All 2,637 AI / ML patents →
Microsoft
Microsoft Patents Shadow Testing Method to Improve AI Decision Thresholds
Salesforce
Salesforce Patents an AI That Catches and Fixes Its Own Broken Connections
Google
Google Patents an AI That Picks the Right Specialist AIs to Answer Your Question
Google