
Google Patents a System for Building Privacy-Safe Fake Datasets From Real Data
Google has filed a patent for a system that creates realistic fake datasets, statistically accurate enough to be useful for analysis, without ever exposing the real personal information underneath.
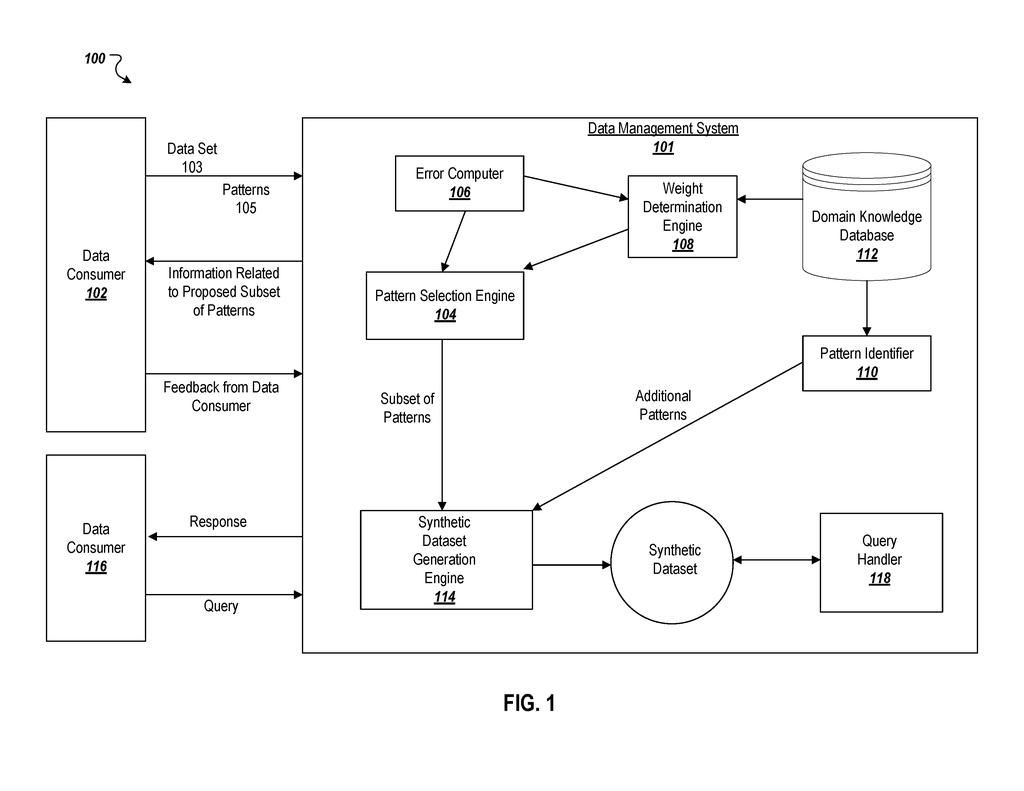
How Google's synthetic data tool keeps private details out
You're a researcher at a hospital, and you need to share patient data with an outside analytics team. The problem: that data is full of names, diagnoses, and personal details you legally cannot hand over. So what do you do?
Google's patent describes a system that reads your real dataset, learns the statistical patterns inside it (things like age distributions or how often two conditions appear together), and then generates a completely fake dataset that mirrors those patterns. The fake data looks and behaves like the real thing for analytical purposes, but no individual person's record is in it. The process uses a formal privacy technique called differential privacy, which adds carefully calibrated noise to prevent anyone from reverse-engineering the originals.
The clever part is how the system picks which patterns matter. It doesn't just copy everything. It searches a space of possible statistical relationships, compares them against what the data consumer actually needs, and selects only the most useful subset before building the synthetic version.
… selecting, using the dataset and the one or more patterns, from the set of candidate patterns, a proper subset of the candidate patterns to be used in generating a synthetic dataset; and generating a differentially private synthetic dataset based on the subset of patterns.
Translation: The system picks the best statistical traits to build a safe fake dataset that hides original user details.
How the pattern-selection process shapes the fake dataset
The patent describes a pipeline with four main steps:
- Pattern intake: A data consumer (a company or researcher who wants to analyze data) sends over the real dataset along with one or more "patterns", descriptions of statistical relationships they care about, such as correlations between columns or frequency distributions of particular values.
- Search space construction: The system identifies a broader universe of candidate patterns derivable from the dataset, going beyond what the consumer explicitly requested.
- Pattern selection: Using both the real data and the consumer's requested patterns as a guide, the system picks a proper subset of those candidates, the ones most likely to make the synthetic dataset useful without overfitting to noise.
- Differentially private synthesis: The system generates a synthetic dataset built on those selected patterns. Differential privacy (a mathematical guarantee that adding or removing any one person's record changes the output only by a tiny, bounded amount) is applied during generation, so the final dataset cannot be traced back to any individual.
The key engineering challenge the patent addresses is pattern selection: picking the right statistical features to preserve, not all of them. Too few patterns and the fake data is useless; too many and it risks leaking information about real individuals. The system tries to thread that needle automatically.
Each pattern defines statistical information characterizing at least a portion of data in the dataset.
Translation: Every rule describes the mathematical traits of a specific chunk of the real data.
What this means for companies sharing sensitive data
For any organization that handles sensitive records, hospitals, banks, insurers, government agencies, sharing data for research or AI training is a constant legal and ethical headache. Synthetic datasets are an increasingly popular answer, but generating ones that are both accurate and provably private is technically difficult. A system that automates the pattern-selection step could make this much faster and more accessible.
From a business angle, several Google filings on privacy-preserving data tools this year suggest the company is building out infrastructure for the kind of enterprise data work that competes directly with cloud analytics rivals. If this system ships inside a Google Cloud product, it could lower the barrier for companies that want to use AI on sensitive data without hiring a team of privacy engineers to sign off on every export.
Google's 48th filing we've tracked since May in our on-device AI privacy watch builds on an ad privacy check and a cloud-vs-on-device AI chooser.
Claim 1 is broad. It covers any method that takes a dataset plus user-specified patterns, identifies candidate patterns, selects a subset, and outputs a differentially private synthetic dataset. There is no restriction on the domain, the type of data, the selection algorithm, or even the specific differential privacy mechanism used. That breadth means, if granted, this claim could reach a wide range of synthetic-data generation tools.
The practical question is how much prior art already exists in this space. Academic research on differentially private synthetic data generation (including Google's own open-source work on tools like the Synthetic Data Vault and related differential privacy libraries) has been active for years. The distinguishing move here is framing pattern selection as the core inventive step, guided by what the data consumer actually wants. Whether that framing is novel enough to survive USPTO scrutiny is uncertain.
For readers outside the privacy-engineering world, the takeaway is simpler: Google is trying to patent the process of automatically deciding which statistical features of your data are worth faking. That is a useful capability, and it makes the filing relevant even if the final granted claims end up narrower than what was filed.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
4 drawing sheets from US 2026/0278150 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in