
IBM
IBM · Display · Filed Mar 24, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
IBM Patents a Way to Stack Multiple Data Records Into One Memory Slot
IBM has filed a patent for a memory technique that folds many separate data records into a single compressed structure, then pulls any one of them back out on demand using a matching key.
- Publication number
- US 2026/0291719 A1(US20260291719A1)
- Applicant
- International Business Machines Corporation
- Filed · Published
- Mar 24, 2025 · Sep 24, 2026
- Inventors
- Athanasios Vasilopoulos, Patrick Diener, Abbas Rahimi, Abu Sebastian
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 708/607
What IBM's layered memory compression actually does
Ever tried to find one email in a ten-year archive? The problem isn't just storage, it's that looking through thousands of separate files one by one takes forever. IBM's idea is to stop storing things separately in the first place.
This patent describes a system that takes a bunch of data records (called vectors, though you can think of them as entries in a database), tags each one with a unique identifier, then mathematically blends all of them together into a single stored object. That one object takes up far less space than all the originals lined up in a row. When you need a specific record back, you use the matching tag to "unmix" it from the blend.
The system is designed to run inside in-memory compute units, a class of chips that process data where it lives rather than shuttling it back and forth to a separate processor. That kind of chip is increasingly important in AI hardware, where moving data is often the biggest bottleneck.
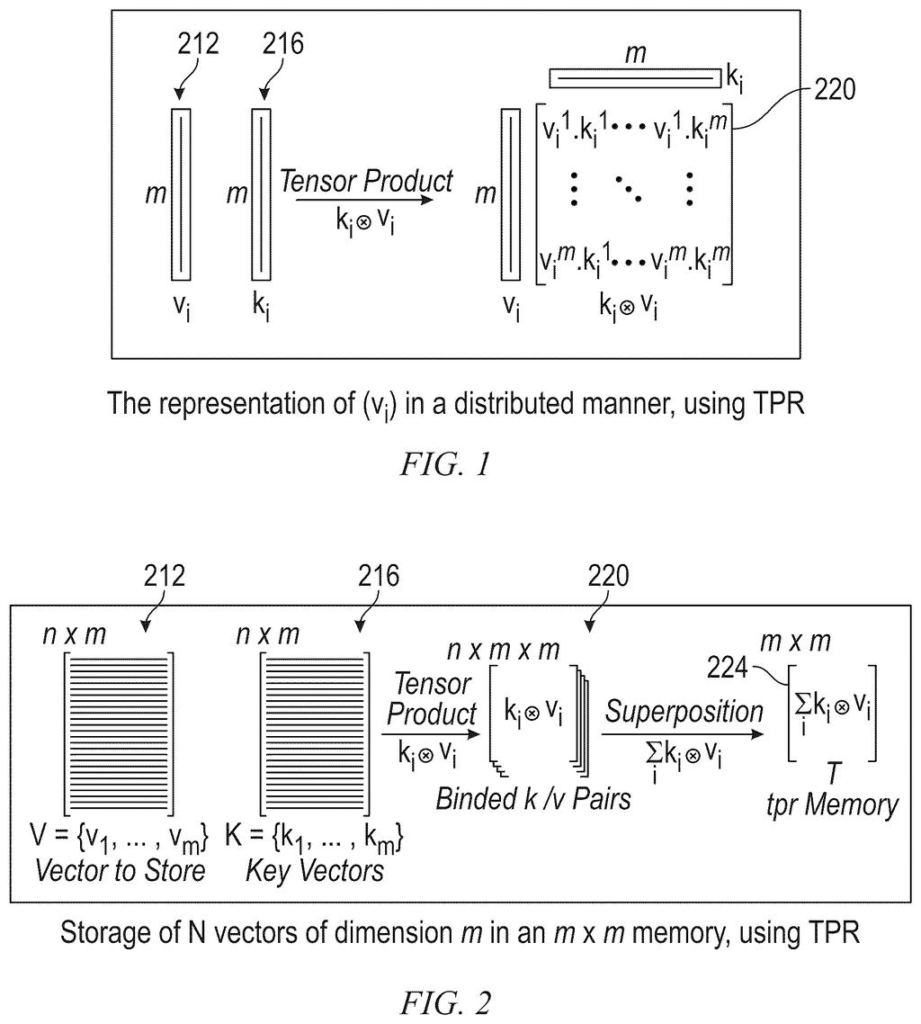
… binding each vector of the plurality of vectors with a corresponding key to create a 2-dimensional distributed representation via an outer product operation; putting the 2-dimensional distributed representation in a superposition with another 2-dimensional distributed representation to create an aggregated 2-dimensional distributed representation; …
Translation: Combining data with special keys lets multiple items merge into one shared memory space.
How keys and outer products pack vectors into one structure
The patent describes a three-step process for storing and retrieving data in compressed form.
Step 1: Tag each record. For every data vector (a list of numbers representing something, such as an image embedding or a sensor reading), the system generates a unique random key. Think of it as a fingerprint specific to that record.
Step 2: Bind and blend. Each vector is combined with its key using an outer product operation (a mathematical operation that takes two lists and produces a 2D grid of their pairwise relationships). The result is a 2-dimensional distributed representation, meaning the data is spread across many positions rather than sitting in one spot. These grids for all records are then added together into one aggregated representation, a superposition in the physics-inspired sense: many signals occupying the same space simultaneously.
Step 3: Retrieve on demand. To get a specific record back, the system regenerates the matching key and uses it to probe the aggregated structure. Because each key was unique and tied to its vector mathematically, the correct record can be separated from the blend without unpacking everything else.
The method draws on hyperdimensional computing (an approach that encodes information in very large random vectors so that patterns survive mathematical operations). The aggregated structure is stored in an in-memory compute unit, a chip architecture where processing happens inside the memory array itself, cutting the time and energy normally spent moving data.
What this means for AI chips squeezed on memory
Memory movement is one of the biggest costs in modern AI inference, the step where a trained model actually answers a question. Chips that process data in place rather than ferrying it across a bus can be meaningfully faster and more power-efficient. A compression scheme that lets many records share a single memory footprint amplifies that advantage further.
For AI hardware designers, IBM keeps filing on in-memory and neuromorphic compute, and this patent fits that pattern: it targets a real constraint (memory capacity and bandwidth) with a technique that could, in principle, let an AI chip hold more context without needing more physical memory. The gap between "in principle" and "in a shipping product" is still wide, but the underlying problem being solved is one the whole industry is working on.
IBM's 362nd filing in our IBM coverage since May adds to a run that includes cross-checking vehicle cameras and sensors and training AI on messy questions.
Source: US 2026/0291719 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 12 sheets
12 drawing sheets from US 2026/0291719 A1 · click any drawing to enlarge


Show the other 4 sheets


More from IBM
All 470 IBM patents →
More in Display
All 730 Display patents →
Samsung
Samsung Patents a Molded Waterproof Frame Built Around a Curved Display Edge
Sony
Sony Patents a Microscopic Surface That Converts Display Colors More Efficiently
Samsung
Samsung Patents a Molded Shell That Protects Phone Screens From the Inside Out
Google
No comments yet