Nvidia
Nvidia · AI / ML · Filed Apr 1, 2026 · USPTO published Aug 13, 2026 · Aug 13 release
Nvidia Patents an AI That Cuts Out Objects in Images Without Being Told What They Are
Teaching a computer to recognize exactly which pixels belong to a car, a dog, or a traffic cone normally requires thousands of hours of hand-drawn labels. Nvidia's new patent describes a system that can generate those precise outlines automatically, from just a photo and a rough box drawn around the object.
- Publication number
- US 2026/0237074 A1(US20260237074A1)
- Applicant
- NVIDIA Corporation
- Filed · Published
- Apr 1, 2026 · Aug 13, 2026
- Inventors
- Shiyi Lan, Zhiding Yu, Subhashree Radhakrishnan, Jose Manuel Alvarez Lopez, Animashree Anandkumar
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 382/156
- Parent application
- Continuation of 18/355,856 (filed Jul 20, 2023)(18355856)
How Nvidia's object-masking AI skips the hard labeling work
Today, training an AI to recognize objects at the pixel level requires someone to manually trace around every single object in thousands of images. That process is slow, costly, and a genuine bottleneck for companies building AI that needs to "see" the world, like self-driving cars or warehouse robots.
Nvidia's patent describes a system that skips most of that hand labor. You give it a photo and a simple rectangle drawn around an object, and it automatically fills in the exact outline of that object down to individual pixels. The clever part: the system doesn't need to know what the object is. It works on any object, whether that's a pedestrian, a traffic cone, or something it has never seen before.
The result is a tool that can automatically build the large labeled datasets that AI systems need to learn from, without requiring a room full of people carefully tracing every shape by hand.
… generating a first random value associated with a first dimension of the cropped image region and a second random value associated with a second dimension of the cropped image region; expanding the cropped image region to provide an expanded image region including at least one row of pixels or at least one column of pixels that exclude the object …
Translation: The system randomly adds extra rows or columns of background pixels around an object to help the AI learn what to ignore.
How the vision transformer turns a bounding box into a pixel mask
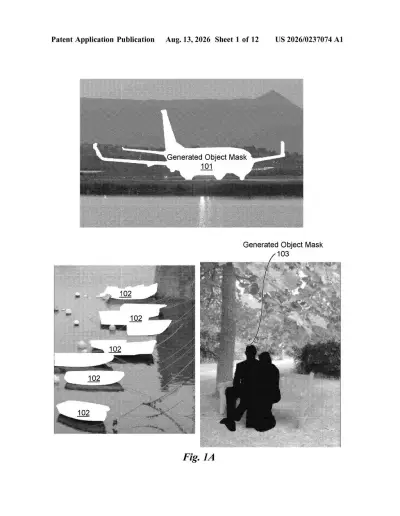
The patent describes an auto-labeling framework built around a vision transformer (a type of neural network that processes images in chunks, the way a language model processes words). The system takes a cropped portion of an image containing some object and produces a binary mask, meaning a pixel-by-pixel map that marks exactly which pixels are "object" and which are "background."
The key step is deliberate randomness. Before the neural network does its work, the system expands the cropped image region by adding extra rows or columns of pixels along the edges. Those extra pixels are chosen randomly in size, and they contain only background, no object. This gives the network a clear contrast to work with: here is pure background, and here is the object you need to outline.
Once the expanded image goes into the neural network, the model predicts which pixels belong to the object and outputs the finished mask. That mask, combined with the original image and any object label, can then be used to train other AI models for instance segmentation (the task of identifying and outlining every individual object in a scene).
Critically, the system is class agnostic, meaning it makes no assumption about what category of object it is masking. It can outline a shoe, a stop sign, or an unfamiliar piece of industrial equipment using the same process.
Class agnostic object mask generation uses a vision transformer-based auto-labeling framework requiring only images and object bounding boxes to generate object (segmentation) masks.
Translation: The AI can outline objects in photos without needing to know what the objects are, using only simple boxes drawn around them.
What this means for training self-driving and robotics AI
For anyone building AI that needs to understand the physical world, like systems in autonomous vehicles, drones, or factory robots, the availability of high-quality labeled training data is often the limiting factor. Generating precise pixel-level masks by hand is one of the most time-consuming parts of that process. A system that automates it from bounding boxes, which are far cheaper and faster to produce, could meaningfully accelerate how quickly these AI systems get trained and improved.
The class agnostic design is the part that stretches the usefulness furthest. Because the system doesn't need to know what it's masking, it can handle objects that no one thought to label in advance, which matters for autonomous vehicles that need to handle unexpected objects in the road. Nvidia's computer vision filings show up regularly among the plain-English patent summaries that track where machine perception research is heading across the industry.
Source: US 2026/0237074 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 12 sheets
12 drawing sheets from US 2026/0237074 A1 · click any drawing to enlarge


Show the other 4 sheets


More from Nvidia
All 665 Nvidia patents →
More in AI vision
All 351 AI vision patents →
Waymo (Google)
Waymo's New Patent Teaches One AI to Plan Its Own Route and Read Every Other Driver at Once
Waymo (Google)
Waymo Patents an On-Board Vision-Language Model That Answers Questions About the Road Ahead
Waymo (Google)
New Waymo Patent Lets Self-Driving Cars Answer Road Questions
Google