
Nvidia
Nvidia · AI / ML · Filed Feb 18, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
Nvidia Patents Technology That Cuts AI Response Time by Choosing Smarter Test Samples
Every time an AI model generates a response, it's doing a huge amount of guesswork, one word at a time. Nvidia's new patent aims to make that guesswork faster by teaching the system to pick better starting points before the main model even gets involved.
- Publication number
- US 2026/0236763 A1(US20260236763A1)
- Applicant
- NVIDIA Corporation
- Filed · Published
- Feb 18, 2025 · Aug 13, 2026
- Inventors
- Liwei Ma, Nikita Korobov
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 706/15
How Nvidia's token-draft system speeds up AI output
Every time a large language model like a chatbot types out an answer, it's running a complex calculation for each word (or word-fragment) it produces, one after another. That's slow, and speed is expensive at scale.
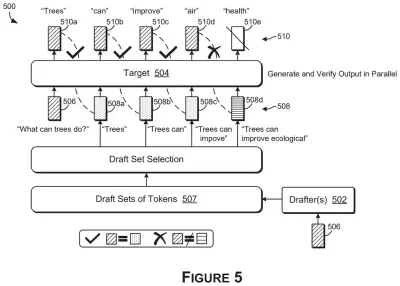
Nvidia's patent describes a smarter shortcut: instead of always guessing from scratch, a smaller "draft" model proposes a batch of likely next words, and the big model checks them all at once. The new trick is in how the system picks which draft proposals to use. It looks at past data, specifically how long each batch took to process and how many of those draft words the big model actually accepted, and uses that history to make better draft selections going forward.
The result is that the main model spends less time doing redundant work. You'd feel this as faster responses from AI tools running on Nvidia hardware, though the improvement happens entirely behind the scenes.
How the system tracks time and accepted tokens to choose drafts
The patent describes a technique that fits inside a broader approach called speculative decoding (a method where a fast, small model proposes several likely next tokens, and a larger, slower model verifies them in parallel rather than one at a time).
The core invention is in the draft-set selection step. The system maintains records of:
- Processing time for different token-batch sizes (how long each candidate draft takes to run)
- Accepted token counts (how many tokens from each draft the big model actually kept)
Using those two data points together, the system can calculate which draft configuration historically delivers the best throughput, balancing speed against accuracy of the proposed tokens. This is a form of data-augmented policy selection (using accumulated performance history to inform future decisions, similar to how a delivery driver learns which route is fastest at which times of day).
The claim is intentionally broad: it covers one or more processors, one or more draft sets, and one or more neural networks, which means Nvidia is staking out the general principle of performance-history-guided draft selection, not just one specific implementation.
What faster speculative decoding means for AI infrastructure
Speculative decoding is already used by major AI inference systems to cut the cost of running large language models, but choosing the right draft configuration is still largely a fixed or manually tuned decision. A system that learns which draft sizes work best over time, and adjusts automatically, could meaningfully reduce the compute cost of serving AI responses at scale. For companies running millions of queries per day, even small per-query efficiency gains add up to significant savings in hardware and energy.
This is squarely an infrastructure-level patent, so you won't see it marketed on a product box. But Nvidia's inference chips and software stack (TensorRT-LLM, for example) are where this kind of optimization would land, and that software layer is increasingly where Nvidia competes beyond raw silicon. It sits alongside a steady stream of new Big Tech patents targeting AI inference efficiency, an area drawing intense engineering attention as model serving costs remain one of the biggest line items for cloud AI providers.
Source: US 2026/0236763 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 17 sheets
17 drawing sheets from US 2026/0236763 A1 · click any drawing to enlarge


Show the other 9 sheets


More from Nvidia
All 665 Nvidia patents →
More in AI / ML
All 2,745 AI / ML patents →
Qualcomm
Qualcomm Patent Fixes a Hidden Bottleneck in AI Image Processing
IBM
IBM Files Patent for Automating AI Model Workload Distribution Across Processors
IBM
IBM Patents an AI System That Pre-Reserves Temporary Storage Before Apps Ask for It
AMD
