
Nvidia Patents a Faster Way to Shrink Complex 3D Models Without Losing Detail
Every 3D scene in a game or simulation is built from millions of tiny triangles, and shrinking that mesh down to something a GPU can handle quickly is still surprisingly slow. Nvidia's new patent attacks that bottleneck by collapsing many edges at the same time instead of one at a time.
How Nvidia speeds up 3D model simplification
Imagine a sculptor who needs to produce a rough sketch of a detailed statue. Right now, most software has to chip away at a 3D model one tiny edge at a time, checking each change before moving to the next. On a model with millions of triangles, that's painfully slow.
Nvidia's patent describes a way to do that simplification work in parallel, handling many edges simultaneously. The system figures out which parts of the mesh can be safely shrunk at the same time without interfering with each other, then collapses all of them in one pass.
Critically, the process keeps a record of every change it makes, so any calculation done on the simplified model can be "mapped back" onto the original high-detail version. You get the speed benefit of working with a simple mesh, but the quality of the detailed one.
How parallel edge collapse actually works in Nvidia's system
The patent describes a method for edge decimation (the process of simplifying a 3D mesh by merging pairs of connected points, called edges, into a single point) done in parallel rather than sequentially.
Here's the core flow:
- The system assigns every edge in the mesh an edge cost, a score representing how much visual or geometric damage collapsing that edge would cause.
- High-priority collapse candidates are selected based on low edge costs (low-damage edges).
- Each candidate "broadcasts" its cost to its neighboring triangles, effectively marking a small exclusion zone around itself so no two conflicting edges are collapsed at the same time.
- Any candidate edge that wins its local contest (its cost is stored in the buffer of all its neighboring triangles) is cleared to collapse. All such winners collapse simultaneously in one parallel pass.
The system also maintains a displacement history, a log of where every original vertex moved as the mesh was simplified. That log lets results computed on the lightweight mesh (like physics simulations or AI-generated lighting) be projected back onto the original high-resolution model with accuracy.
What this means for real-time graphics and AI geometry
3D mesh simplification is a foundational step in real-time rendering, physics simulation, and increasingly in training AI models on geometric data. Doing it faster and in parallel is a direct win for anything running on a GPU, from video game engines to neural rendering pipelines. Nvidia's hardware is already built for parallelism, so a decimation algorithm designed around that architecture fits naturally into its software stack.
The "map results back to the original" feature is the less obvious but arguably more important part. It means you could run an expensive calculation (say, ambient occlusion or collision detection) on a coarse mesh, then transfer those results to a detailed one at low cost. That's a meaningful shortcut for both real-time graphics and offline content creation tools like those in Nvidia's Omniverse platform.
This is squarely an infrastructure patent, not a consumer-facing feature, but it's the kind of foundational work that shows up inside every major Nvidia graphics and simulation product. The parallel-collapse approach is a genuine algorithmic improvement over the traditional sequential approach, and the vertex-history mechanism that enables result propagation is the detail that makes this more than a routine optimization filing.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
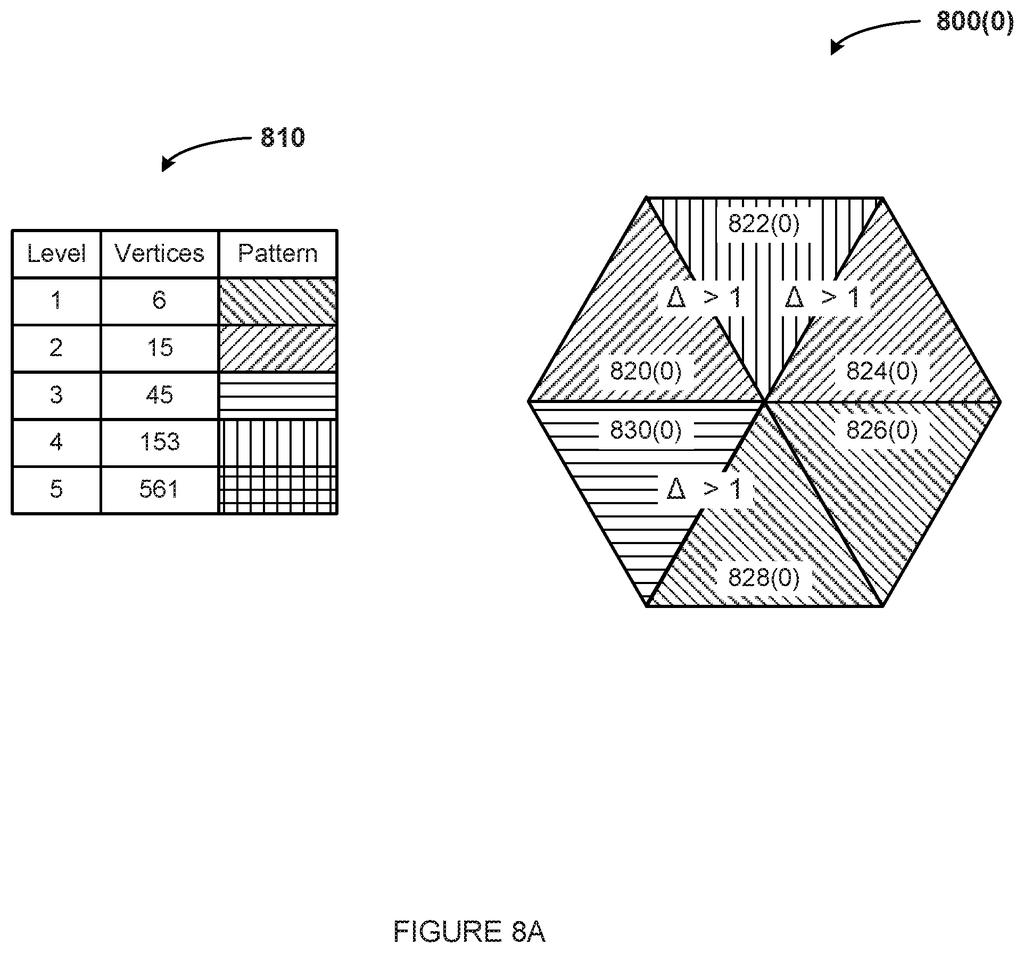
19 drawing sheets from US 2026/0212607 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in