
Nvidia · Filed Mar 9, 2026 · Published Sep 10, 2026

Nvidia Patents a Method to Run AI Processing Steps on Separate Chips

Every AI model you interact with runs a long chain of calculations, one layer feeding the next. Nvidia's new patent describes a way to run those layers on separate chips at the same time, cutting the wait.
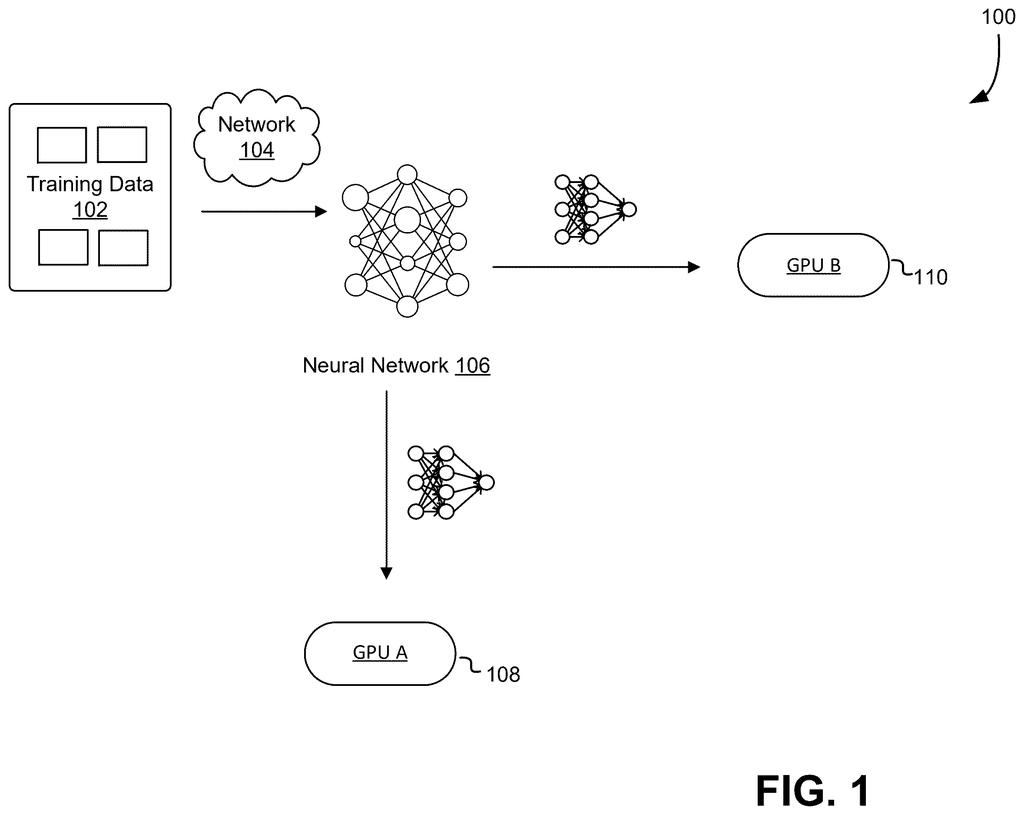
A neural network is trained with data and then processed by two separate GPUs. Drawing from patent filing US 2026/0268651 A1.
A neural network is trained with data and then processed by two separate GPUs.
See all 57 drawings from this filing ↓
Publication number US 2026/0268651 A1 US20260268651A1
Applicant NVIDIA Corporation
Filing date Mar 9, 2026
Publication date Sep 10, 2026
Inventors Wentao Zhu, Daguang Xu, Can Zhao, Ziyue Xu, Holger Reinhard Roth
US classification 706/25
Status when we published Waiting for an examiner (Jun 5, 2026)
Parent application is a Continuation of 16885170 (filed 2020-05-27)
Document 21 claims

How Nvidia's layer-splitting idea speeds up AI responses

Every time you ask an AI chatbot a question or use a photo app that recognizes faces, a chain of math happens inside the computer. Each step in that chain has to finish before the next one can start, which means the whole process is only as fast as its slowest step.

Nvidia's patent describes a system that watches how each step in that chain depends on the others, then ships the results of one step directly to a second chip so the next steps can start running in parallel. Instead of a single chip working through the whole chain by itself, the work gets spread out.

The goal is to cut the time it takes an AI to produce an answer, which engineers call inference time. Faster inference means snappier AI features in apps, faster image recognition in cameras, and quicker responses from AI assistants.

From the filing · THE ABSTRACT
… copying output from one layer of the neural network to another computing resource based on dependencies among layers in the network …

Translation: Moving data between different computer chips depending on what the neural network needs next.

How output gets copied between chips and layers

At its core, the patent covers a processor that analyzes the dependency graph of a neural network (a map of which layers need results from which other layers) and then routes the output of one layer to a separate computing resource so that two or more downstream layers can start processing immediately.

The key mechanism is output copying. When layer A finishes its calculation, the result is copied to another chip or compute unit without waiting for the entire network to run sequentially. Because the system knows in advance which later layers don't depend on each other, it can run them in parallel on those separate resources.

In practical terms, the patent describes:

  • A processor with one or more circuits that orchestrates this split
  • Mapping of layer dependencies so the system knows what can be parallelized
  • Routing of intermediate outputs to the correct compute resource at the right time

This is essentially a pipeline parallelism strategy (breaking a sequential process into overlapping stages, the way an assembly line works) applied to neural network inference, not just training.

What faster AI inference means for real products

Inference speed is one of the biggest cost and experience factors in modern AI. Every millisecond shaved off a model's response time reduces compute costs for companies running AI at scale, and makes AI features feel instant rather than sluggish to end users. Nvidia's steady investment in inference optimization reflects how competitive this space has become.

For you as a consumer, faster inference translates directly into AI assistants that respond without a noticeable pause, real-time video effects that don't drop frames, and medical imaging tools that flag results in seconds rather than minutes. The underlying technique here isn't tied to one product category, so its impact, if widely deployed, would touch any device or service running a neural network.

This is the 44th Nvidia filing we've tracked in our AI training and infrastructure coverage since May, alongside earlier applications like multiplying robot training videos and splitting AI workloads across machines.

Editorial take

The first independent claim in this patent was canceled before publication, leaving nothing enforceable on the page. A patent lives or dies by its claims, and with claim 1 gone, there is no legal boundary defining what Nvidia would own or what a hardware maker would need to work around.

What the abstract describes is a real engineering idea: finish one stage of AI processing, copy the result to a separate chip, and let the next stages run simultaneously rather than waiting in line. That kind of parallel handoff can meaningfully cut the delay between a user asking a question and an AI system answering it.

Whether this filing ever gains a surviving claim that locks down a specific version of that idea is still unresolved. Until it does, the document describes a promising technique without protecting one.

Get our take in your Top Stories

Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.

There are more where this came from

We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.

The drawings

57 drawing sheets from US 2026/0268651 A1 · click any drawing to enlarge

Neural network training and processing., drawing sheet 1 from US 2026/0268651 A1
Sheet 1 Neural network training and processing.
Encoder-decoder processing on devices., drawing sheet 2 from US 2026/0268651 A1
Sheet 2 Encoder-decoder processing on devices.
Parallel processing throughput comparison., drawing sheet 3 from US 2026/0268651 A1
Sheet 3 Parallel processing throughput comparison.
Steps for pipeline parallelism training., drawing sheet 4 from US 2026/0268651 A1
Sheet 4 Steps for pipeline parallelism training.
Steps for modifying neural networks., drawing sheet 5 from US 2026/0268651 A1
Sheet 5 Steps for modifying neural networks.
Accuracy and inference speed on HAN., drawing sheet 6 from US 2026/0268651 A1
Sheet 6 Accuracy and inference speed on HAN.
Accuracy and inference speed on liver., drawing sheet 7 from US 2026/0268651 A1
Sheet 7 Accuracy and inference speed on liver.
Training hardware structure components., drawing sheet 8 from US 2026/0268651 A1
Sheet 8 Training hardware structure components.
Show the other 49 sheets
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 9
Sheet 9
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 10
Sheet 10
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 11
Sheet 11
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 12
Sheet 12
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 13
Sheet 13
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 14
Sheet 14
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 15
Sheet 15
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 16
Sheet 16
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 17
Sheet 17
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 18
Sheet 18
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 19
Sheet 19
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 20
Sheet 20
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 21
Sheet 21
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 22
Sheet 22
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 23
Sheet 23
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 24
Sheet 24
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 25
Sheet 25
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 26
Sheet 26
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 27
Sheet 27
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 28
Sheet 28
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 29
Sheet 29
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 30
Sheet 30
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 31
Sheet 31
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 32
Sheet 32
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 33
Sheet 33
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 34
Sheet 34
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 35
Sheet 35
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 36
Sheet 36
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 37
Sheet 37
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 38
Sheet 38
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 39
Sheet 39
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 40
Sheet 40
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 41
Sheet 41
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 42
Sheet 42
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 43
Sheet 43
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 44
Sheet 44
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 45
Sheet 45
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 46
Sheet 46
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 47
Sheet 47
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 48
Sheet 48
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 49
Sheet 49
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 50
Sheet 50
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 51
Sheet 51
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 52
Sheet 52
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 53
Sheet 53
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 54
Sheet 54
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 55
Sheet 55
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 56
Sheet 56
Nvidia Patents a Method to Run AI Processing Steps on Separate Chips patent drawing, sheet 57
Sheet 57
Browse all the drawings 57 drawing sheets
Patent filing page

Source. Full patent text and figures from the official USPTO publication PDF.
Reader comments

Be the first to weigh in

Start the discussion

Real name or a handle, either is fine. Comments are read by a person before they appear, so allow a little time. Keep it about the filing.