
Amazon Patents a Way to Keep AI Training Jobs Running When a Server Crashes
Training a large AI model can take days across hundreds of servers, and a single server crash can throw away all that work. Amazon has a patent for a system that swaps in a spare server mid-training, with almost no lost progress.
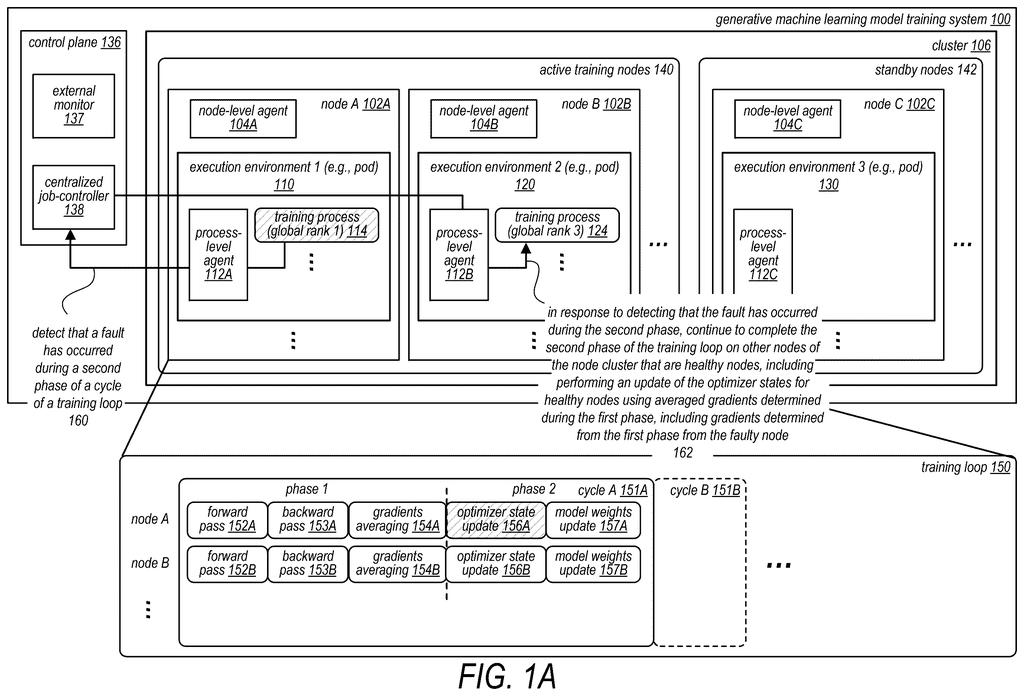
How Amazon keeps AI training alive after a server dies
You're running a months-long AI training job across a warehouse full of servers, and one of them dies halfway through. Without a recovery plan, every server stops, the job restarts from scratch, and you've just burned hours of expensive compute time.
Amazon's new patent describes a training system that handles that exact failure more gracefully. Instead of halting everything, the healthy servers finish the step they were already working on, then copy their current progress to a spare server waiting on standby. Training picks back up with the replacement in the mix, and the failed machine is dropped.
The key insight is that each training "step" has two parts: a heavy calculation phase where all servers share results, and a lighter update phase where each server adjusts its own copy of the model. A crash during the update phase is actually recoverable because the shared results from the first phase are already done. That means the healthy servers have everything they need to finish the step and bring the standby up to speed.
… determine whether the fault has occurred during a first phase or a second phase of a cycle of a training loop for the training job …
Translation: The system figures out exactly which part of the training process was running when the server failed.
How the system hands off state to a standby node
Training a large AI model is a coordinated process split across many servers, called nodes. Each node holds a copy of the model and processes a slice of the training data in repeated cycles.
Each cycle has two phases. The first phase runs a forward pass (the model makes predictions), a backward pass (the model figures out how wrong it was), and a gradient averaging step (all nodes share and average their error signals across the cluster, so every node has the same combined signal). The second phase uses those averaged gradients to update each node's internal tuning values (the optimizer state) and model weights.
This patent focuses on what happens when a node fails during the second phase. Because the gradient averaging already completed in phase one, the healthy nodes already have all the information they need to finish the update independently. Amazon's system lets them do exactly that rather than stopping the whole job.
Once the healthy nodes finish the update, one of them sends its updated optimizer state and model weights to a standby node that was pre-positioned but idle. The standby is initialized with that data and joins the next training cycle as a full participant. The crashed node is excluded, and training continues without restarting from a checkpoint.
What faster fault recovery means for AI training costs
Large AI models take enormous compute budgets to train, and infrastructure failures are a real, recurring cost. Every hour of training time lost to a node crash translates directly into money and delay. A system that can absorb a mid-run failure, skip the full restart, and recover in seconds rather than hours changes the economics of running these jobs at scale.
For Amazon, which sells AI training infrastructure through AWS, this kind of fault tolerance is a concrete competitive feature. Customers training large models, the kind that can run for weeks, care deeply about job reliability. Amazon's bet on AI infrastructure resilience shows up in patents like this one, where the engineering focus is less on model architecture and more on making the plumbing dependable enough that researchers can trust it.
Amazon's ninth filing we've tracked in our AI chip wars watchlist since May follows quantum and classical work splitting and migrating paused jobs to new servers.
The system only recovers cleanly when a failure happens in the second half of a training cycle, after the nodes have already shared their calculations. A crash in the first half still kills the cycle entirely. That's a real cost, and whether it matters depends on when servers actually tend to fail, which this document doesn't address.
Keeping a spare server running in reserve, idle until something breaks, adds ongoing expense. For training runs lasting weeks, that cost is easy to justify. For shorter jobs, the math gets murkier.
The focused scope is ultimately the right call. A solution that handles one failure scenario reliably beats a sprawling one that handles many scenarios poorly, and the recovery path described here is concrete enough to trust.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
9 drawing sheets from US 2026/0300819 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in