
AMD Files Patent for Keeping AI Chip Clusters Running When a Network Card Dies
When a network card fails in the middle of an AI training run, the job usually has to stop and redo work. AMD's patent hides the failure from the software entirely.
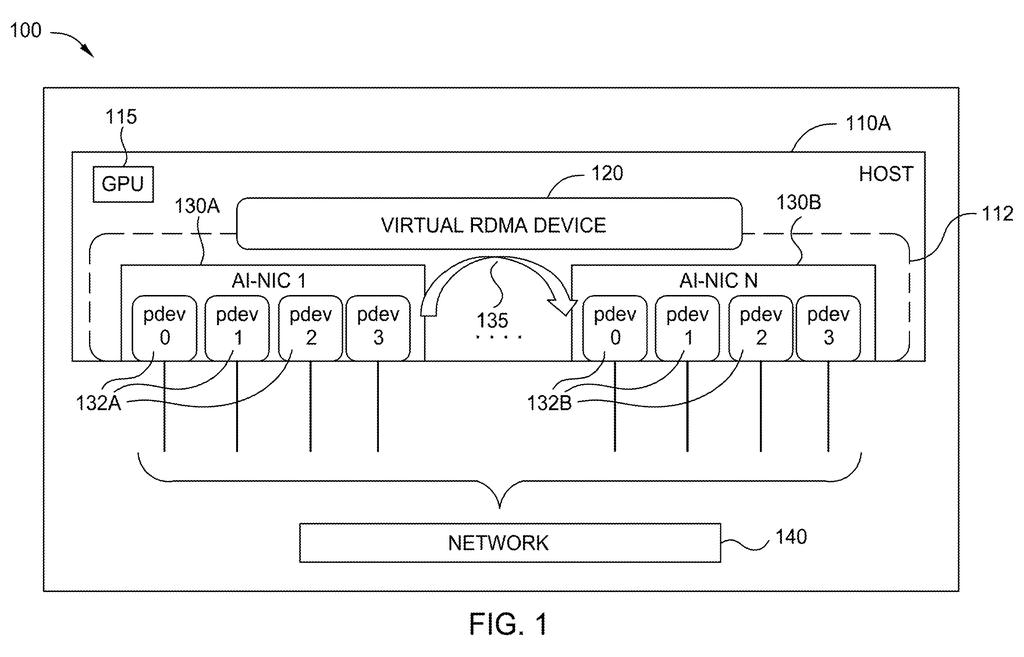
What AMD's stand-in network card actually does
Ever had a video call freeze because one router hiccupped, forcing you to rejoin and start over?
Something similar happens inside the data centers that train AI models. Hundreds of graphics chips (GPUs) trade data constantly through network cards, and when one card fails, the software running on the chips often has to stop, fall back to its last saved point, and redo work.
AMD's patent adds a stand-in network device that sits between the software and the real cards. The software talks only to the stand-in. Behind the scenes, the stand-in watches the real cards, and if one breaks, gets overloaded, or goes offline for a planned update, it moves the traffic to a healthy card. The AI job never finds out anything went wrong.
… a virtual remote direct memory access (RDMA) device configured to manage data workloads between processor applications and the multiple NICs when a failure event is detected in at least one NIC of the multiple NICs.
Translation: A special software layer reroutes data when a network card breaks so the system keeps running.
How traffic hops to a healthy card mid-job
The core piece is a virtual RDMA device. RDMA (remote direct memory access) lets one machine's chip read and write another machine's memory over the network without the main processor getting involved. Here, the virtual device presents itself to GPU software as one ordinary RDMA network card, while several physical cards (NICs, or network interface controllers) sit behind it.
GPU software posts requests to virtual queue pairs, which work like numbered in-trays for outgoing and incoming messages. An RDMA driver maps those virtual in-trays onto real ones on whichever physical card is healthy. The description says the virtual device checks card health with heartbeats, error reports, or network diagnostics.
The claims cover three kinds of trouble:
- Uplink failure (the card's connection out to the network breaks): traffic is rebalanced onto working cards.
- Soft or hard failure (a temporary slowdown or a permanent fault): traffic is redirected to functional cards.
- Maintenance or upgrade downtime: traffic is rebalanced and the affected card is isolated.
The filing also describes live migration of a queue pair from one card to another. Both cards briefly share the job, a log of in-flight operations gets replayed on the new card, and a rollback path exists if the move goes wrong. Some claims also describe the cards being electrically connected to each other inside the host machine.
The processor applications are unaware of the failure event detected in the at least one NIC of the multiple NICs.
Translation: The artificial intelligence software never notices when a hardware component fails.
Why one dead network card shouldn't stall AI
If you use chatbots, image tools, or any service built on large AI models, a lot of it depends on racks of GPUs trading data nonstop. The filing says a failed network card can stall the whole job, force a rollback to a saved point, and make GPUs redo computation. Hiding that failure from the software could mean fewer interrupted training runs and less wasted computing time, which usually shows up as lower costs for whoever runs the data center.
For AMD, which sells GPUs and describes data processing units as one way to build these network cards, this is a pitch about reliability at cluster scale: the description mentions clusters of dozens or even hundreds of GPUs. The description says rerouting can happen within microseconds, but it gives no measured results.
AMD's 45th filing we've tracked in our AI chip wars watchlist since May adds to a run that includes one on spare chip blocks and one on combined AI math commands.
On the ship-path question, this reads as a software and firmware project more than a new chip. GPUs, network cards with their own small processors, and RDMA drivers already exist in data centers, and the filing describes the virtual layer as software-defined or hardware-assisted.
The hard part is moving a live connection between two cards without dropping a single message. That means copying a lot of connection state very fast, and the filing gives the outline of that process and no test numbers. The shortest route to a product is a driver and firmware update for servers that already have several network cards wired to each other.
You would never see this as a feature. If it works, the payoff is an AI service that keeps running when a piece of hardware misbehaves, and that makes it a sensible piece of plumbing with a clear path forward and no new chip required.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
7 drawing sheets from US 2026/0311285 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in