
Nvidia Files Patent for a Translator Between Raw Data and AI Models
Every AI model is picky about the exact shape of the data it receives. Nvidia's new patent application describes a middleman that reshapes data for each model automatically, then checks the model's work as it runs.
What Nvidia's AI data translator actually does
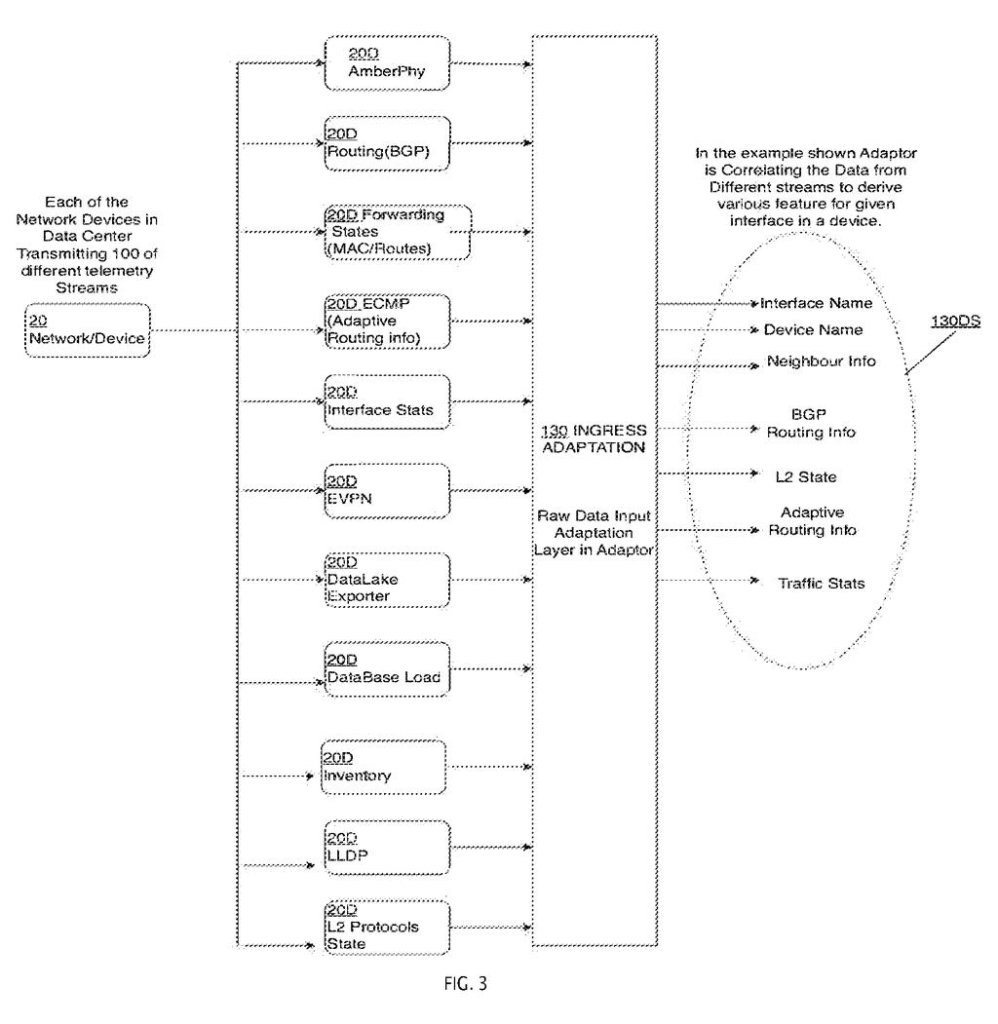
A company's network equipment sends out status reports all day, and each kind of device writes its report in its own format. The AI model that is supposed to spot trouble in those reports understands only one specific layout. You have probably hit a small version of this yourself: a file that won't open because it's the wrong type.
Nvidia's patent application describes a middleman it calls an adaptor. When an AI model is plugged in, the adaptor reads a description of that model, including what kind of data it expects. It then converts incoming data into that shape before the model ever sees it. Data with key pieces missing gets repaired if possible, or tossed out.
The filing also describes the trip in reverse: turning the model's answers into something other tools, like a Slack alert or a dashboard, can read. And it watches how hard the model is working, so it can ask for more computing power when work backs up.
… employ an ingress adaptation module, to receive an input data element from one or more data input sources, and translate said input data element according to the ingress data format …
Translation: It takes raw input data from various sources and converts it into the exact format the AI model needs.
How the adaptor reformats data for each model
Claim 1 covers an adaptor, a piece of software that sits in front of an AI model, or a chain of them (the filing calls this an inference pipeline, meaning the production line that pushes data through models to get answers). It does four things:
- Collects model metadata, a description of the deployed model, such as the data formats and sizes it expects.
- Uses that description to define the ingress data format, the exact layout the model must receive.
- Runs an ingress adaptation module that takes data from one or more sources and translates it into that layout.
- Feeds the translated data through the model to produce a result.
The dependent claims add extras. An egress adaptation module (the same idea in reverse) reshapes the model's answers for whatever system uses them. A compression step shrinks incoming data when the model can't keep up. A telemetry module (a live monitor) tracks how much computing power the model uses and warns an orchestrator, the software that adds or removes copies of a model, such as Kubernetes, when there is a backlog or idle capacity.
Another claim adds a digital twin, a second model that gets the same data so its answer can be compared with the live model's. If accuracy drops below a set threshold, the system calculates a loss value (a score of how wrong the model was) and retrains the live model.
… collect model metadata describing at least one machine-learning (ML) based inference model deployed within the inference pipeline …
Translation: It gathers technical details about how the deployed AI model operates.
Why AI plumbing matters for companies using Nvidia
If you work anywhere that runs AI on real business data, you know the hard part is often not the model. It's getting messy data in and usable answers out. A tool that handles that translation, scaling and accuracy checking automatically could save teams a lot of custom glue code each time they add or swap a model.
The filing's examples come from network monitoring: router and interface reports going in, alerts to Slack or PagerDuty coming out. The text also refers to NIM deployment, which hints this is aimed at companies deploying AI models on Nvidia's software and hardware. Nothing in the filing says it is a product, but it shows where the day-to-day friction of running AI lives.
Nvidia's 15th filing we've tracked since July in our AI teams working together watchlist follows earlier applications like loading only needed model parts and training on multiple image types.
Claim 1 is short and wide. It asks for four steps: read a description of an AI model, decide what data format that model needs, convert incoming data to that format, and run the model. Nothing in the claim names a network, a chip, or even a kind of data.
If granted, that wording could reach any system that looks up what a model expects and converts data to match before running it. Plenty of software does some version of that already, so the claim's real weight depends on how an examiner reads the phrase "based on the model metadata" (the model's own description).
The sharper ideas sit further down: a second "twin" model that checks the live model's answers while it runs (claim 7), and retraining when accuracy slips (claim 8). Those are narrower and easier to tell apart from everyday practice. Taken together, the filing is useful plumbing for companies running many models at once, with a couple of more distinctive parts.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
7 drawing sheets from US 2026/0320433 A1 · click any drawing to enlarge


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in