
Amazon
Amazon · AI / ML · Filed Feb 13, 2026 · USPTO published Nov 12, 2026 · This week's release
Amazon Files Patent for Transcription That Gets Rare Names and Jargon Right
Speech-to-text software stumbles on words it has rarely heard, like a drug brand, a company name or a small-town street. Amazon's filing describes handing the system a list of those words and nudging it to pick them.
- Publication number
- US 2026/0360352 A1(US20260360352A1)
- Applicant
- Amazon Technologies, Inc.
- Filed · Published
- Feb 13, 2026 · Nov 12, 2026
- Inventors
- Devang Kulshreshtha, Saket Dingliwal, Brady Houston, Sravan Babu Bodapati, Srikanth Ronanki, Jeffrey John Farris, Vivek Govindan, Katrin Kirchhoff
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 704/232
- Parent application
- Continuation of 18/345,754 (filed Jun 30, 2023)(18345754)
What Amazon's custom-word transcription does
You're dictating notes after a meeting, and the transcript turns a client's unusual name into gibberish. The software has simply never seen that word, so it swaps in the closest everyday phrase.
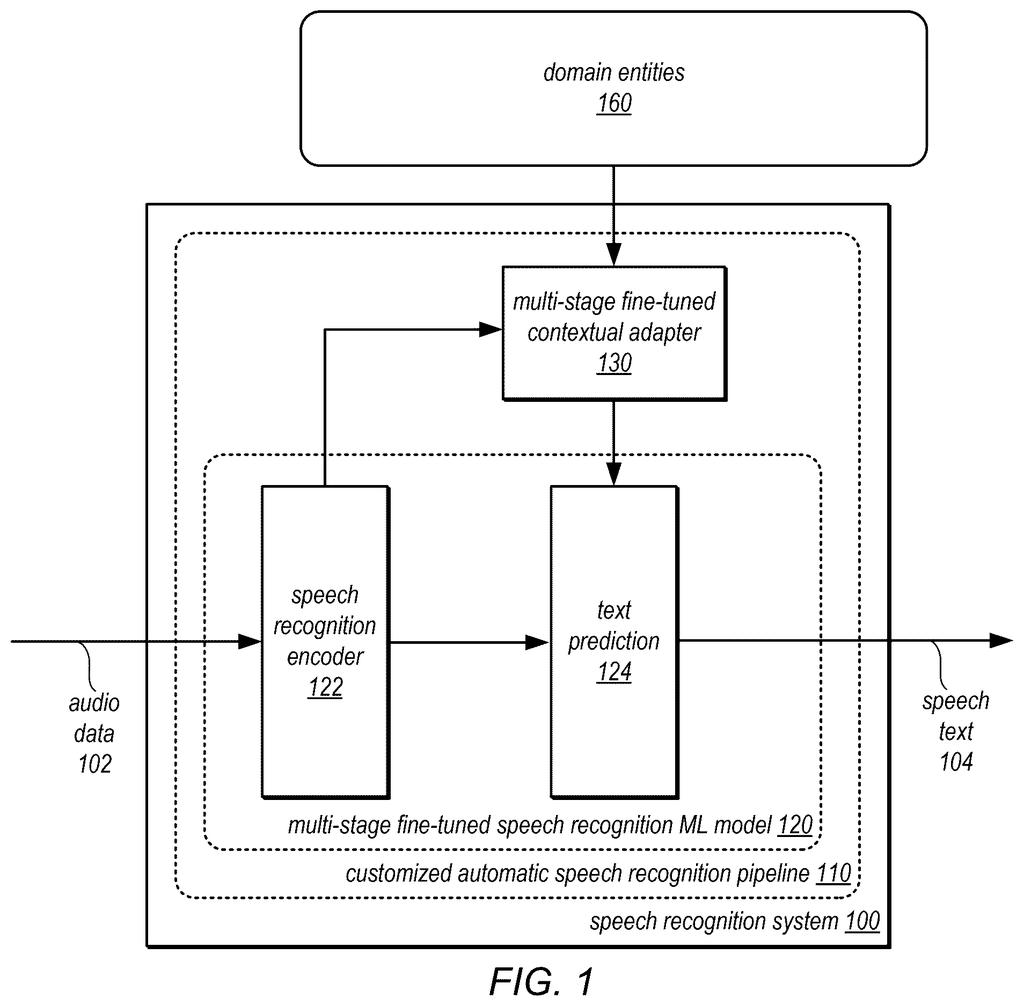
Amazon's patent describes a fix offered as a cloud service. You send along a list of words that matter to you, such as product names, people or technical terms, and the system leans toward those words whenever the audio sounds close.
The filing also covers how to prepare the add-on that does the leaning. It is trained in stages, first on many languages at once, then more narrowly, so that languages with little recorded audio still get decent results.
… the plurality of text entities are used to bias one or more weights at a decoder of the one or more speech recognition models to increase a probability of recognizing the plurality of text entities when generating the transcription of the speech in the audio data.
Translation: Specific words are given extra statistical weight so the AI is much more likely to spell them right.
How Amazon trains the word-list add-on in stages
The claims cover the customer-facing part. A client sends a request through an interface (an API, which is a way for programs to talk to each other, or a command line) asking for a transcript of some audio, plus a list of text entities, meaning words or phrases to favor. While the transcript is generated, those entities bias the weights at the decoder (the final stage that turns the model's internal guesses into words), raising the odds that a listed word wins. One variation boosts sub-word sequences, the word fragments that make up each listed word.
The description explains the machinery. A contextual adapter (a small add-on attached to the main speech model) has a catalog encoder that converts each listed word into numbers, and an attention scorer (a part that decides which listed words matter at each moment of audio). The main model can use a CTC encoder, a common speech-to-text design.
Training happens in stages:
- Train the main model on audio from many domains (languages, professional fields) at once.
- Tune it again on single domains, or lock it in place ("freeze" it) while only the adapter learns.
- In one variation, tune the adapter first, then tune both together.
The filing also describes pre-training the catalog encoder on text alone, since text is easier to find than paired audio.
… subsequent tuning stages that freeze the speech recognition machine learning model while tuning the contextual adapter and tune the speech recognition machine learning model again.
Translation: The system updates its core vocabulary engine in careful stages to learn new terms without breaking.
Why rare names and languages get the attention
If you've watched live captions mangle a name, this targets that failure. Businesses that transcribe calls, meetings or medical notes could supply their own vocabulary and get transcripts that spell it correctly, without building a custom speech model from scratch. Because the claims describe a request sent to a cloud service, the benefit would arrive through whatever apps sit on top of it.
The training angle may matter more. The filing says adapters normally need thousands of hours of paired audio and text, while many languages have under 1,000 hours. Staged tuning is meant to make customization work in those low-resource languages too, which could widen who gets accurate custom transcripts.
Amazon's fifth filing in Voice & speech AI we've tracked since May follows earlier applications on picking images for Alexa answers and ranking emotionally charged call topics.
Source: US 2026/0360352 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Amazon patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 8 sheets
8 drawing sheets from US 2026/0360352 A1 · click any drawing to enlarge


More from Amazon
All 111 Amazon patents →
More in AI / ML
All 2,637 AI / ML patents →
Google
Google Files Patent for Teaching Speech Recognition to Learn From Its Own Best Guesses
IBM
IBM Files Patent for Speech Transcription That Arrives Already Capitalized and Punctuated
Google
Google Patents a Speech Recognizer That Types Fast, Then Fixes Its Own Mistakes
Google
No comments yet