
Adobe
Adobe · AI / ML · Filed May 8, 2025 · USPTO published Nov 12, 2026 · This week's release
Adobe Files Patent for AI Video That Cuts From One Scene to the Next
Most AI video tools hand back one unbroken take. Adobe's patent application describes a way to ask for several shots in a row and get a video that actually cuts between them.
- Publication number
- US 2026/0360065 A1(US20260360065A1)
- Applicant
- Adobe Inc.
- Filed · Published
- May 8, 2025 · Nov 12, 2026
- Inventors
- Tobias Hinz, Ozgur Kara, Krishna Kumar Singh, Feng Liu, Duygu Ceylan Aksit
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 345/581
- Examiner
- USSERY, CAIDEN ALEXANDER (Art Unit 2611)
What Adobe's multi-scene AI video patent does
Every time you ask an AI tool for a video, you get back one unbroken take. Ask for a man sketching at a café, and the camera never cuts away from him.
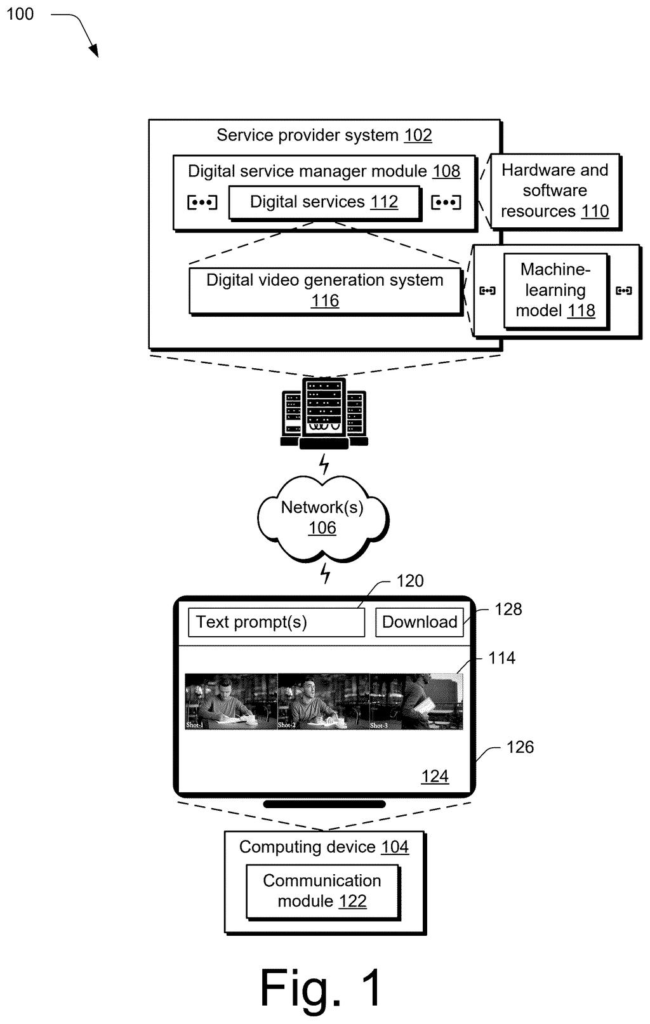
Adobe's patent application describes a way to write a prompt for several shots in a row and get a video that cuts between them. In the filing's example, a man sketches in a notebook, looks up thoughtfully, then steps outside with the notebook under his arm. That is three shots, and he is meant to stay recognizably the same person throughout.
You could also say how many shots you want and how long each one lasts. The system marks each cut with a special placeholder so the AI knows exactly where one scene ends and the next begins.
obtaining, by a processing device, one or more text prompts describing a plurality of shots in a digital video; generating, by the processing device, the digital video using a machine-learning model based on a sequence of tokens as corresponding to the plurality of shots and a transition token corresponding to a transition between the plurality of shots …
Translation: The software reads text descriptions to create multiple video scenes and the cuts that connect them.
How Adobe marks the cuts between scenes
The main claim covers a method with three steps. You supply one or more text prompts that describe a set of shots. A machine-learning model then builds the video from a sequence of tokens (small numeric chunks that stand in for pieces of text and video), including a transition token that marks where one shot ends and the next begins. The finished video is then shown in an interface.
The filing says the model can be a diffusion transformer, which starts from random noise and removes it step by step until a video appears. To keep shots separate, it uses an attention mask (a rule limiting which pieces of information can influence each other). Each shot's text only shapes that shot's frames, and the transition token focuses on the frames where the cut happens. Without the mask, the filing says, shot-specific details get diluted.
A separate claim covers training. The filing builds multi-shot training videos out of ordinary single-shot clips:
- Chop a long, high-motion clip into random pieces of random length and stitch them together.
- Combine separate clips of the same subject, grouped by things like the same uploader within three days and similar captions.
Another AI model writes a caption for each shot, and clips showing more than one subject or a changing identity are filtered out.
The work can run on your own device, or be sent to a server if the device lacks the power or memory.
Why scene-by-scene control matters for creators
If you have ever wanted an AI video to feel like a scene from a story instead of a single looping clip, cuts are the missing piece. This filing lets you choose the number of shots and how long each one runs, which starts to look like writing a shot list instead of rolling the dice on one prompt.
The filing also points out the weak alternatives: squeezing every action into one prompt, or generating each shot separately and gluing them together, which can leave the person looking different from shot to shot. Its training approach reuses plentiful single-shot video, and it fine-tunes an existing model with 5,000 iterations or less, a light touch. Keep in mind this is a patent application, and nothing in it says a product is on the way.
Adobe's 59th filing we've tracked since May in our AI photo editing race follows earlier applications like filling missing edges and rotating objects around.
Source: US 2026/0360065 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Adobe patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 16 sheets
16 drawing sheets from US 2026/0360065 A1 · click any drawing to enlarge


Show the other 8 sheets


More from Adobe
All 264 Adobe patents →
More in AI vision
All 339 AI vision patents →
Google
Google Patents AI That Drops a Plain Product Photo Into a Lifestyle Scene
Nvidia
Nvidia Patents Technology That Changes Lighting on People in Video Without Flickering
Nvidia
Nvidia Files Patent to Keep AI-Altered Faces From Looking Pasted Onto Video
Sony
No comments yet