The AI Photo Editing Race in Google and Nvidia Patents, and Where They Point
This tracker collects Google and Nvidia filings on photo and video editing, covering per-region edits, text-guided recoloring, compression, and smoother zoom previews. The batch shows camera software moving from single-pass fixes toward layered, context-aware editing built into the pipeline.
268 filings
· tracking since Apr 2026 · latest Nov 2026 · updates weekly
based on all tracked filings in this watchlist · refreshes every week
Companies are racing to own the tools that let software fix, reshape, and reinvent photos and videos automatically, from erasing unwanted objects to rebuilding lighting after the shot is taken. The core fight is over which company's methods become the standard layer sitting between a camera and a finished image.
Google and Adobe carry the most weight here by a wide margin, with Google leaning into fixing flaws at capture time and Adobe concentrating on giving editors precise control over every element after the fact.
What’s new in the AI photo editing race
a dated entry each week this watchlist moves · older entries stay archived
Nov 5, 2026 12 filings joined
Google leads this week with seven filings covering everything from glare detection to erasing text from photos. Adobe and Samsung each added two filings, touching up sharpening, zoom, and object editing.
Adobe leads this week with four filings covering color, blur repair, lip sync, and keeping AI people looking right on moving cameras. The broader push is about making AI photo and video fixes work faster, smaller, and more precisely.
Adobe leads this week with five filings, mostly around placing and lighting objects in photos. Sony, Google, Qualcomm, and Samsung each added tools to fix or reshape photos after they are taken.
Adobe and Samsung lead this week, each filing several patents around fixing and reshaping photos and videos after the fact. Google also added multiple filings, mostly around turning simple camera input into richer images and scenes.
Nvidia leads this week with three filings covering photo repair, 360-degree scenes, and video cleanup. Google and Adobe also filed, pushing the week's focus toward fixing and reshaping images before and after they are taken.
Google leads this week with four filings covering light, text, faces, and camera framing. Sony follows with three, focused on cutting out subjects, fixing harsh lighting, and keeping video edits consistent across frames.
This week's filings center on AI that selects, removes, and fills in parts of photos and video automatically. Google and Adobe are the most active, each filing three patents covering everything from text-based edits to frame rebuilding.
Adobe leads this week with seven filings covering cutting, lighting, shadows, and motion in photos and videos. Google and Adobe together push hard on making AI understand and edit specific parts of an image rather than the whole thing.
Google dominates this week with seven filings spanning video, lighting, and image repair, while Adobe adds four focused on color, reflections, and repositioning people in photos.
This week's filings show companies focused on fixing photo and video quality problems, from brightening dark spots to repairing blurry compressed video. Google and Apple each filed two patents, making them the most active this week.
Aug 27, 2026 14 filings joined
Adobe leads this week with five filings covering edge cleanup, 3D scene compression, and video edit scoring. Most other companies are focused on fixing or sharpening images and video, from removing spots to rebuilding blurry photos.
Aug 20, 2026 8 filings joined
This week's filings lean heavily toward AI that understands and reshapes photos and video, from changing how far away a subject looks to copying a director's camera style. Google leads the pack with three new filings, joined by Sony with two.
Who’s filing patents in the AI photo editing race
counts from tracked filings · focus read from each company’s own filings
The battlegrounds inside the AI photo editing race
the fights inside the fight · each with its three newest filings · new filings join every week
Removing and Replacing Photo Objects 39 filings
Adobe 19, Google 5, Qualcomm 4
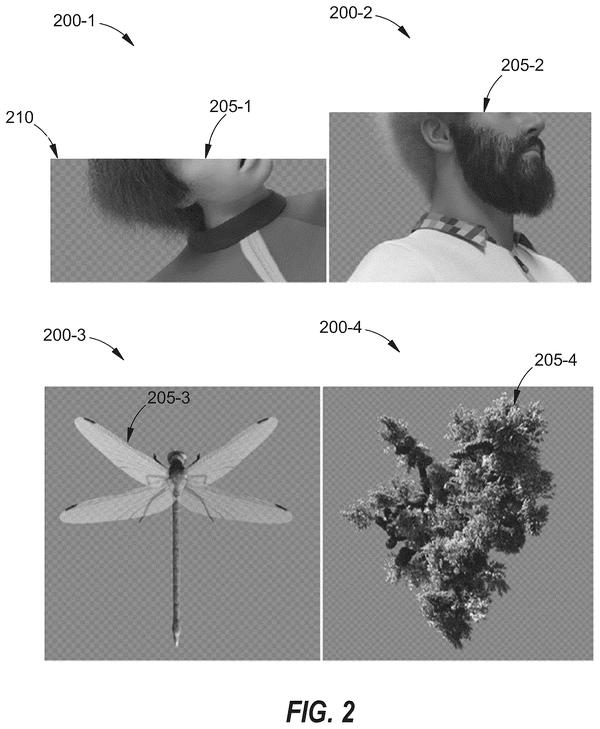
Several companies are filing on ways to cut things out of photos and fill the empty space convincingly. The approaches range from cutting at multiple detail levels to finishing objects that were cut off at the edge of the frame.
These filings cover ways to correct color and lighting problems, from faces shot against bright windows to scenes lit by two different light sources at once. The approaches differ but the goal is the same: make the colors look right without the person having to fix them by hand.
These filings tackle AI-generated or AI-processed video looking jumpy or flickery from one frame to the next. Each approach to the fix is different, but all of them target the same visual glitch.
Teaching AI With Examples Instead of Instructions 14 filings
Google 6, Samsung 3, Disney 1
These filings cover ways to train image and video AI by showing it examples rather than writing out rules. The AI learns what good output looks like by studying real photos or videos, which can make it better at tasks like sharpening, restoring, or matching a style.
Controlling What AI Generates With Words 21 filings
Google 13, Adobe 7, Meta 1
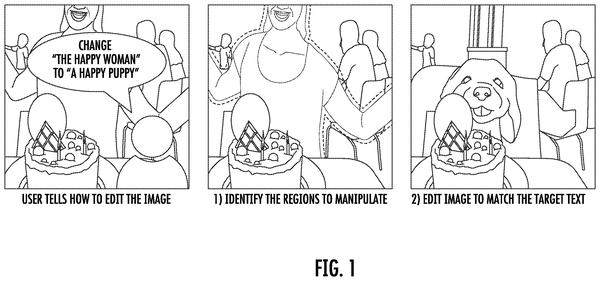
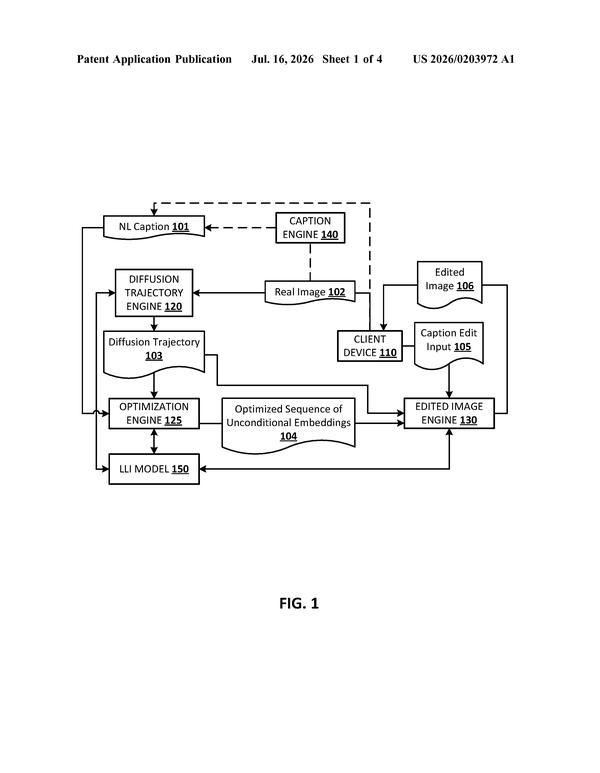
These filings let people describe what they want in plain words and have the AI follow those instructions precisely, including editing existing photos by rewriting their text description. They cover everything from matching words to image details to keeping brand styles consistent.
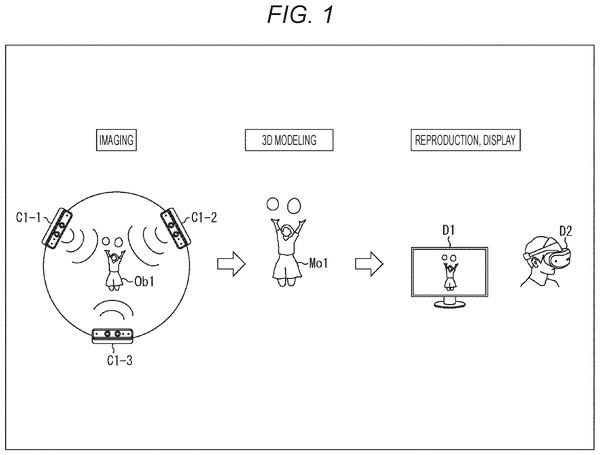
These filings build a three-dimensional model of an object or scene from ordinary flat photos or video. They cover everything from single objects to full scenes with moving parts, pointing to a broad push to make 3D creation possible without special equipment.
Photo tools that read the picture and offer edits before you ask: swap options, keyword taps, self-written suggestions, or a filter picked by what is in the shot.
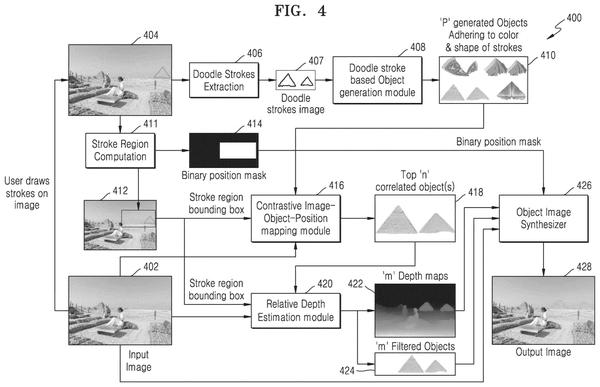
Filings that change the story of a picture: rewind or fast-forward objects, fill in missing elements, change how close a subject looks, or turn a sketch into a photo.
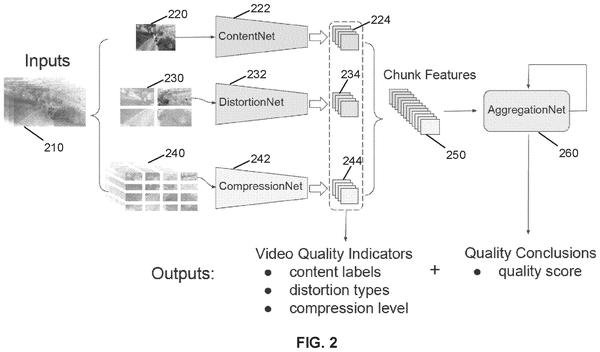
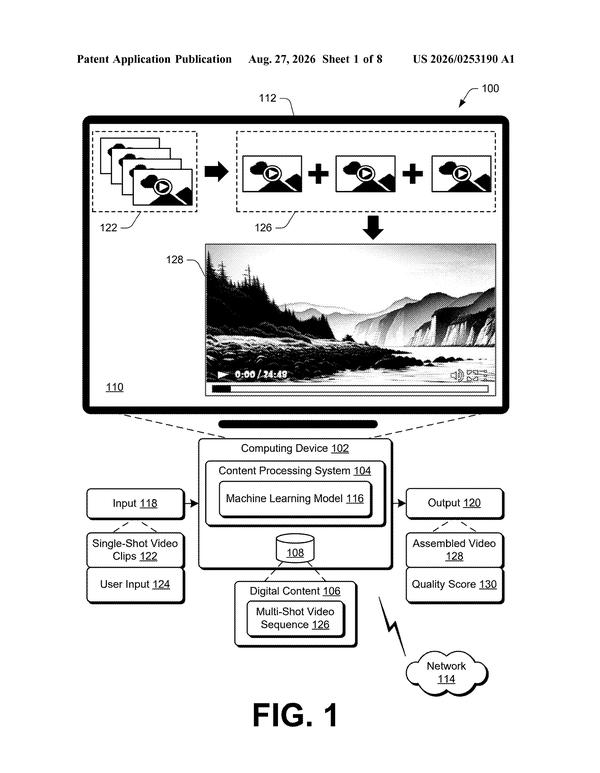
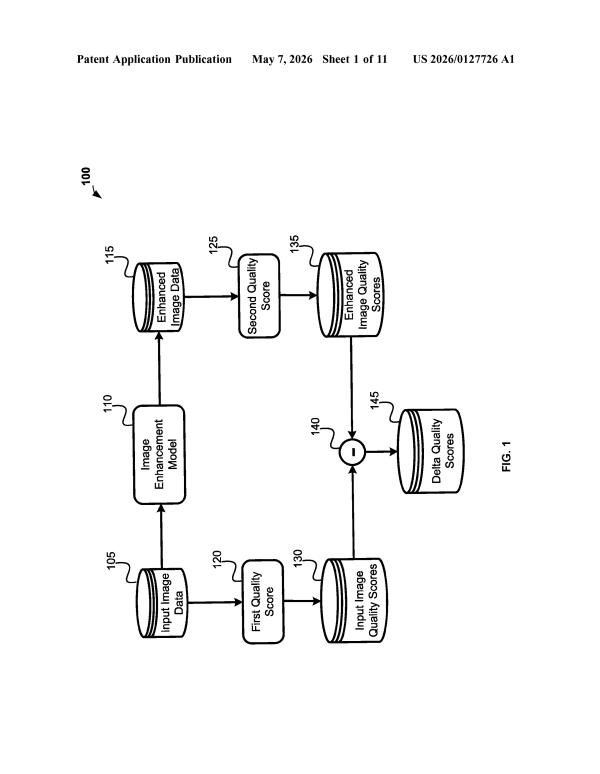
A learned model that scores video quality across interest, artifacts, and compression levels, automating the human review step that currently slows down distribution decisions.
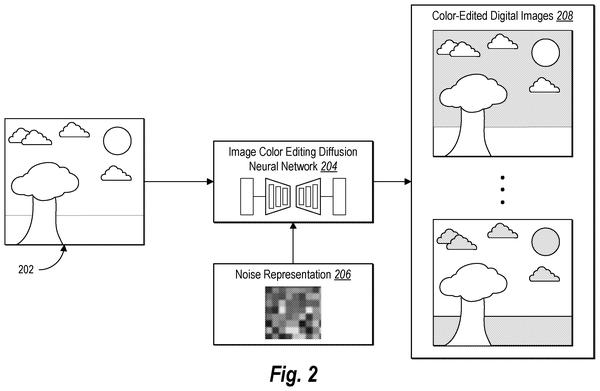
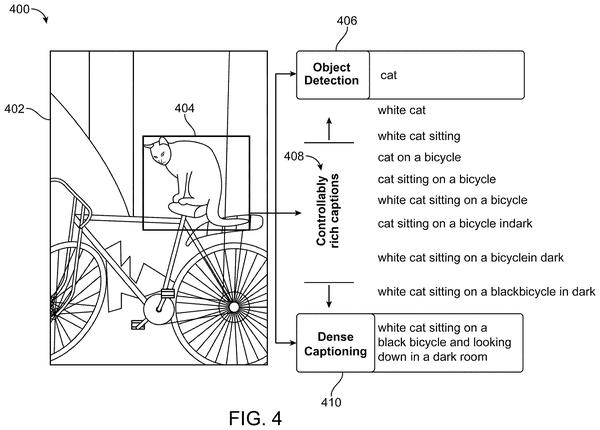
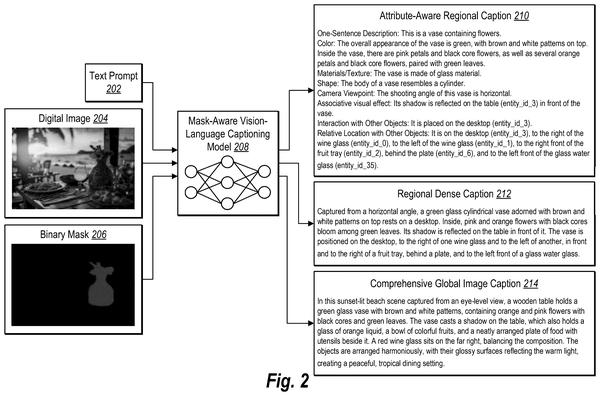
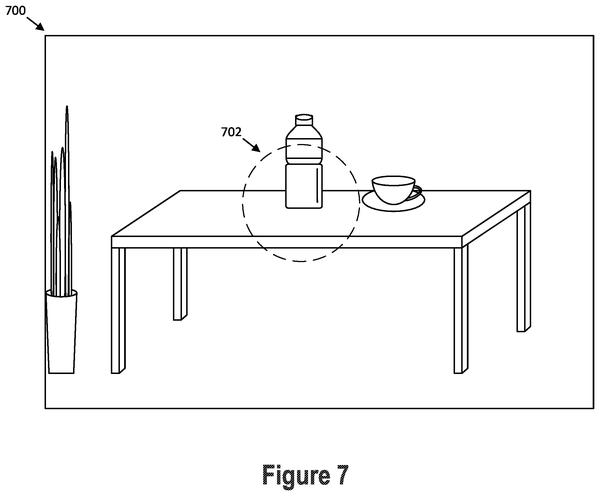
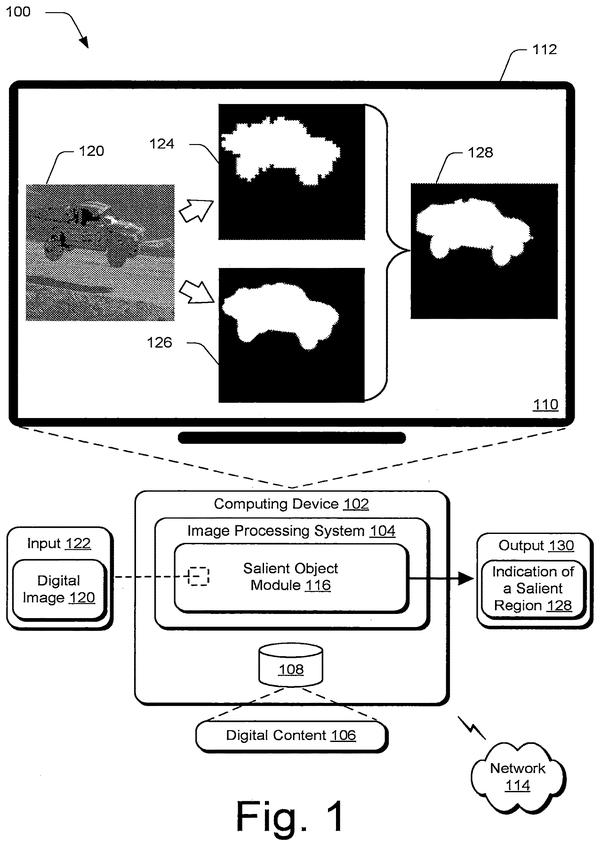
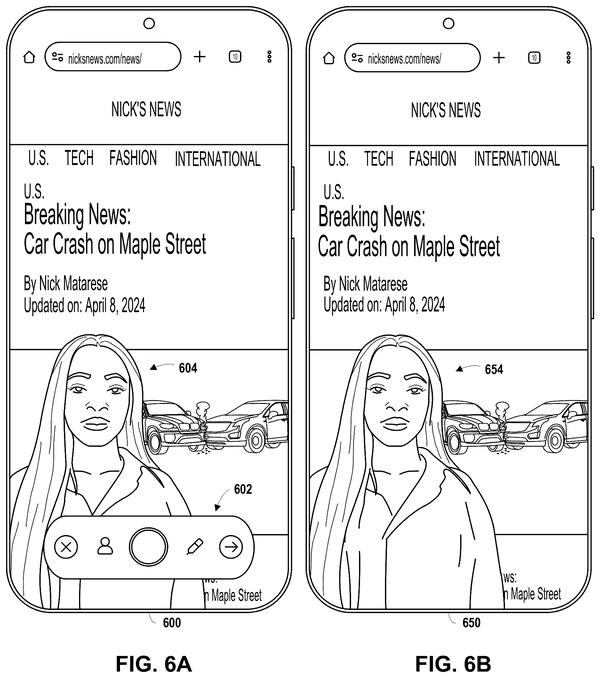
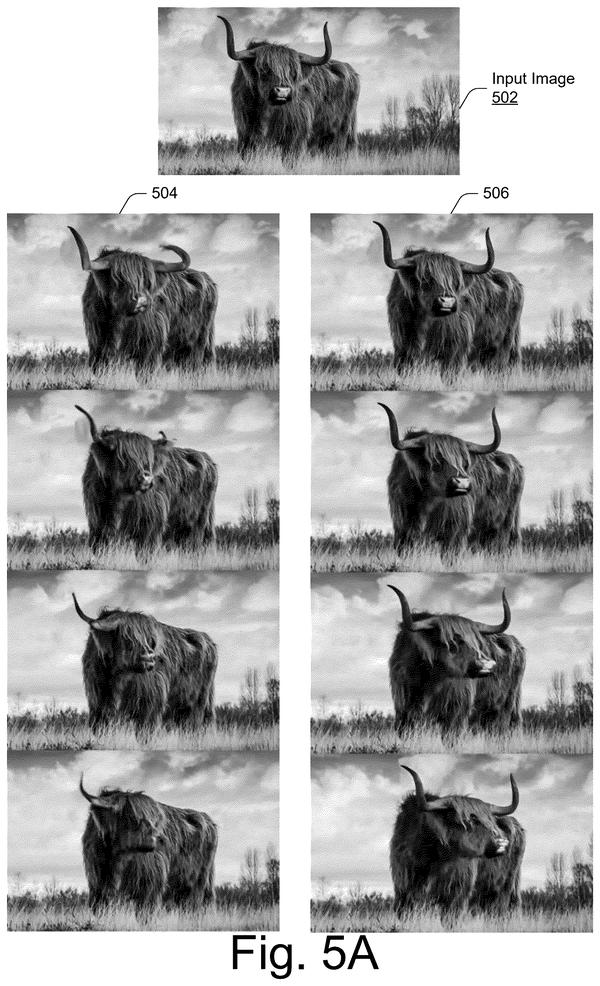
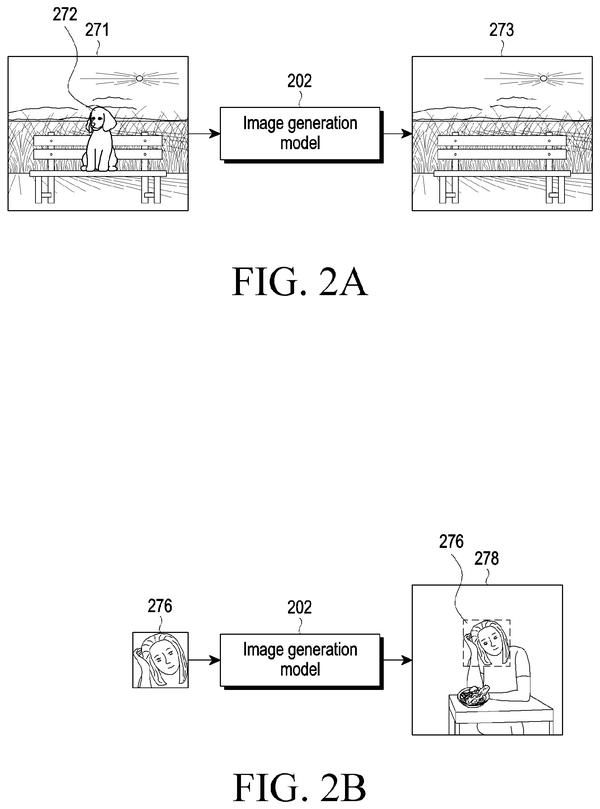
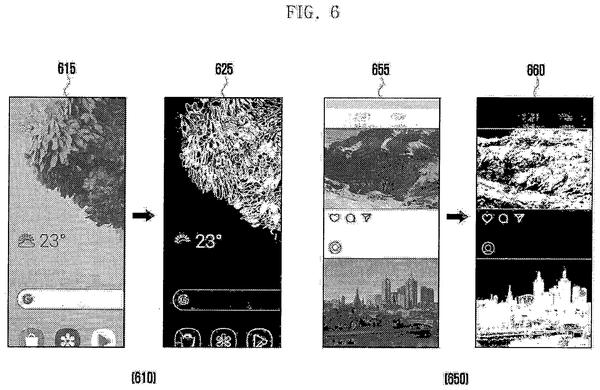
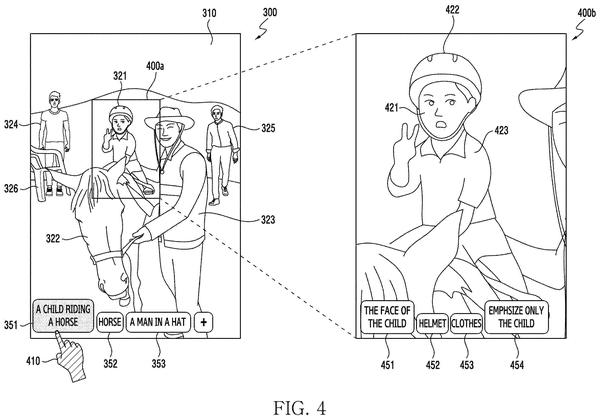
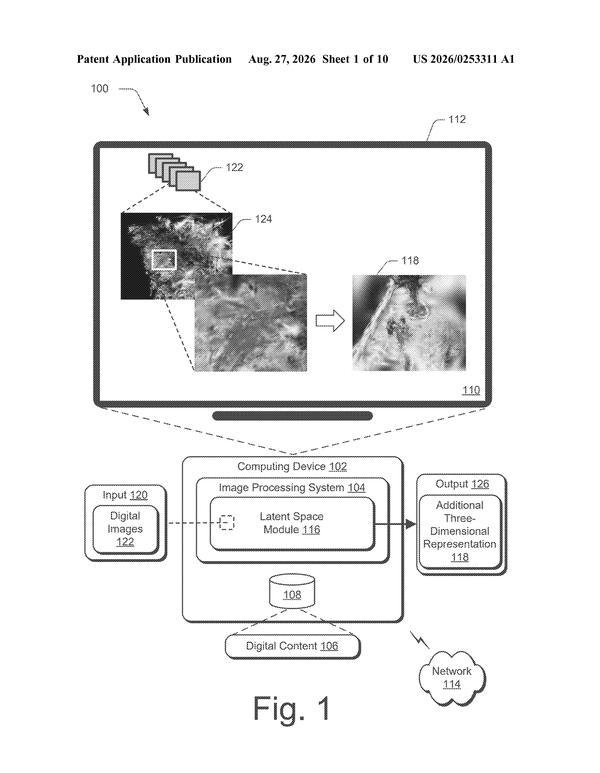
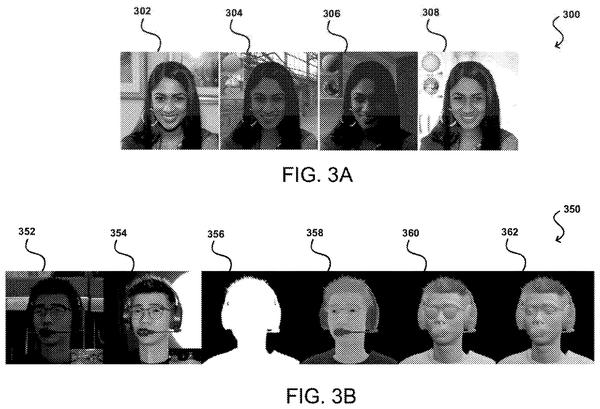
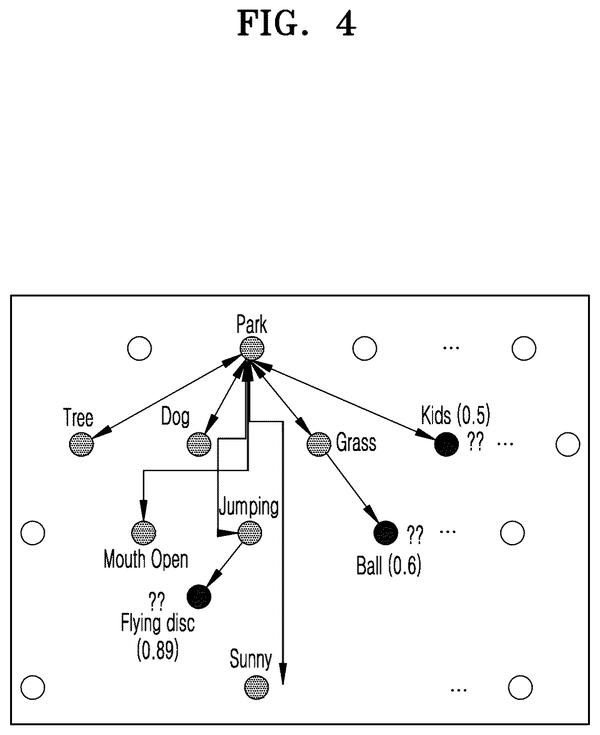
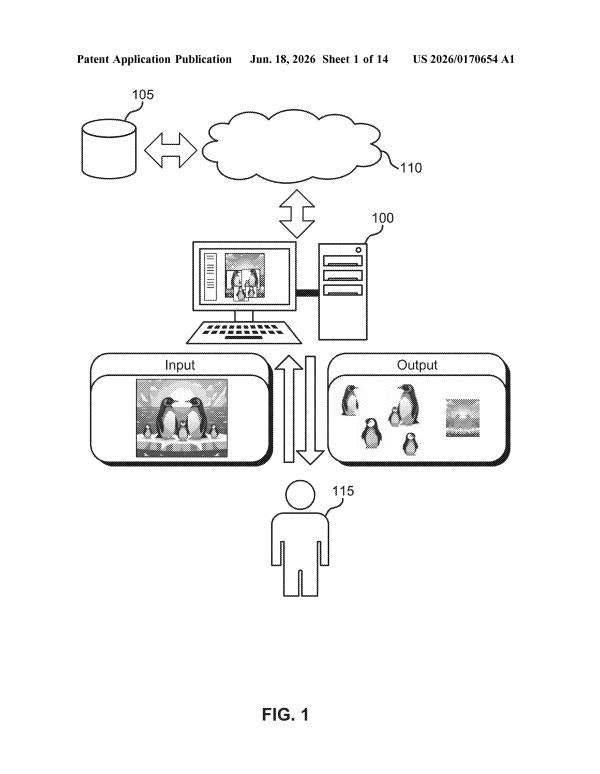
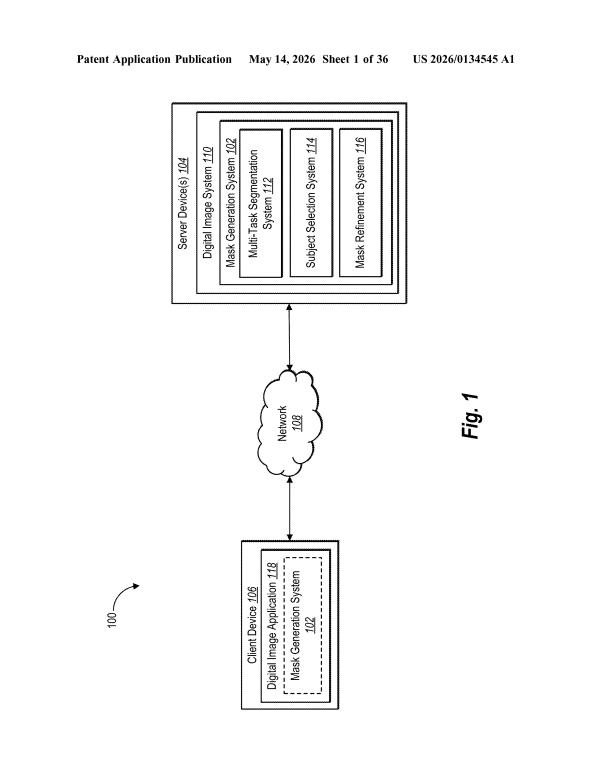
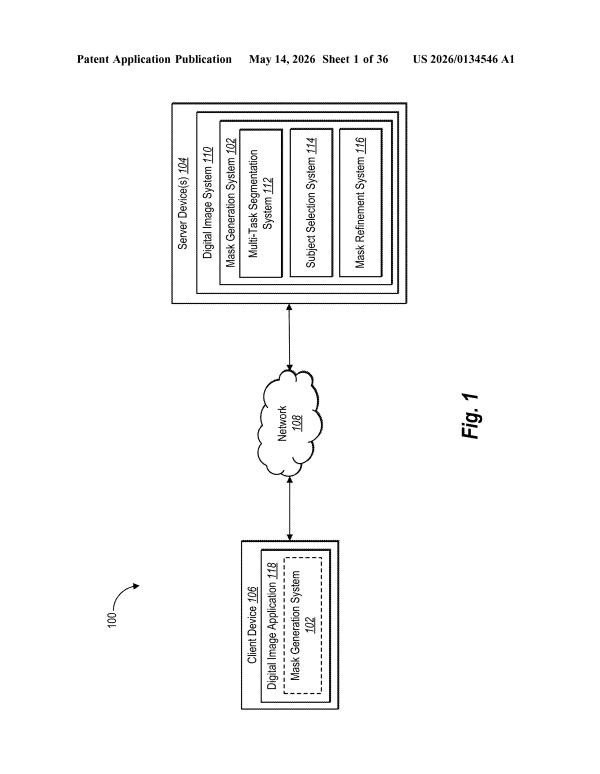
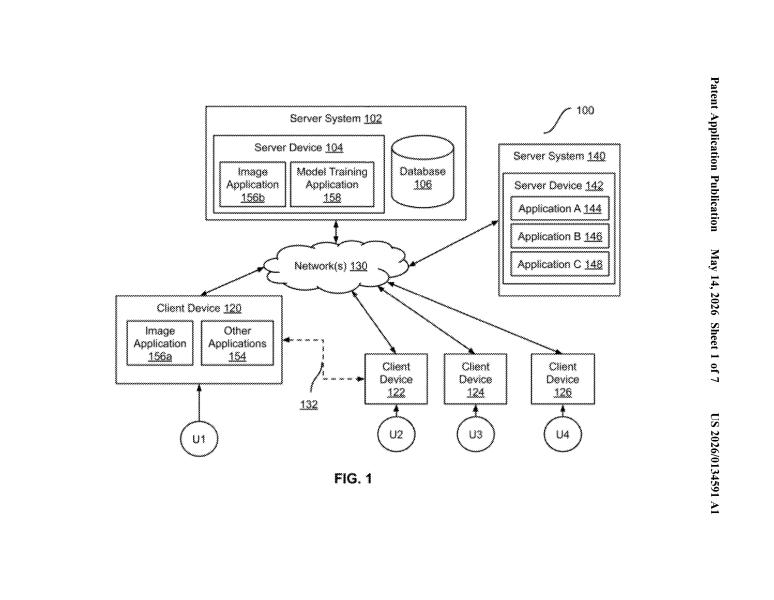
Confirms the tracker's coverage of region-specific edits by showing Google's work on isolated object captioning, the system identifies and describes only user-selected areas rather than full images, extending AI control to granular spatial selection.
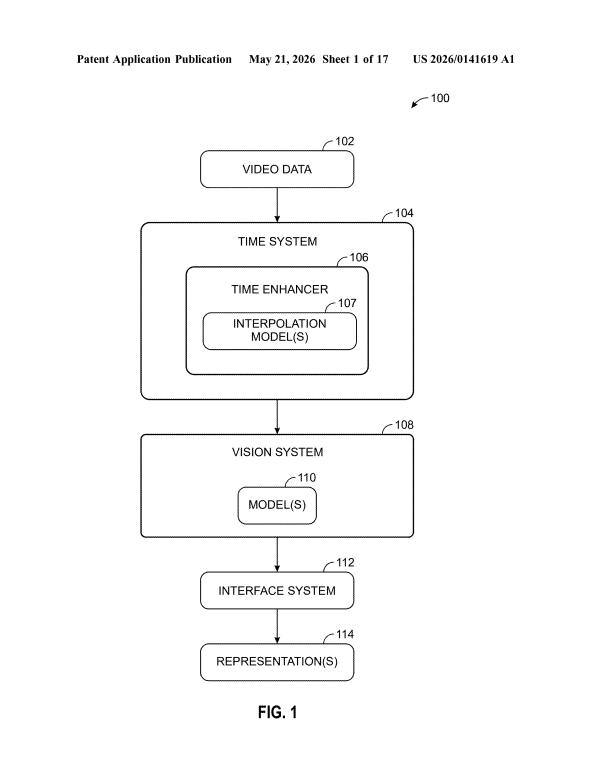
The race has centered on text guidance and regional control; Microsoft now targets the speed bottleneck by running AI sharpening on sparse frames and interpolating between them for real-time playback.
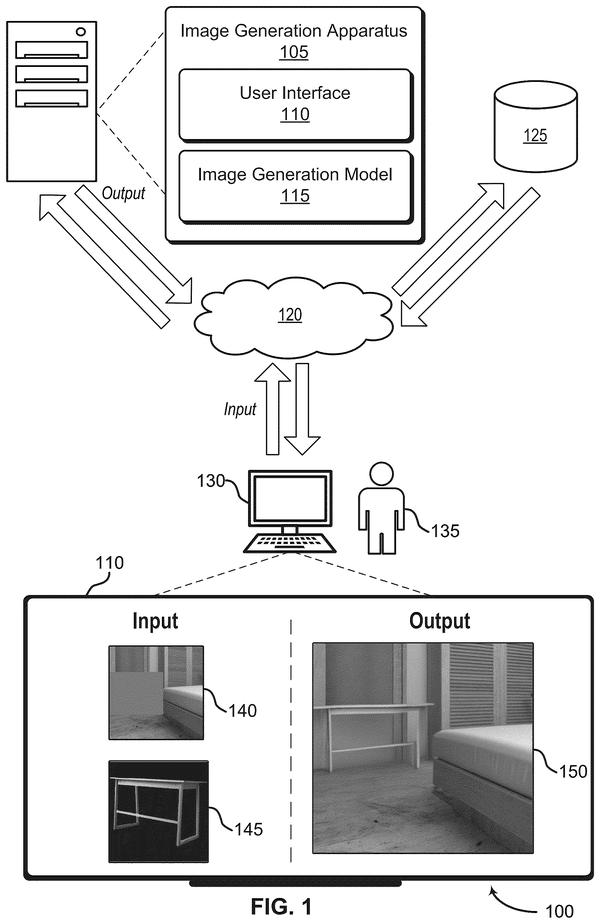
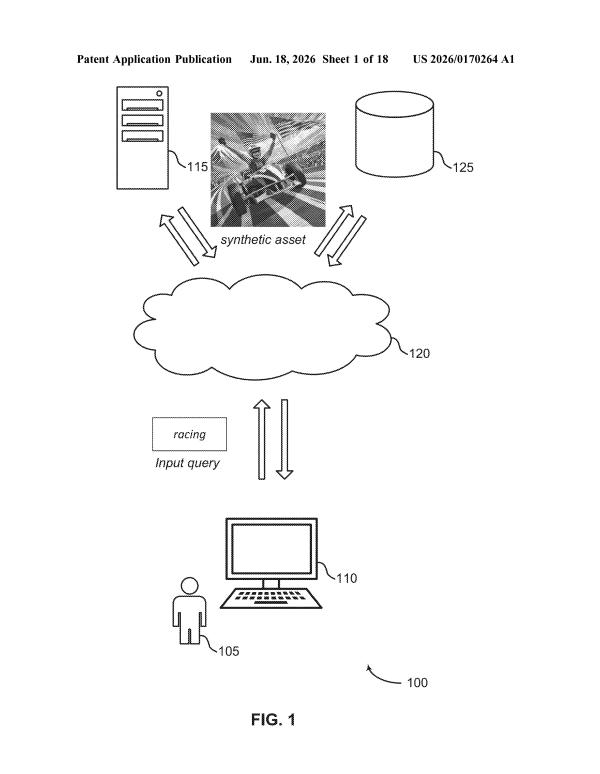
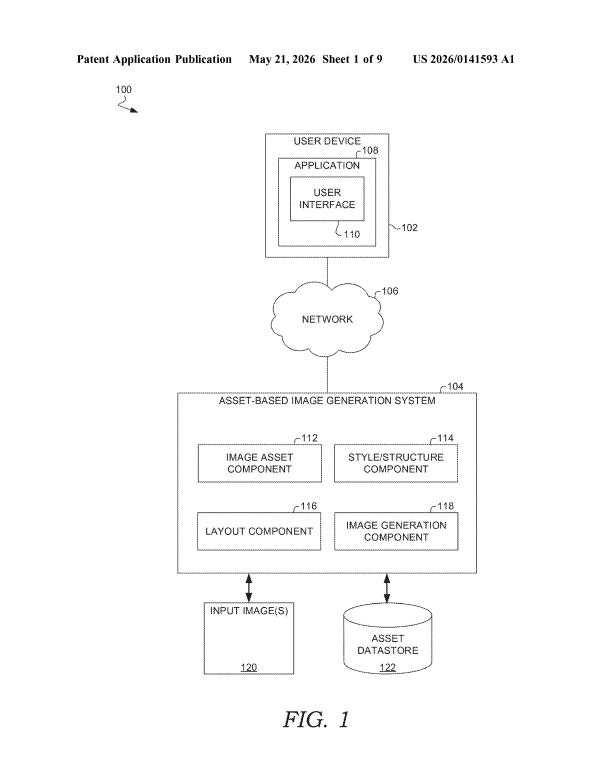
Google moves beyond editing individual product shots to generating full lifestyle scenes around them, eliminating the photographer and model costs that currently gate visual variety in e-commerce.
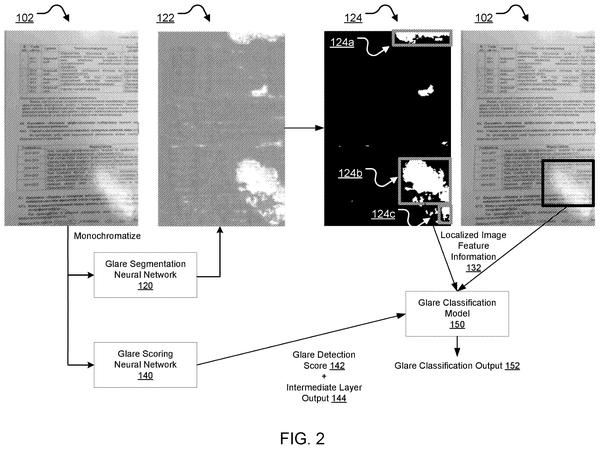
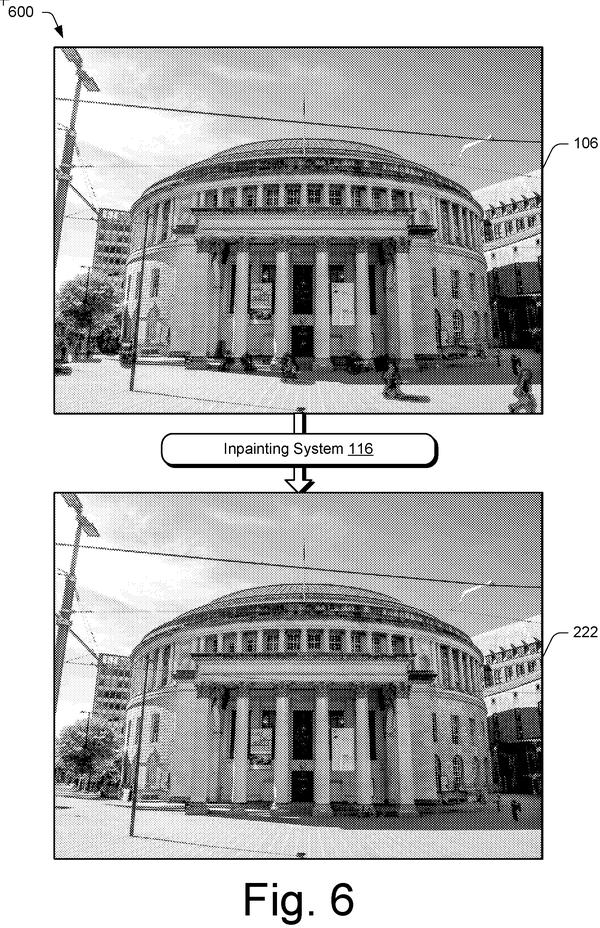
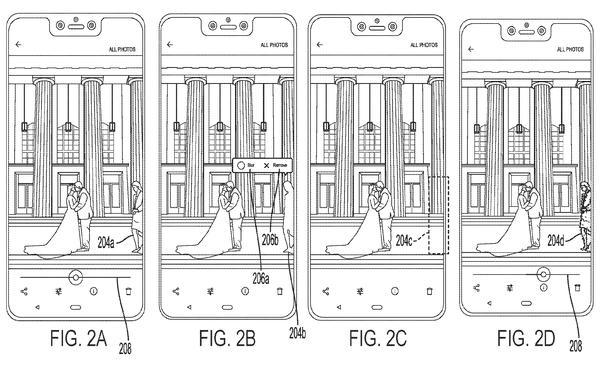
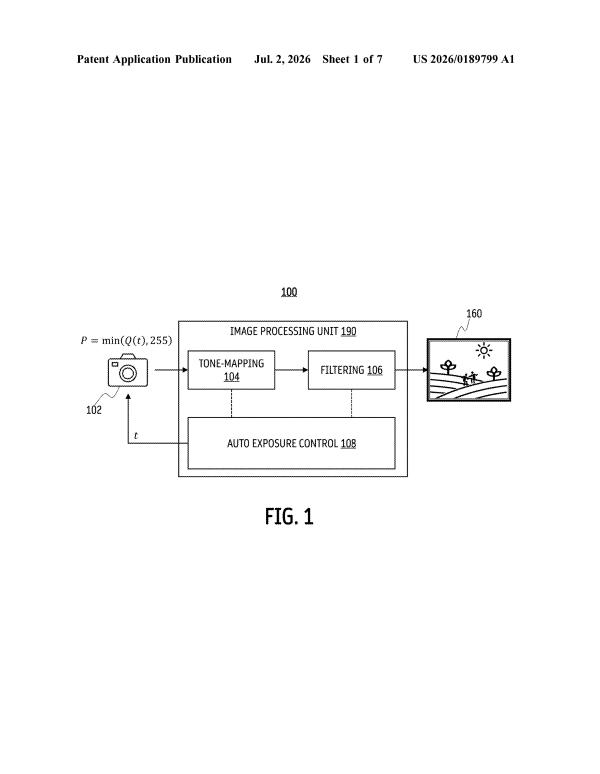
Detecting glare on document scans by analyzing overall image brightness and isolating peak highlights extends the editing toolbox beyond color and layout toward capture quality repair.
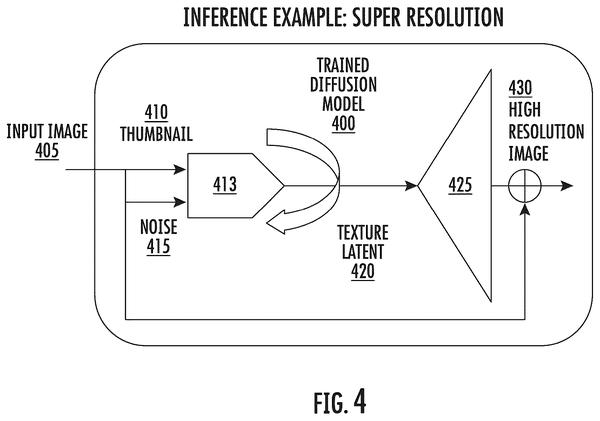
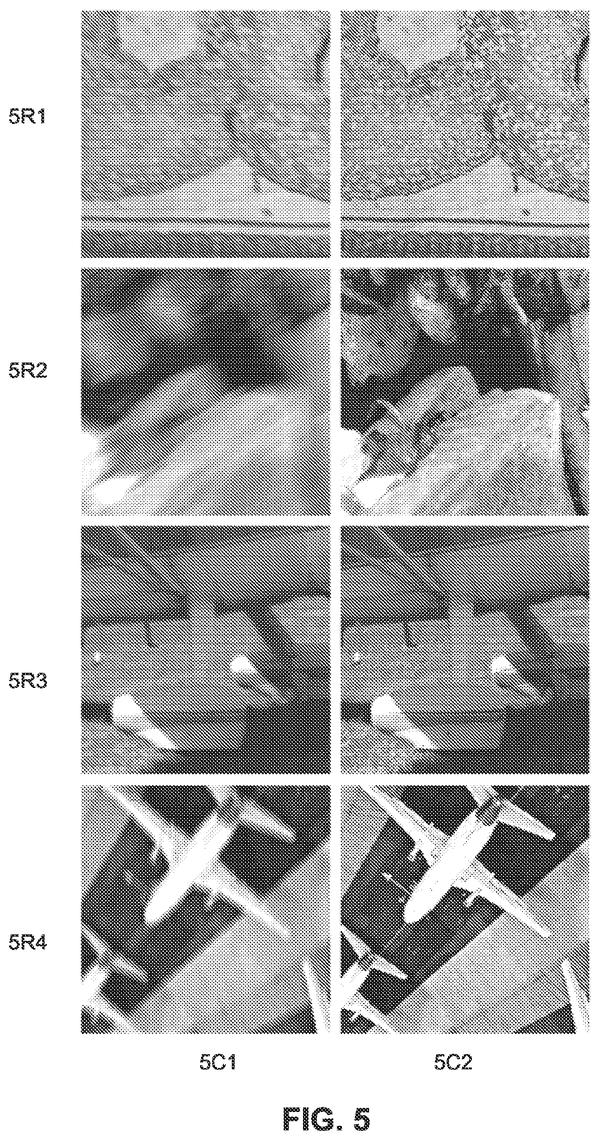
Splitting deblurring into separate passes on thumbnail and texture layers lets phones do the heavy lifting without draining the battery as fast as full-image processing would.
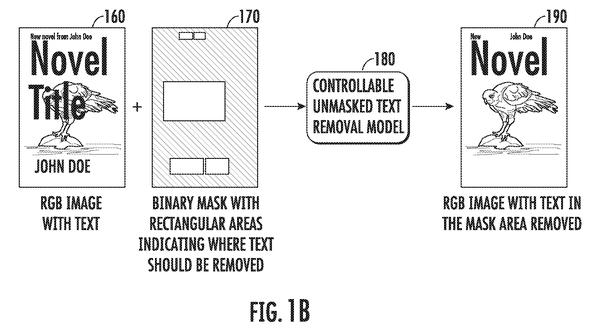
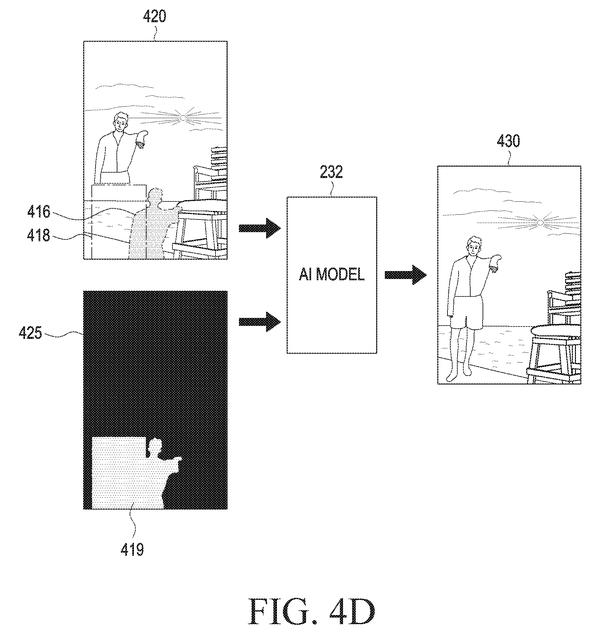
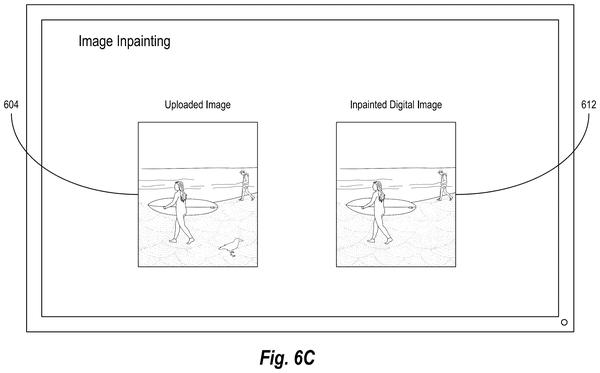
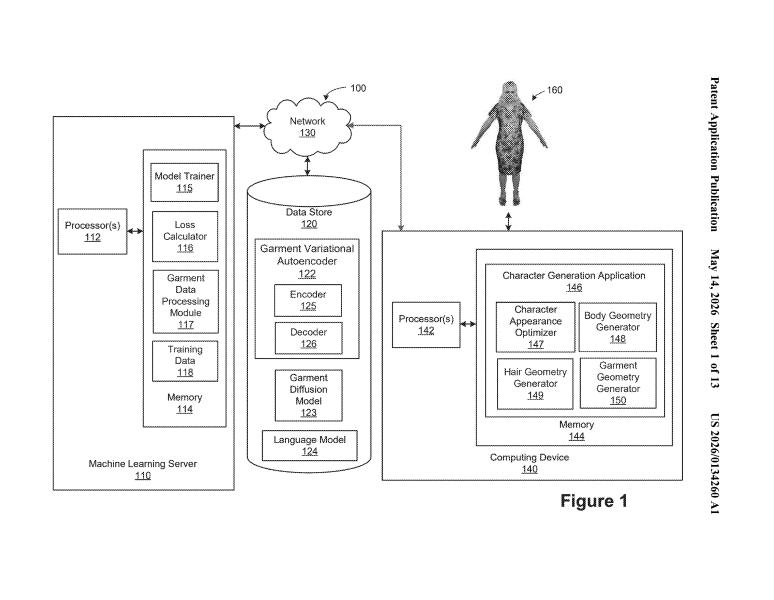
Within the broader race on photo editing, Google moves past the bottleneck of needing hand-paired training data by having the AI generate its own clean reference images for text removal, crucial for real-time translation overlays.
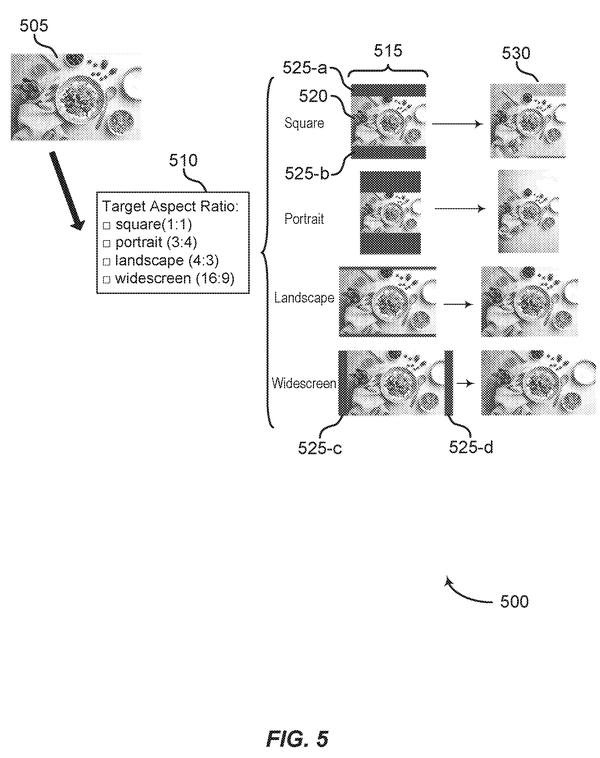
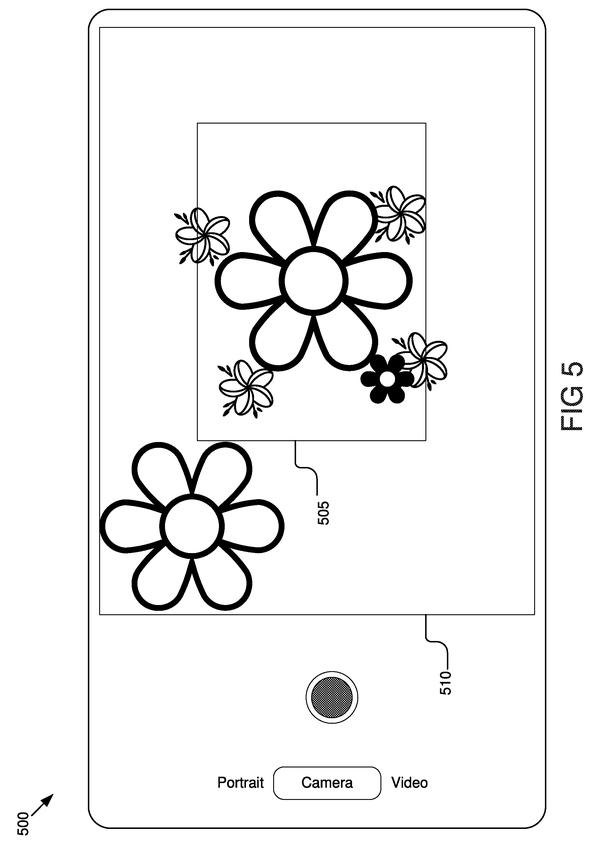
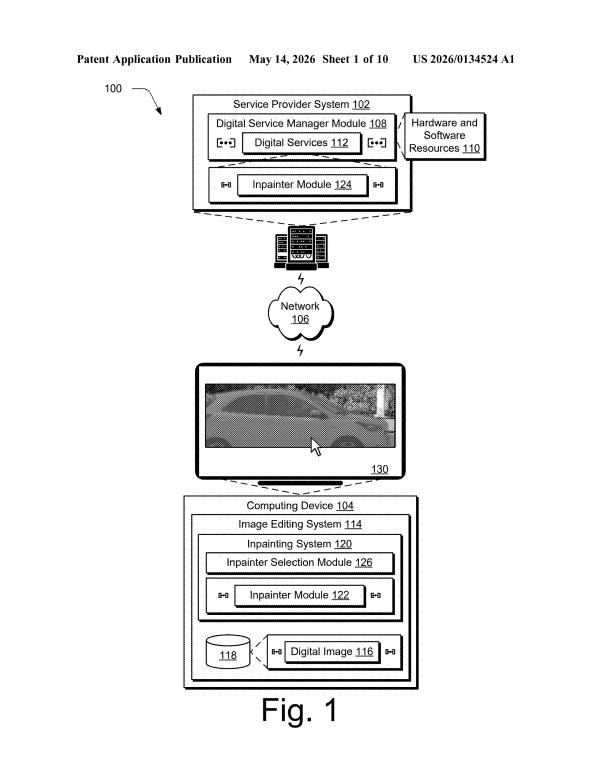
The race to automate canvas expansion, filling empty space when you reframe a photo, now includes Adobe's one-click approach, which generates missing edges after you select an output format and reposition the original image.
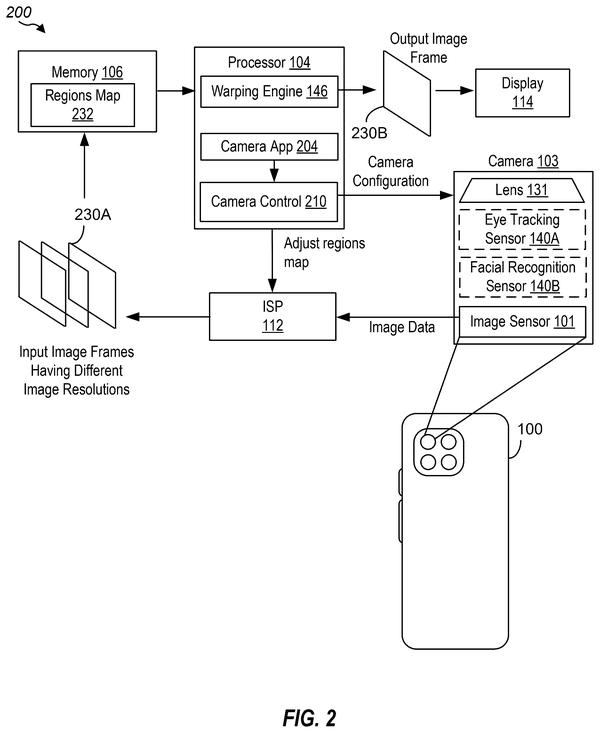
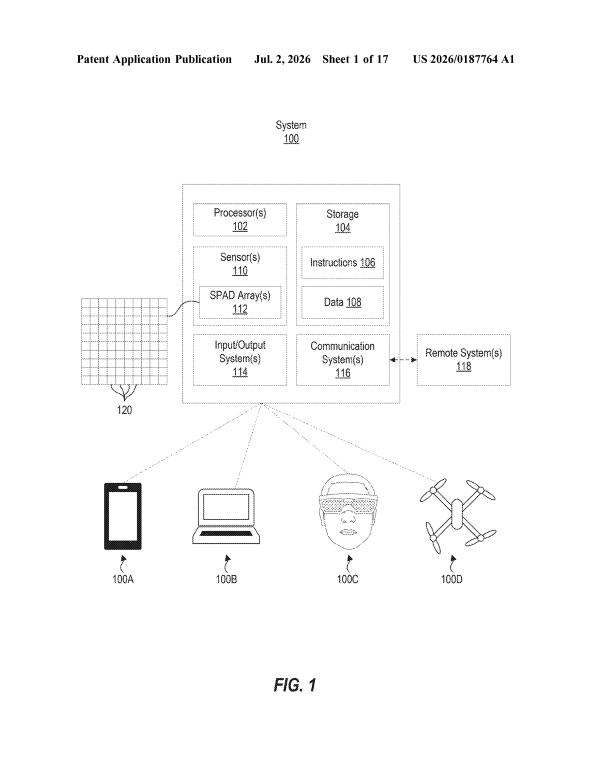
The race so far has focused on regional edits and color control, but Samsung's filing shifts toward fixing what zoom itself destroys: restoring texture detail that gets smoothed away during heavy cropping and magnification.
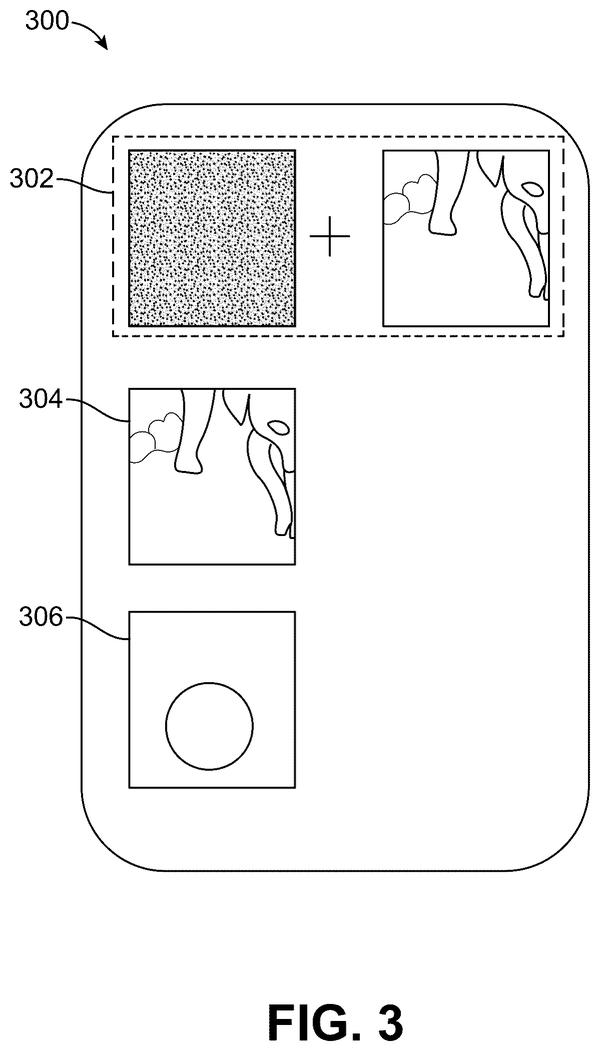
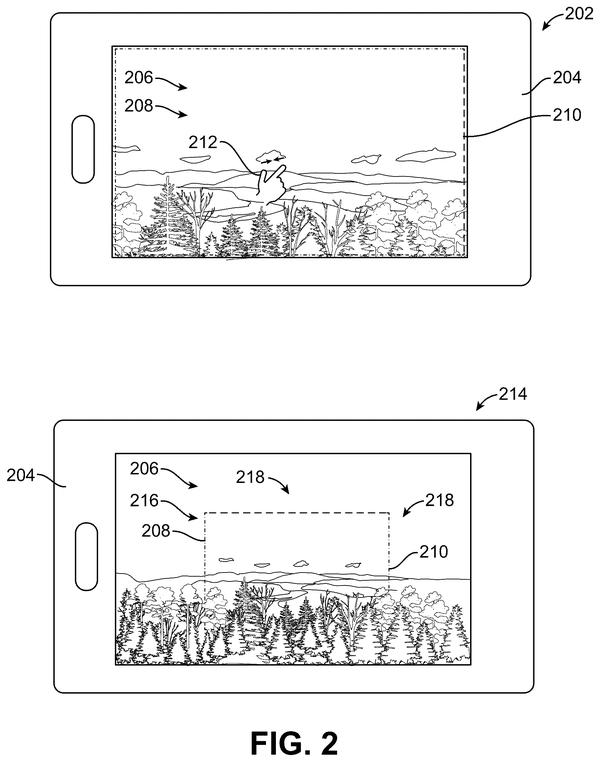
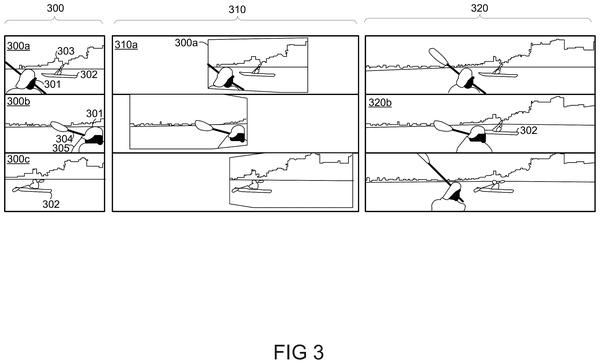
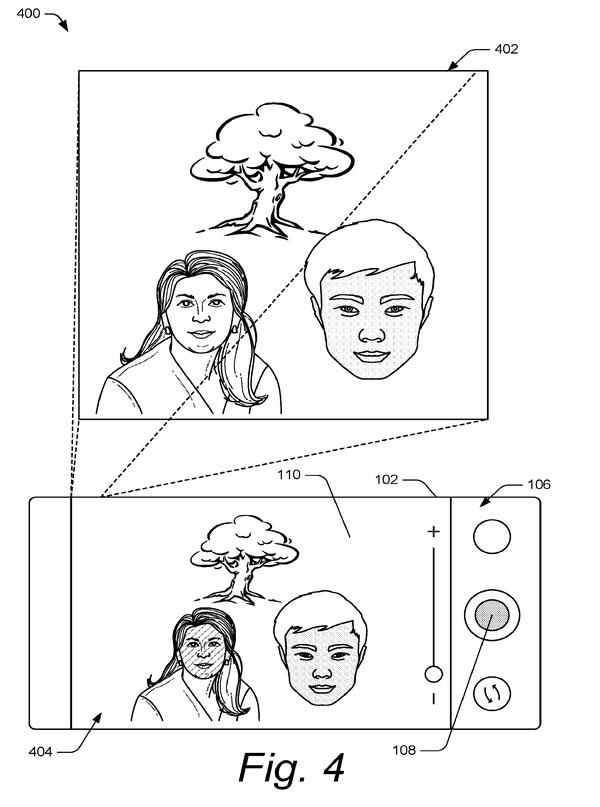
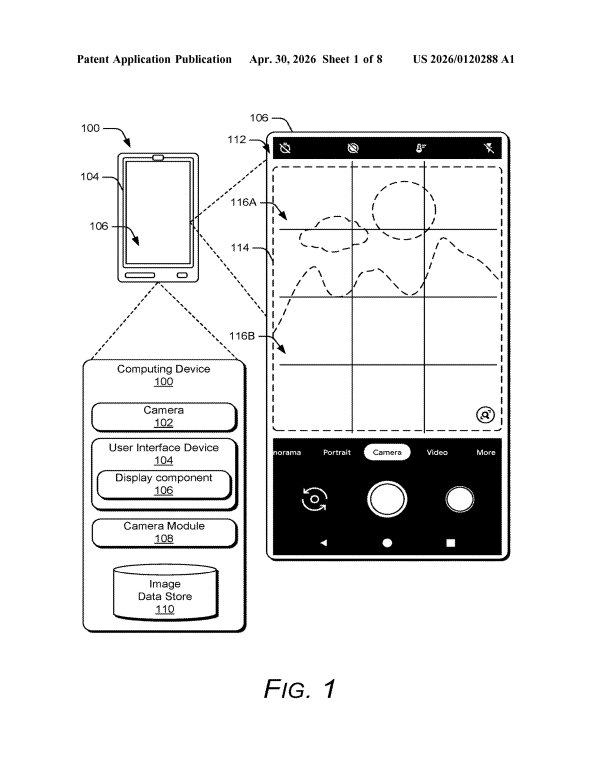
Storing the original wide frame alongside the cropped preview lets users override the phone's initial subject choice when editing, shifting focus selection from a one-time capture decision to a post-shoot adjustment.
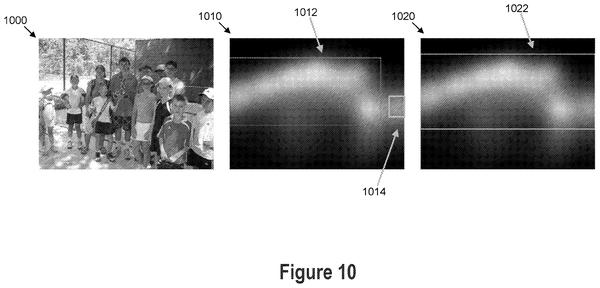
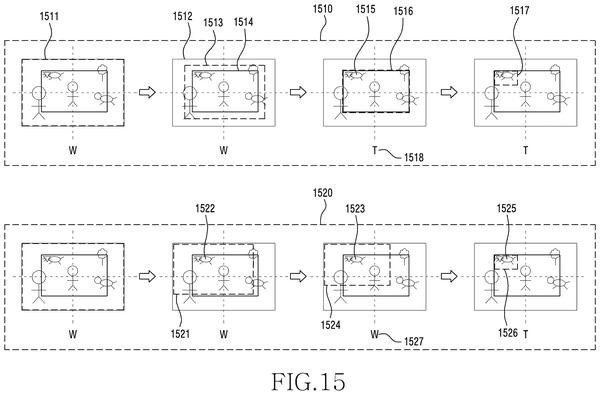
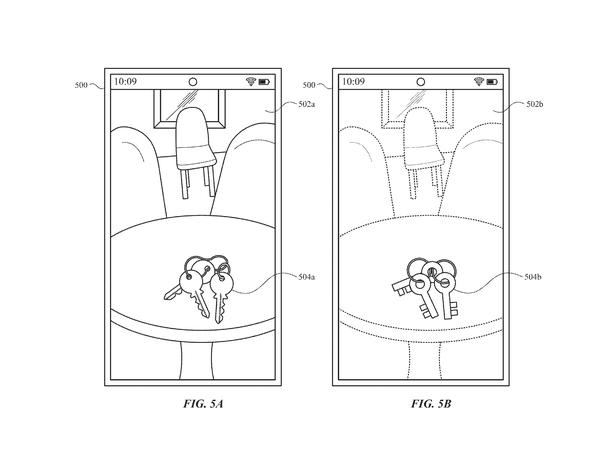
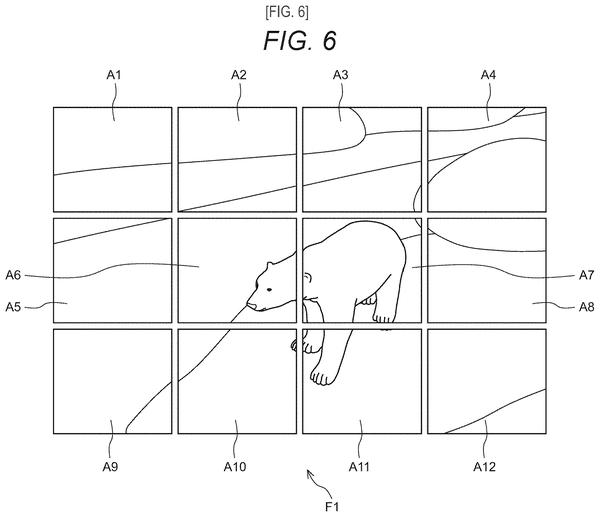
Detecting faces at frame edges lets the camera preserve them during zoom instead of guessing where to crop, solving the common problem of losing people at the sides of group shots.
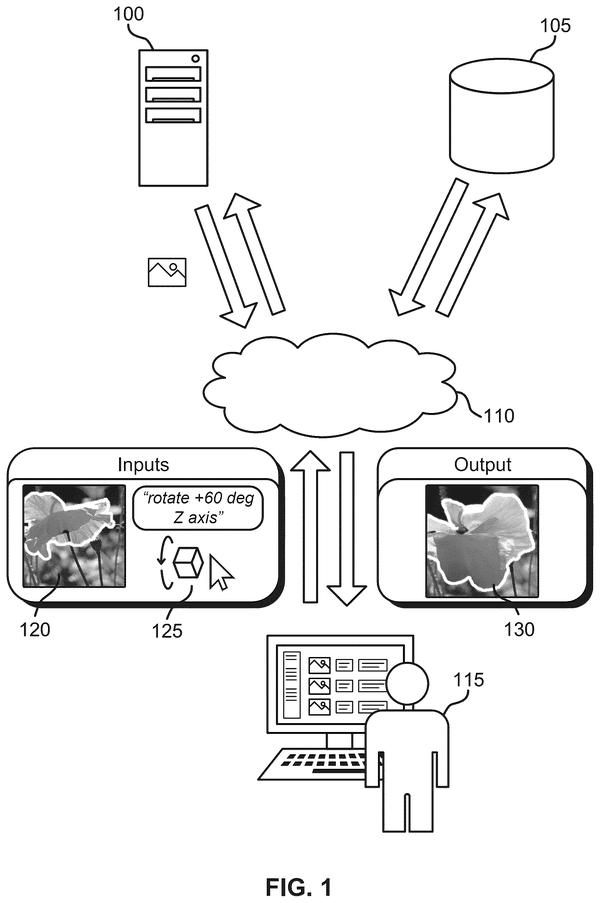
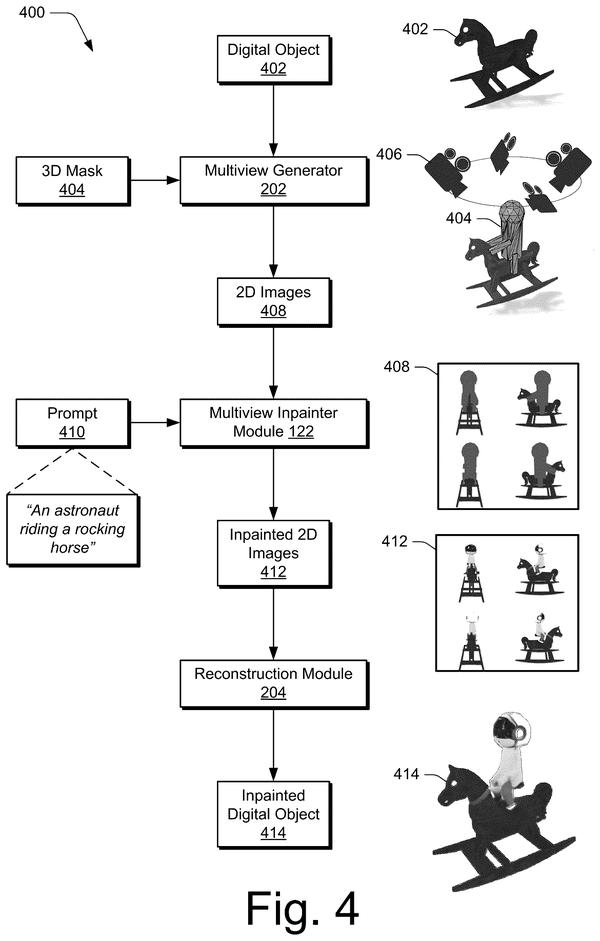
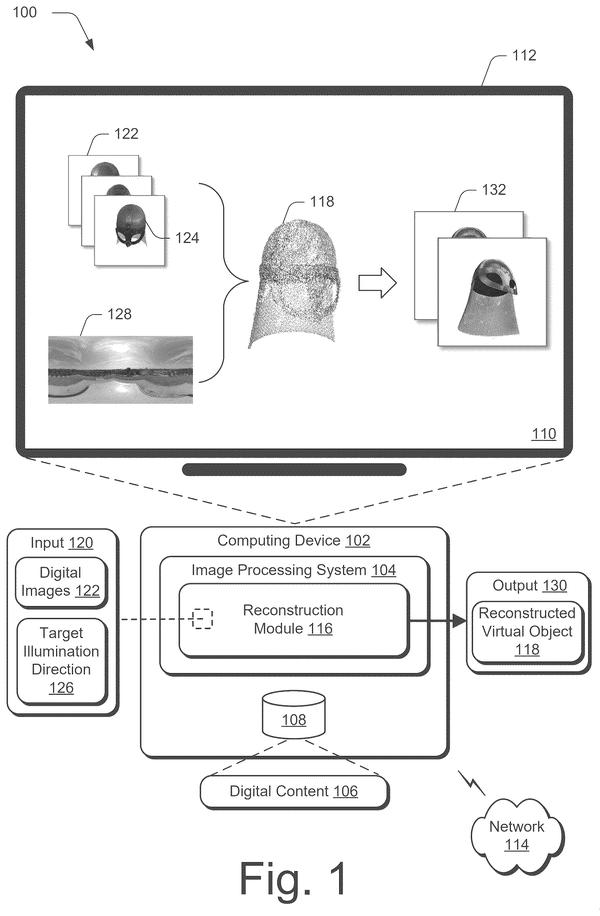
Reconstructing unseen surfaces from a single image via 3D geometry lets editors rotate objects to reveal hidden angles, extending AI photo editing beyond what the camera captured.
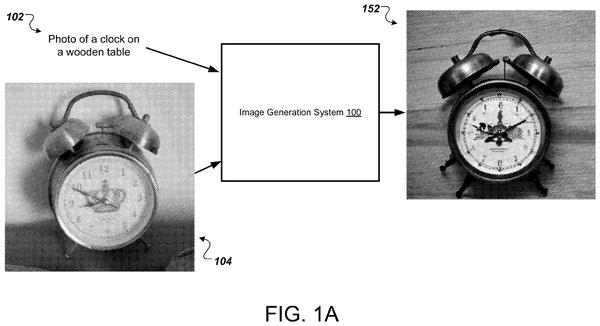
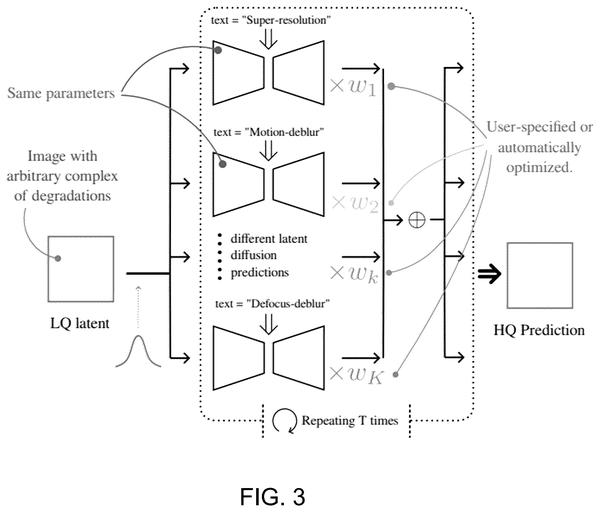
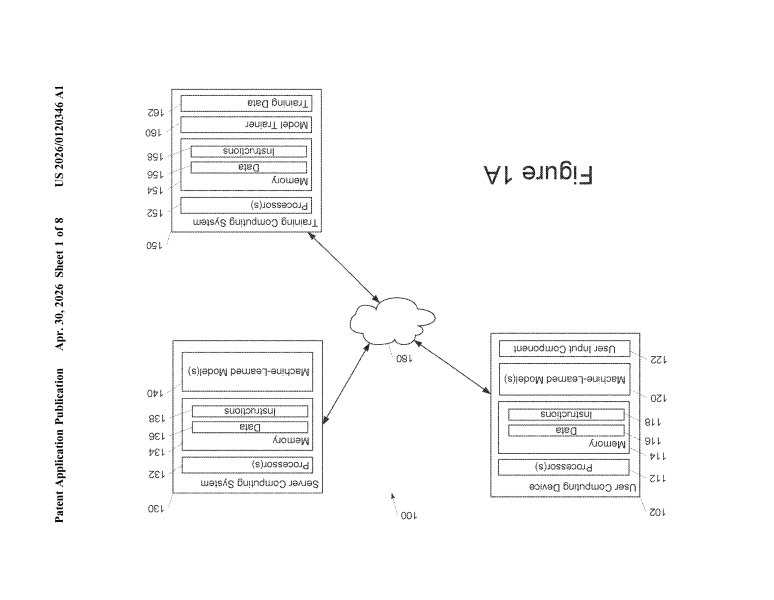
Users could fix multiple damage types (blur, grain, compression artifacts) in one pass instead of running separate tools. Google's approach trains a single model by having specialist networks teach it, sidestepping the scarcity of real paired training data.
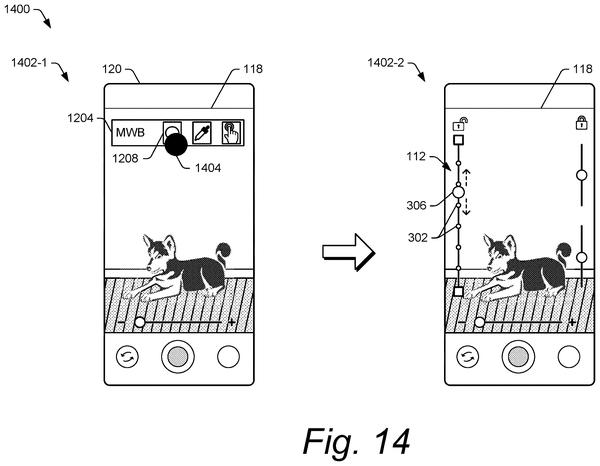
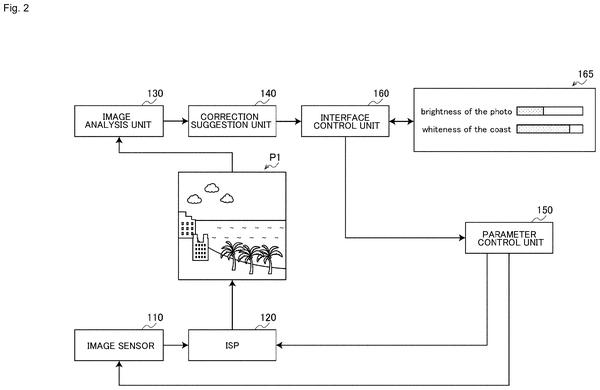
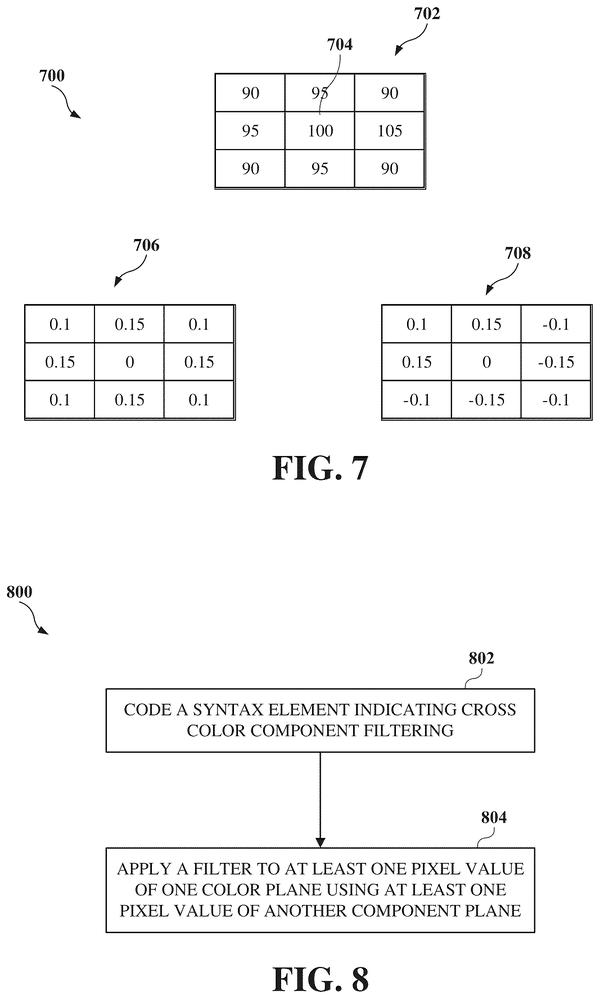
Users could dial in skin tones or correct color casts in real time rather than picking from preset categories that rarely match actual lighting. This extends the tracker's coverage of per-region color control into the camera pipeline itself.
Users can remove objects by describing them in text, but the filled-in background needs to look natural. Qualcomm's filing shows how to train the AI using paired photos of the same scene to grade its reconstruction work.
Photo inpainting on-device requires shrinking models that typically live on servers. Qualcomm's approach uses a large teacher model paired with intentional noise injection to train smaller versions that can run directly on phones.
Users get preset filters that adapt to what's actually in the frame instead of applying the same color shift everywhere. Confirms the tracker's focus on context-aware edits over one-size-fits-all adjustments.
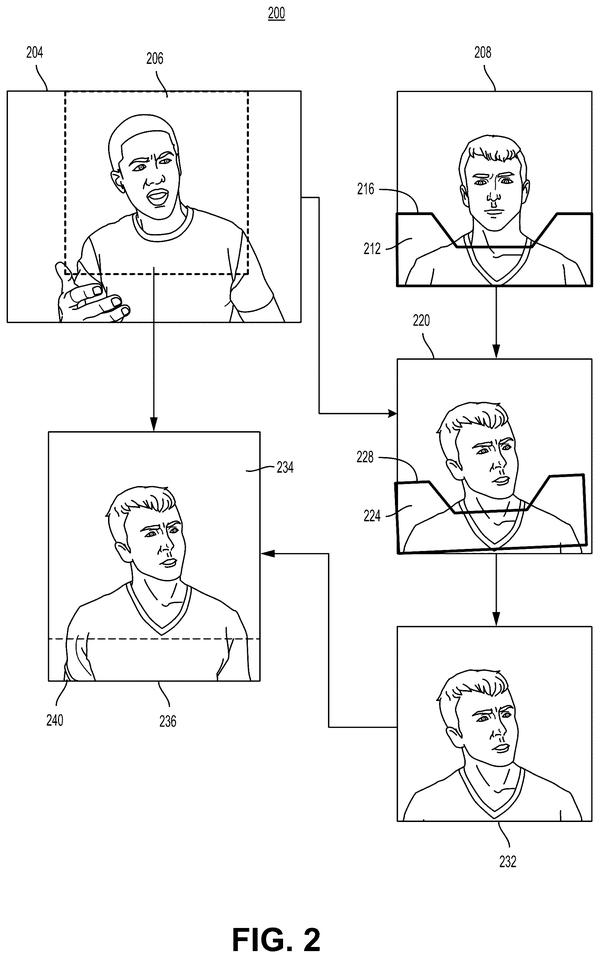
Users editing selfies could correct perspective distortion without sacrificing fine details like jewelry or skin texture, moving beyond simple face-shape corrections into optical geometry fixes.
Syncing audio edits to mouth movements in real time shifts the challenge from speech cleanup alone to maintaining visual continuity during live playback, extending the race beyond static image retouching into dynamic video correction.
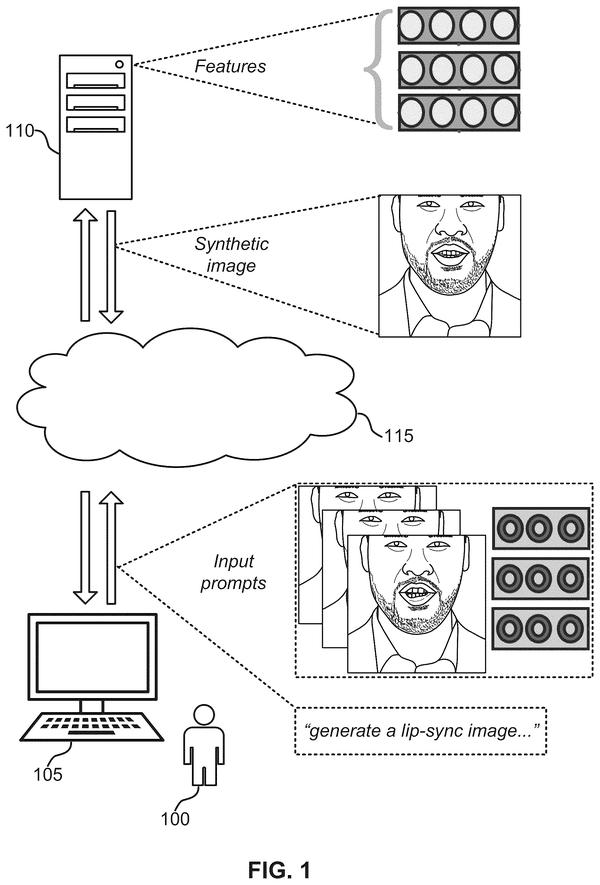
Mouth sync in dubbed video usually flattens an actor's distinctive speech habits. This filing proposes redrawing lips to match new audio while preserving individual quirks like smile timing and vowel shapes.
Users could fix flubbed dialogue without re-recording, shifting video cleanup from post-production specialists to automated speech rewriting paired with lip-sync regeneration.
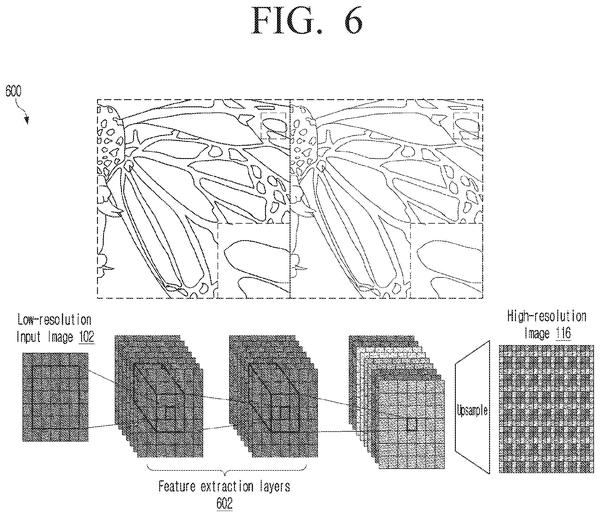
Users zooming into old photos would get usable detail instead of mush. Adobe's approach reconstructs from multiple reduced copies simultaneously, cutting processing time while reducing the hallucinated artifacts that single-image methods produce.
Camera motion in generated video exposes inconsistencies across viewing angles. Adobe's approach uses multiple reference photos to maintain coherent geometry when zooming or panning around a figure.
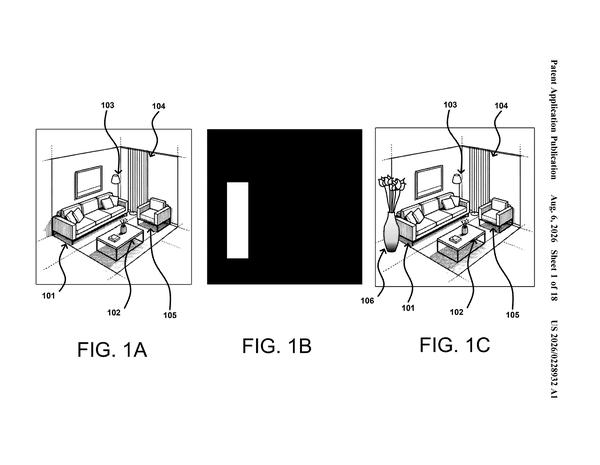
Users pasting objects into scenes can skip manual shadow and relighting work, letting the AI handle geometry rotation and lighting consistency in a single operation.
Adobe's automation layer extends beyond which tool to use: the system now routes removals based on device power and connection speed, picking faster methods on constrained hardware.
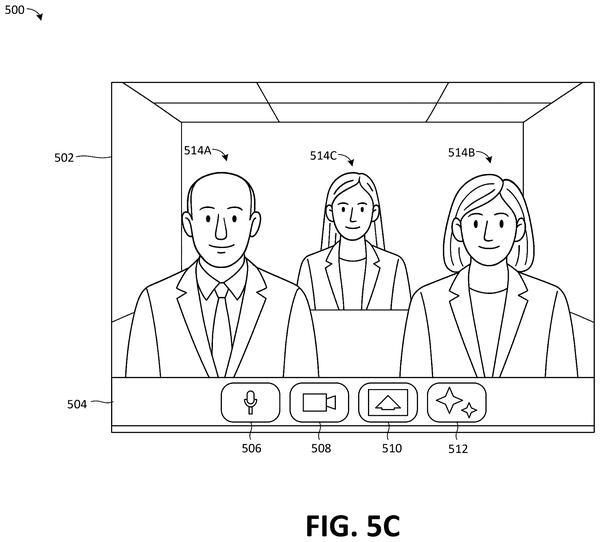
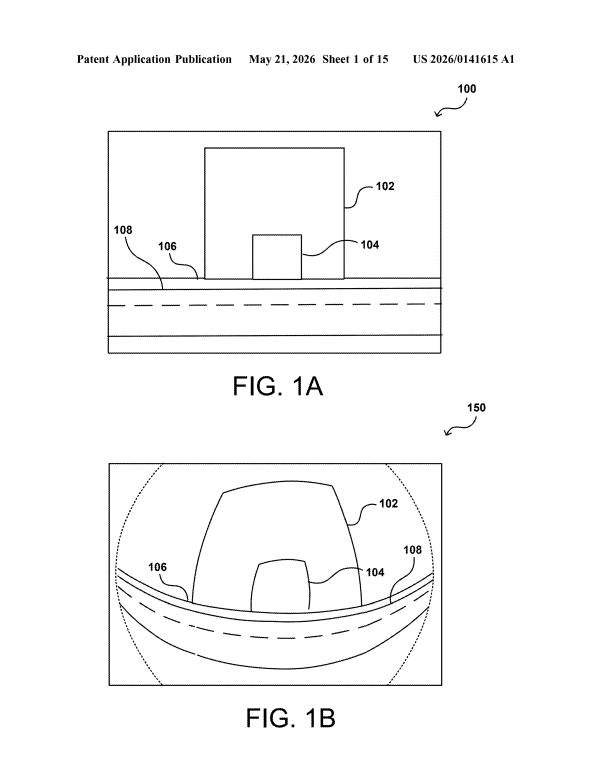
Live video redrawing to normalize distances in wide-angle conference room feeds, so remote participants see balanced framing instead of proximity-based size distortion.
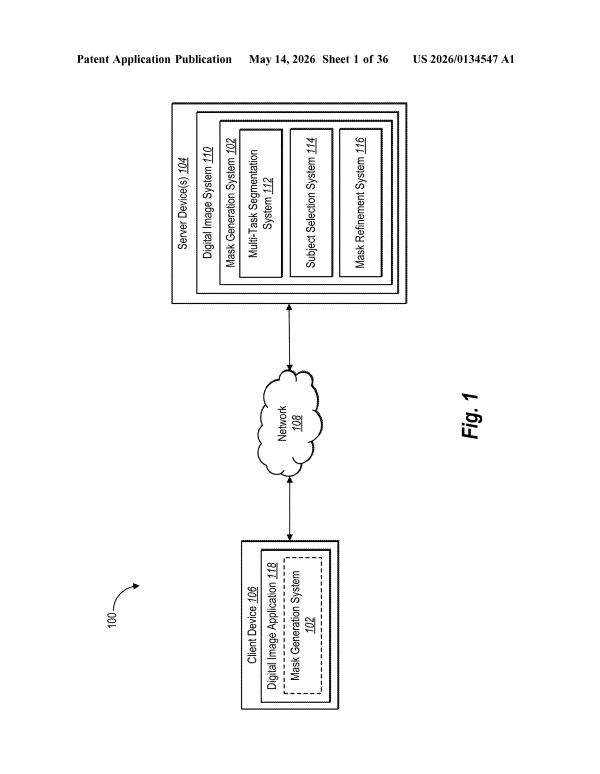
Google and Nvidia have focused on guided edits and compression; Adobe pushes toward isolating subjects more precisely by analyzing photos at multiple scales before merging results into sharp boundaries.
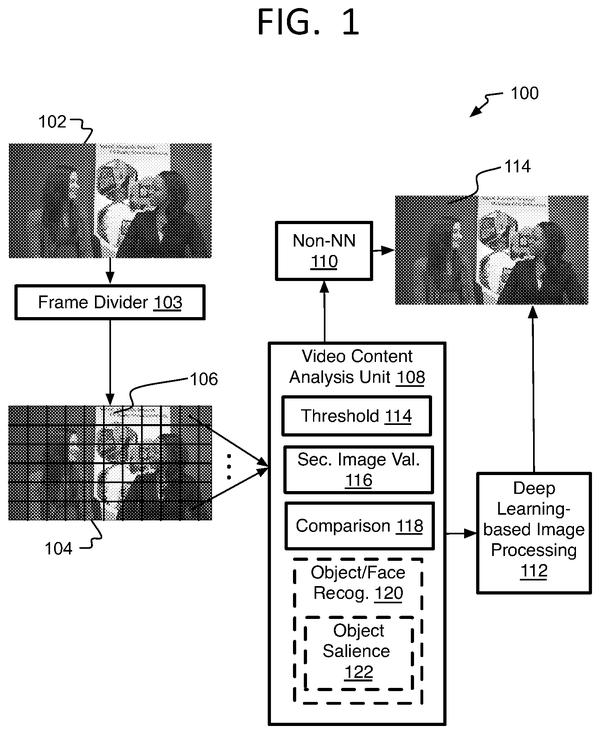
Providing AI sharpeners with text labels and spatial maps lets the system cross-check ambiguous regions before generating detail, reducing hallucinated textures that contradict the actual subject.
Shrinking the photo first to analyze grain patterns lets the chip skip full-resolution processing and compute a custom filter per region, cutting the work needed to denoise dim shots without preset recipes.
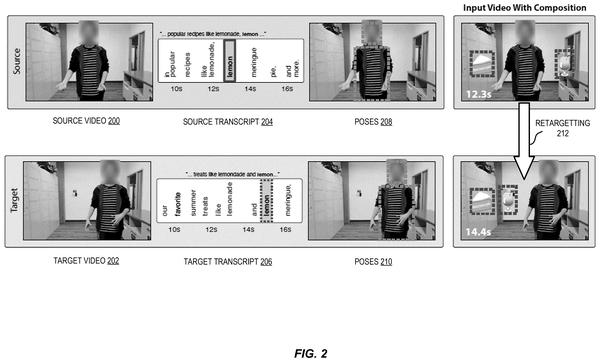
Automatic graphic repositioning across re-recorded takes eliminates re-syncing graphics to new speaker positions and timing, extending the editing toolkit for multi-take workflows where reshoots change camera framing or delivery pace.
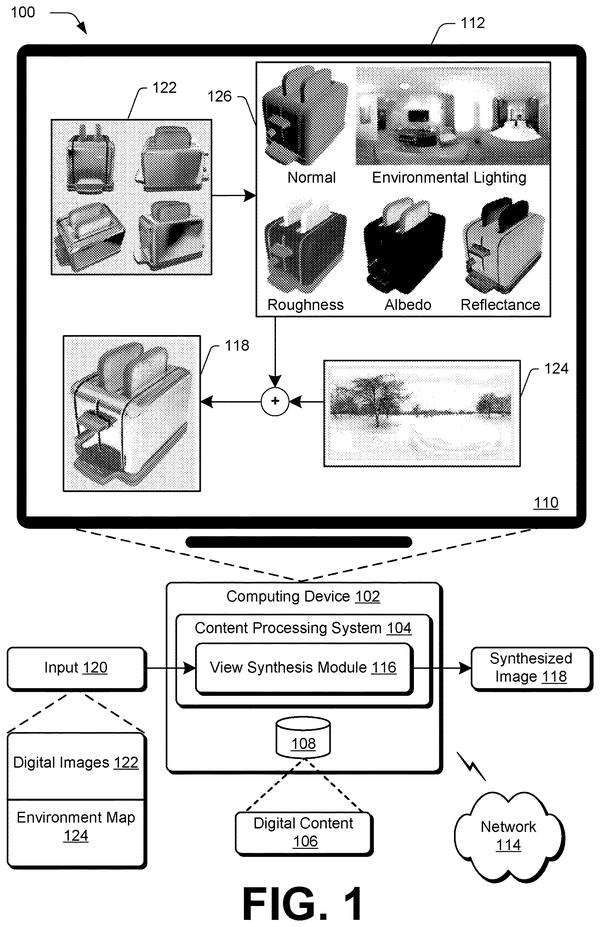
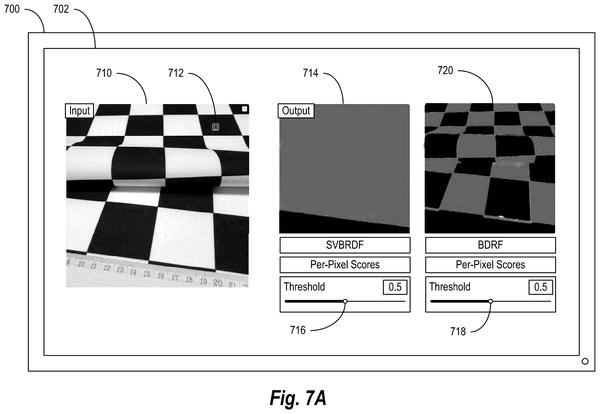
Material inference from multi-angle captures lets users relight shiny objects without reshooting, extending the compression and recoloring work to handle reflective surfaces and their physical properties.
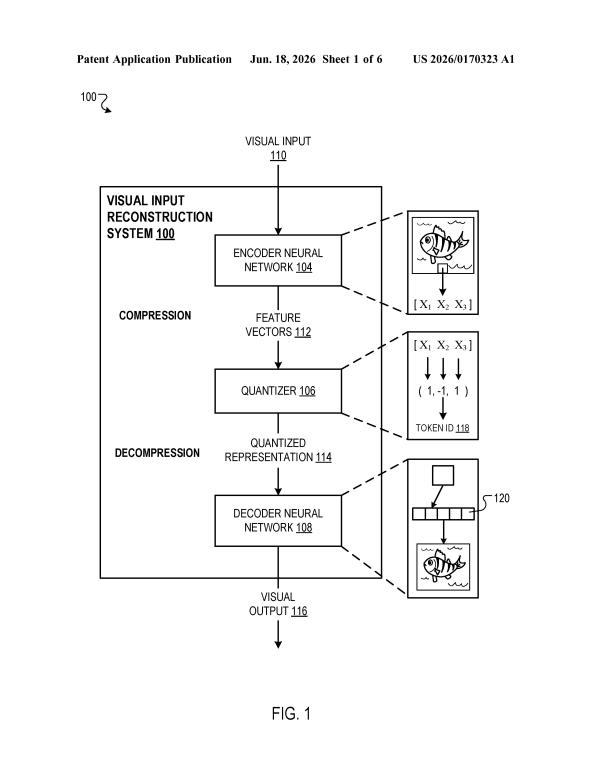
Compression via selective pixel transmission extends the AI redraw toolkit beyond guided edits to bandwidth constraints, shifting the race toward inference-side reconstruction.
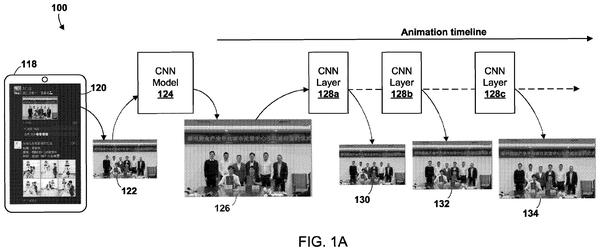
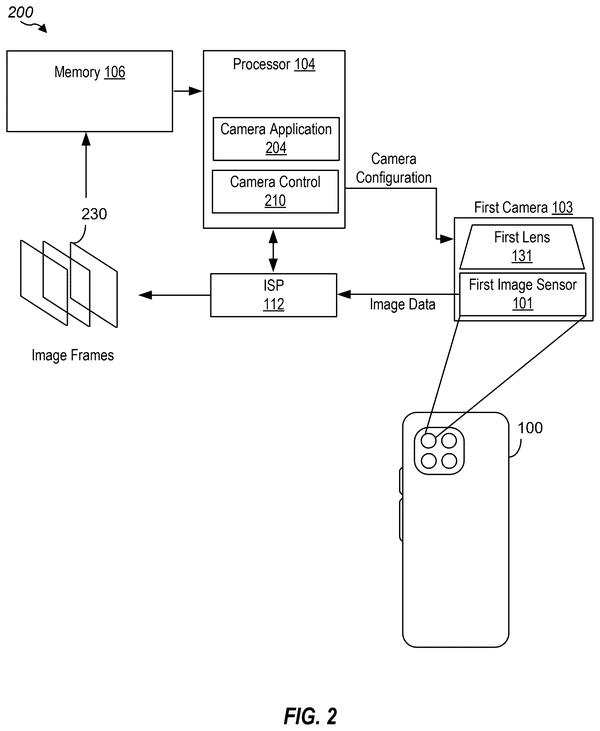
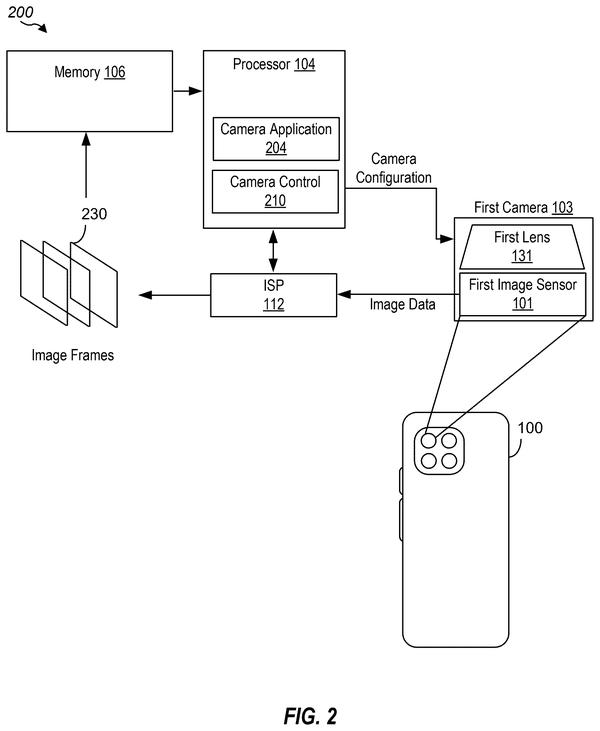
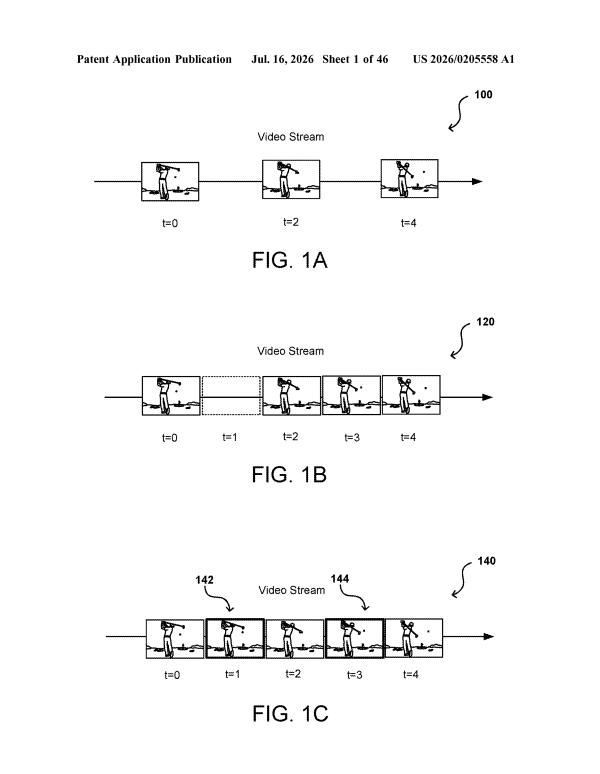
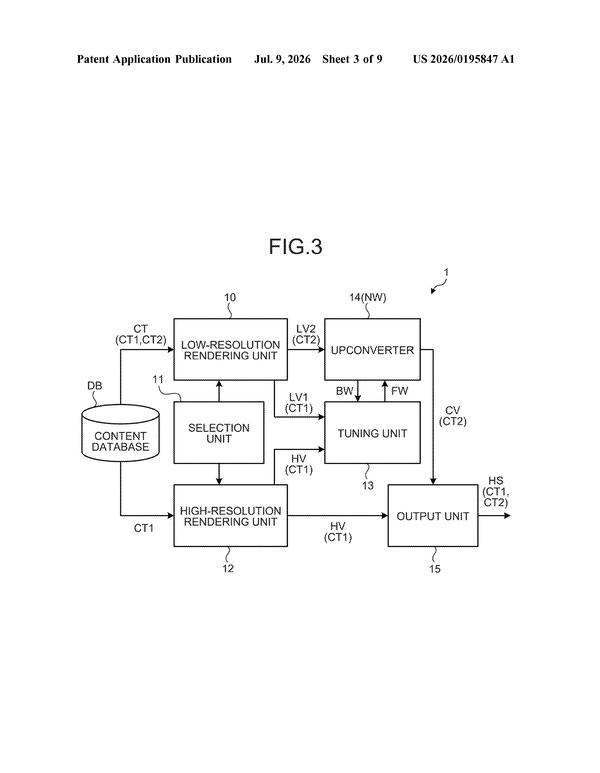
Adaptive frame skipping during AI upsampling lets phones smooth zoom motion without running full inference on every frame, cutting the battery hit that makes real-time zoom editing impractical today.
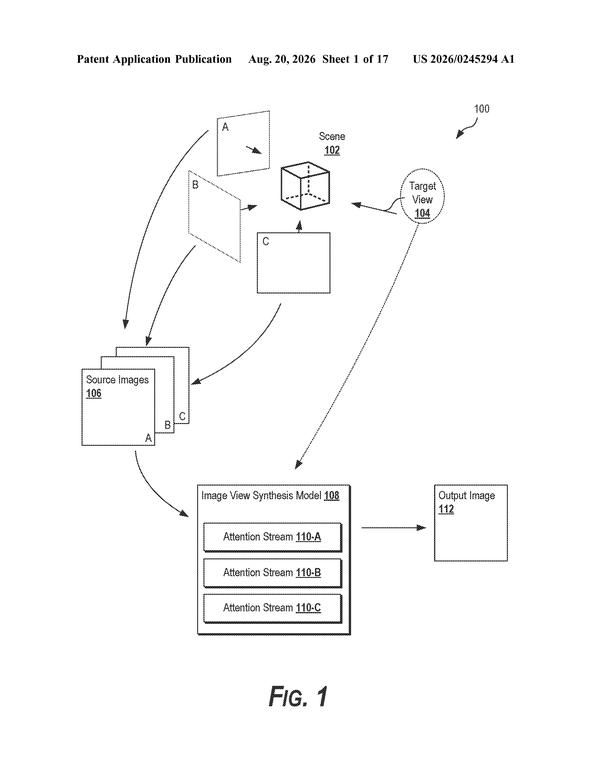
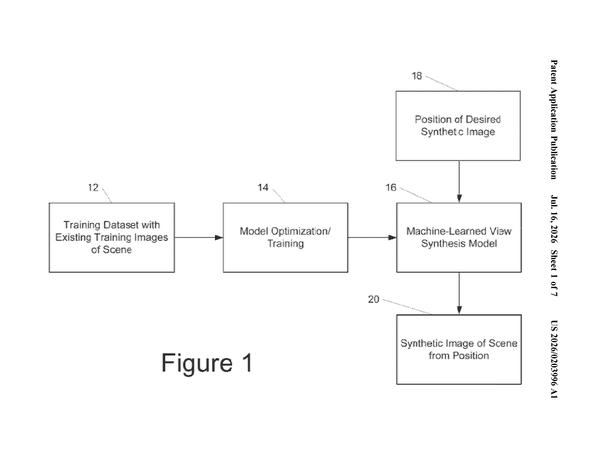
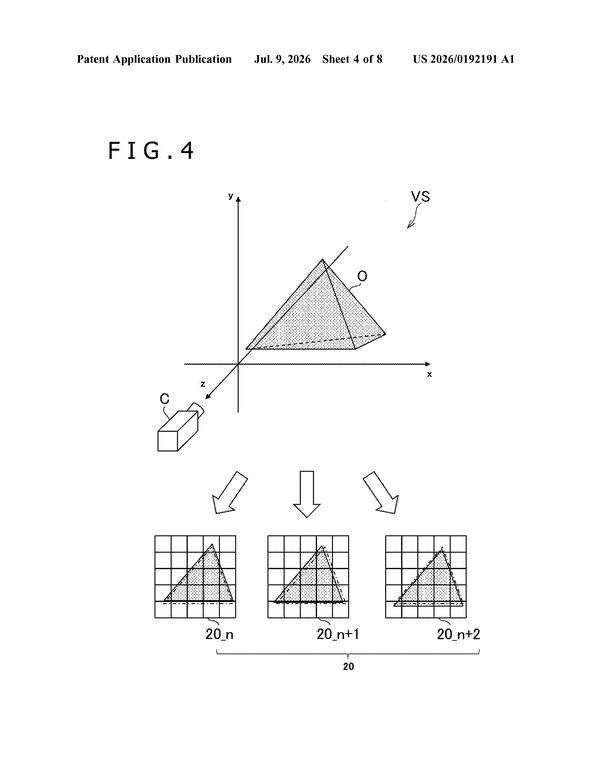
Reconstructing 3D scene geometry from flat photos to synthesize new viewpoints extends the zoom and reframing work already tracked here, pushing past crop-based solutions toward synthetic angle shifts.
Google's region-by-region word checking extends the race beyond bulk image quality into instruction-following precision, especially for multi-object scenes where earlier generators lost track of placement details.
Pinch-to-expand gestures trigger generative fill at image edges, extending the frame beyond what the camera captured rather than recovering clipped content from sensor data.
Generating panoramic video from a single camera sweep requires synthesizing motion in unseen frame regions, here Google specifies how to invent plausible movement for objects that slip past the lens edges during capture.
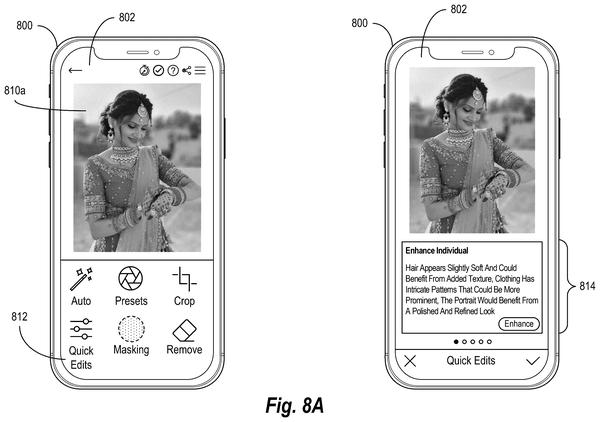
Classifying image content to surface relevant edits narrows the tool menu from hundreds of options to a matched handful, cutting through the generic slider problem that plagues standard editors.
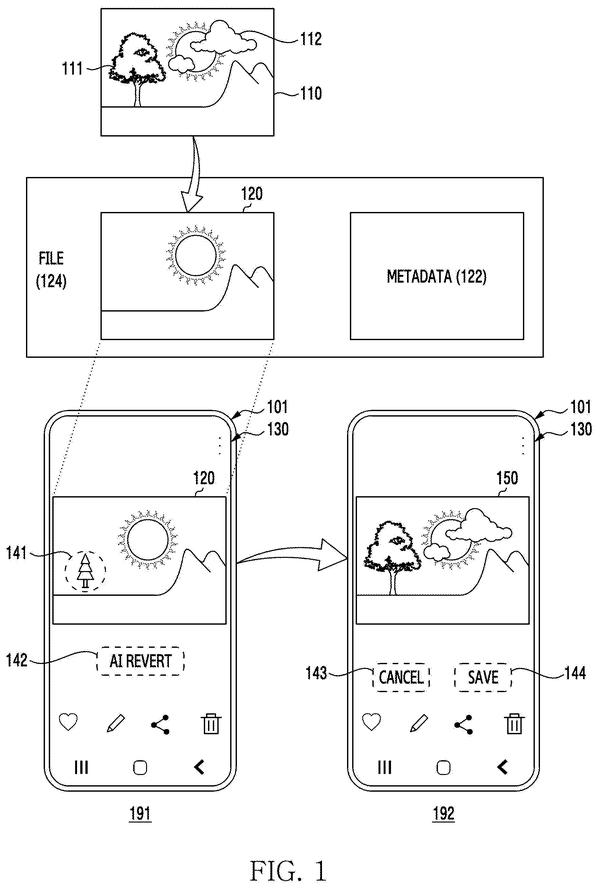
Embedding reconstruction data inside edited files lets users recover deleted originals without storing backup copies, a key constraint on memory-limited phones competing in the editing space.
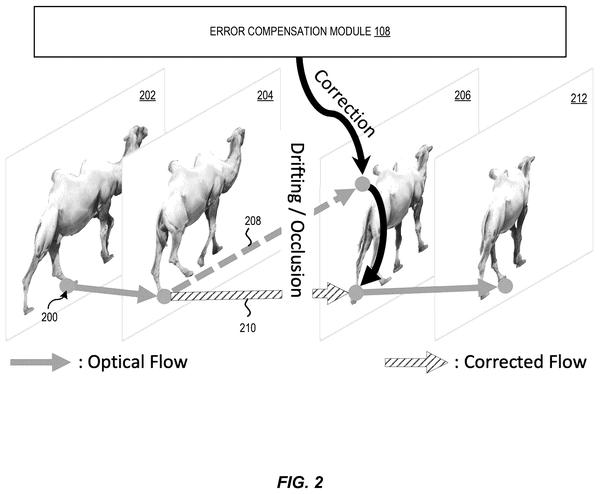
Dual-model approach catches tracking drift mid-sequence rather than in post-review, letting a secondary AI correct paths when the primary tracker loses lock due to occlusion or camera movement.
Recording multiple lens streams simultaneously lets Samsung defer zoom decisions to post-processing, where it can interpolate between angles and eliminate the visible jumps that occur when lens-swapping happens live during capture.
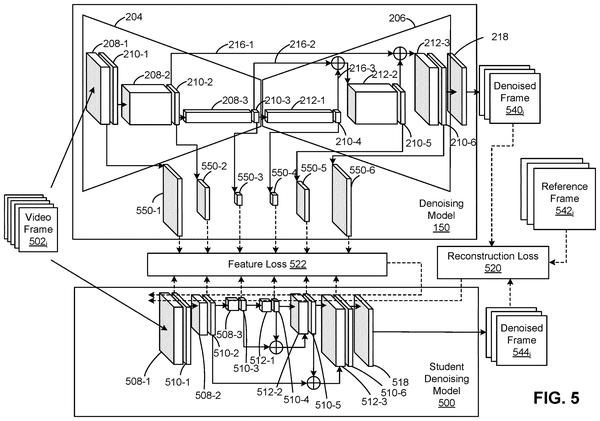
Among the race's speed-versus-quality tradeoff, Disney's approach splits the difference by building a fast student model trained directly by a cleaner teacher, avoiding the usual blur and ghosting that plague real-time denoise.
Precise object segmentation lets users query single elements rather than whole scenes, shifting the AI's focus from broad image analysis to targeted element description.
Inferring off-camera light sources from reflective surfaces in inserted objects solves why 3D additions look pasted in, the AI reconstructs the full surrounding environment to make reflections believable without manual scene setup.
Nvidia's filing points toward localized fixes: the patent describes semantic understanding of scene content so adjustments stay confined to their target region, moving past the broad-stroke processing that degrades untouched areas.
Wide-angle capture picks up unwanted set details, so the patent applies inpainting to remove them in post-production rather than requiring physical obstruction or repositioning during filming.
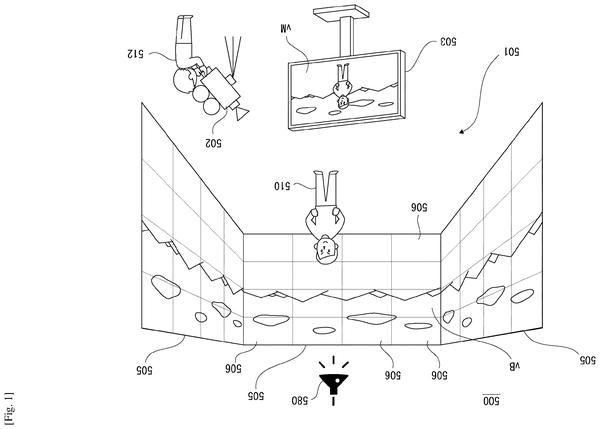
Rough previews let users adjust composition and object placement before final generation, cutting the retry loop that plagues text-only prompting in competing photo tools.
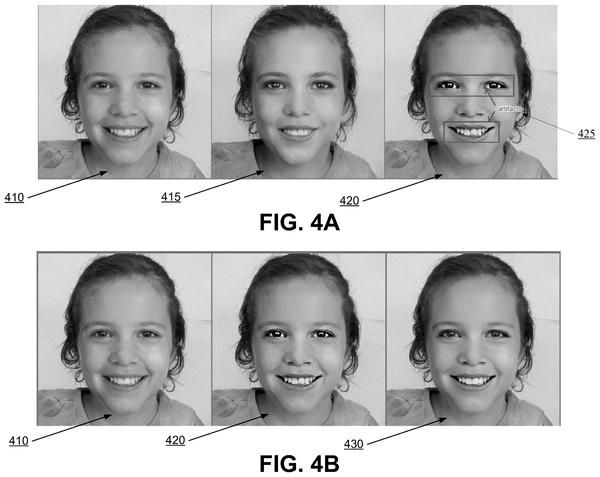
Synthetic face pairs let the filter isolate makeup effects from facial geometry, keeping jawlines untouched while color and texture shift. Confirms Google's push toward surgical precision in real-time beautification.
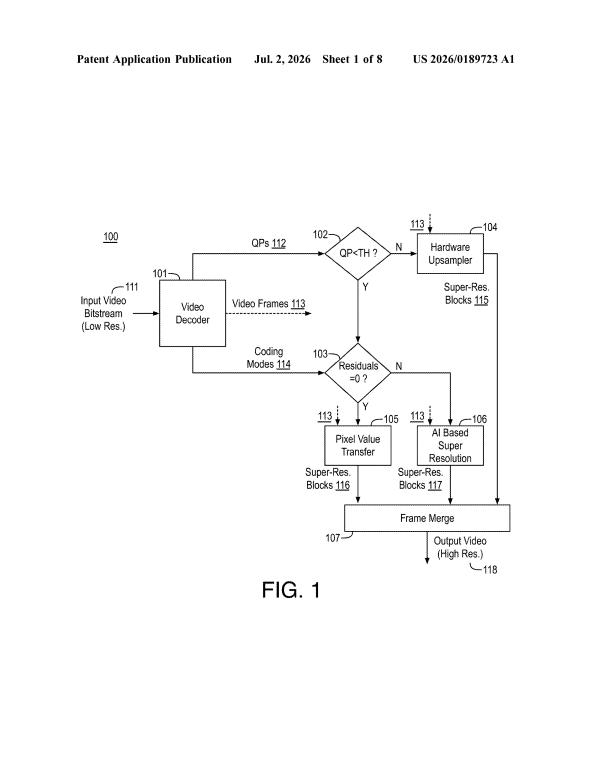
Spatial filtering to skip upscaling on uniform regions cuts processing load by roughly 75 percent, pushing AI enhancement closer to real-time mobile performance without sacrificing sharpness where it matters.
Google's synthetic data approach sidesteps the training bottleneck that has kept text style transfer limited to basic fonts. Automated labeling could accelerate stylized text rendering across editing tools.
Metadata tags tracking object positions across frames let the AI maintain visual consistency when applying the same edit to moving subjects, addressing the flicker problem that plagues automated video recoloring and element replacement.
Among the tracker's focus on guided edits and regional adjustments, Sony's dual-model approach adds a method for the extraction layer itself, treating subject isolation as a problem that needs multiple algorithmic views rather than one pass.
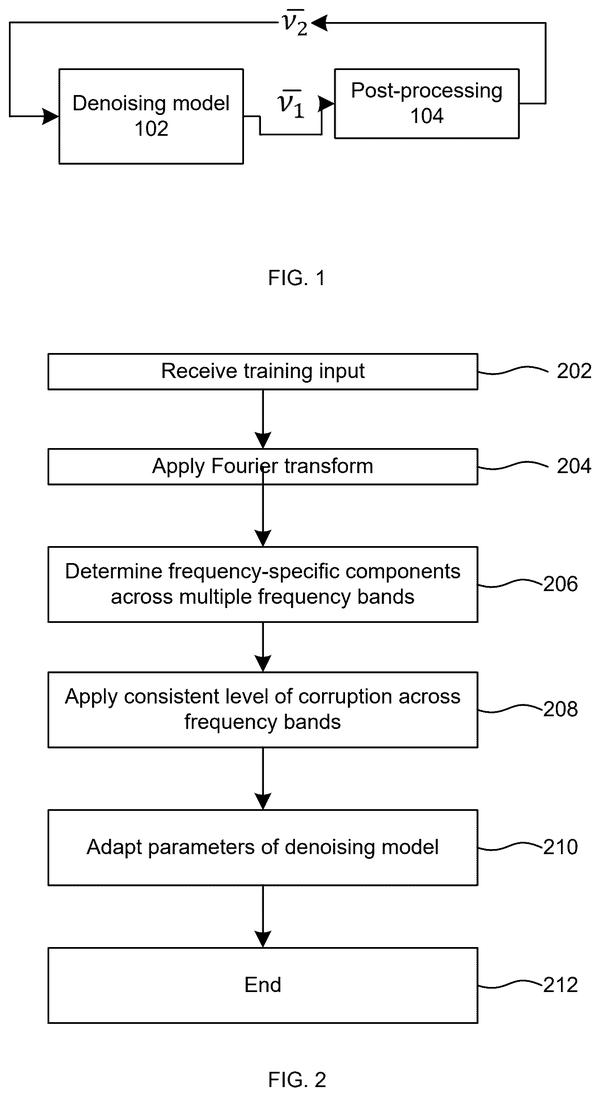
AI image generators learn by practicing how to clean up noisy pictures, but they typically treat all parts of an image the same way when adding that noise. Microsoft's new patent describes a different approach: add noise according to how each frequency band in the image actually behaves, which could make the learning process more accurate from the start.
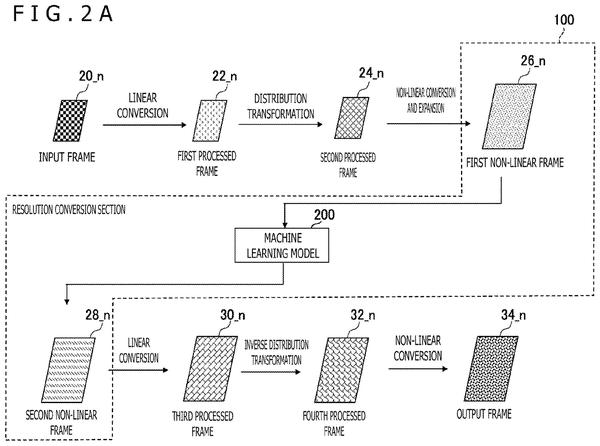
Preprocessing frames through brightness normalization before upscaling prevents the AI model from encountering extreme lighting conditions it wasn't trained on, keeping output quality consistent across high-contrast scenes.
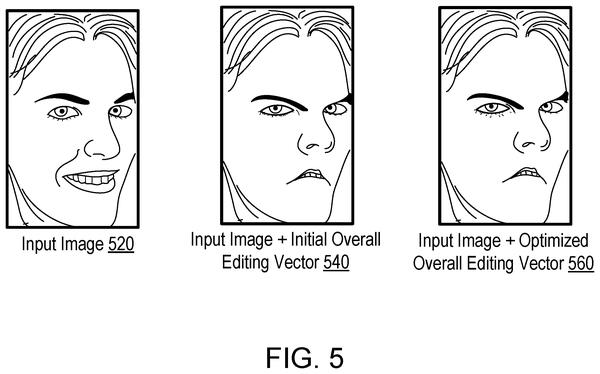
Extracting expression edits from paired examples rather than relying on preset filters lets the system learn face-specific changes, moving photo editing toward personalized adjustments instead of one-size-fits-all effects.
Tap-based subject detection shifts framing from center-locked zoom to user-indicated regions, automating composition around detected subjects rather than fixed frame centers.
Self-grading feedback loops let the AI compare its edits against a reference result, closing the gap between user intent and output that existing tools leave unmeasured.
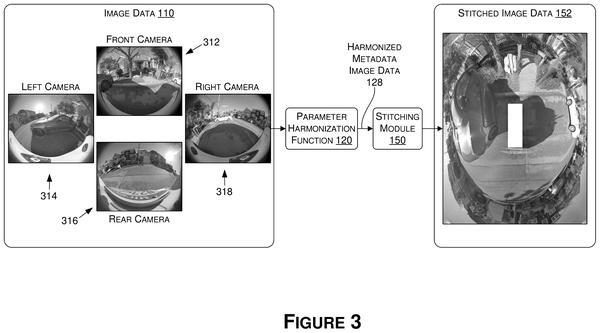
Color-matching adjacent camera feeds before stitching to eliminate visible seams in 360 and surround-view captures. Shifts focus from post-stitch blending to pre-capture calibration.
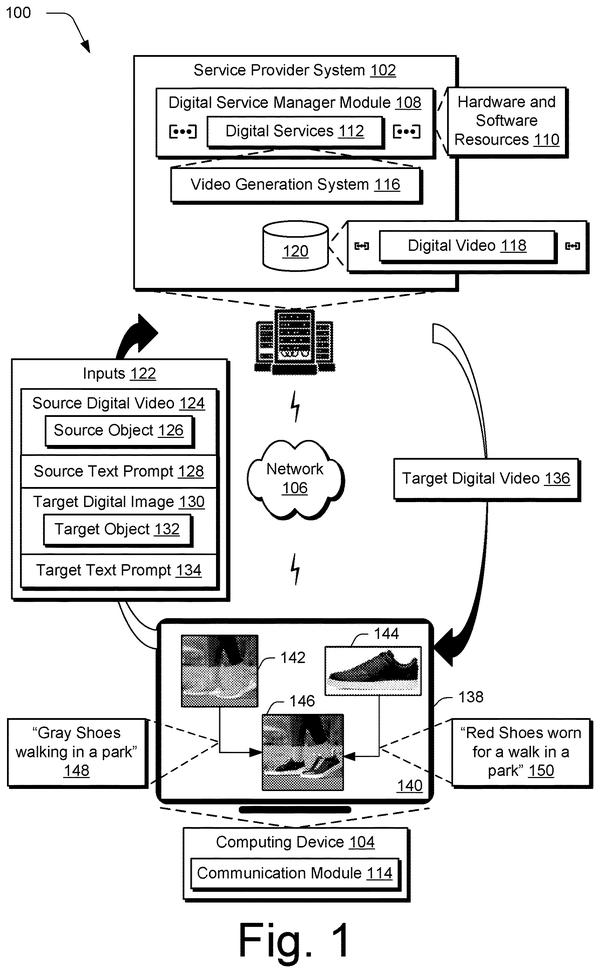
Feeding a reference photo and text prompt into frame-by-frame synthesis sidesteps the manual masking work that dominates multi-frame object replacement in video editing.
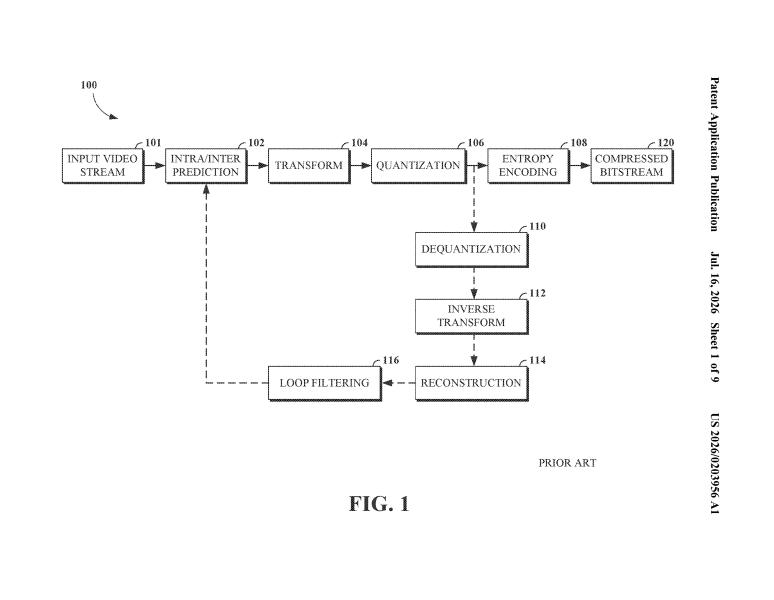
Google's lightweight neural network approach fits the compression track by moving artifact removal to the decode stage rather than relying on heavier post-processing. The filing confirms the race is turning toward on-device efficiency as a core constraint.
After Google and Nvidia pushed text-guided fills, Samsung refines the upstream step: reshaping selection borders before the generator runs, aiming to eliminate the smeared edges that plague removal tools.
Automatic mode detection based on region geometry and context reduces the setup friction that currently forces users to manually select between inpainting, outpainting, and object removal workflows.
Google and Nvidia have focused on per-region edits and text-guided recoloring; Samsung shifts the problem upstream to object removal itself, using depth data to keep inpainted frames temporally consistent rather than fixing flicker after the fact.
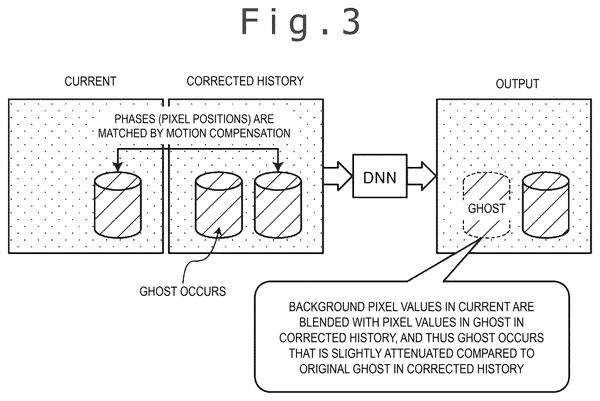
Dedicated artifact removal during frame prediction prevents accumulated ghosting errors in video inference, addressing quality drift that compounds across sequences.
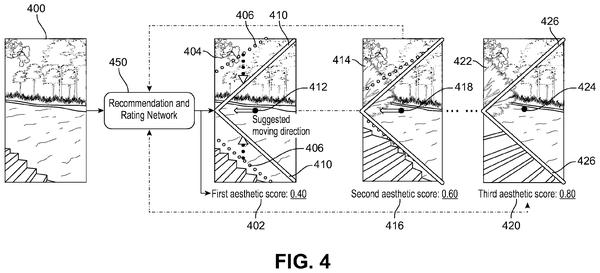
Real-time composition scoring pushes beyond focus detection into spatial arrangement, rating how your current frame aligns with detected visual interest points and suggesting repositioning before you shoot.
Confidence-weighted blending lets the processor favor whichever exposure the neural network trusts more in each region, avoiding the flat averages that plague mixed-light shots.
Temporal transfer learning from reference objects lets the system predict aging effects on entirely different subjects, extending photo editing beyond static transformations into object lifecycle simulation.
Sparse frame sampling cuts the computational load for video regeneration by letting AI infer missing frames between keyframes rather than processing every frame in the source clip.
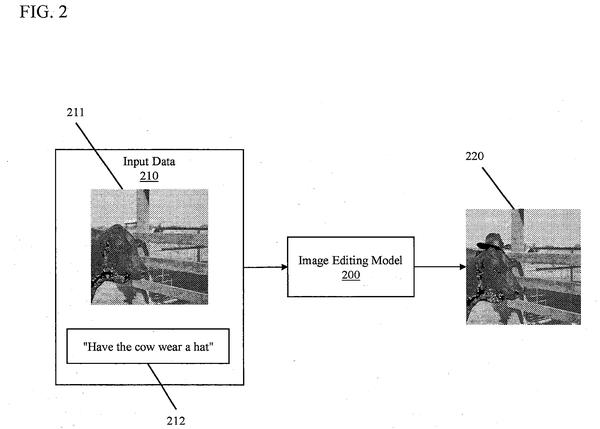
Parsing object descriptions and modification requests from plain text lets the system skip manual selection tools entirely, moving camera software toward conversational rather than menu-driven workflows.
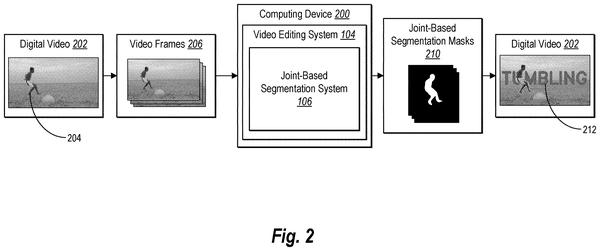
Frame-by-frame masking of moving subjects. Adobe's skeleton-mapping approach automates the tedious work of tracking body position across shots where subjects shift and occlude.
Extends the photo recovery angle by automating vignette removal, detecting dark corner borders and synthesizing missing content rather than cropping. Fills a gap in the restoration workflow that Google and Nvidia haven't targeted yet.
Removing a standard decoder layer speeds up decompression on devices, cutting the latency between transmission and display in gallery apps and similar interfaces.
Rotoscoping automation requires training data that mixes real and synthetic footage. Disney's method generates its own labeled training set by blending computer-generated actors into real backgrounds, sidestepping the manual annotation bottleneck.
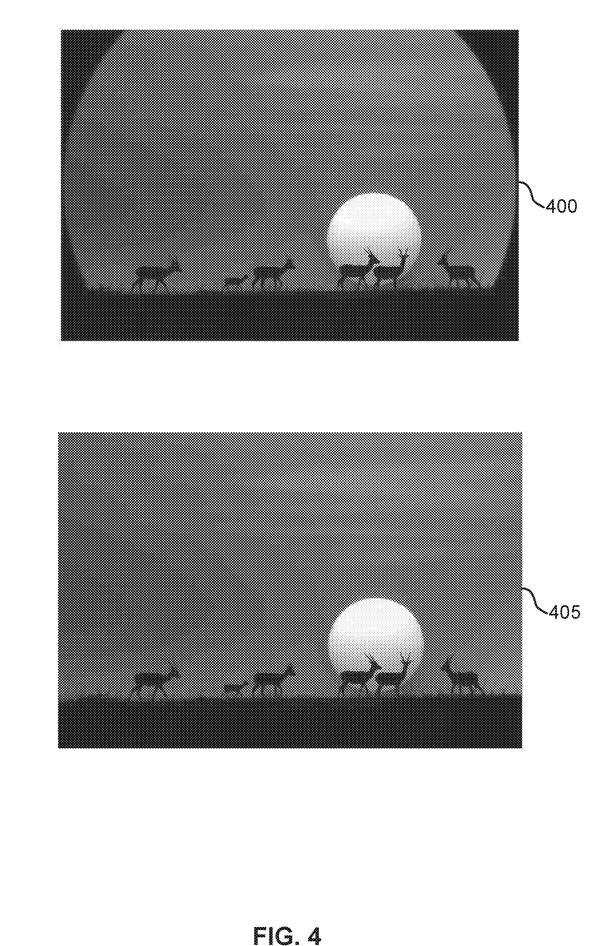
Inpainting and outpainting pull matching textures from the user's nearby shots rather than generating them, reducing artifacts when editing complex backgrounds like brick or foliage in burst sequences.
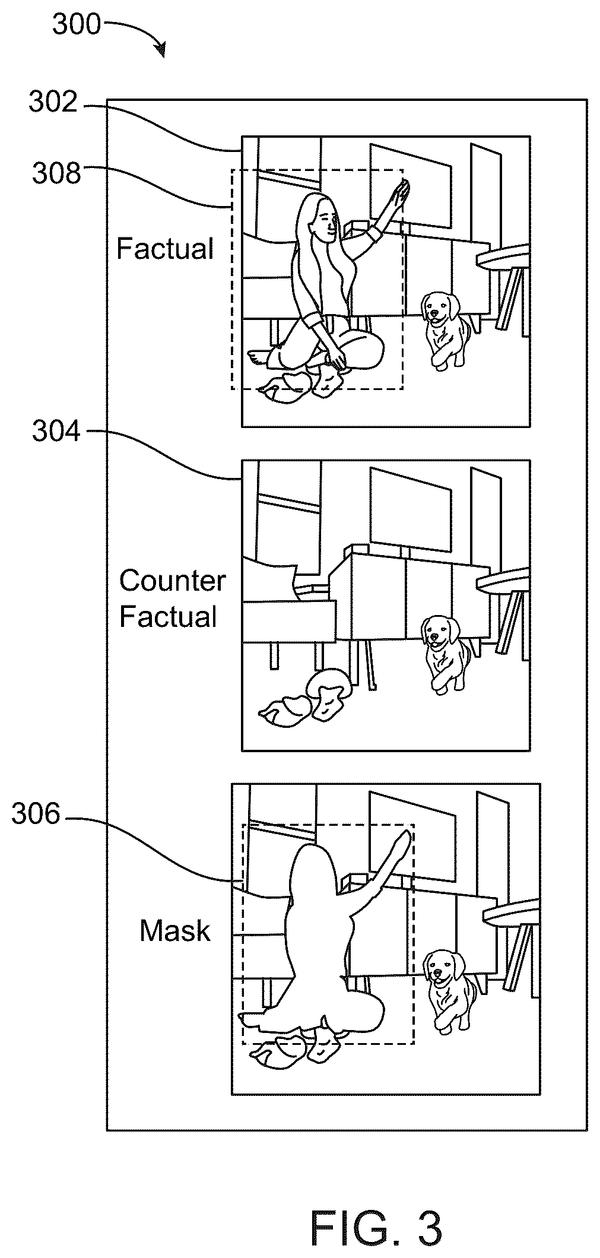
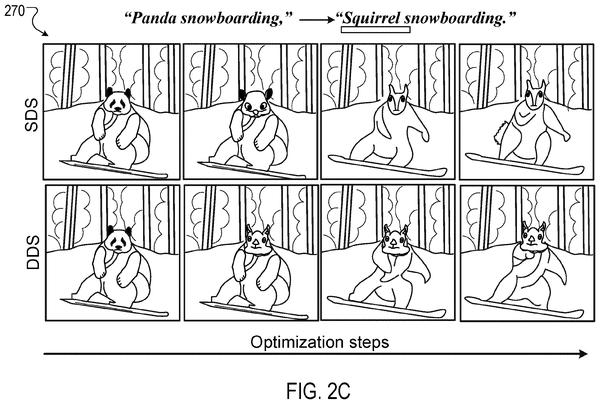
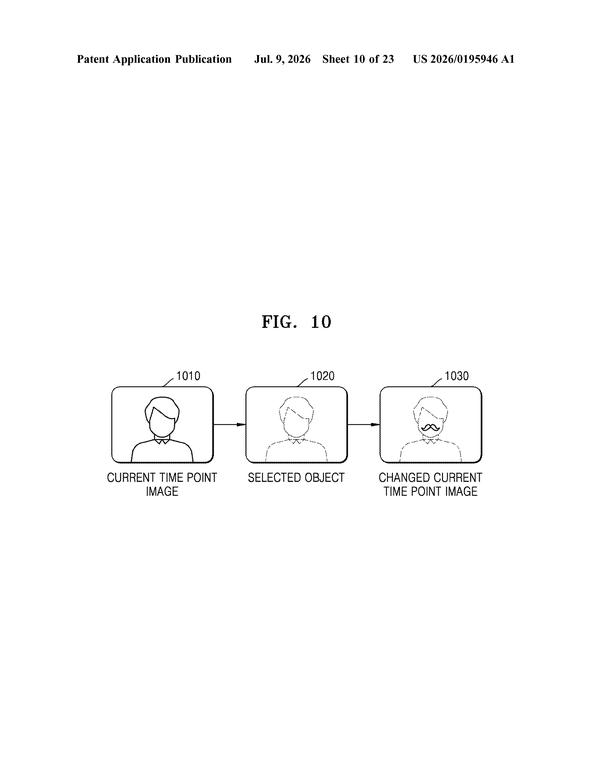
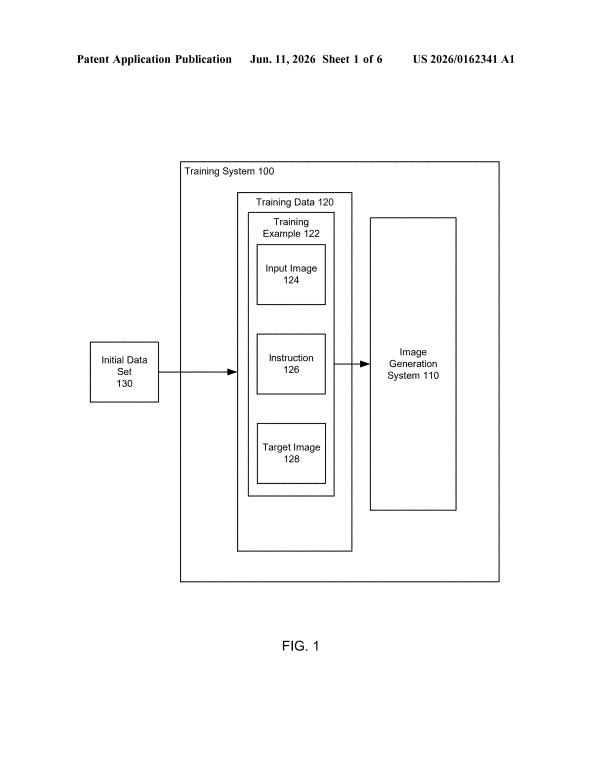
Within the race to isolate edits to specific image regions, Google's approach trains models on paired before-and-after examples to learn the precise scope of change rather than generating from scratch.
Detecting absent subjects through reference images embedded in the scene, like a photo visible in the background, extends the recoloring and object-swapping work beyond what's already captured, toward reconstructing what should have been there.
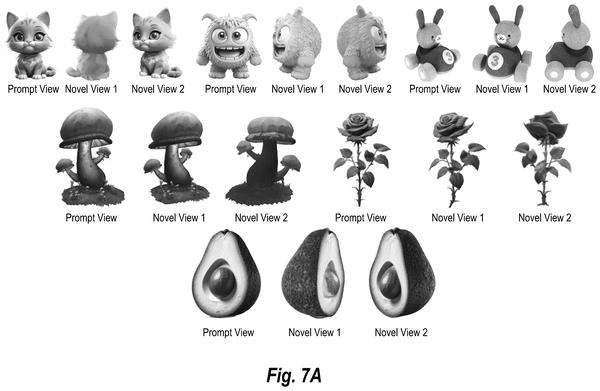
Synthesizing novel camera angles from single images fills a gap in product photography workflows. Adobe's approach generates unseen viewpoints computationally, removing the need for reshoot or 3D modeling work.
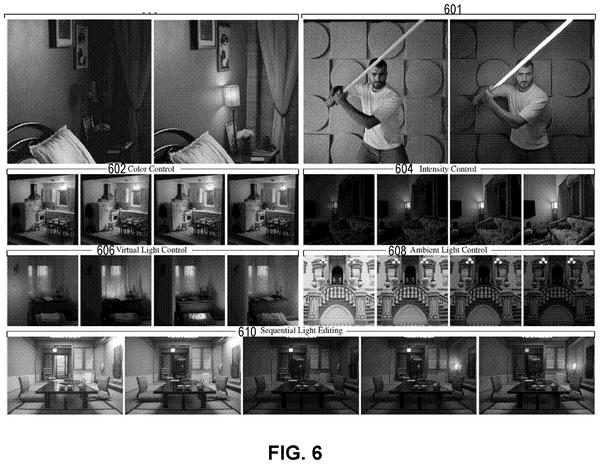
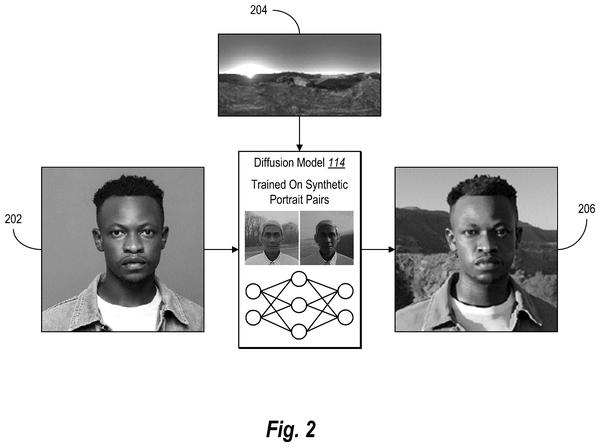
Relighting portraits to match arbitrary lighting environments extends Adobe's work beyond basic color shifts into 3D-aware scene matching, suggesting the tracker's focus on guided edits now includes physical light simulation.
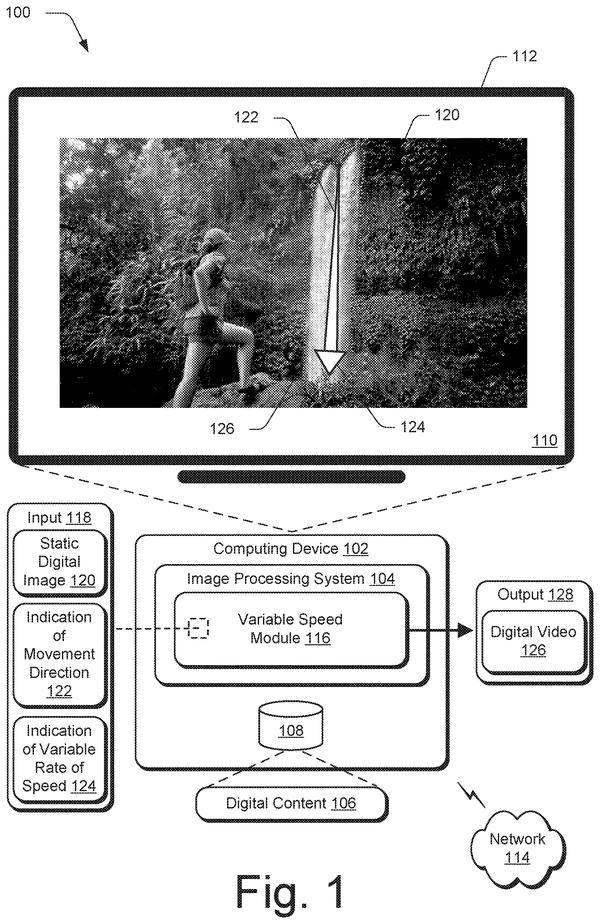
Motion inference from static scene analysis lets the system automatically determine object movement direction and speed without manual tracking, extending the photo editing race beyond recoloring and compression into video synthesis.
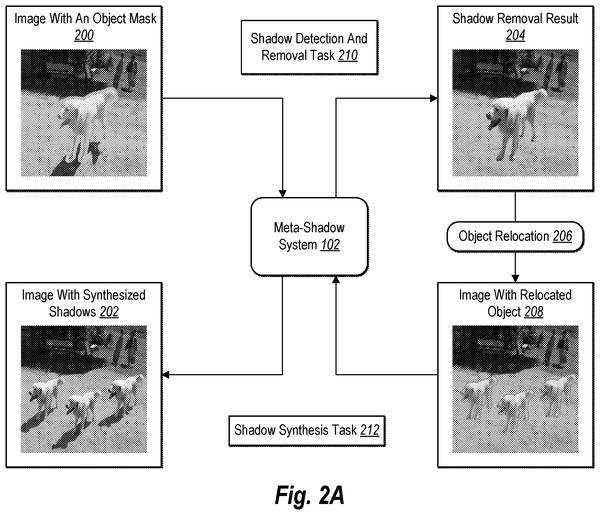
Within the race to simplify photo editing workflows, Adobe's unified shadow-handling system consolidates what currently requires manual detection, removal, and inpainting into a single model trained on all three operations together.
Google and Nvidia have focused on what to edit; Samsung's approach isolates where editing is needed, cutting processing load by skipping unchanged regions.
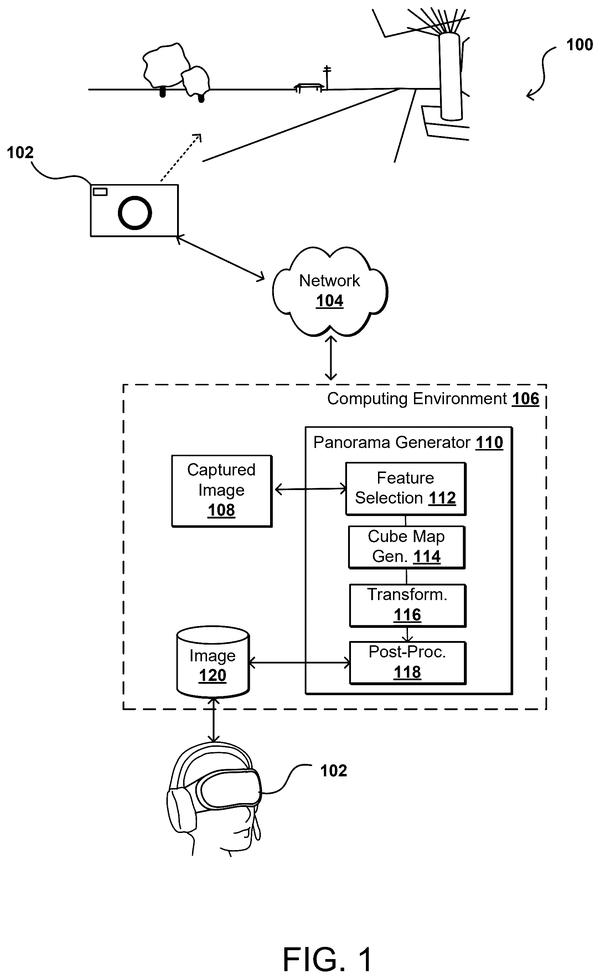
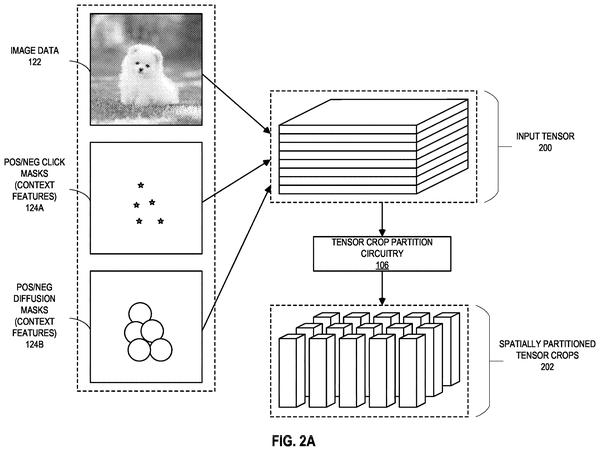
Leveraging depth maps to automate object isolation cuts down manual masking work in mobile editing. Google's tap-to-cut approach reuses camera sensor data already present on modern phones rather than relying on computational segmentation alone.
Content-aware repair splits the workload: the model identifies faces, text, and backgrounds separately, then applies targeted fixes instead of one uniform filter across the whole frame.
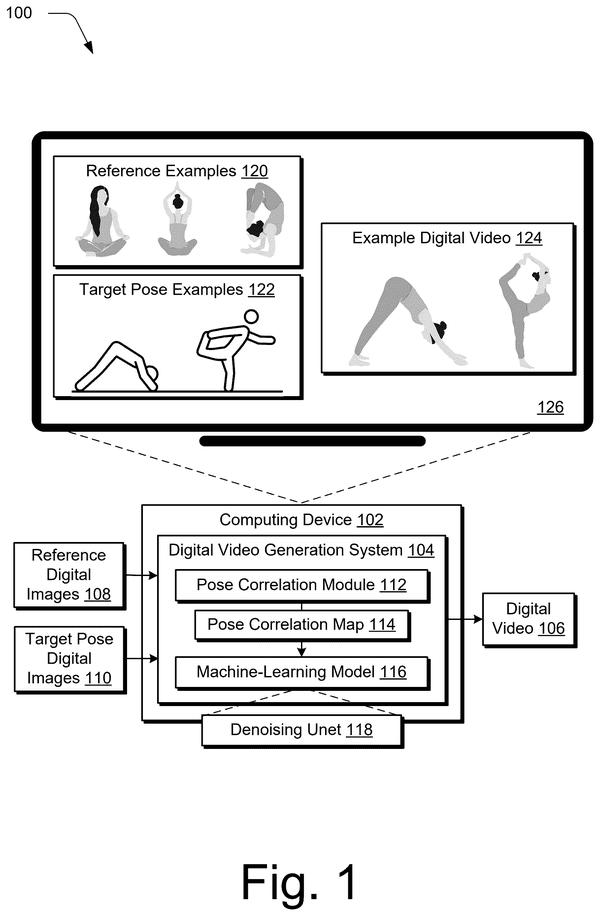
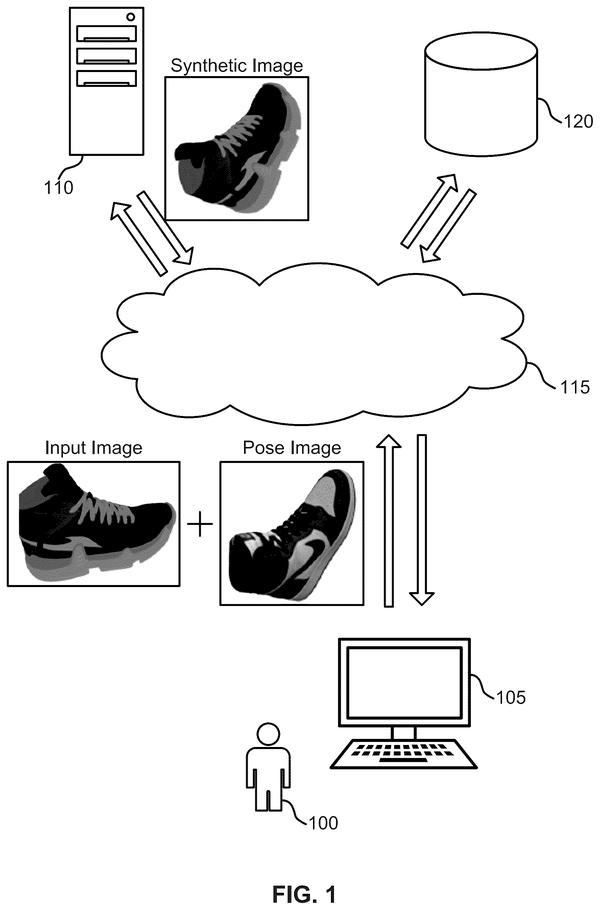
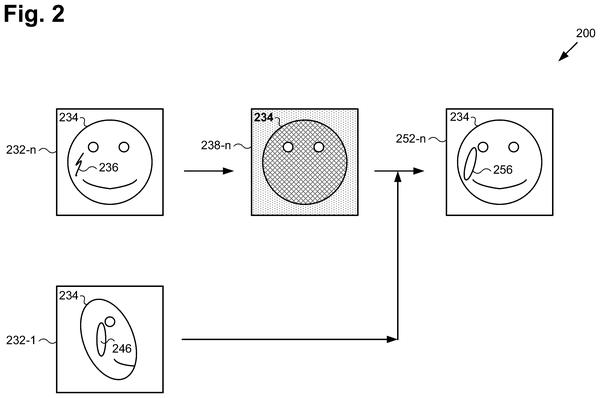
Users could fix awkward poses by borrowing body positions from other photos, cutting the manual frame-by-frame work that dominates this editing category.
Automating camera preset tuning through user feedback loops shifts the editing burden from post-capture software to the camera itself, reducing manual adjustment cycles.
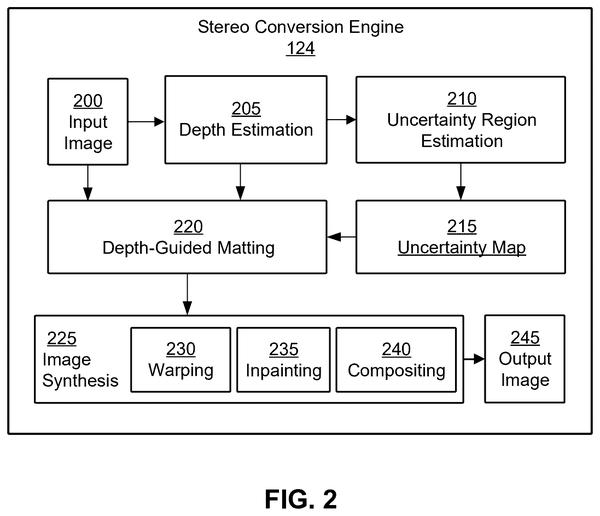
Repositioning subjects in photos leaves hollow voids and distorted backgrounds. Samsung's 3D model approach fills those gaps by recalculating perspective and occlusion instead of relying on flat cutouts.
Photos edited to match a specific movie or TV scene extend the race beyond color and composition into full scene synthesis. Samsung's approach automates the visual translation between your image and a target scene's lighting, costume, and setting.
Users could stream longer videos on limited data by cutting the file size that motion encoding demands. The patent confirms Google's focus on predictive models that estimate object movement before decoding, rather than measuring it after the fact.
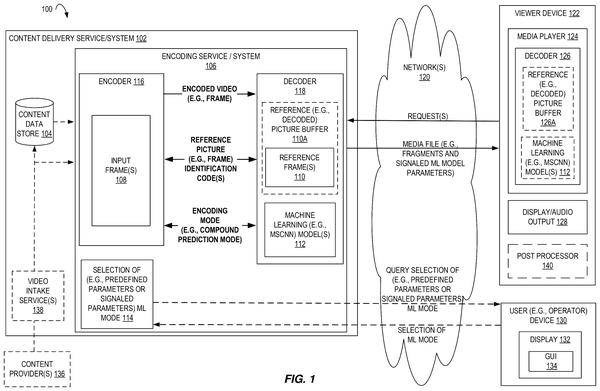
Embedding AI corrections in the video stream itself sidesteps the need to retransmit edited footage, cutting bandwidth while letting client devices apply fixes locally as frames arrive.
Recovering detail from compressed video feeds without re-encoding opens a practical path for real-time streaming cleanup, particularly relevant for security and live-capture workflows where original files are already discarded.
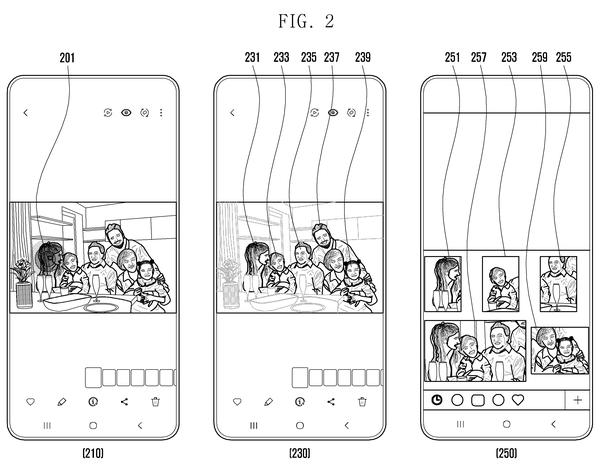
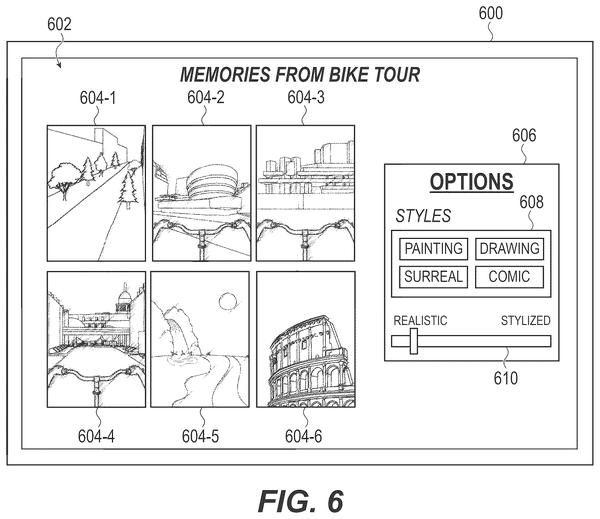
Users could get stylized versions of their best moments without manually sorting through hundreds of shots or editing each one. The filing extends the race beyond region-specific edits into automated curation and generative transformation of whole libraries.
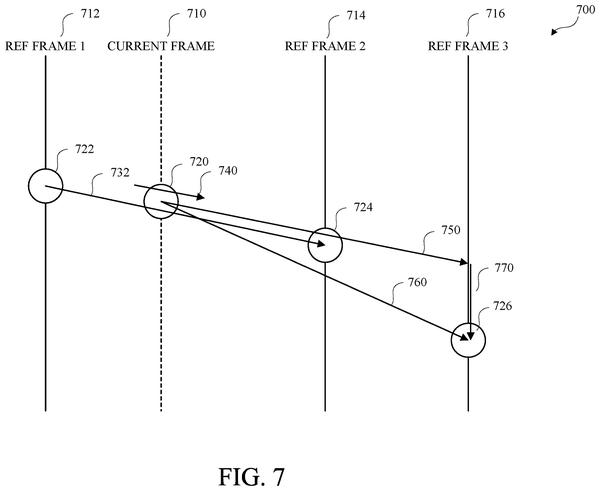
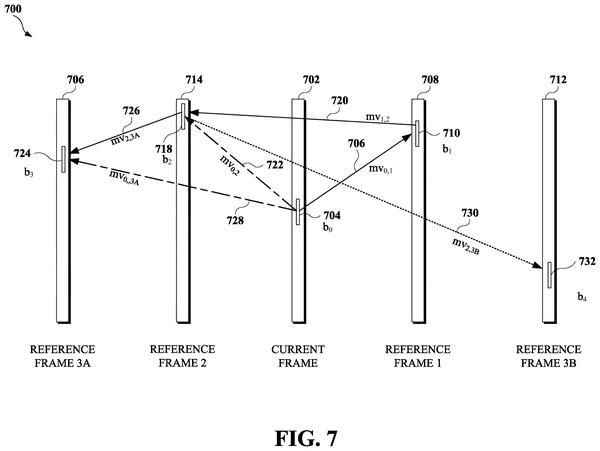
Predicting motion from a single prior frame breaks down in complex scenes. Using two reference frames instead lets the encoder capture multi-directional movement more accurately, reducing the bitrate needed for smooth playback.
Cross-location angle transfer cuts the data burden. Google's method trains on paired viewpoints in one scene, then generates unseen angles in novel environments without retraining, reducing the photo inventory needed before editing can begin.
Pre-avatar photo conditioning via text prompts lets users refine reference images before 3D conversion, sidestepping manual editing steps that typically slow avatar creation workflows.
Exposure inconsistency across multi-angle captures: Google embeds lighting correction into the 3D model during reconstruction rather than correcting each photo separately.
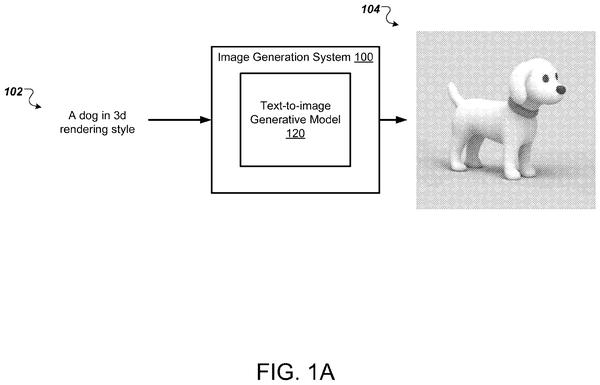
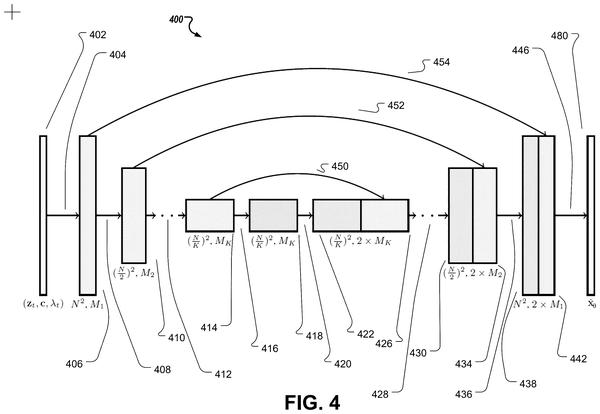
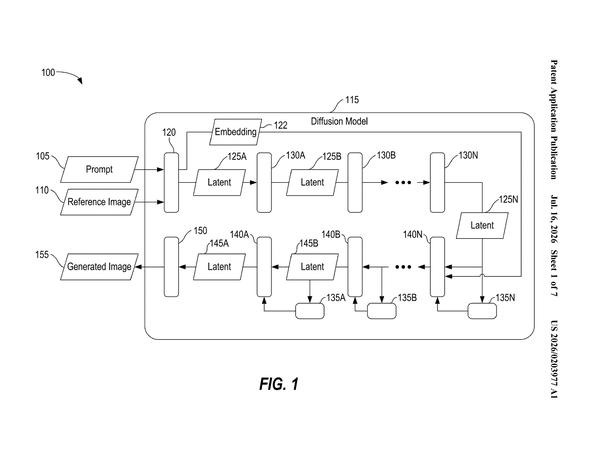
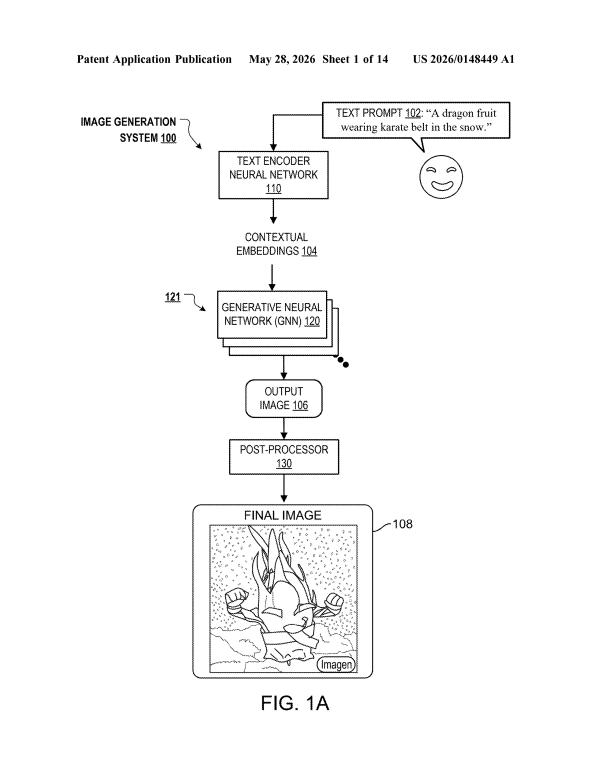
Most AI image generators take a single text prompt and feed the same instructions to every part of the model. Google is patenting a system that gives each layer its own separate set of instructions, potentially giving creators far finer control over the final result.
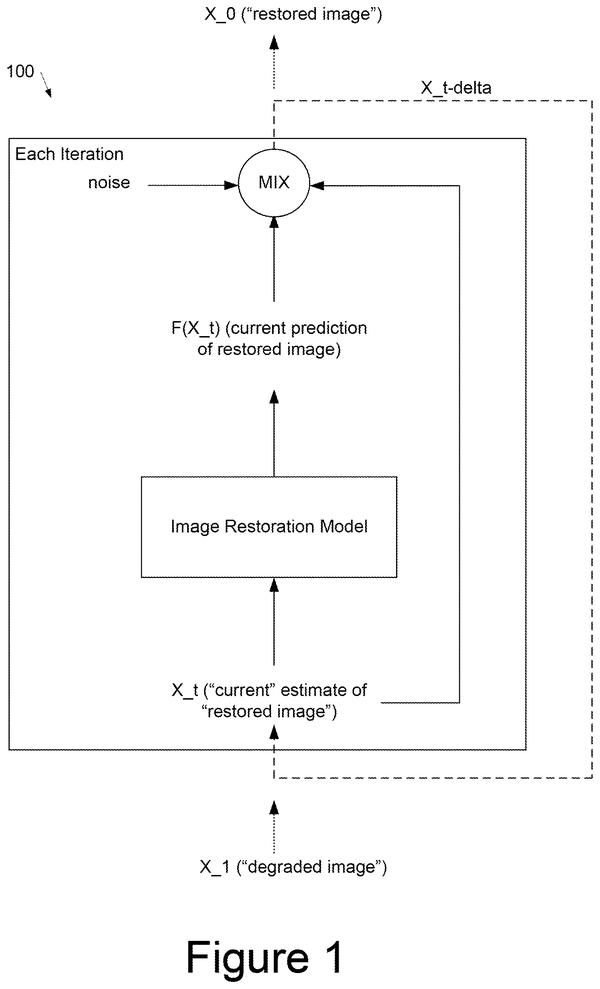
Iterative repair of degraded photos sidesteps the single-pass model's failures by cycling through guided corrections, letting each step build on the last rather than betting everything on one inference pass.
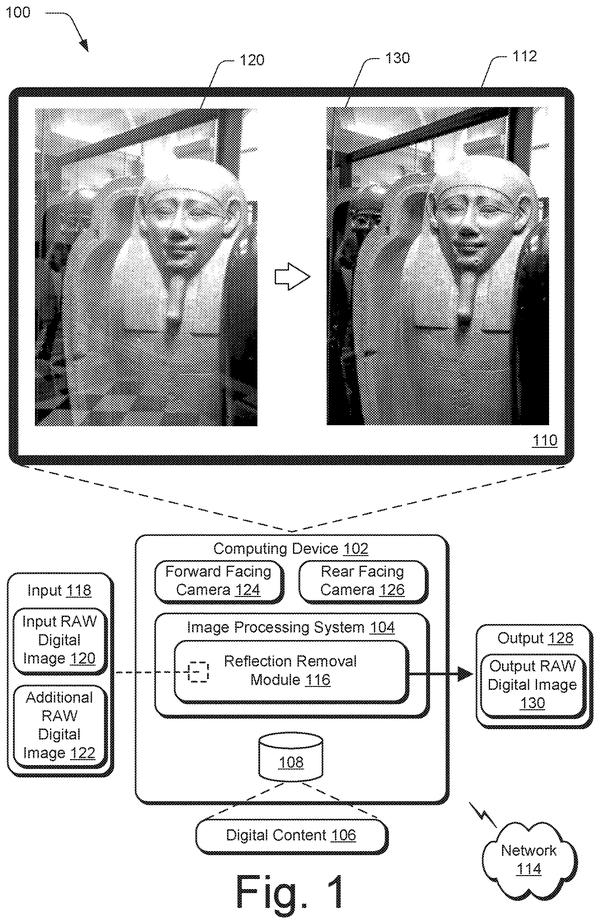
Users shooting through windows could finally get clean shots without repositioning. Adobe's dual-image approach to separating reflections from the actual scene suggests a practical path for handling one of photo editing's messiest real-world problems.
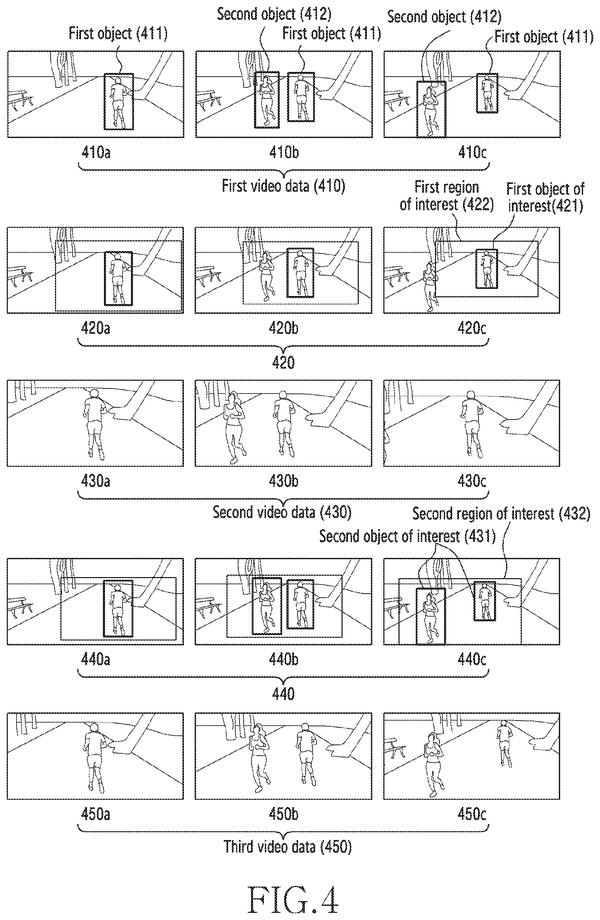
Tracking moving objects frame-to-frame without manual adjustment cuts production time on mask alignment, a core bottleneck in video post-production workflows.
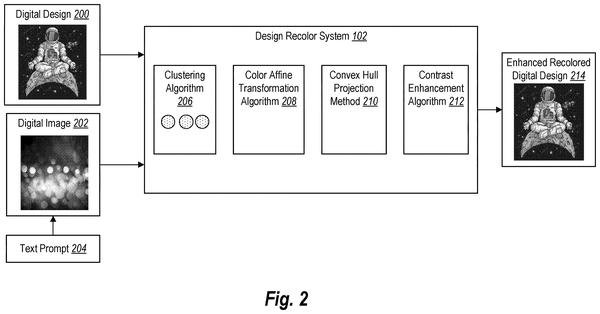
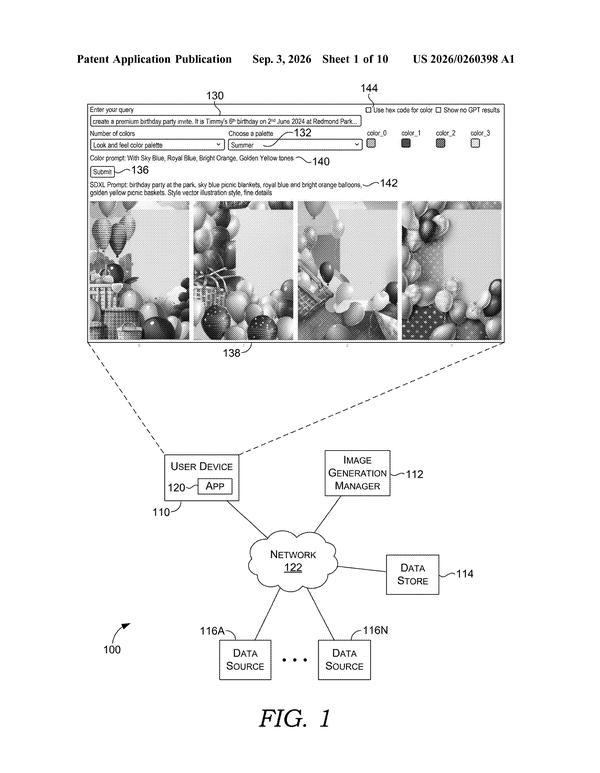
Applying text prompts to redesign entire color palettes at once cuts out the manual per-element recoloring step that currently dominates design iteration workflows.
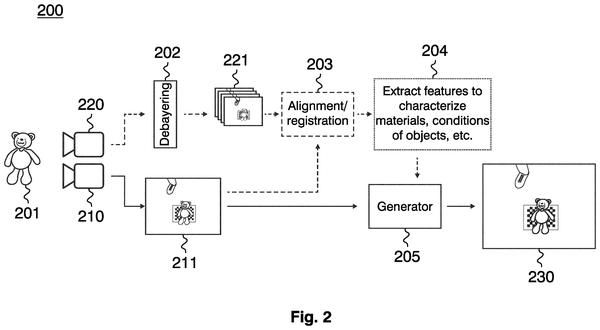
Shadow and highlight recovery in dim or backlit scenes requires data the visible spectrum alone can't capture. Sony's approach fuses infrared wavelengths recorded alongside standard photos to recover detail the camera physically missed.
Adapting color palettes to different light sources currently requires manual adjustment across every element. Adobe's filing automates that translation, letting designers shift from one lighting condition to another without rebuilding the palette by hand.
Camera hardware limits how much detail phones can store from high-contrast shots. Google's compression method routes extra color and brightness data around those constraints, keeping what older chips would normally discard.
Users get stylized photos without manual filter selection, the camera reads what's in the frame and applies treatment automatically. This extends the race beyond guided edits and recoloring into content-aware style application triggered by scene recognition.
Google and Nvidia focus on text-guided edits; Samsung's approach uses AI to isolate and enhance specific subjects without user prompts, pushing toward fully automatic subject detection.
Smoother playback on devices means recovering detail lost to compression at the decoder stage using AI rather than standard algorithms, extending Apple's push into neural reconstruction across media formats.
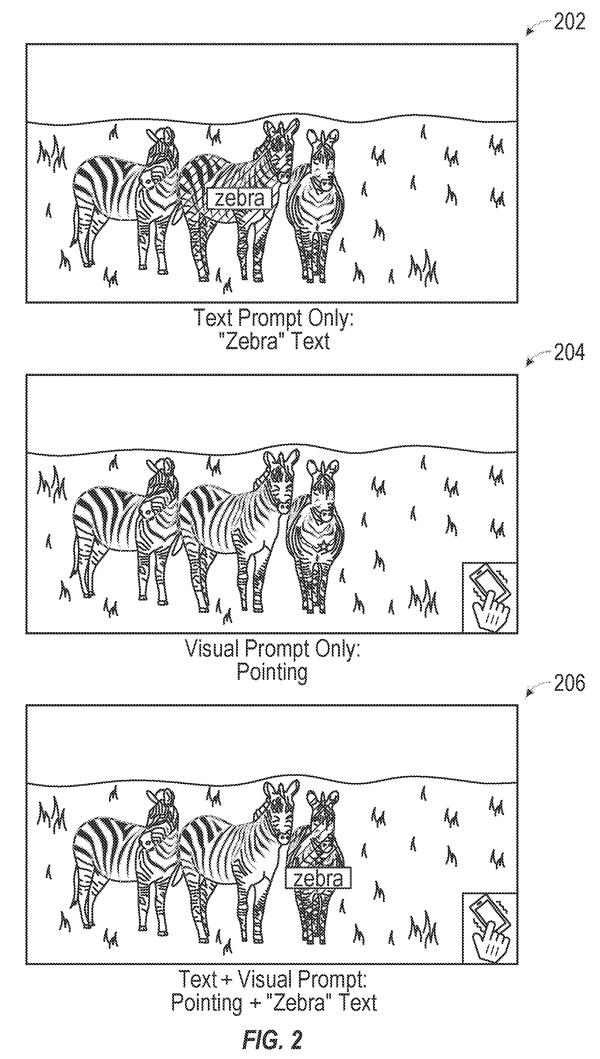
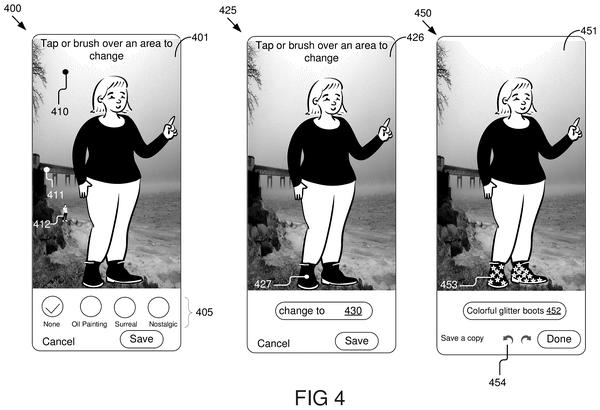
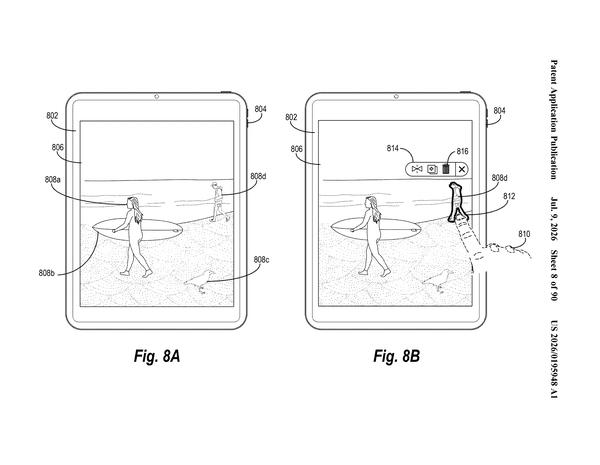
Within the tracker's focus on text-guided edits, this filing shifts toward direct manipulation: users gesture over regions instead of rewriting prompts, moving AI photo editing closer to traditional brush-based tools.
Color matching in generated images requires multiple constraints layered together. Microsoft's approach uses three simultaneous controls to keep AI output within brand-specific color ranges rather than guessing from text alone.
Parallel reconstruction with degradation mapping lets users adjust sharpening intensity before final output, addressing the compression and blur artifacts that plague zoom-in workflows.
Users won't need to write prompts from scratch, since the system auto-detects subjects and suggests preset edits. This fills a gap in the race where competitors still rely on typed commands.
Per-frame compression tuning shifts from fixed settings to adaptive bitrate allocation. Nvidia's approach feeds encoder decisions back into a learning loop, letting the system preserve detail during motion while cutting waste in static scenes.
Inpainting artifacts at edit boundaries require a separate refinement pass. Adobe's filing describes a dedicated cleanup model that runs after primary removal to smooth color and texture mismatches where filled areas meet original pixels.
Users could recolor marble veins separately from the base surface in one click, splitting material selections by natural pattern hierarchy instead of forcing a choice between whole-surface and manual brushing.
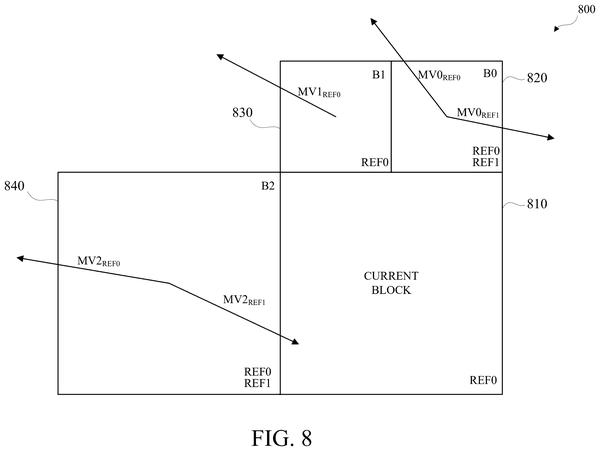
Video compression relies on predicting missing blocks between frames. Google's filing shows how selecting between motion-based and image-based predictions per block could improve decoder accuracy.
Measuring edit flow quality in real time. Adobe's system scores pacing and continuity across clips before human review, cutting iteration cycles in post-production work.
Filling 3D geometry gaps without manual sculpting moves photo editing into model manipulation. Text-guided replacement of object parts extends the guided-edit pattern beyond 2D surfaces into spatial structures.
Users could compose group shots in real time rather than fix framing after the fact. The patent extends the tracker's coverage of real-time guidance tools, joining Google's earlier work on spatial layout assistance during capture.
Artifact suppression during frame merge: Qualcomm embeds defect detection into the burst-capture pipeline, catching glitches before multi-shot stacking rather than correcting them after.
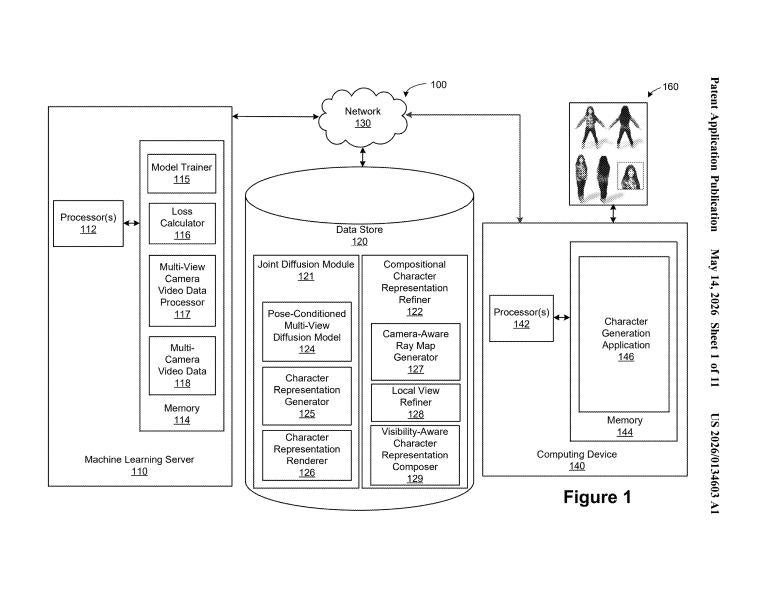
Users could explore video footage in 3D without manual camera tracking or scene reconstruction. Sony's approach learns lighting behavior per-point to rebuild navigable space from handheld shots.
Storing full 3D scenes demands massive memory and slows interactive editing. Adobe's compression method uses AI to encode complex spatial data into compact form, then reconstructs it on demand, potentially enabling real-time manipulation of dense 3D content.
Selective color enhancement by attention mapping shifts the race from global image treatment to region-specific tuning. The filing confirms hardware makers are moving enhancement decisions to the camera processor itself rather than post-capture software.
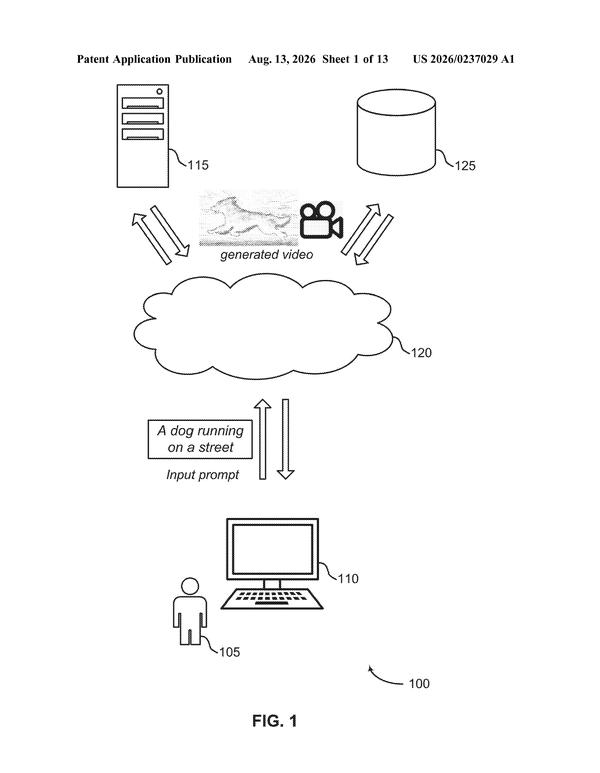
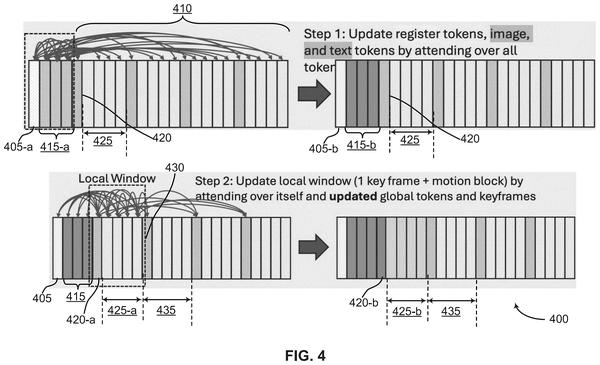
Users could generate video directly rather than stitching frames together, since the system refines temporal consistency across passes instead of solving each frame independently. Extends Google's diffusion work from stills into motion.
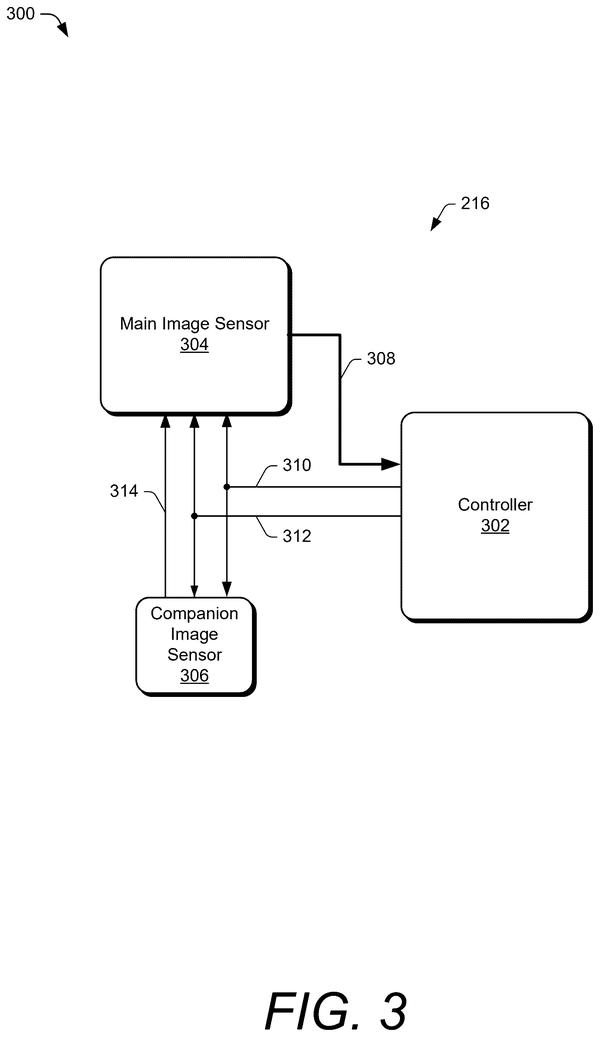
Splitting motion detection from image capture onto separate sensors lets the system skip sharpening static areas, which matters for video where most frames are wasted pixels anyway.
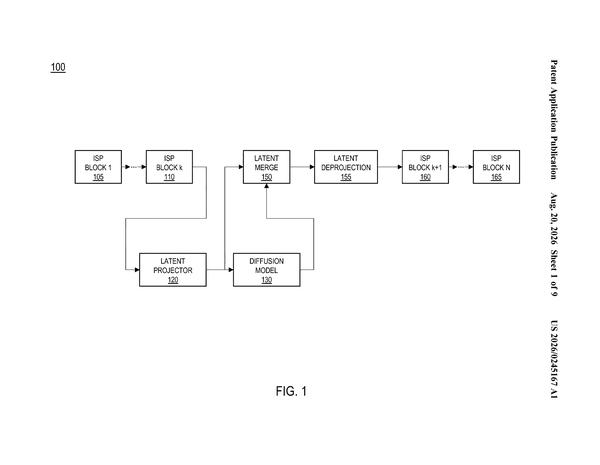
Compact neural networks embedded in the image signal processor itself let AI synthesis happen alongside sensor cleanup rather than after it, collapsing the pipeline delay that normally forces cloud offload or queuing.
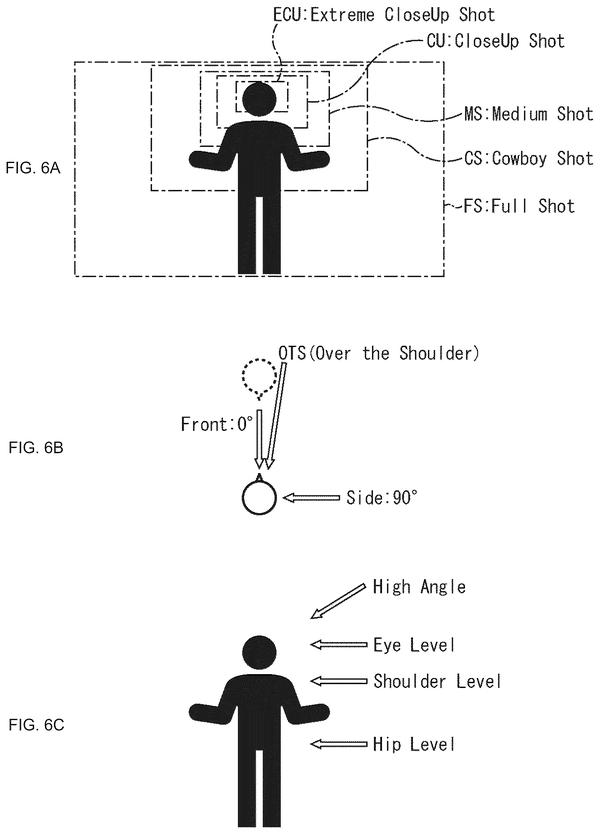
Sony is patenting a way to bottle a film director's visual signature, so that new scripts can be shot, automatically, in the style of Kubrick, Kurosawa, or whoever you pick.
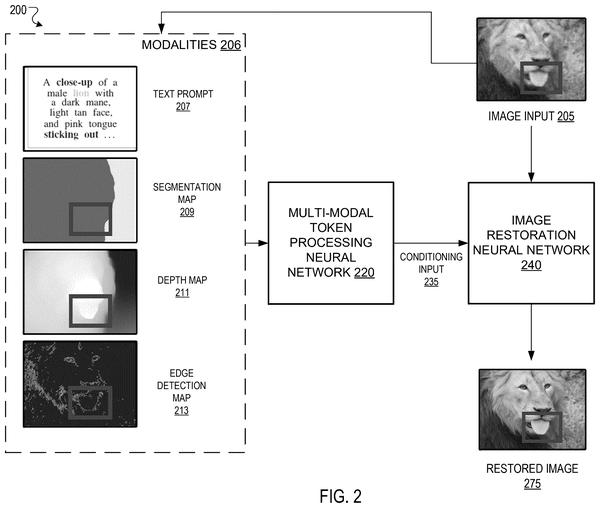
Breaking a photo into separate learned tokens for each object lets editors isolate and manipulate individual visual elements instead of treating the whole scene as one unit, moving the race beyond full-image operations.
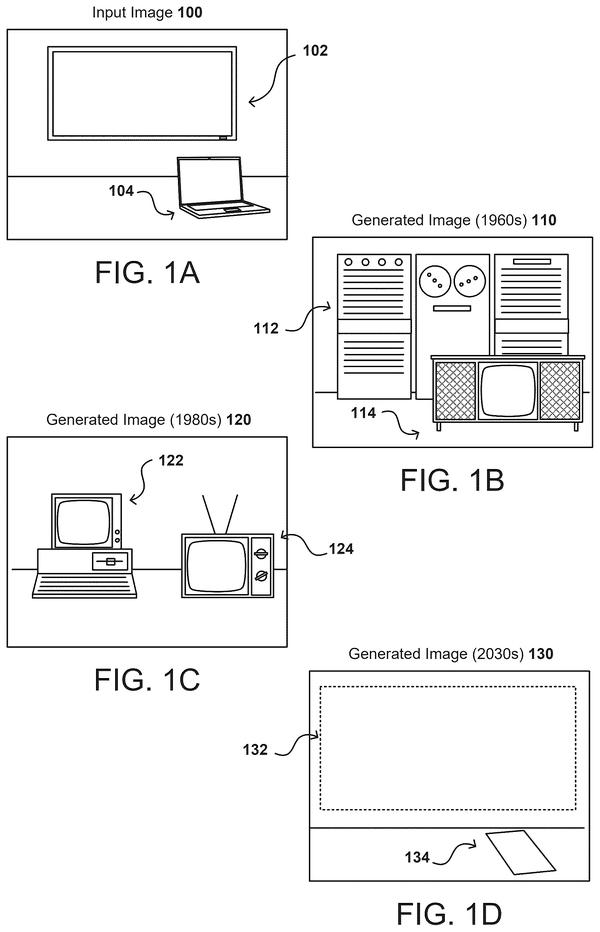
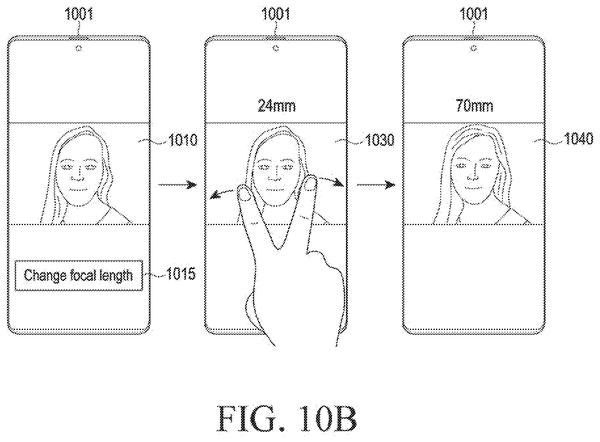
Lens distortion correction in the timeline has moved from optical fixes applied at capture time to post-shot AI redrawing that lets users pick their target focal length after seeing the result, shifting the problem from hardware constraint to software choice.
Sony is patenting a way for a game to look at a photo you upload and automatically decide how an in-game object should appear, skipping the manual sliders entirely.
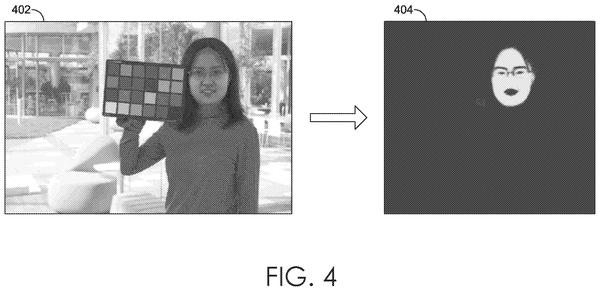
Users could skip manual white balance correction entirely if the software learns what neutral should look like for skin tones, clothing, or other known objects in the frame, moving beyond the pixel-averaging approach that plagues mixed-lighting scenes.
Solving flicker across frames expands the tracker's coverage from still-image edits into real-time video lighting correction, a harder constraint than per-frame processing.
Boundary frames between video chunks tend to drift in color and lighting when AI processes segments separately. Adobe's approach locks those junction points to shared parameters so adjacent chunks render with visual continuity.
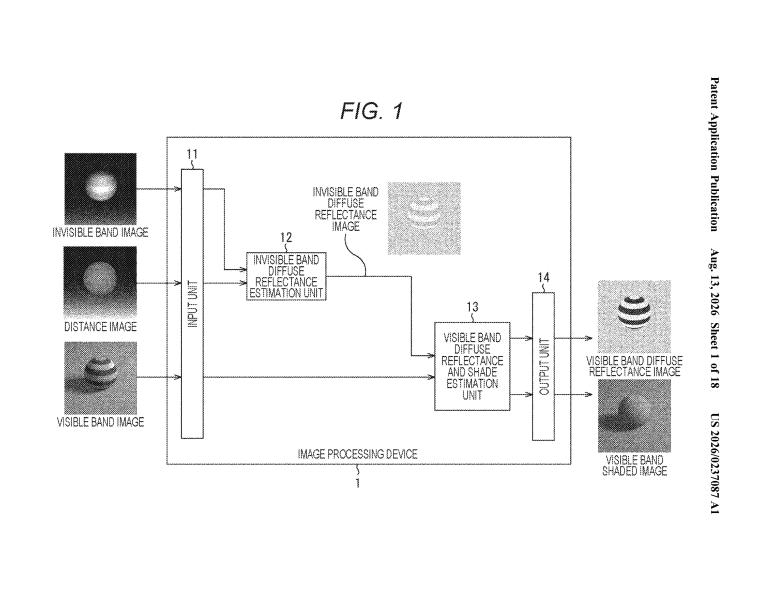
Extracting intrinsic color from cast shadows lets editors relight photos without recoloring the actual surface. This fills the gap between global adjustments and per-region edits by working at the optical physics layer.
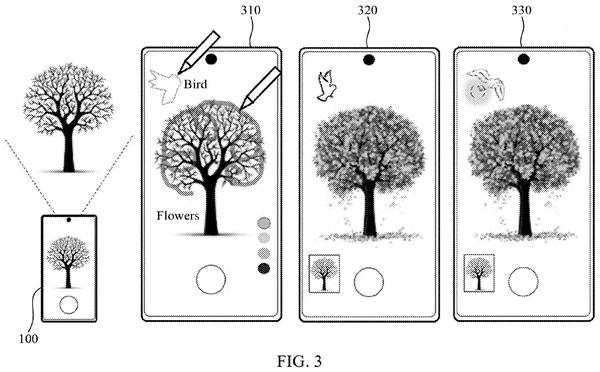
Users could compose photos by sketching directly into the live preview, letting the camera generate missing elements where they draw. This shifts the editing workflow from post-production touchups to real-time scene composition.
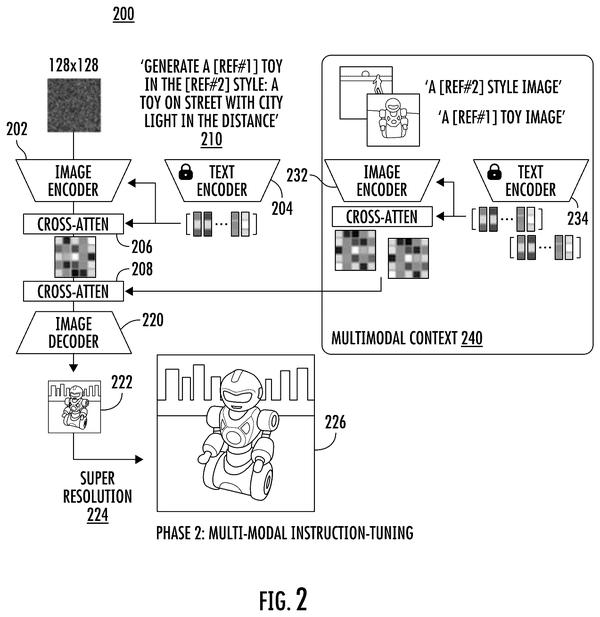
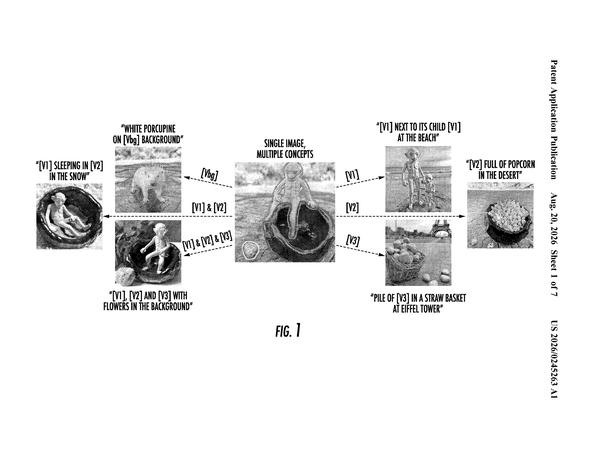
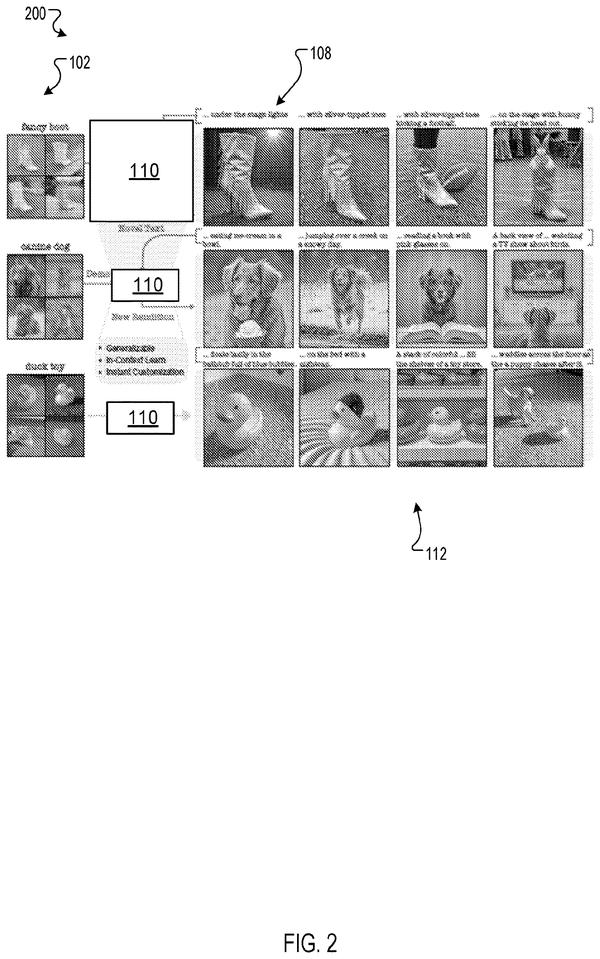
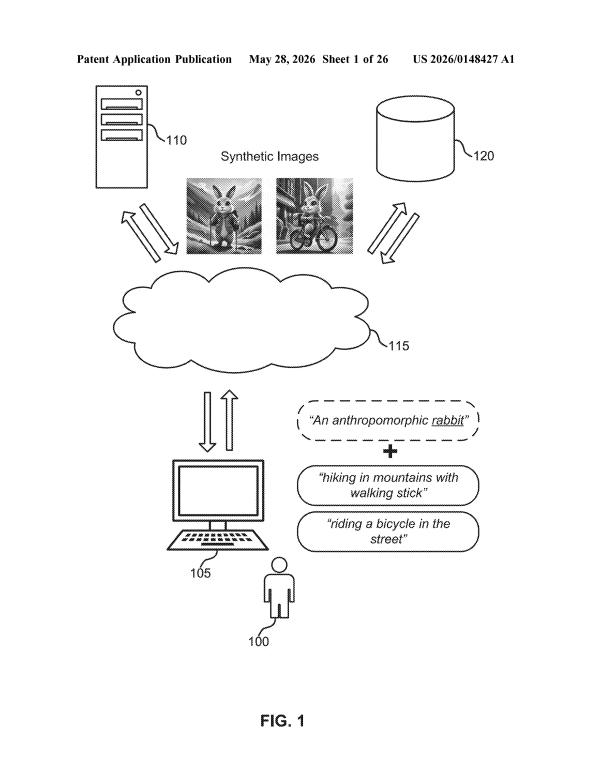
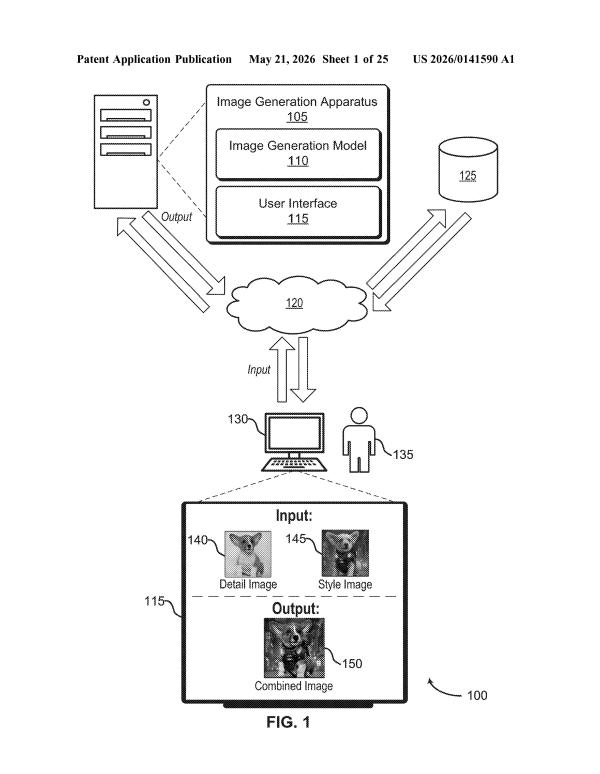
Personalizing edits from minimal reference shots lets AI recompose subjects into new scenes without requiring massive training datasets per user, narrowing the gap between generic photo tools and custom output.
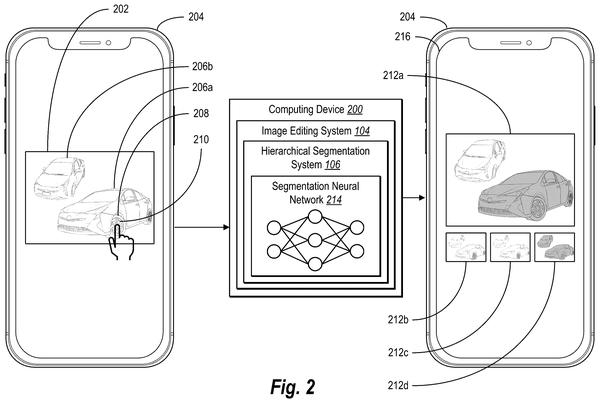
Selecting the right granularity of an object costs repeated clicks in current editors. Adobe's system generates hierarchical selections at once, letting users pick their desired scope from a single interaction without re-selecting.
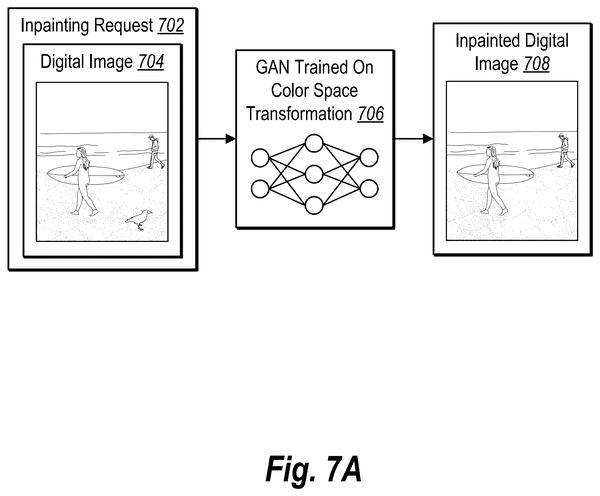
Color consistency in AI-generated fill regions stays prone to subtle mismatches. Adobe's dual color-space validation during training catches errors that single-pass evaluation misses.
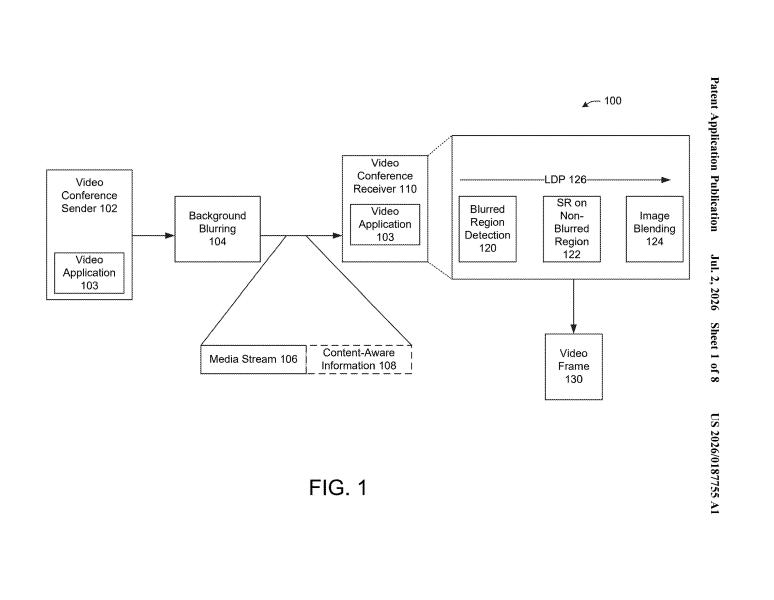
Users could get sharp subjects with blurred backgrounds without post-processing, since the camera chip itself would render foreground and background at mismatched resolutions and merge them before saving.
A generative model trained to infer absent objects from scene context rather than user prompts pushes the editing race toward fully automated completion, moving past text-guided tools toward systems that recognize what a scene should contain.
Motion transfer between unrelated subjects extends the editing race beyond appearance changes into movement synthesis, letting users impose choreography or gesture patterns without frame-by-frame animation.
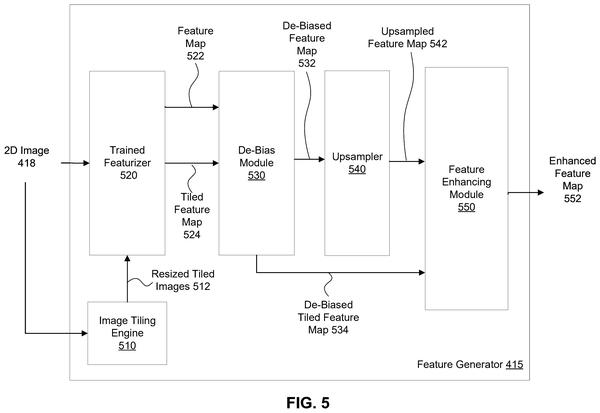
Reconstructing detail from compressed feature maps during inference sidesteps the blurriness that standard upscaling introduces when vision systems need to work with shrunk representations.
Nvidia trains generators to sharpen output by applying refinement in a secondary pass, steering models away from the statistical averaging that produces soft features in early generation stages.
Dual-level region analysis sharpens object boundary detection, a core bottleneck when users need clean selections in camera editing workflows where background separation determines final image quality.
Splitting noise removal from detail recovery lets the pipeline restore texture in low-light shots without amplifying grain, shifting the phone's post-processing toward selective refinement rather than blanket smoothing.
Sony's filing keeps on-screen content and presenters on separate layers during recording, skipping the frame-by-frame cutout work that usually follows.
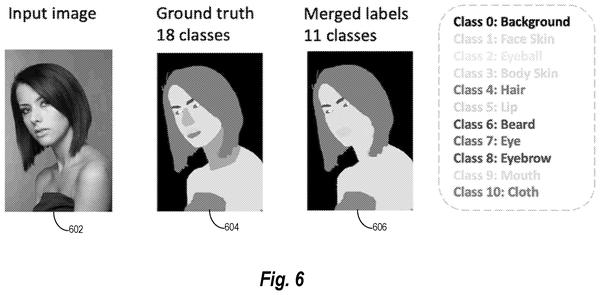
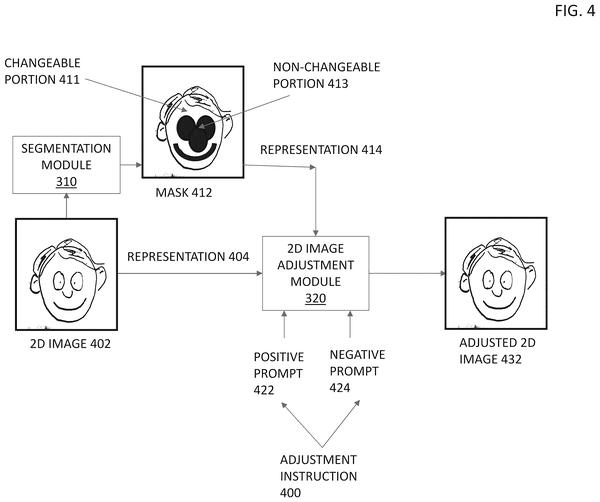
The per-region edits strand gains a key mechanism: semantic segmentation that sorts pixels by content type before applying distinct filter chains, solving the washed-out face problem.
Reconstructing detail from low-resolution input by first mapping the blur structure itself rather than guessing at missing pixels. Extends the tracker's compression and zoom preview coverage into satellite and remote imaging where pixel recovery matters most.
Auto-extracted keywords let users skip typing prompts, reducing friction in the text-guided editing workflow that other players require. Confirms the race is moving toward lower-barrier interfaces for AI recoloring and scene swaps.
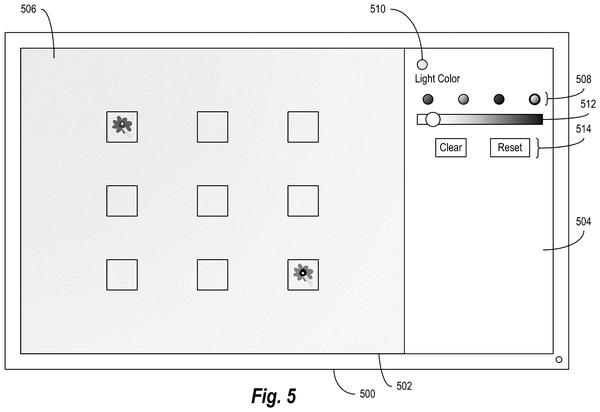
Reconstructing 3D geometry from multi-angle shots lets editors reposition light sources in post rather than reshooting or manually correcting each frame, a shift from 2D per-image fixes toward object-space relighting.
Storing a reference face model lets the system correct white balance drift by comparing live skin tones to known baseline, sidestepping the camera's general-purpose light guessing that fails under mixed lighting.
Adaptive bitrate assignment during encoding lets compression parameters shift frame-by-frame based on motion and scene content rather than applying uniform settings across an entire video, improving efficiency for mixed-pacing clips.
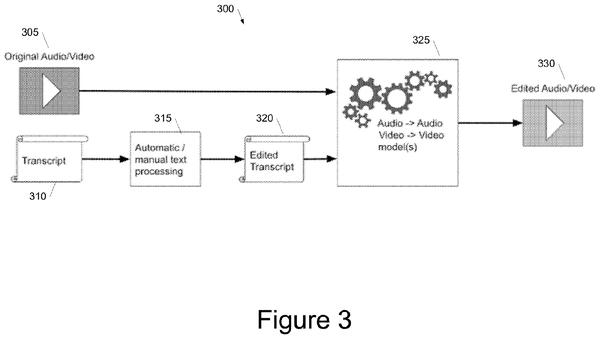
Syncing transcript edits back to raw media files lets users reshape audio and video from the text layer instead of the timeline, shifting the editing surface from waveform manipulation to document-style word deletion.
Separating brightness correction from color grading during multi-shot merging lets Samsung preserve natural tones where exposures overlap, a key step toward seamless HDR and panorama output that won't need manual fixes.
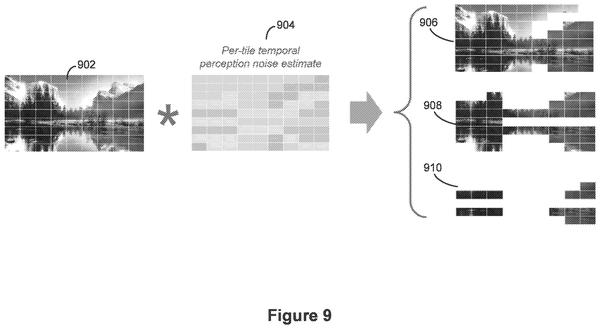
Selective noise filtering based on human visual perception lets the system prioritize smooth faces and subjects over peripheral areas, reducing computational load while maintaining perceived image quality in camera processing.
Users could watch stretched or gap-filled video without the blurring and stuttering that plague current frame-insertion tools, shifting the burden from post-production timing choices to predictive motion modeling.
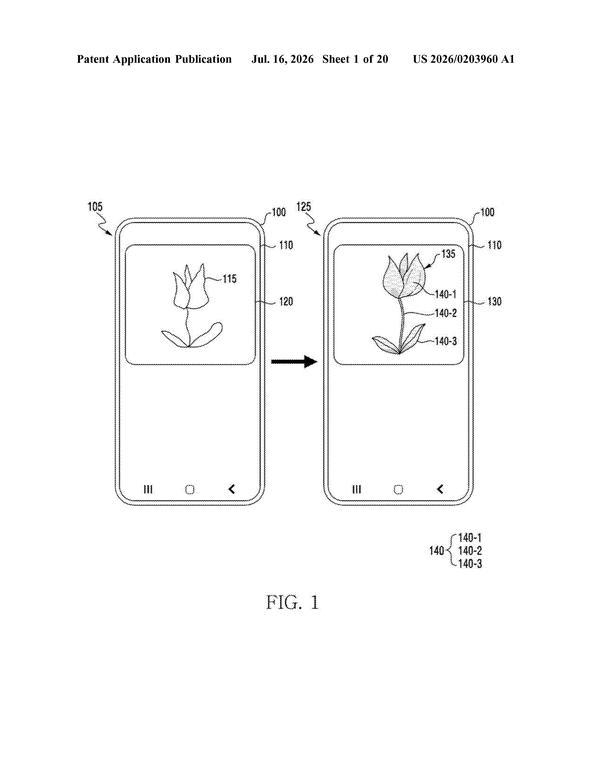
Users won't need to describe what they want changed; the system scans the image itself and offers preset alternatives for each detected element, speeding up the edit-select workflow that text-guided approaches require.
Merging multiple exposures into one frame requires separate AI models for highlights and shadows, a two-stage approach that avoids forcing a single model to balance conflicting exposure demands.
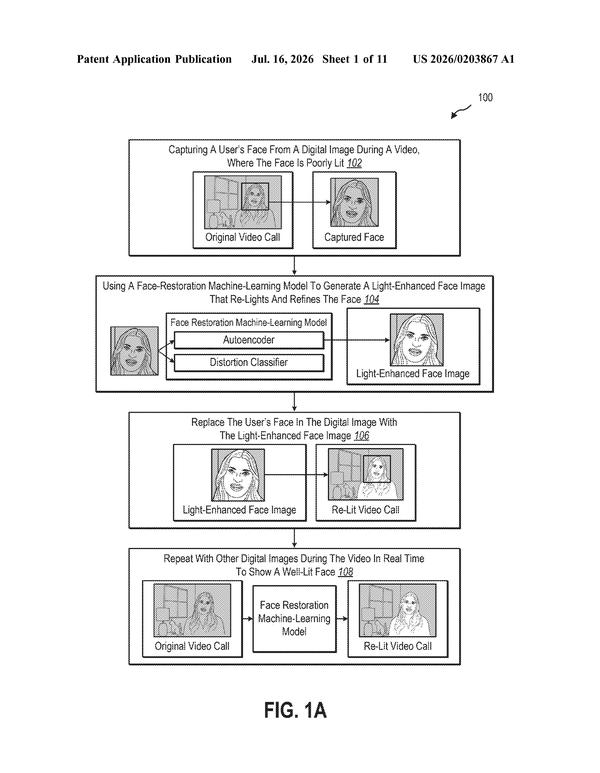
Poor facial visibility in dim environments blocks smooth video calls. Microsoft's filing describes real-time relighting that reconstructs underlit faces without hardware fixes or manual repositioning.
Reconstructing stable 3D scenes from video requires filtering transient objects like pedestrians and cars during model training, a step Google's method automates rather than leaving to manual cleanup afterward.
Users won't have to manually dial in edit intensity for each step, the system learns when to apply instructions heavily versus lightly across different image regions, reducing over-processing and artifact creep that text-guided edits typically suffer from.
Semantic photo reconstruction from natural language lets editors skip manual masking and regeneration workflows by describing desired changes in plain text.
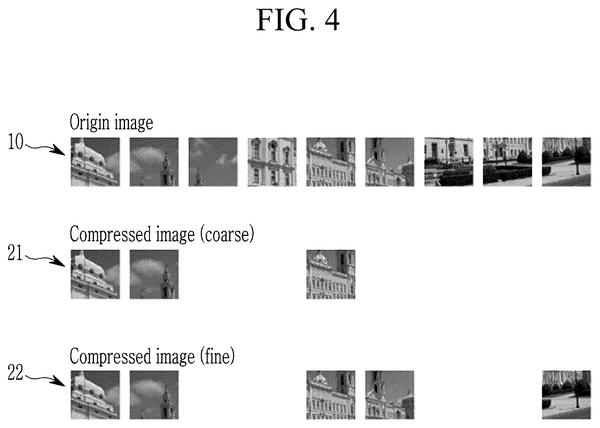
Compression artifacts need selective recovery. Google's filing lets a single compressed file generate multiple detail levels on decode, pushing the recreation work to the viewing device rather than baking in one quality choice at compression time.
Adaptive training on source footage itself rather than fixed datasets lets the upscaler tune to each video's specific noise patterns and content, sharpening results beyond generic models that must work across all input types.
Predicting future lighting and color shifts within a single frame moves beyond static filters into temporal reasoning, extending the tracker's coverage beyond per-region edits into physics-aware scene dynamics.
The confidence-based white balance system extends the race beyond binary correction into graduated adjustments, letting the camera pull back when lighting conditions resist a clean answer.
Within the race's focus on per-region edits, Adobe's filing confirms the race is moving into spatial reasoning: automatically inferring light direction and shadow geometry to make composited objects blend into their new backgrounds.
Swapping video backgrounds per viewer without re-rendering the foreground object adds a personalization layer to the editing race, moving beyond one-size-fits-all recoloring into dynamic content delivery that preserves the hero product across versions.
Sampling color values from adjacent frames to correct isolated color shifts in animation sequences fills a gap between Samsung's earlier text-guided recoloring work and the broader video consistency problem that Google and Nvidia have been pursuing.
Preserving 3D geometry during generation lets users reposition elements and adjust lighting after the fact, moving AI images closer to the malleable asset status of traditional 3D renders rather than locked photographs.
Separating compression noise from real image detail during streaming, Nvidia's layered detection approach identifies miscolored pixels without blurring edges, a direct fix for the banding and grid patterns that plague low-bandwidth video playback.
Frame-to-frame motion tracking lets the upscaler maintain pixel continuity across fast cuts and pans, addressing the compression artifacts that plague quick camera movements in low-res video.
Exposure bracketing during capture lets the camera recover detail across extreme lighting ratios instead of forcing a single-shot compromise, extending the editing race beyond software reconstruction to hardware capture strategy.
The compression and preview category now includes selective sharpening: Intel's approach separates intentional blur from quality loss before applying filters, letting devices sharpen only what needs it rather than degrading soft backgrounds.
Selective AI upscaling based on codec entropy signals reduces compute waste by skipping frames where compression artifacts are minimal, addressing the efficiency gap between per-frame processing and practical deployment.
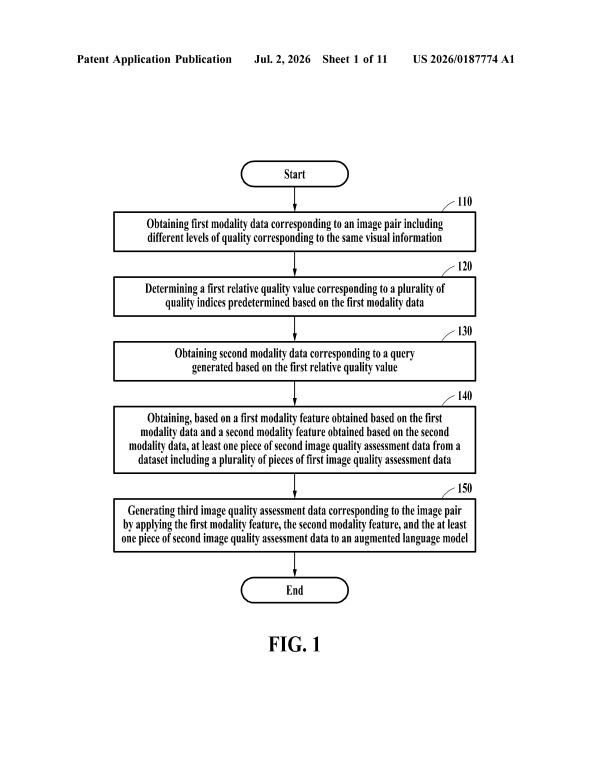
Retrieving similar photos from a database to justify quality comparisons lets the system ground its verdicts in real examples rather than abstract metrics, moving the feedback loop closer to how humans actually evaluate camera output.
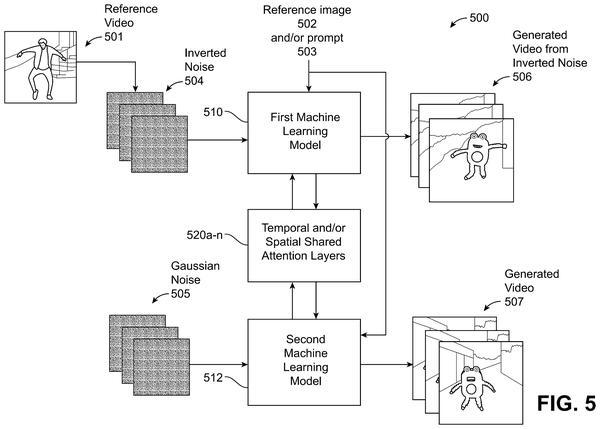
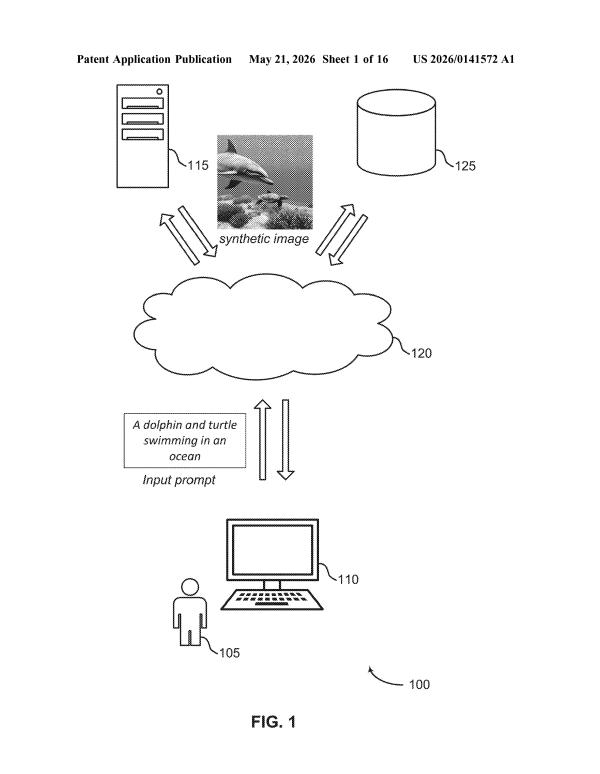
Photos with mismatched details across regions, a dog's leg disconnecting from its body, a couch edge that vanishes, would become rare if AI regions could share information during generation instead of working in isolation.
Batch object removal speeds up the core editing workflow by identifying and extracting multiple subjects simultaneously rather than forcing users through repetitive individual selections.
Automating prompt refinement shifts the bottleneck from user skill to machine interpretation, letting Adobe's software bridge the gap between casual description and generator-ready specification without manual editing cycles.
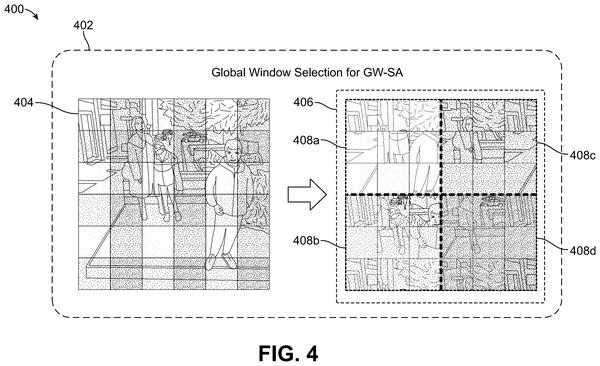
Breaking images into numbered chunks like text tokens lets Google run photo editing through the same AI models that already power its language systems, sidestepping the need for separate image-specific architectures.
Users typing casual commands like "zoom out" could get photos recomposed as if the camera had physically moved, shifting the race from editing pixels to repositioning the virtual camera itself.
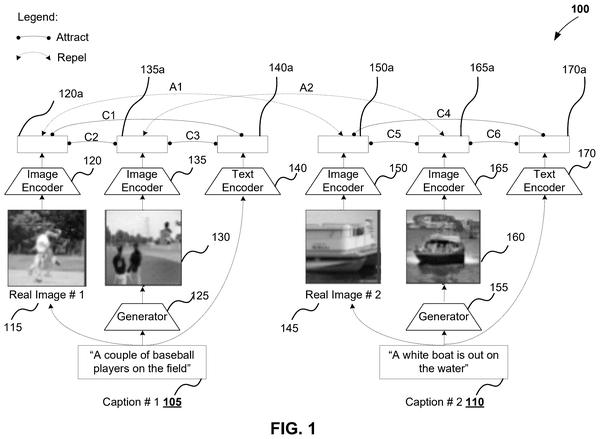
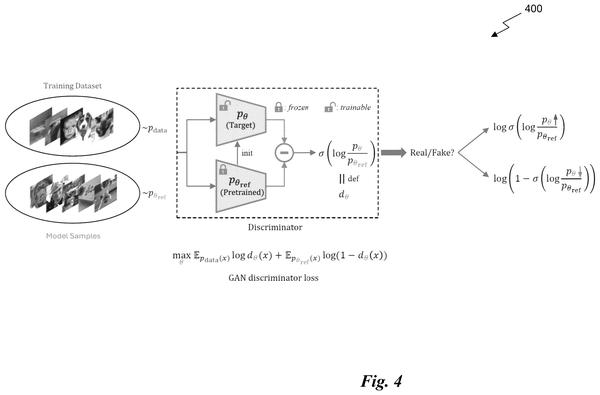
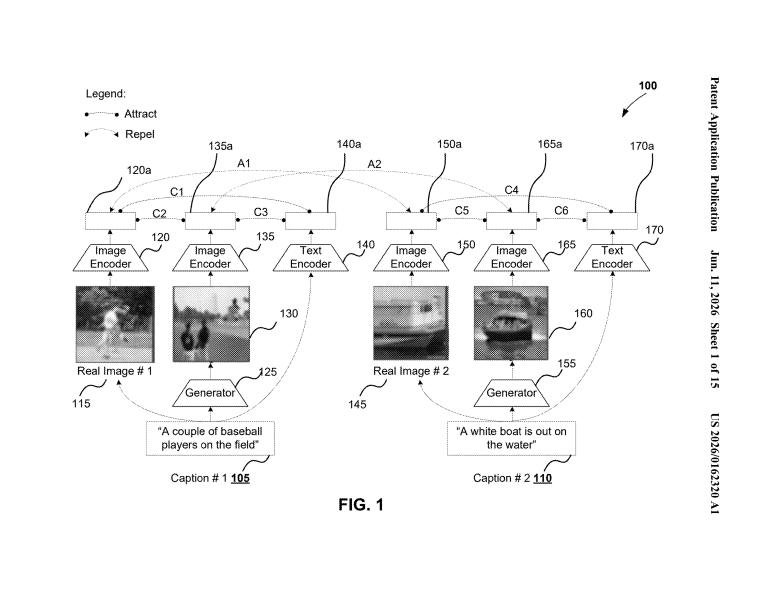
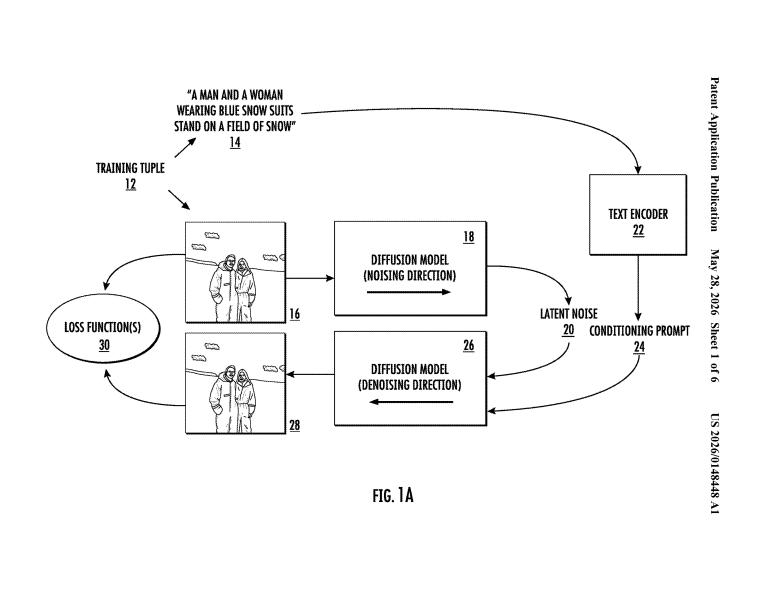
Pinning down which words map to which image regions during training. Google's method uses contrastive learning to force its generator to match text descriptions with sharper spatial precision, moving beyond approximate semantic alignment.
Photo edits need to know which parts they're inventing versus observing. Google's approach runs multiple reconstructions to flag where different 3D interpretations fit the same 2D image, letting the system mark its uncertainty rather than guess confidently.
Splitting exposure control by object instead of by frame region lets the system preserve face detail without blown-out skies, a different approach from traditional HDR's zone-based compromise.
Photos lose detail when bright areas max out the sensor. Google's method reconstructs those clipped pixels by training a generative model to invent plausible detail, rather than trying to recover what was never recorded.
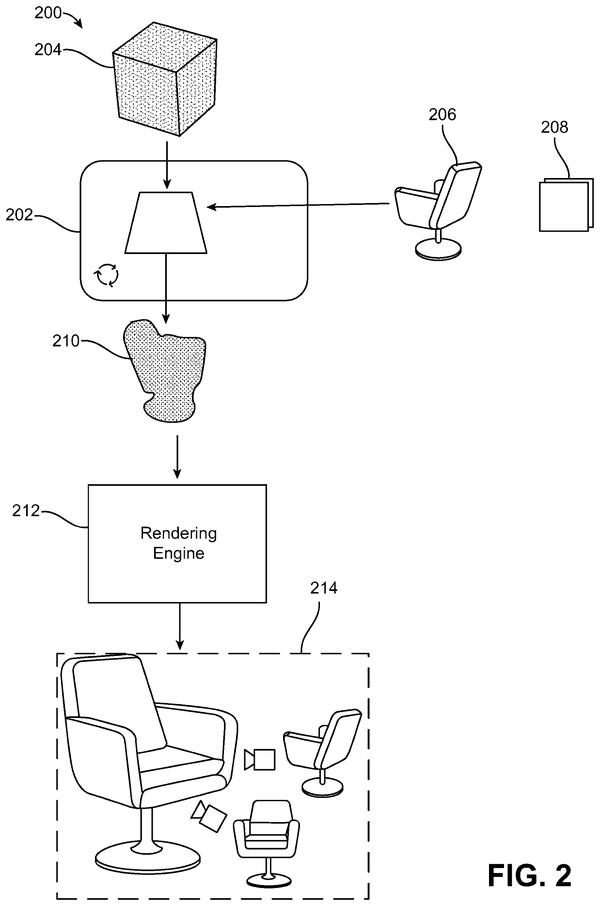
Reconstructing individual objects in 3D space from limited reference images solves a bottleneck in photo-to-model workflows where generic generation fails to preserve real-world specifics like wear patterns and exact colorways.
Running the removal process twice, first to fill the gap and then to refine the boundary, Adobe targets the artifact that haunts content-aware fill: the visible seam where synthetic pixels meet the original photo.
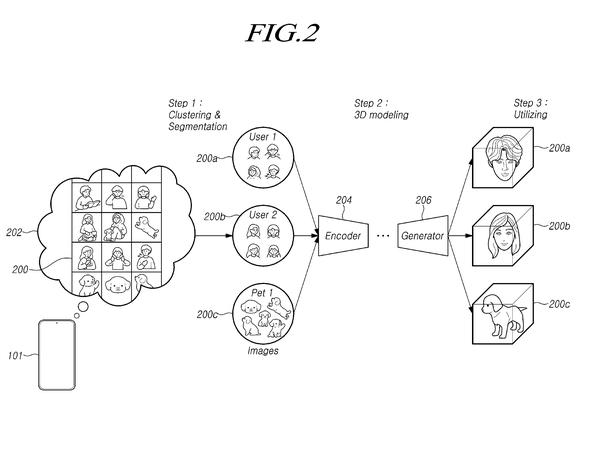
Training a generative model on messy, uncontrolled 2D photos sidesteps the need for expensive 3D capture rigs, letting companies build poseable digital humans from internet-scraped images instead of controlled studio data.
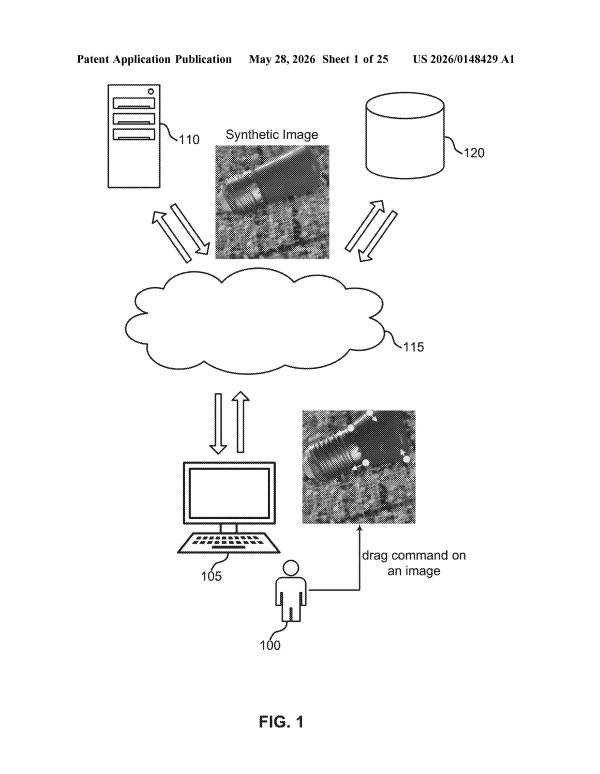
Making realistic pose changes with minimal user input. Adobe's system lets editors drag sparse control points to reshape objects, cutting the manual masking and warping that currently makes physical adjustments tedious.
Splitting image generation across multiple models in sequence lets each one focus on a specific quality problem, roughness, then color, then sharpness, rather than one model juggling everything at once.
Embedding character traits into the model itself rather than regenerating them per-prompt, so the same person stays recognizable across a multi-image sequence without manual intervention between frames.
Building realistic 3D human models from random internet photos instead of studio footage would let photo editors generate new poses and angles without reshoots, a major cost cut for the AI retouching pipeline.
Fitting photos to different aspect ratios without losing subject matter requires generating plausible pixels where none existed. Google's approach expands the image first, then crops, rather than choosing between distortion and loss.
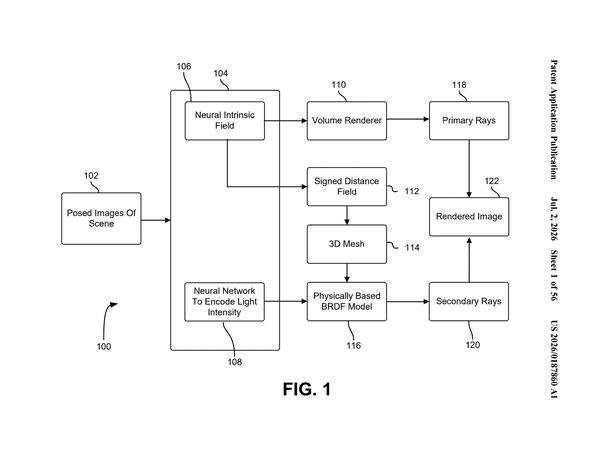
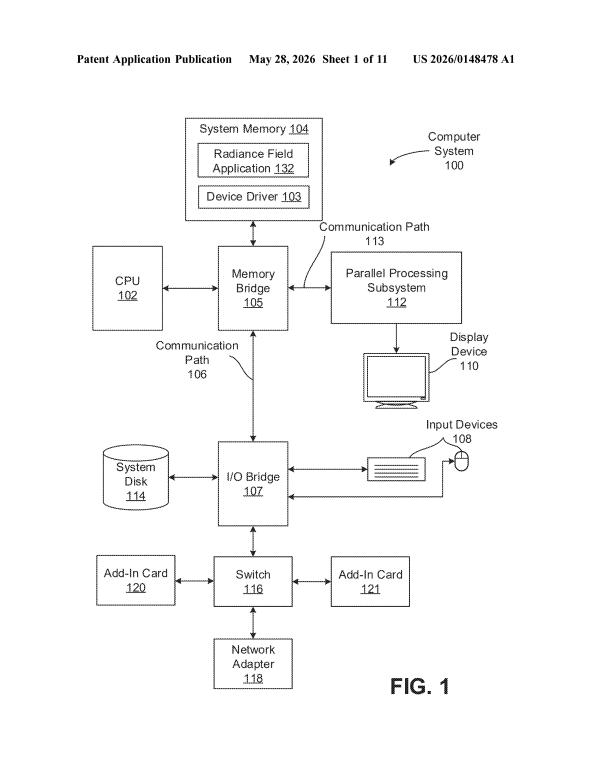
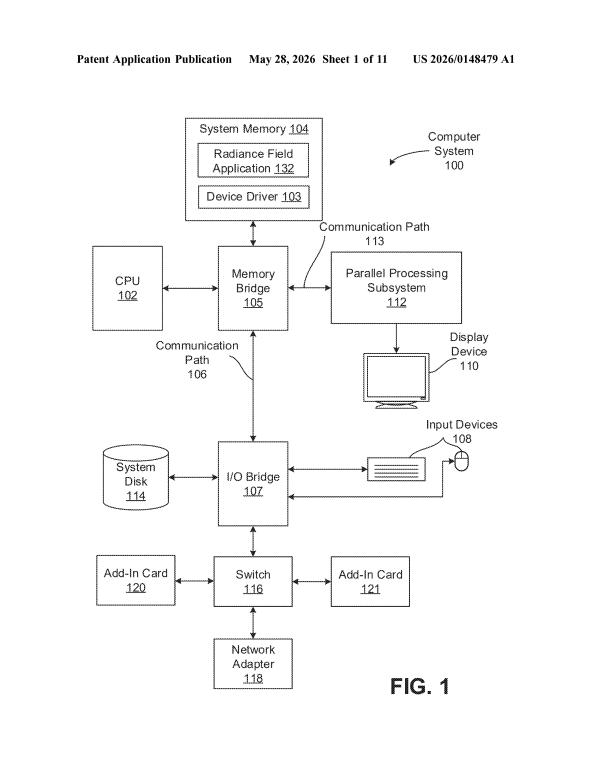
Real-time radiance field rendering would let editors apply light and view changes instantly rather than waiting for re-renders. Nvidia's Morton-code sorting accelerates the voxel lookup bottleneck that currently makes these edits feel sluggish.
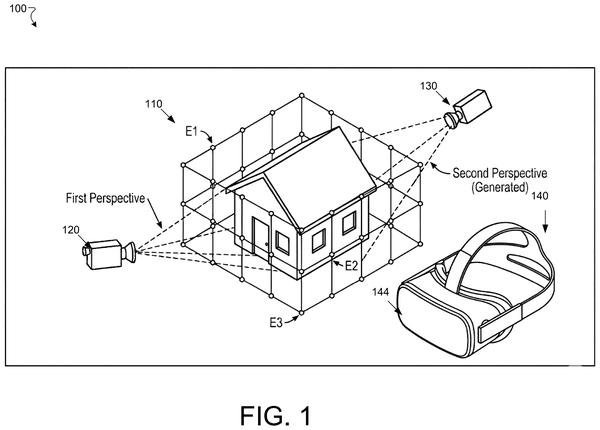
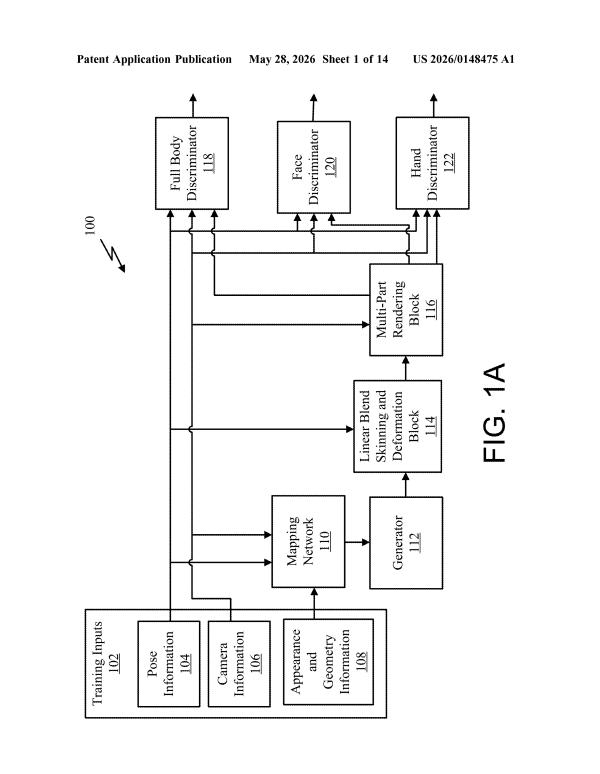
Nvidia's filing builds editable 3D scenes from photos in real time, which could let you change an image from several angles before flattening it back to 2D.
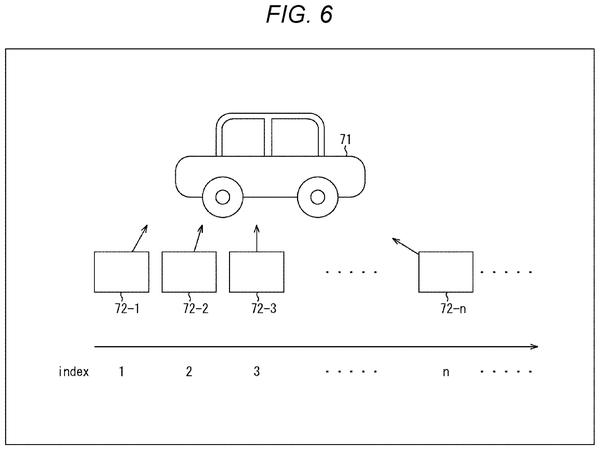
Reconstructing intermediate frames from multi-camera video in 3D lets editors pull usable shots from moments never actually recorded, filling gaps between the camera's capture rate and creative intent.
Users could reshape their photos by pointing to reference images instead of describing what they want, speeding up the editing workflow and reducing reliance on written prompts to guide the AI.
Gaussian splatting with learned motion tokens lets the system infer dynamic 3D geometry and movement directly from ordinary photo sequences, avoiding the depth sensors or manual annotation that currently bog down video-to-3D conversion.
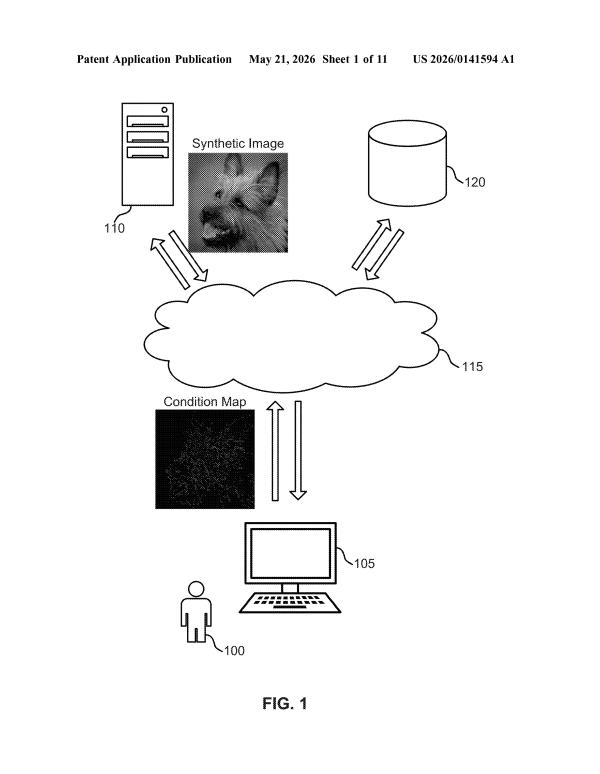
Companies racing to edit photos after capture need AI that follows spatial rules. Adobe's condition-map approach shifts the control earlier, letting users blueprint where objects land before generation even starts.
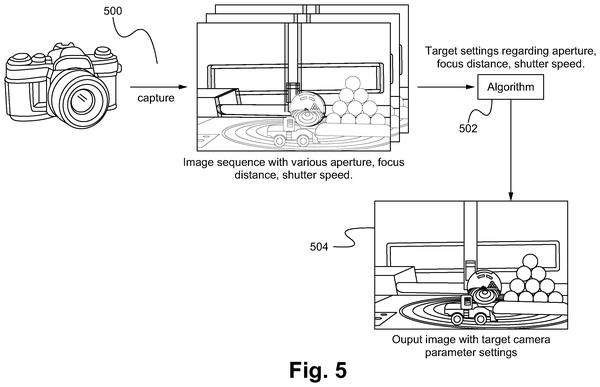
Photos with flawed exposure or focus could be auto-corrected before the user ever sees them, shifting the race from editing after capture to preventing bad shots in the first place.
Keeping spatial relationships stable in generated images requires enforcing layout constraints before rendering, which Adobe's method does by mapping object positions during the generation process itself rather than correcting them after.
Generating inpainting in two stages, global layout first, then local detail refinement, lets the AI match surrounding textures and perspective without the blurry compromise of single-pass methods.
Photos edited by AI would stay visually consistent with your existing brand instead of drifting toward generic templates. Adobe's approach extracts stylistic rules from your reference images to constrain what the generator can produce.
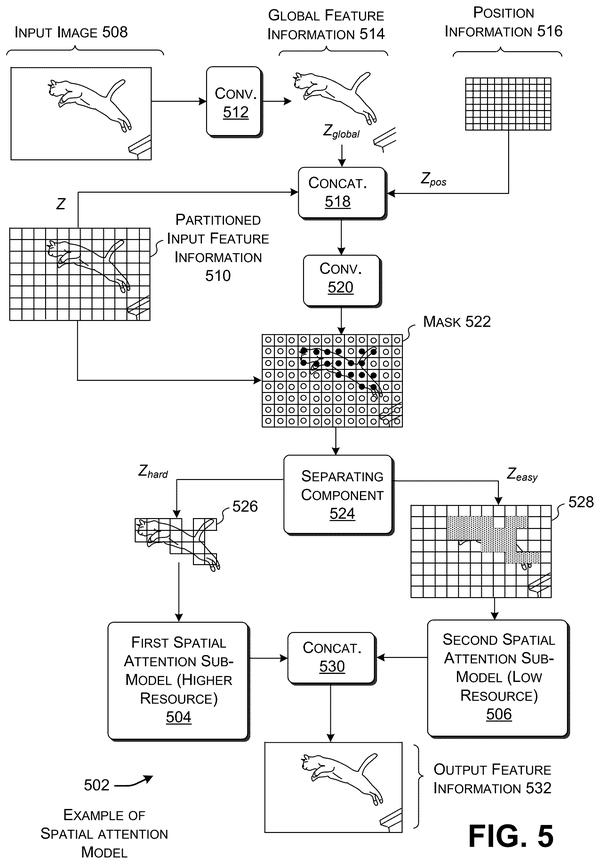
Photos could be edited faster if one AI model handles cutting out subjects, isolating skies, and detecting people in a single pass instead of running three separate networks.
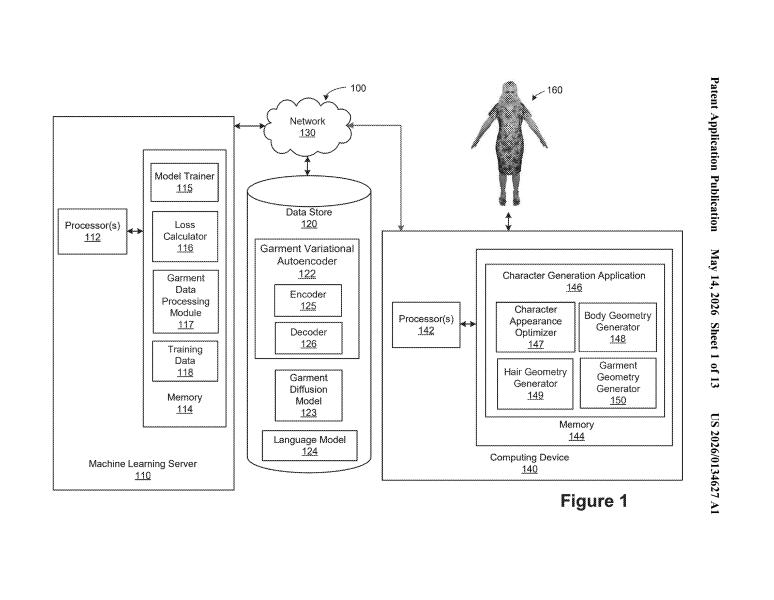
Generating clothing that physics engines can actually use cuts out the manual rigging step that currently requires technical artists to make garments move realistically in simulations.
Picking the right AI model for inpainting depends on scene complexity. Adobe's system analyzes visual difficulty first, then routes the job to whichever model handles that specific type of scene best.
A neural network that refines masks separately for each disconnected region stops Adobe's selection tool from averaging detail across a person's hand, fork, and hair as one blob.
Semantic segmentation of body parts before color assignment lets the network apply different color logic to faces versus hair versus fabric, solving the greenish-skin problem that plagues simpler colorization tools.
Photos edited after capture expand from still images into video: Nvidia's approach converts footage into riggable 3D models, letting creators animate people rather than just retouch them.
Generating photorealistic edits requires 3D geometry that won't break under physics simulation, Nvidia's approach builds that constraint directly into the generation step rather than fixing problems afterward.
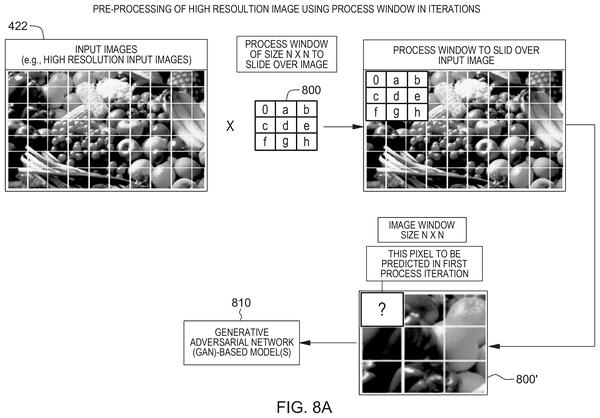
Within the race to move photo AI onto devices rather than cloud servers, Google is focusing on the training problem: how to pack restoration quality into models small enough for smartphones to run without lag.
Automating the rigging and skeleton step, making generated characters actually movable, pushes the race beyond static image editing into animated content creation.
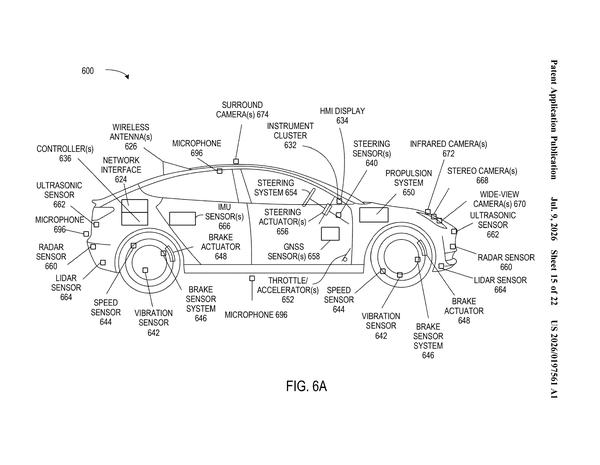
Running two depth sensors in parallel lets the system reject bad focus locks when one sensor gets fooled by close subjects, improving the raw material that AI photo editing later works with.
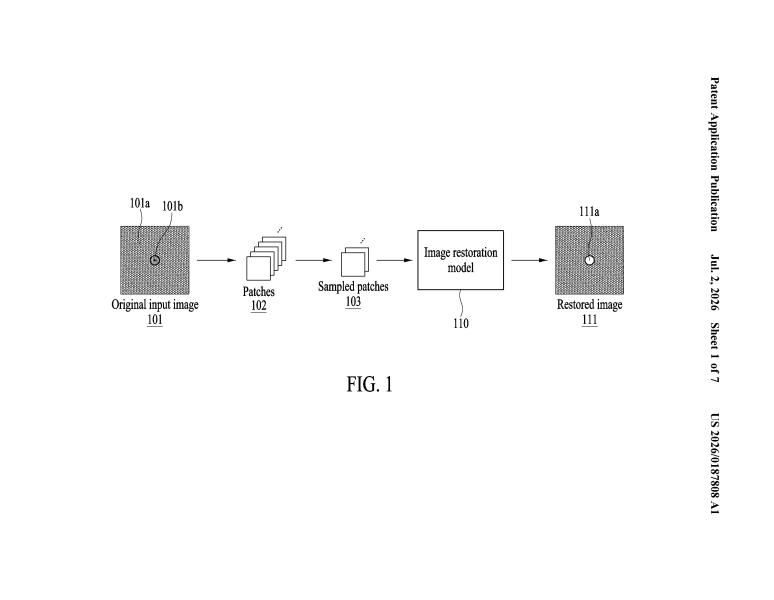
Photos edited with this system would rely on AI trained through a structured pipeline that separates the learning process itself, potentially making the fill-in results more consistent and predictable than current erase tools.
Generative models that iterate toward a text description reveal how companies are automating color grading entirely, moving the workflow from slider adjustments to natural language prompts.
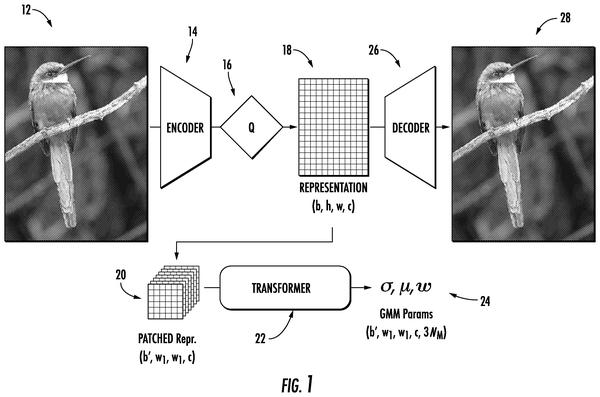
Storing a personalized AI model alongside compressed photos means the reconstruction happens on your device, not in the cloud, reducing the server load that photo editing at scale would otherwise demand.
Questions readers ask
Is Google actually building AI photo editing into products, or is this just patents?
These are patent filings, which show research direction, not confirmed features. Google has filed systems for per-region editing, text-based recoloring, compression, and zoom smoothing, but a patent does not guarantee any of these ship in a camera app. It signals where engineering time is going, not a release date.
Why does Nvidia show up in a photo editing watchlist?
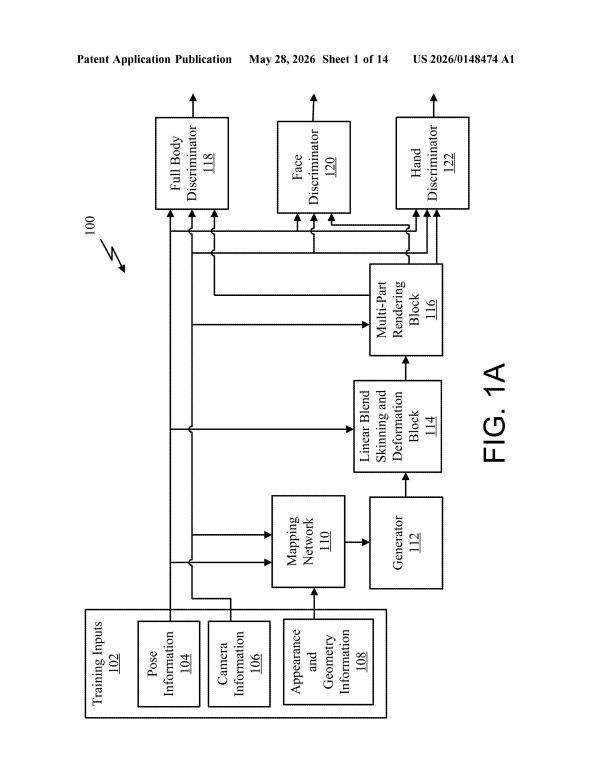
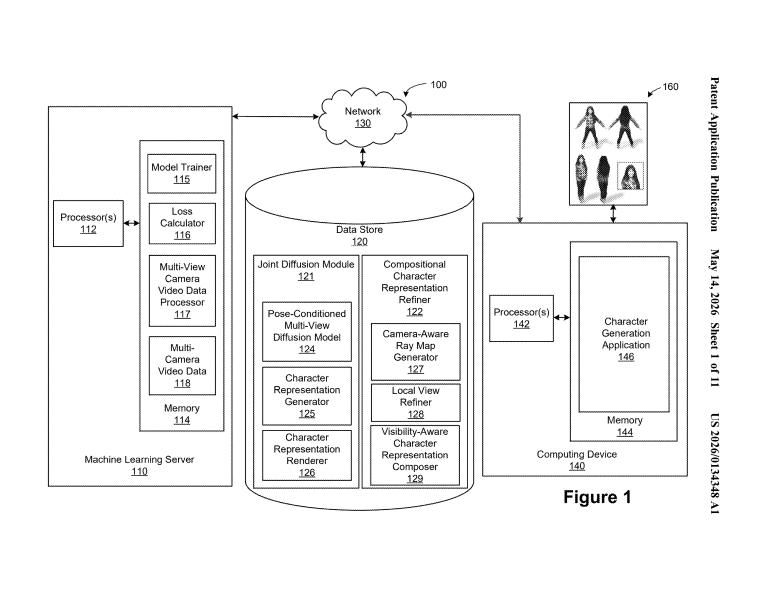
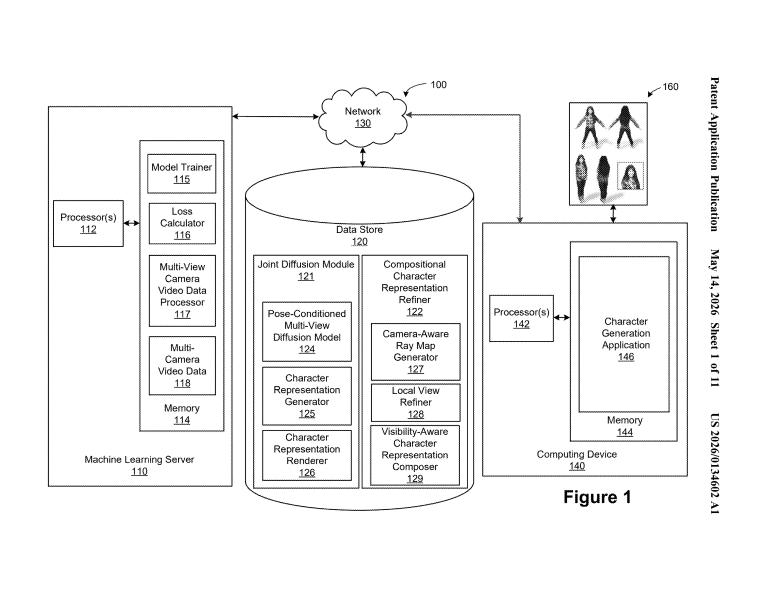
Nvidia's filings in this batch focus on turning text descriptions or video footage into animatable 3D characters, which overlaps with photo and image work through shared AI techniques like generative modeling. It is not photo editing in the traditional sense, but the underlying methods for building and refining visual content connect the two companies' patents.
What problems keep showing up across these patents?
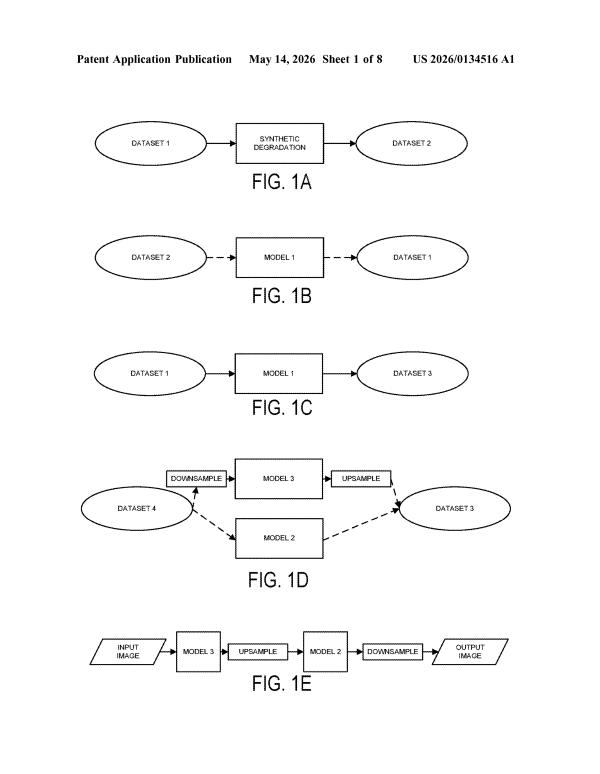
Several filings return to the same challenges: deciding which photos need heavy AI processing, editing different regions of an image with different rules, and shrinking images without losing quality on rebuild. Restoration and inpainting also appear more than once, suggesting both companies see removing flaws and filling gaps as an ongoing area worth patenting repeatedly.
Will these patents mean my phone's photos change soon?
Not necessarily, and not on any predictable timeline. Patents describe technical approaches companies want to protect, sometimes years before a feature reaches a device, if it ever does. This watchlist is a useful way to see what problems Google and Nvidia are actively working on, not a preview of your next software update.
Want this weekly breakdown for a company we don't cover?
Patentlyze Pro →
The weekly email: the best of Big Tech's filings, in plain English. Free.