
AMD
AMD · Chip · Filed Mar 24, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
AMD Patents a Way to Keep GPUs Busy While Memory Catches Up
GPUs are fast, but they spend a surprising amount of time just waiting for data to arrive from memory. AMD's new patent describes a way to sneak data-loading requests into the instruction queue so the chip is never caught idle.
- Publication number
- US 2026/0288642 A1(US20260288642A1)
- Applicant
- ADVANCED MICRO DEVICES, INC.
- Filed · Published
- Mar 24, 2025 · Sep 24, 2026
- Inventors
- Rakan Khraisha, Alexander Fuad Ashkar, Harry J Wise, Manu Rastogi
- Status when we published
- Approved; patent expected soon
- Document
- 20 claims
- US classification
- 711/137
- Examiner
- BLUST, JASON W (Art Unit 2132)
What AMD's GPU memory pre-loading trick actually does
A racing driver sits at the starting line, engine revving, waiting for the pit crew to finish loading the tires. The car is ready; the crew is the bottleneck. Your GPU faces a version of this problem every time it runs a complex game or AI workload.
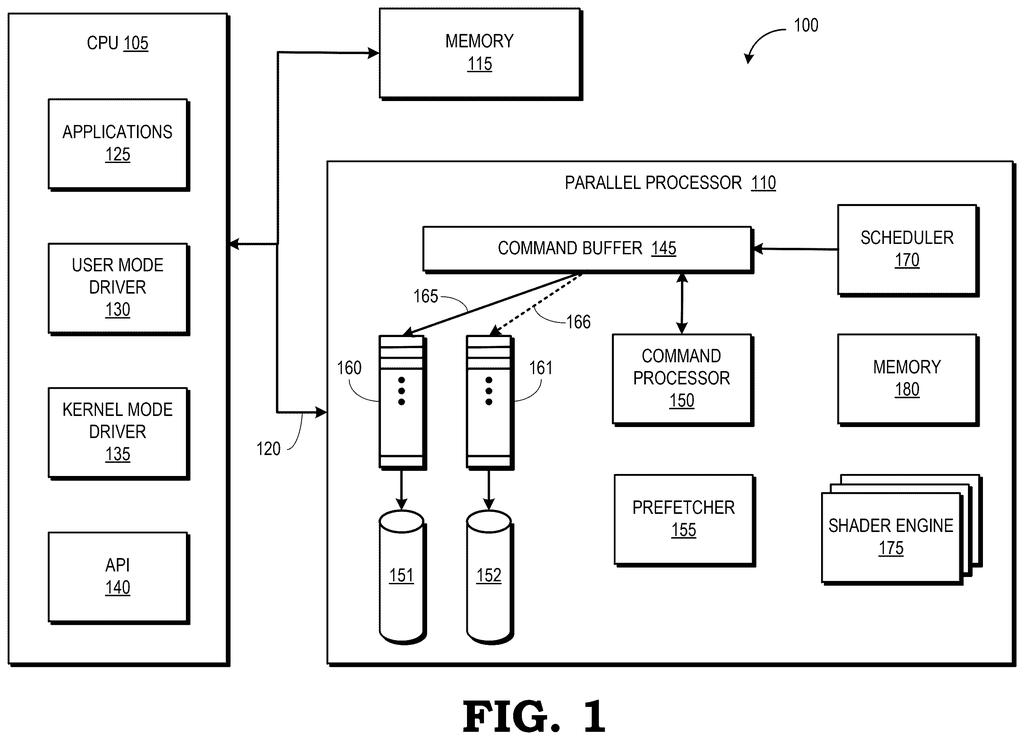
When a graphics chip processes a scene, it works through a list of instructions called a command buffer. Normally, it hits an instruction, realizes it needs some data from memory, and has to wait for that data to arrive before it can move on. AMD's patent describes stuffing small "fetch this data now" requests between the real work commands, so that by the time the chip gets to an instruction, the data it needs is already waiting.
The system figures out the right spacing for those pre-load requests based on the physical limits of the chip's local memory, so it doesn't over-stuff the queue or request too much at once. Both the software driver on your CPU and a processor inside the GPU itself can set this up.
… interleaving, at the command buffer, the prefetch packets with at least one of the indirect draw commands and the indirect dispatch commands …
Translation: Mixing data fetching instructions directly in with the regular rendering tasks.
How prefetch packets get woven into the command buffer
The patent centers on a structure called a command buffer, which is essentially an ordered to-do list that a GPU's command processor works through sequentially. The list normally contains indirect draw commands (instructions to render geometry) and indirect dispatch commands (instructions to kick off compute tasks, like AI inference or physics simulation). The word "indirect" means the actual arguments for each command, such as how many triangles to draw, are themselves stored in memory and have to be fetched at runtime.
The problem is that fetching those arguments from memory introduces latency (a delay, measured in nanoseconds, while the chip waits for data to travel from RAM). During that wait, compute units inside the GPU sit idle.
AMD's fix is to insert prefetch packets into the command buffer ahead of the commands that need them. A prefetch packet is a small instruction that says, in effect, "go grab this block of data from memory right now, before I actually need it." By the time the real draw or dispatch command executes, the data is already in the GPU's fast local memory.
The interleaving pattern, meaning how many prefetch packets appear before each command and how far apart they are spaced, is determined by the physical constraints of the GPU's on-chip memory. Either the CPU-side graphics driver or the GPU's own command processor can populate the buffer, which keeps the approach flexible across different workloads:
- Rendering-heavy workloads driven by indirect draw commands
- Compute-heavy workloads driven by indirect dispatch commands
- Mixed workloads that include both
An indirect command buffer mitigates memory latencies associated with fetching data, arguments, and state by interleaving prefetch packets with indirect draw commands and/or indirect dispatch commands.
Translation: The system hides memory delays by slipping data fetch requests right in between rendering commands.
What this means for GPU performance in games and AI workloads
For everyday users, the immediate target is smoother frame rates and lower GPU stall times in games and applications that use indirect rendering, a technique common in modern engines that hand the GPU a large batch of work at once. When a chip stalls waiting for memory, performance drops and power is wasted on a chip that is spinning without doing useful work.
the pattern in AMD's GPU-efficiency filings suggests the company is investing in squeezing more out of existing memory bandwidth rather than simply adding more. That matters because memory bandwidth is expensive in both cost and power, and this kind of software-level scheduling can deliver real gains without changing the underlying chip hardware at all.
AMD's 16th application we've tracked since June in our GPU rendering race watchlist follows training data for sharper images and skipping detail during camera moves.
Source: US 2026/0288642 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time AMD patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 4 sheets
4 drawing sheets from US 2026/0288642 A1 · click any drawing to enlarge


More from AMD
All 119 AMD patents →
More in Chip
All 645 Chip patents →
Qualcomm
Qualcomm Patents a Way to Polish Game Frames With a Dedicated AI Chip
Qualcomm
Qualcomm Patents a Graphics Chip That Converts Video Data Mid-Process Without Pausing
Nvidia
Nvidia Patents a Two-Processor System That Stops Games From Freezing Mid-Task
Intel
No comments yet