Nvidia
Nvidia · Chip · Filed Feb 14, 2025 · USPTO published Aug 20, 2026 · Aug 20 release
Nvidia Patents a Two-Processor System That Stops Games From Freezing Mid-Task
When a graphics processor finishes its work, something still has to clean up after it, and right now, that cleanup can stall the whole pipeline. Nvidia's new patent describes a way to hand that job off to a second processor that's better positioned to do it.
- Publication number
- US 2026/0245165 A1(US20260245165A1)
- Applicant
- NVIDIA Corporation
- Filed · Published
- Feb 14, 2025 · Aug 20, 2026
- Inventors
- Ziyad Hakura, Gregory Scott Palmer, Feiqi Su, Gentaro Hirota, Jonathan William Robbins
- Status when we published
- Examiner raised objections; the company can respond
- Document
- 20 claims
- US classification
- 345/501
- Examiner
- TSENG, CHENG YUAN (Art Unit 2615)
How Nvidia's memory-lock handoff actually works
You're running a heavy graphics workload, a game, a simulation, maybe an AI render, and behind the scenes, your GPU is juggling dozens of tasks at once. Each task claims a chunk of memory and holds a "lock" on it, like putting a 'reserved' sign on a table, so no other task can touch it mid-work.
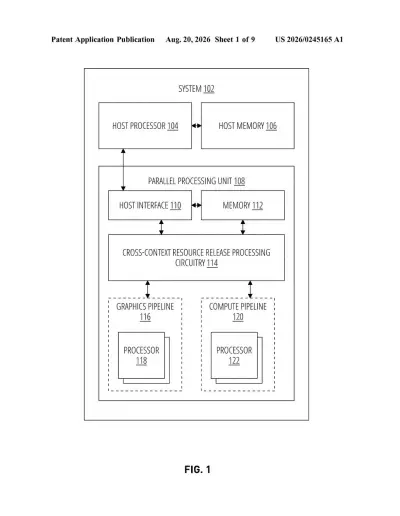
The problem comes at the end. When the first processor finishes its job, it can't always release that lock itself because the lock lives in a different memory space than where the processor is currently working. Nvidia's patent proposes a fix: the finishing processor sends a signal to a second processor that does live in the right memory space, and that second processor does the cleanup instead.
The result is that locks get released faster and the pipeline keeps moving, rather than sitting idle while the wrong processor tries to reach across a memory boundary it can't easily cross.
acquiring a first lock within a first memory context; providing first work to be executed by a first processor, wherein the first processor executes within a second memory context; receiving a first signal from the first processor that the first lock can be released; …
Translation: The system secures a memory resource while sending tasks to the first processor.
How the two-processor signal chain releases the lock
The patent centers on a concept called a lock, a software mechanism that reserves a shared resource (a block of memory, a buffer, a data structure) so only one task can write to it at a time. Locks are everywhere in parallel computing; without them, two processors writing to the same address simultaneously would corrupt data.
The complication Nvidia is solving is a memory context mismatch. A memory context is essentially a processor's view of the address space, its own private map of where things live. When two processors operate in different memory contexts, they can't directly touch each other's resources. That's usually fine, but it creates a handoff problem: if the processor that acquired the lock runs in one memory context, and the lock itself lives in a different memory context, that processor can't release the lock directly when it's done.
The patent's method works in four steps:
- A first memory context acquires a lock, then hands off work to a first processor running in a second memory context.
- That first processor does the work and, when finished, sends a signal indicating the lock can be released.
- The signal is routed to a second processor that runs in the first memory context, the same context where the lock lives.
- The second processor releases the lock directly, without any cross-context reach.
The key insight is that who releases the lock matters as much as when it's released. By routing the release to a processor that already has the right memory context, the pipeline avoids stalls caused by cross-context access penalties.
Disclosed are systems and techniques for efficient release of computing resources across memory contexts and processor pipelines.
Translation: The patent covers methods for managing shared memory and tasks between different processors.
What this means for GPU workload efficiency
GPU pipelines live and die on throughput. Every millisecond a lock sits unreleased is a millisecond the next task spends waiting, and in workloads that chain thousands of small tasks together (AI inference, real-time rendering, physics simulation), those waits add up fast. A cleaner lock-release path means more tasks per second on the same hardware, which matters whether you're a data center operator paying for GPU time by the hour or a gamer who just wants a steady frame rate.
For chip architects and systems engineers, Patentlyze covers these kinds of plain-English patent summaries on GPU pipeline management and parallel computing from Nvidia and its peers, where incremental efficiency gains like this one often have outsized effects on real workload performance.
Nvidia's 24th filing we've tracked since July in our GPU rendering race watchlist builds on earlier applications covering faster text searches on GPUs and smoother curved surfaces.
Source: US 2026/0245165 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 9 sheets
9 drawing sheets from US 2026/0245165 A1 · click any drawing to enlarge


Show sheet 9

More from Nvidia
All 665 Nvidia patents →
More in Chip
All 651 Chip patents →
Intel
Intel Patents a GPU Shortcut That Skips Redundant 3D Geometry Work
Samsung
Samsung Patents a Chip That Loads the Next Filter While the Current Image Renders
Intel
Intel Patents a Fix That Keeps Its Graphics Chips Busy While Drawing Scenes
Qualcomm