Samsung
Samsung · Chip · Filed Jan 8, 2025 · USPTO published Jun 25, 2026 · Jun 25 release
Samsung Patents Technology That Stops Processors From Stalling While Teaching Computers New Skills
- Publication number
- US 2026/0178912 A1(US20260178912A1)
- Applicant
- SAMSUNG ELECTRONICS CO., LTD.
- Filed · Published
- Jan 8, 2025 · Jun 25, 2026
- Inventors
- Ziyan ZHAO, Beomsig CHO, Dan CAO, Kun DOU
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 706/16
What Samsung's GPU data pre-loading system actually does
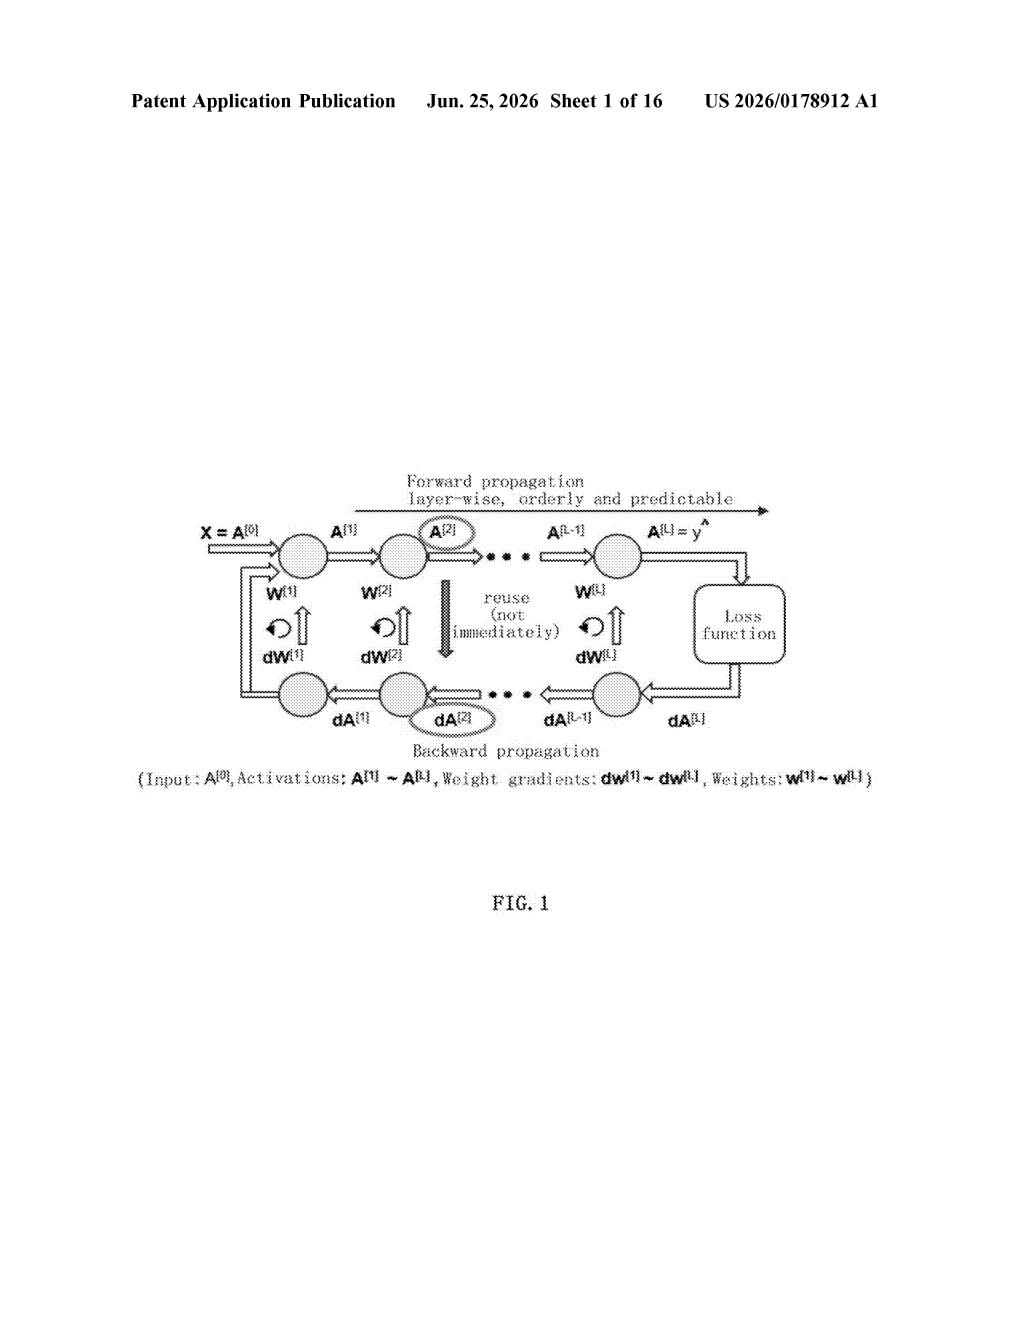
When you train a large AI model, the process involves running data through many layers, forward and then backward, over and over. The problem is that modern AI models are so large they don't fit entirely in a GPU's fast memory. That means the system constantly has to fetch data from slower storage, and the GPU sits idle waiting. That's expensive and slow.
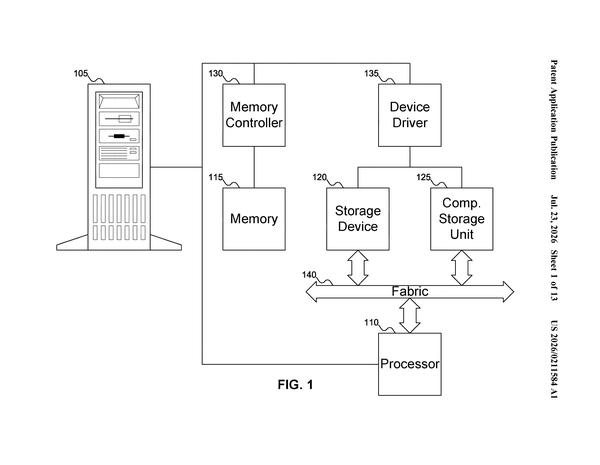
Samsung's patent describes a coordination system where a central "host" chip orchestrates two things at once: it tells the GPU which data to load right now, and it simultaneously tells the storage drive to start pulling the next batch of data into a faster middle layer of memory. By the time the GPU finishes with the current data, the next chunk is already waiting nearby.
The key detail is that the system checks how much room is available in that middle memory layer before deciding what to pre-load, so it never accidentally overfills it. It's essentially a pipeline manager for AI training data.
How the host coordinates DRAM prefetch and GPU loading
The patent targets the backward propagation phase of neural network training (the step where the model calculates errors and adjusts its internal weights). This phase is particularly memory-hungry because it needs to revisit data that was generated during the forward pass, data that may have already been pushed out of fast GPU memory to make room.
The system has three memory tiers in play:
- NAND flash storage: the slowest but largest layer, where overflow data lives on the SSD
- DRAM inside the storage device: a faster intermediate buffer sitting between the SSD and the GPU
- GPU on-chip memory (HBM): the fastest layer, where the GPU actually does its work
The host apparatus (essentially the CPU or system controller) acts as a traffic coordinator. It sends two parallel instructions: one telling the GPU to load current-layer data from DRAM into its own memory, and a second telling the storage device to begin pre-fetching the next layer's data from NAND flash into DRAM. The prefetch decision is gated by checking available DRAM capacity, preventing buffer overflow.
The result is that data movement across all three tiers happens in parallel rather than sequentially, which reduces or eliminates the GPU stall time that would otherwise occur between training layers.
What this means for training very large AI models cheaply
GPUs are among the most expensive hardware in any AI training cluster, and they're only valuable when they're actually computing. Every millisecond a GPU spends waiting for data to arrive from slower storage is wasted money. For companies training very large models that can't fit entirely in GPU memory, this kind of intelligent pre-fetching can meaningfully reduce training time and cost.
For Samsung specifically, this patent is strategically interesting because Samsung makes both NAND flash storage and DRAM. A storage device that actively participates in AI training pipelines, rather than just passively handing over data, could become a real product differentiator as AI infrastructure spending grows. Your AI training bill could shrink if the storage drive itself becomes a smarter partner in the process.
Source: US 2026/0178912 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Samsung patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.