
Intel
Intel · Chip · Filed Mar 28, 2026 · USPTO published Aug 13, 2026 · Aug 13 release
Intel Patents a Way to Split AI Model Memory Across Two Chip Types at Runtime
Running a large AI model on a single device means constantly fighting over memory. Intel's new patent describes a system that automatically decides, layer by layer, which parts of an AI model should sit in fast chip memory and which can wait in slower storage.
- Publication number
- US 2026/0236467 A1(US20260236467A1)
- Applicant
- Intel Corporation
- Filed · Published
- Mar 28, 2026 · Aug 13, 2026
- Inventors
- Madhur KUMAR, Sandeep Kumar, Sathvik Swaminathan, Sreenivas Subramoney
- Status when we published
- On hold at the patent office
- Document
- 20 claims
- US classification
- 707/715
How Intel's memory-splitting idea speeds up on-device AI
Every time an AI assistant on your phone or laptop generates a response, it's pulling data from memory thousands of times per second. The faster that memory, the faster the answer. But fast memory is expensive and limited, so devices have to make trade-offs.
Intel's patent describes a system that watches which part of an AI model is actively running and shuffles the right data into the fastest available memory just in time. Think of it like a chef who keeps the ingredients for the current dish on the counter and stores everything else in the pantry. The system also handles database searches that AI models often need to run, doing those lookups out of order when there's a spare moment, rather than waiting in line.
The result is that more of an AI model's workload fits on a single chip without grinding to a halt, which matters a lot if you want AI that runs locally on your laptop or PC rather than shipping your data to a remote server.
determining a memory split between a kev-value (KV) cache and weights for memory of a first type to be used by a machine learning model based, at least in part, on a total amount of available memory of the first type for the machine learning model and an indication of which layer of the machine learning model is to execute using an accelerator …
Translation: The system decides how to divide AI data between two memory types based on available space and which chip handles the task.
How the system decides what data lives where
The patent describes a two-tier memory architecture for running AI models (specifically large language models, or LLMs) on a single device.
The system tracks two critical types of data that LLMs constantly need:
- KV cache (key-value cache): a running record of everything the model has processed so far in a conversation, which grows as the conversation gets longer
- Weights: the trained parameters that define how the model thinks, which are fixed but large
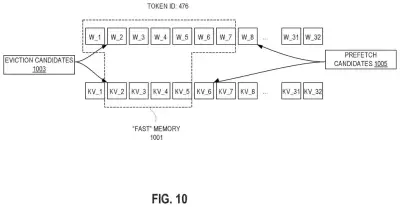
A memory manager component determines a split at runtime, deciding how much of each type of data fits in fast accelerator memory (like GPU VRAM or an NPU's dedicated SRAM) versus slower system memory (like regular DRAM). It adjusts this split based on which layer of the model is currently executing, migrating data in and out of fast memory accordingly.
Separately, a vector database search module handles lookup requests (a common step where an AI model searches a database of stored facts or documents to ground its answers). The patent's key claim here is that these lookups can happen opportunistically and out of order (meaning the system doesn't wait for a lookup request to be first in line; it fires one off whenever the hardware has idle cycles). That prevents the AI model from sitting idle while waiting for a search result.
… the machine learning model memory manager is to determine and implement a memory split between the memory of the first type and the memory of the second type for the KV cache and weights of the machine learning model and the vector database search module is to perform an opportunistic, out-of-order vector database lookup upon receiving a vector database request.
Translation: A manager balances AI data across different memory chips while the system searches databases whenever it has a spare moment.
What this means for running AI directly on Intel chips
The memory wall is one of the most concrete bottlenecks holding back on-device AI today. Running a capable LLM locally requires moving enormous amounts of data in and out of fast memory continuously, and most consumer chips simply don't have enough fast memory to hold an entire model at once. The better a system gets at deciding what data to keep close, the more capable the model you can run without needing a data center.
Intel's approach ties directly into its push to make its own chips, including its Arc GPUs and AI-focused NPUs, credible platforms for local AI workloads competing with Nvidia and Apple Silicon. The out-of-order database lookup piece is especially practical: retrieval-augmented generation (where an AI checks a personal document library before answering) is increasingly common, and stalling the model to wait for each search is a real throughput cost. This filing sits alongside the broader wave of on-device AI infrastructure patents covered in the latest Big Tech patents, where chip companies are racing to close the gap between cloud AI performance and what a laptop can do locally.
Source: US 2026/0236467 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Intel patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
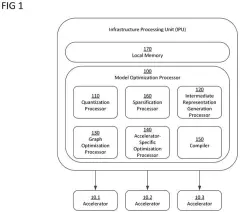
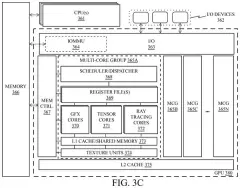
The drawings · 24 sheets
24 drawing sheets from US 2026/0236467 A1 · click any drawing to enlarge


Show the other 16 sheets


More from Intel
All 199 Intel patents →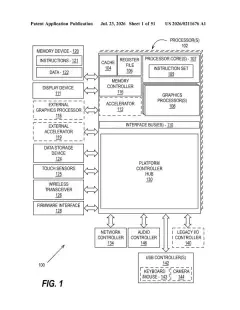
More in Chip
All 651 Chip patents →
Apple
New Apple Patent Shrinks AI Data on Chip Using Lookup Tables
Qualcomm
Qualcomm Patents an AI System That Auto-Tunes Chips Across Manufacturing Differences
Qualcomm
Qualcomm Patents a Backup Channel That Keeps Chiplets Running After a Link Failure
Samsung
