
Microsoft
Microsoft · Chip · Filed Feb 7, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
Microsoft Patents a Chip That Loads AI Model Data Before It Is Required
Microsoft has filed a patent for a dedicated coprocessor that tries to predict, in advance, which chunks of an AI language model will be needed next, and loads them into a cache buffer before the main AI chip even asks.
- Publication number
- US 2026/0236679 A1(US20260236679A1)
- Applicant
- Microsoft Technology Licensing, LLC
- Filed · Published
- Feb 7, 2025 · Aug 13, 2026
- Inventors
- Zhuo RUAN, Edward GAMSARAGAN, Arijit CHATTOPADHYAY
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 712/34
What Microsoft's AI weight-prefetching coprocessor actually does
You're waiting for an AI assistant to finish generating a long response, watching it tick out words one by one, slower than you'd like. A big reason for that delay is memory: large AI models are enormous, and the chip has to constantly fetch the right pieces of the model from memory every time it produces a new word.
Microsoft's patent describes a dedicated helper chip, a coprocessor, whose entire job is to predict which pieces of the AI model will be needed next and load them into a fast memory buffer before the main AI chip requests them. Think of it like a sous chef who pre-chops the vegetables before the head chef calls for them. If the prediction turns out to be wrong, the system can roll back and try again.
This is about making AI text generation faster without necessarily needing a bigger or more expensive main processor. The coprocessor sits alongside the AI chip and the regular CPU, coordinating memory traffic so the AI chip spends less time waiting.
… predicting a subset of large language model (LLM) weights, the subset LLM weights for the use of generating a next token by an LLM executing in the AI accelerator; and initiating caching of the subset of LLM weights into the cache buffer.
Translation: The system guesses which data the AI will need next and moves that information into a temporary storage area ahead of time.
How the coprocessor predicts and caches LLM weights ahead of time
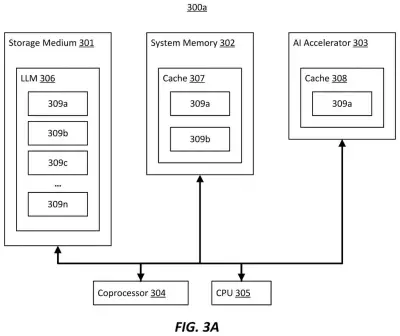
The patent describes a data management coprocessor that works alongside an AI accelerator (the specialized chip that runs the language model) and a standard CPU inside a computer system.
Here is how the system operates:
- Allocates a cache buffer in a separate region of memory, giving itself a dedicated staging area for incoming data.
- Predicts which LLM weights will be needed for generating the next token (a token is roughly a word or word-fragment). Large language models contain billions of numerical parameters called weights; at any moment, only a subset of those weights is actually needed to produce the next output.
- Initiates early caching of that predicted subset, moving the data into the buffer before the AI accelerator formally requests it, so the accelerator spends less time idle.
- Handles mispredictions by monitoring a confidence score. If the score indicates the prediction was wrong, the coprocessor can roll back the AI model's internal state and correct course.
The speculative approach here is borrowed from a technique decades old in CPU design called speculative execution (where a processor guesses which instructions come next and runs them early, then discards the work if the guess was wrong). Microsoft is applying that same idea to the memory-fetching problem specific to large language models.
The data management processor may also roll back a state of the LLM executing in the Al accelerator when a confidence score for the next token meets a criterion indicating a misprediction.
Translation: If the system makes a wrong guess about what the AI will do, it can undo the action and return to a previous state.
What this means for faster, cheaper AI inference hardware
AI inference, the act of running a trained model to generate answers, is expensive and slow largely because of memory bandwidth. The model weights have to travel from storage or main memory to the accelerator chip repeatedly, and that journey is a bottleneck. A coprocessor dedicated to anticipating and smoothing that traffic could meaningfully cut the time users spend waiting, without requiring a faster or larger main AI chip.
The rollback mechanism is also notable. It means the system is designed to fail gracefully rather than produce wrong output silently when a prediction misfires. For enterprises running AI inference at scale, even modest latency gains translate into real cost reductions across millions of requests. This filing sits squarely in the current wave of AI chip architecture patents covered in this week's Big Tech patents, where companies are racing to optimize the hardware layer beneath the models themselves.
Source: US 2026/0236679 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read the new patents from Big Tech, carmakers and more and send you the ones worth knowing. Plain English, free, every week.
The drawings · 5 sheets
5 drawing sheets from US 2026/0236679 A1 · click any drawing to enlarge


More from Microsoft
All 681 Microsoft patents →
More in Chip
All 651 Chip patents →
Qualcomm
Qualcomm Patents a Way to Shrink AI Image Filters by Cutting Redundant Math
AMD
Xilinx Patents a Processor That Loans Its CPU Cores to an Accelerator on Demand
AMD
Xilinx Patents an AI Chip Multiplier That Handles More Number Formats Than Usual
Nvidia
