
Microsoft Files Patent for an AI That Decides Whether to Answer You in Text, Voice or Images
Ask a chatbot something while your hands are full, then switch to typing on your phone, and today's AI often keeps talking at you anyway. Microsoft's patent application describes a model whose only job is to choose how each answer should reach you.
What Microsoft's reply-format patent actually does
Today, if you want an AI assistant to read an answer aloud or draw a picture, you usually have to ask for it or dig through a menu. And if you start out talking because your hands are busy, then switch to typing, the AI often keeps answering out loud anyway.
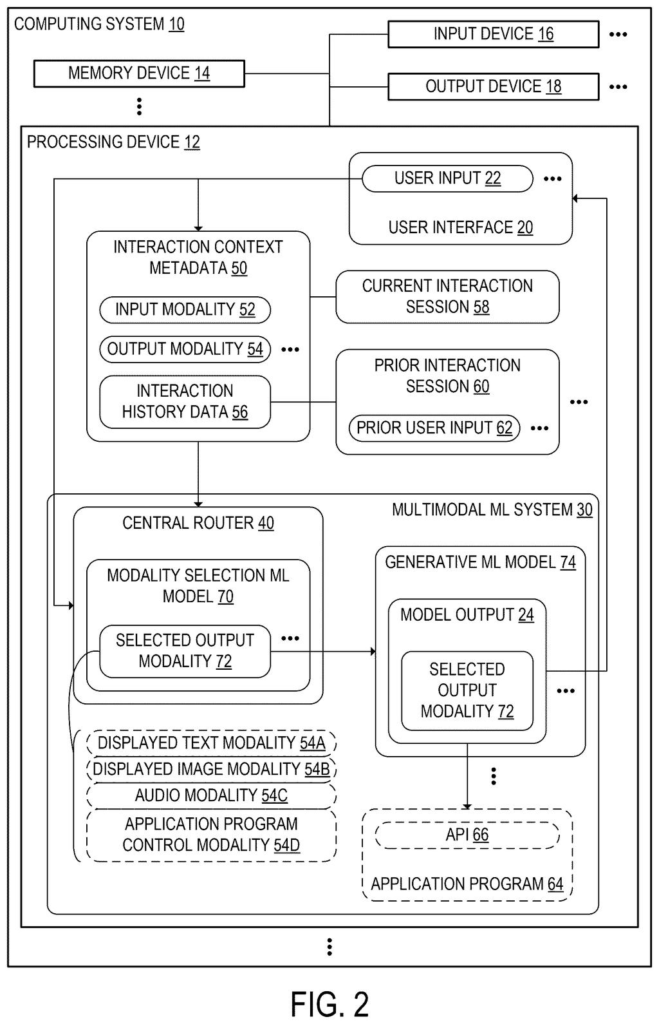
Microsoft's patent application describes a system that makes that call for you. It looks at how you asked (voice, typing, an image), which screens, speakers or apps are available right now, and what you did in past sessions. Then a separate model picks the format of the reply, and the AI that writes the answer builds it that way.
It can also pick more than one format at once, such as a short spoken summary while the full text appears on screen. If a speaker is busy or you plug in a new device, the answer can wait in line or be rewritten to fit the new setup.
… select one or more of the output modalities based at least in part on the user input and the interaction context metadata; at one or more generative ML models, based at least in part on the user input, compute one or more respective model outputs that respectively have the one or more selected output modalities; …
Translation: The AI picks the best output format and then generates the response in that style.
How the router picks voice, text or an app action
The claims center on a modality selection model, an AI classifier (a model trained to sort inputs into categories) that decides the format of a reply. The choices named in the claims are displayed text, a displayed image, audio, or an application control action, meaning instructions sent to another program. It works from the user's input plus interaction context metadata: a bundle of facts that includes how the input arrived, which output formats the connected devices can handle, and optionally the user's history from earlier sessions.
Once a format is chosen, one or more generative models (AI that writes text, makes images or produces speech) create the answer in that format. The selector can steer them by inserting a short instruction into the prompt, such as "Generate your response as an image," or by choosing which generative model to call. It can also set a detail level, for example brief for audio and fuller for text shown at the same time.
The dependent claims add scheduling:
- An event trigger (a condition like "the speaker is free again") is stored with the finished answer in an output queue.
- Queues can be kept per device or per format.
- If the context changes while an answer waits, the selector re-runs and the answer is rewritten in the new format.
The filing also describes letting you keep chatting while a slow model works on an earlier question, though that is separate from the claims shown here.
A computing system including one or more input devices, output devices, and processing devices. The one or more processing devices receive a user input via an input device and receive interaction context metadata associated with the user input.
Translation: The system takes in your message along with details about how you sent it and what devices are available.
Why Microsoft's AI reply-picking could matter to you
If this idea shows up in a real assistant, you would spend less time managing how answers arrive. Ask a question by voice while your hands are busy and you could get a short spoken reply plus the full text on a nearby screen, without ever asking for both. Switch to typing and the replies could follow you.
For Microsoft, the filing points at assistants that live across many devices: PCs, phones, speakers, headsets. The more screens and speakers one AI has to work with, the more it matters that something decides which one to use. It is also a patent application, so nothing here says any product works this way.
Microsoft's 17th filing we've tracked in voice and speech AI since May follows earlier work on identity-scrubbed speech training and audio redaction for medical records.
The mismatch between how an answer arrives and what a moment actually allows is a small friction that happens constantly. Getting a wall of text read aloud while driving, or missing a spoken reply because you glanced away, costs something real each time, and most people experience it dozens of times a day across their phone, car, speaker, and laptop.
Microsoft is treating that friction as a problem large enough to build a dedicated system around, one that reads your situation and chooses the right format automatically, holds answers in a queue when your context shifts, and rewrites them when you move from your car to your desk.
The most human idea here is a spoken summary paired with a full written answer waiting for later, which matches how people actually move through their days. Whether the system guesses right often enough that people trust it over just asking again is the real test, and that question is still open.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
25 drawing sheets from US 2026/0320413 A1 · click any drawing to enlarge


Show the other 17 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in