Microsoft
Microsoft · AI / ML · Filed Mar 31, 2025 · USPTO published Aug 13, 2026 · Aug 13 release
Microsoft Patents a Way to Feed AI Search Engines Only What They Need
Every AI search engine has a hard cap on how much text it can read at once. Microsoft's new patent describes a system that decides what to throw away before the AI ever sees the results.
- Publication number
- US 2026/0236548 A1(US20260236548A1)
- Applicant
- Microsoft Technology Licensing, LLC
- Filed · Published
- Mar 31, 2025 · Aug 13, 2026
- Inventors
- Anant KHANDELWAL, Puneet AGRAWAL, Tushar SINGHAL, Manish GUPTA
- Status when we published
- Examiner raised objections; the company can respond
- Document
- 20 claims
- US classification
- 707/722
- Examiner
- MACKES, KRIS E (Art Unit 2153)
How Microsoft's AI search trims its own reading list
Ever asked an AI search engine a question and gotten an answer that felt weirdly vague or just plain wrong? Part of the problem is that AI models can only read so much text at one time, and search results can be enormous.
Microsoft's patent describes a system that acts like a smart editor between the raw search results and the AI. It takes everything the search engine finds, then cuts, condenses, and focuses that pile of information down to the parts most relevant to your specific question. The leftover, trimmed-down block is what the AI actually reads before writing its answer.
The goal is to stop the AI from either ignoring useful information because there's too much of it, or from padding its answer with irrelevant details. You ask a question, the system figures out what matters, and the AI gets a cleaner brief to work from.
… generating compressed grounding data from the search results by refining the search results to below a token limit of a generative AI model; generating a search query prompt that includes the search query and the compressed grounding data …
Translation: The system shrinks search results to fit inside the AI's memory limit before sending them as a prompt.
How the compression system prunes and distills search results
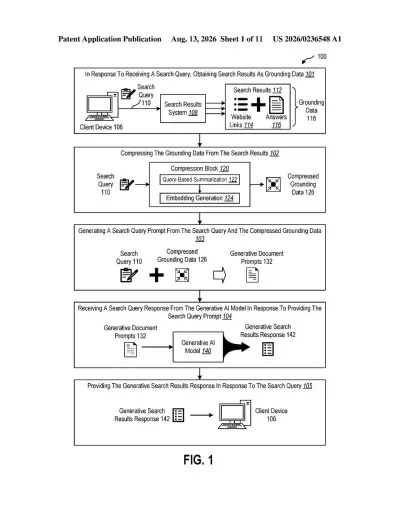
When you type a query into an AI-powered search engine like Microsoft's Copilot-integrated Bing, the system first pulls a standard list of web results: links, snippets, and related answers. The problem is that the combined text of those results can easily exceed the token limit (think of it as the AI's working memory) of the generative model being used to write a response.
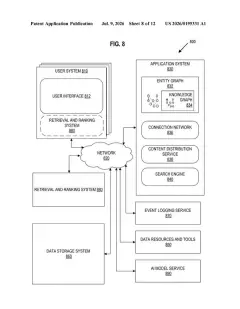
This patent introduces a grounding compression system that sits between the raw search results and the AI model. "Grounding" in AI refers to anchoring the model's responses in real, retrieved facts rather than letting it invent things. The compression system takes the full set of search results and applies a process described as distilling, condensing, and pruning that text down into a compressed grounding block.
Critically, the pruning is not random. The system keeps the information most relevant to the original query, discarding content that is off-topic or redundant. The final compressed block is then packaged with the original query into a prompt that gets sent to the generative AI model.
The model generates its response based on that focused, curated input, and the answer is returned to the user. The chain looks like this:
- User submits a search query
- Search system returns raw results (links, snippets, answers)
- Compression system trims results to fit the AI's token limit
- AI receives the compressed, query-focused context and writes its response
- User gets the final answer
… the grounding compression system intelligently distills, condenses, and prunes the grounding data into a compressed block that focuses on the search query, enabling the generative AI model to more efficiently and accurate create a generative response …
Translation: The software trims away irrelevant information so the AI can focus on the specific answer the user needs.
What this means for AI-powered search accuracy
For anyone who uses AI-powered search regularly, the practical payoff here is fewer confident-sounding wrong answers. A big source of AI search errors is the model working from too much noise, too little relevant signal, or both at once. A compression layer that actively filters for query relevance before the AI sees anything should, in theory, produce answers that are more accurate and more directly responsive to what you actually asked.
Microsoft is clearly investing in the infrastructure layer that makes generative search reliable enough to trust, which is a harder engineering problem than the flashy front-end demos suggest. This kind of context-management filing sits in the middle of an active wave of Big Tech patent news around making AI search grounding more precise, and it signals that Microsoft sees the token-limit bottleneck as a real obstacle worth patenting around.
Source: US 2026/0236548 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 11 sheets
11 drawing sheets from US 2026/0236548 A1 · click any drawing to enlarge


Show the other 3 sheets