
Microsoft
Microsoft · AI / ML · Filed Oct 16, 2025 · USPTO published Sep 24, 2026 · Sep 24 release
Microsoft Patents a Way to Run AI Math Efficiently on Any Processor
Every time an AI model runs a calculation, it has to adapt to the specific chip underneath it. Microsoft's new patent describes a system that handles that adaptation automatically, without rewriting the math for each processor.
- Publication number
- US 2026/0288531 A1(US20260288531A1)
- Applicant
- Microsoft Technology Licensing, LLC
- Filed · Published
- Oct 16, 2025 · Sep 24, 2026
- Inventors
- Wei CUI, Jilong XUE
- Status when we published
- Waiting for an examiner
- Document
- 21 claims
- US classification
- 718/102
- Parent application
- National Stage Entry of PCT/US2024/033180 (filed Jun 10, 2024)(PCTUS2024033180)
What Microsoft's tensor-sizing system actually does
Every time you run an AI feature on your phone, laptop, or a cloud server, the software has to crunch through enormous grids of numbers. Those grids are called tensors, and different chips handle them in different ways and different sizes. Normally, engineers have to tune that math by hand for each type of chip.
Microsoft's patent describes a system that figures out the right chunk size automatically. It looks at how big the grid of numbers is, picks a fitting "window" size, then breaks the work into blocks the chip can handle efficiently. The instructions for each block are precompiled, meaning they're prepared in advance so there's no wasted time at the moment the AI actually runs.
The goal is one approach that works across many different processors, without anyone needing to rewrite the underlying math. That matters a lot as AI software gets deployed on everything from cloud data centers to consumer devices with wildly different chips inside.
… based on a size of a target tensor, a target window size is determined for a target operation associated with the target tensor to be processed on a processing device. At least one data block is determined based on the target window size and the target tensor.
Translation: The system breaks down massive AI math problems into smaller chunks tailored to whatever chip is running them.
How the window-sizing and block-splitting process works
The patent describes a compilation-time optimization scheme for tensor operations, the basic building blocks of nearly all AI and machine-learning workloads.
Here's the core flow:
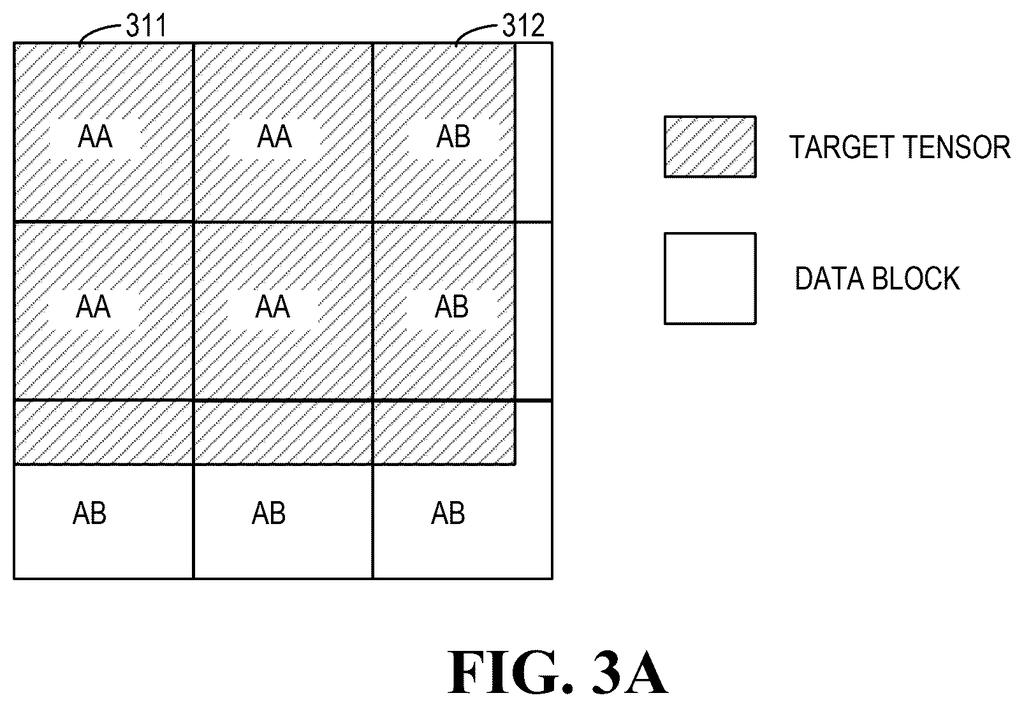
- The system examines the size of the target tensor (the grid of numbers to be processed).
- Based on that size, it picks a target window size, essentially the portion of the grid a given processor can handle efficiently in one pass.
- It then divides the tensor into data blocks whose combined elements cover the entire tensor, even if a block extends slightly beyond its edges.
- For each block, it runs precompiled tasks that correspond to the desired mathematical operation, using each element's position in the original tensor to compute correct results.
The key design choice is precompilation. The tasks are compiled ahead of time (before the model actually runs) for each combination of operation type and window size. That means at runtime, the chip isn't doing any extra bookkeeping work; it just executes the prepared instructions.
The patent emphasizes that this scheme is meant to be universal across processing device types, covering GPUs, specialized AI accelerators, and other chips without requiring device-specific rewrites of the core math.
What this means for AI software running across different hardware
For most users, this kind of patent is invisible, but its effects are not. AI features on phones, laptops, and cloud services are only as fast as the software layer that translates model math into chip instructions. When that translation is inefficient, your AI assistant is slower and the cloud server running it burns more energy.
A universal scheme like this could reduce the engineering time needed to port AI models across hardware generations or new chip designs. Microsoft's interest in AI infrastructure efficiency shows up repeatedly in its patent activity, and a filing like this fits a broader push to make AI workloads cheaper to run at scale, whether on Azure servers or on Windows devices with dedicated AI chips.
Microsoft's 16th filing we've tracked in the AI chip wars since July adds to a pattern that includes running giant models on small chips and splitting work across chip types.
Source: US 2026/0288531 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Microsoft patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 11 sheets
11 drawing sheets from US 2026/0288531 A1 · click any drawing to enlarge


Show the other 3 sheets


More from Microsoft
All 646 Microsoft patents →
More in AI / ML
All 2,637 AI / ML patents →
Samsung
Samsung Patents a Two-Stage AI Reading Method That Skips Unimportant Sentences First
Nvidia
Nvidia Patents a Compiler That Skips Unnecessary AI Math at Runtime
Google
Google Patents an AI That Fetches One-Time Login Codes From Your Email
IBM
No comments yet