
Nvidia Patents a System That Reserves AI Resources Before Agents Actually Need Them
Instead of waiting for an AI agent to start working and then scrambling to find computing resources, Nvidia wants to send a forecast ahead of every job, so the server is already ready when the work arrives.
How Nvidia's AI agents predict their own workloads
AI agents today create a basic coordination problem: the server handling the heavy computation doesn't know what's coming until a request actually lands on its doorstep. By then, resources have to be grabbed on the fly, which wastes time and can slow things down when many tasks pile up at once.
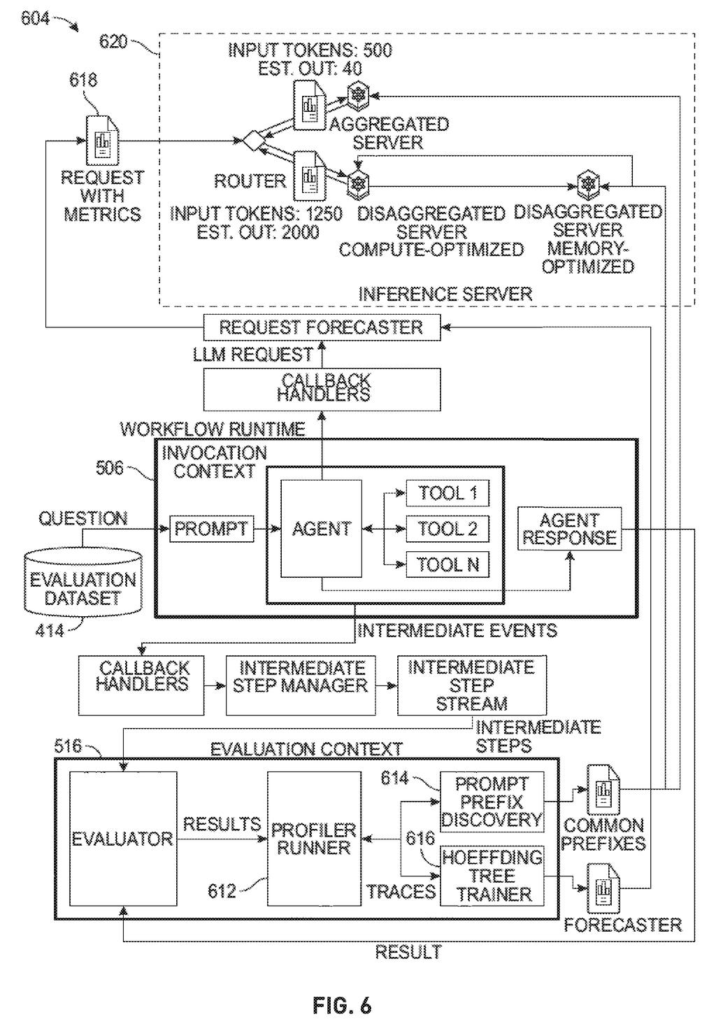
Nvidia's patent describes a system that studies how AI agent workflows behave over time, then builds prediction models from that history. When a new request comes in, the system attaches a small "forecast note" to it, describing how much compute power the task is likely to need and how the workflow will probably unfold.
The server receiving that request reads the forecast note and sets aside the right resources before the actual work begins. Think of it like a restaurant kitchen getting a heads-up about a large party's order before they even sit down, so nothing is rushed or improvised.
training, by an artificial intelligence (AI) agent system, one or more forecasting models based on offline profiling data collected from one or more AI agent workflows, the one or more forecasting models predicting future workflow behavior patterns and resource utilization characteristics for the one or more AI agent workflows; …
Translation: The system learns how AI workflows typically behave by studying past performance data.
How the forecasting model attaches predictions to live requests
The system works in two phases: an offline training phase and a live runtime phase.
During the offline training phase, the system collects profiling data from past AI agent workflow runs, capturing how much compute each task consumed, how long each step took, and which paths through a workflow were most common. Those observations train forecasting models (predictive algorithms that learn patterns from historical data, similar to how a weather model learns from past readings).
During runtime, when a new request enters the system, the AI agent layer runs the forecasting model against that request. The output is predictive metadata, a structured annotation that travels with the request and contains:
- Expected workflow execution paths (which steps will likely run and in what order)
- Anticipated resource utilization (how much CPU, GPU, or memory the task will need)
- Estimates of future work that downstream systems should prepare for
That annotated request is then forwarded to an inference server (the machine that actually runs the AI model computations). The server reads the metadata and makes resource allocation decisions proactively rather than reactively, assigning compute capacity before the demand spike arrives.
During runtime execution, the system generates predictive metadata for incoming requests, including estimates of expected workflow execution patterns and anticipated resource utilization.
Translation: As tasks run, it forecasts exactly what computing power each upcoming request will require.
What predictive compute means for AI assistant speed
For anyone using AI-powered tools, whether that's a coding assistant, a customer-service bot, or an autonomous research agent, response time is the thing that determines whether the tool feels useful or frustrating. Systems that scramble for compute after a request lands introduce unpredictable delays, especially under heavy load.
Nvidia has been filing around AI inference optimization since at least 2024, and this patent fits that pattern. By moving resource decisions earlier in the pipeline, the approach could make inference servers handle more requests with the same hardware. That matters for the data center operators who buy Nvidia chips and for end users who interact with agents built on them.
Nvidia's 41st filing we've tracked since July in the AI chip wars builds on routing tasks to workers and splitting steps across chips.
The core trade-off here is accuracy versus usefulness. A forecast that is even slightly wrong, predicting a lightweight task that turns out to be heavy, could leave a server under-provisioned and no better off than the reactive status quo. The system's value depends entirely on how well the forecasting models generalize from historical data to genuinely new requests.
AI agent workflows are also notoriously unpredictable. A user asking a coding agent to "fix the bug" might trigger two tool calls or twenty, depending on what the model finds. That variability is exactly why nobody has solved this cleanly with heuristics. Whether learned forecasting models can stay accurate as agent behavior evolves is an open question the patent doesn't fully answer.
That said, even a rough forecast that is right 70 percent of the time could produce measurable throughput gains, and the downside of a bad prediction (slightly misallocated resources for one request) is low-stakes. The trade reads as worth making, with the caveat that the real test is how frequently the forecast is wrong in the expensive direction.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time Nvidia patent news breaks.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings
12 drawing sheets from US 2026/0278406 A1 · click any drawing to enlarge


Show the other 4 sheets


Want this weekly breakdown for a company we don't cover? Patentlyze Pro →
Be the first to weigh in