IBM
IBM · AI / ML · Filed Feb 19, 2025 · USPTO published Aug 20, 2026 · Aug 20 release
IBM Patents a Memory-Saving Compression System for AI Text Generation
Every word an AI language model generates costs memory, and that cost compounds fast. IBM's new patent targets the biggest memory hog in that process and squeezes it down without waiting for the model to finish.
- Publication number
- US 2026/0244860 A1(US20260244860A1)
- Applicant
- INTERNATIONAL BUSINESS MACHINES CORPORATION
- Filed · Published
- Feb 19, 2025 · Aug 20, 2026
- Inventors
- Fatih Ilhan, Gong Su
- Status when we published
- Waiting for an examiner
- Document
- 20 claims
- US classification
- 704/9
- Examiner
- BLANKENAGEL, BRYAN S (Art Unit 2658)
How IBM's KV cache trick cuts AI memory use mid-run
Imagine you're asking an AI assistant to summarize a 50-page document. Behind the scenes, the model is keeping a running record of every word it has already processed, so it can refer back to earlier context as it writes each new sentence. That record, called a KV cache, can balloon to enormous sizes and is one of the main reasons running large AI models demands so much expensive memory.
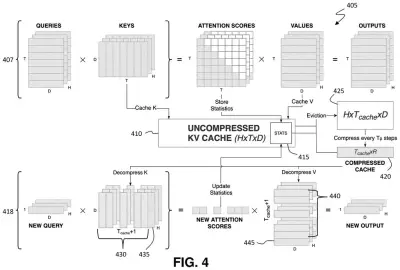
IBM's patent describes a system that compresses that cache while the model is still generating text, rather than leaving it uncompressed until the job is done. Crucially, it only decompresses the specific parts it needs at any given moment, not the whole thing at once. Think of it like reading a compressed zip file one folder at a time instead of unpacking everything onto your desktop first.
The goal is to let AI models handle longer conversations or bigger documents without needing as much hardware memory, which is one of the main costs in running AI systems at scale.
performing, during a decoding phase performed by a large language model (LLM), multi-head compression of key-value data in a cache; and performing partial decompression of the key-value data during the decoding phase …
Translation: The system shrinks memory data while the AI generates text, only restoring parts of it as needed.
How multi-head compression and partial decompression work together
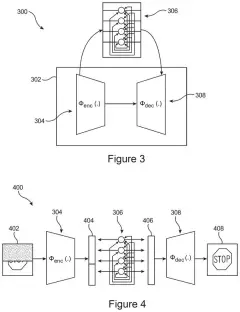
When a large language model (LLM) generates text, it works in stages. First it breaks your input into tokens (small chunks of text), then runs a prefill phase to process the whole input at once, then enters a decoding phase where it produces output one token at a time, and finally converts those tokens back into readable text.
During decoding, the model repeatedly consults a KV cache (key-value cache), a data store that holds intermediate computations for every token the model has seen. Without compression, this cache grows linearly with context length and can consume tens of gigabytes of GPU memory for a long document or conversation.
IBM's patent addresses this with two linked operations:
- Multi-head compression: The cache is compressed across all attention heads simultaneously. Attention heads are the parallel sub-systems inside a transformer model that each focus on different relationships in the text; compressing across all of them at once is more efficient than handling each separately.
- Partial decompression: Rather than expanding the entire compressed cache each time the model needs to look something up, only the relevant slice is decompressed, used, and then left compressed again.
The patent applies specifically to decoder-based transformer models, the architecture underlying most popular AI chat and text-generation systems, meaning the technique targets a widely used class of AI rather than a narrow edge case.
… decoder-based transformer model that is configured to generate an output based on an input by performing a tokenization phase, a prefill phase, the decoding phase, and a detokenization phase.
Translation: The AI processes text through distinct steps that break down input, generate responses, and format the final output.
What this means for running large AI models on tighter budgets
Memory is the main bottleneck in deploying large AI models, especially for long conversations or documents. Reducing how much memory the KV cache consumes means you can either run the same model on cheaper hardware, fit more simultaneous users onto one server, or handle longer inputs that would otherwise exceed memory limits. For enterprise AI deployments, those translate directly into cost savings.
IBM operates heavily in the enterprise AI infrastructure space, so a patent aimed at making LLM inference cheaper to run fits squarely into that strategy. The technique described here sits in an area of active engineering interest: how to run bigger models on the hardware that already exists. Patentlyze publishes plain-English patent summaries across AI memory and inference optimization filings, and IBM's focus on KV cache compression reflects a wider industry push to reduce the per-token compute cost before better hardware catches up.
IBM's tenth filing we've tracked since July in the AI chip wars builds on splitting models across nodes and smarter memory for connections.
Source: US 2026/0244860 A1 at the USPTO (PDF). Full patent text and figures are in the official publication.
Get our take in your Top Stories
Liked this breakdown? Add Patentlyze as a preferred source on Google, and our plain-English take shows up more often in your Top Stories the next time IBM patent news breaks.
Add Patentlyze on Google
One click.
There are more where this came from
We read every patent application Big Tech publishes and send you the ones worth knowing. Plain English, free, every week.
The drawings · 7 sheets
7 drawing sheets from US 2026/0244860 A1 · click any drawing to enlarge


More from IBM
All 470 IBM patents →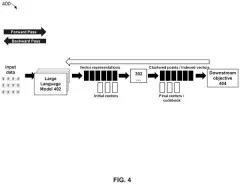
More in AI assistant & agent
All 413 AI assistant & agent patents →
Qualcomm
Qualcomm Patents a Way to Keep Only the Video Frames That Actually Matter for AI
Samsung
Samsung Patents a Technique to Train AI That Learns Your Preferences Faster
Qualcomm
Qualcomm Patents a Way to Stop AI Video Models From Running Out of Memory
Microsoft